
深層強化学習における高速価値追跡
1Department of Statistics, Purdue University, West Lafayette, IN 47907, USA.

Abstract:
Reinforcement learning (RL) tackles sequential decision-making problems by creating agents that interacts with their environment. However, existing algorithms often view these problem as static, focusing on point estimates for model parameters to maximize expected rewards, neglecting the stochastic dynamics of agent-environment interactions and the critical role of uncertainty quantification. Our research leverages the Kalman filtering paradigm to introduce a novel and scalable sampling algorithm called Langevinized Kalman Temporal-Difference (LKTD) for deep reinforcement learning. This algorithm, grounded in Stochastic Gradient Markov Chain Monte Carlo (SGMCMC), efficiently draws samples from the posterior distribution of deep neural network parameters. Under mild conditions, we prove that the posterior samples generated by the LKTD algorithm converge to a stationary distribution. This convergence not only enables us to quantify uncertainties associated with the value function and model parameters but also allows us to monitor these uncertainties during policy updates throughout the training phase. The LKTD algorithm paves the way for more robust and adaptable reinforcement learning approaches.
関連する概念動画
 01:23
Reinforcement
Positive reinforcement occurs when a behavior is followed by the presentation of a rewarding stimulus, increasing the frequency of that behavior. For example:
 01:24
Reinforcement Schedules
Once a behavior is learned,...
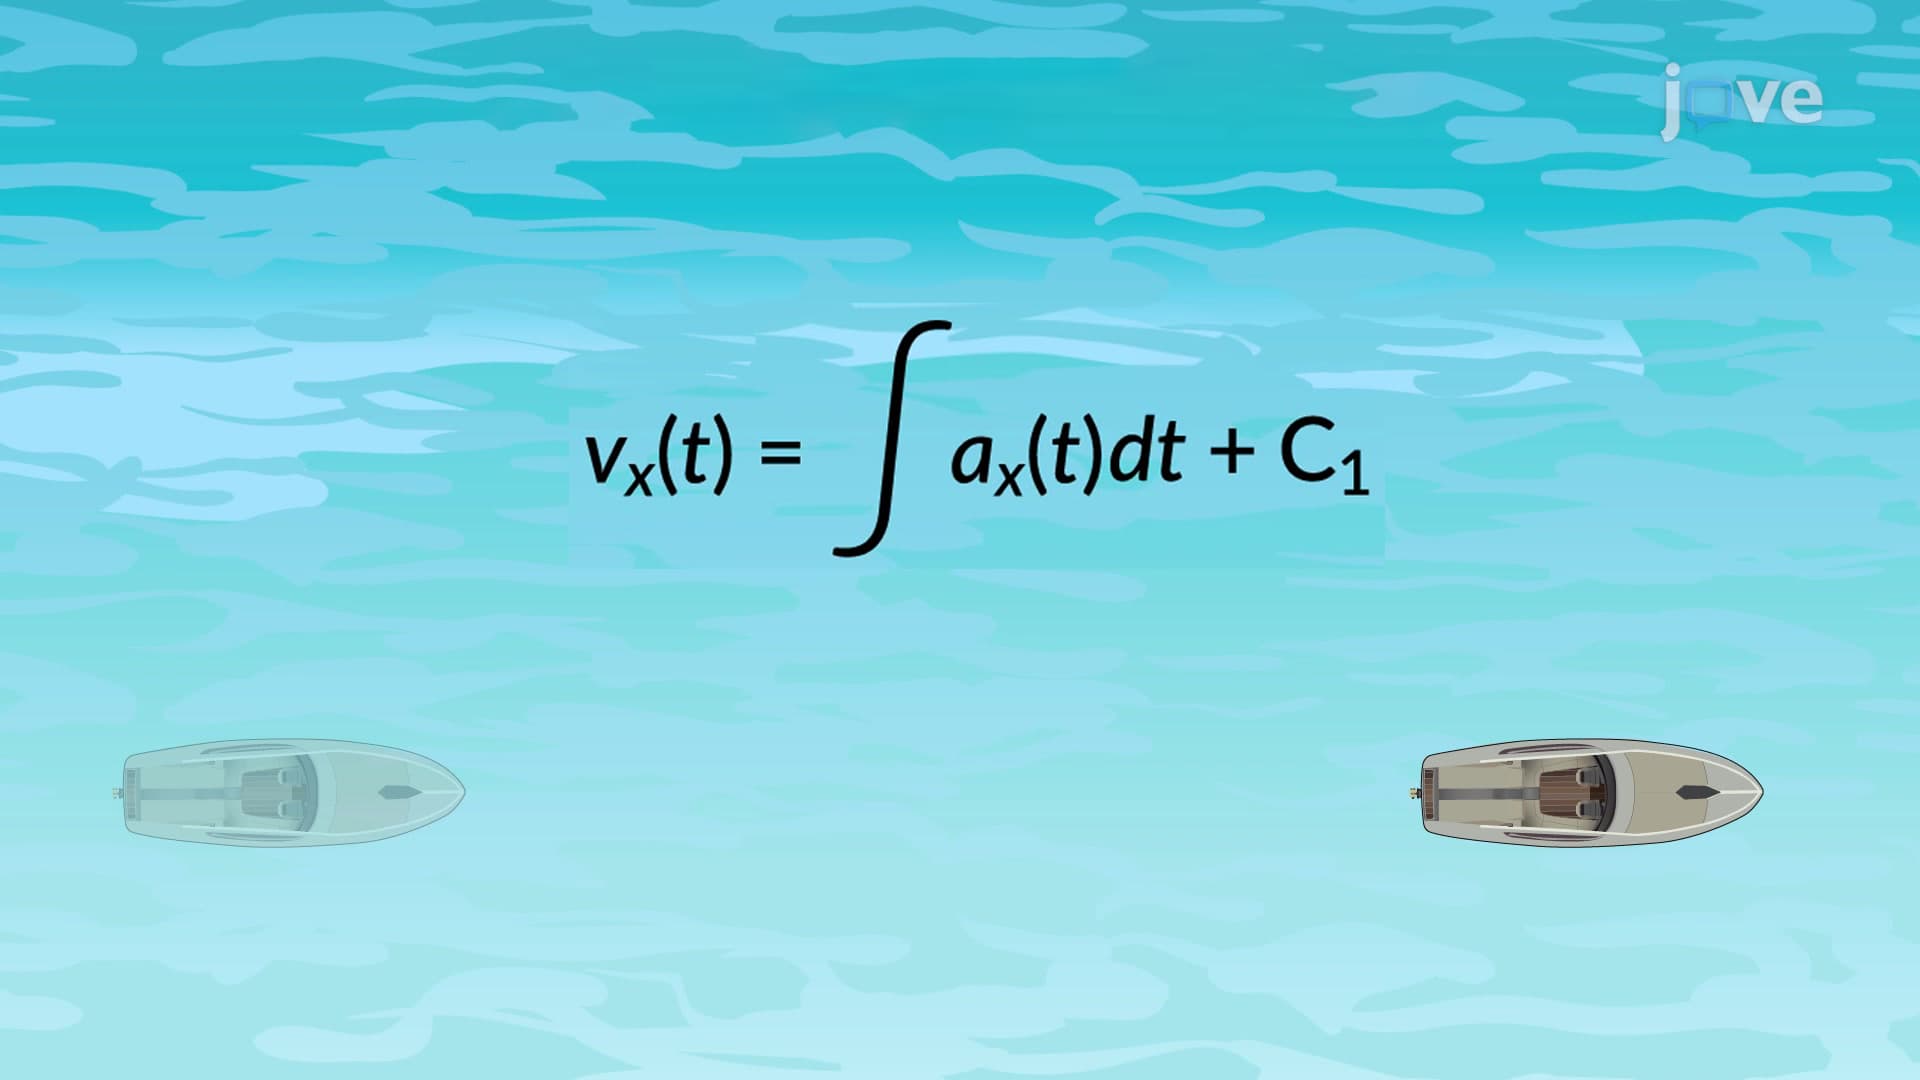 01:13
Velocity and Position by Integral Method
Consider an example to calculate the velocity and position from the acceleration function. A motorboat is traveling at a constant velocity of 5.0 m/s when it starts to decelerate to arrive at the dock. Its acceleration is...
 01:12
Observational Learning
 01:12
Average and Instantaneous Velocity Vectors
 01:15
Instantaneous Velocity - I