
GreenViT:都市緑地セグメンテーションと監査可能面積推定のためのシングルパス段階的アップサンプリングを備えたビジョントランスフォーマー
Ziqiang Xu1, Young Choi2, Changyong Yi3
1Department of Robot and Smart System Engineering, Kyungpook National University, 80, Daehak-ro, Buk-gu, Daegu 41566, Republic of Korea.

Abstract:
Urban green-space monitoring in dense cityscapes remains limited by accuracy-efficiency trade-offs and the absence of integrated, auditable area estimation. We introduce GreenViT, a Vision Transformer (ViT) based framework for precise segmentation and transparent quantification of urban green space. GreenViT couples a ViT-L/14 backbone with a lightweight single-path, progressive upsampling decoder (Green Head), preserving global context while recovering thin structures. Experiments were conducted on a manually annotated dataset of 20 high-resolution satellite images collected from Satellites.Pro, covering five land-cover classes (background, green space, building, road, and water). Using a 224 × 224 sliding window sampling scheme, the 20 images yield 62,650 training/validation patches. Under five-fold evaluation, it attains 0.9200 ± 0.0243 mIoU, 0.9580 ± 0.0135 Dice, and 0.9570 PA, and the calibrated estimator achieves 1.10% relative area error. Overall, GreenViT strikes a strong balance between accuracy and efficiency, making it particularly well-suited for thin or boundary-rich classes. It can be used to support planning evaluations, green-space statistics, urban renewal assessments, and ecological red-line verification, while providing reliable green-area metrics to support urban heat mitigation and pollution control efforts. This makes it highly suitable for decision-oriented long-term monitoring and management assessments.
関連する概念動画
 01:22
Upsampling
 01:20
Downsampling
The Fourier transform of the decimated sequence reveals a combination of scaled and shifted versions of the original spectrum. This...
 01:29
Topographic Surveying and Contours
 01:20
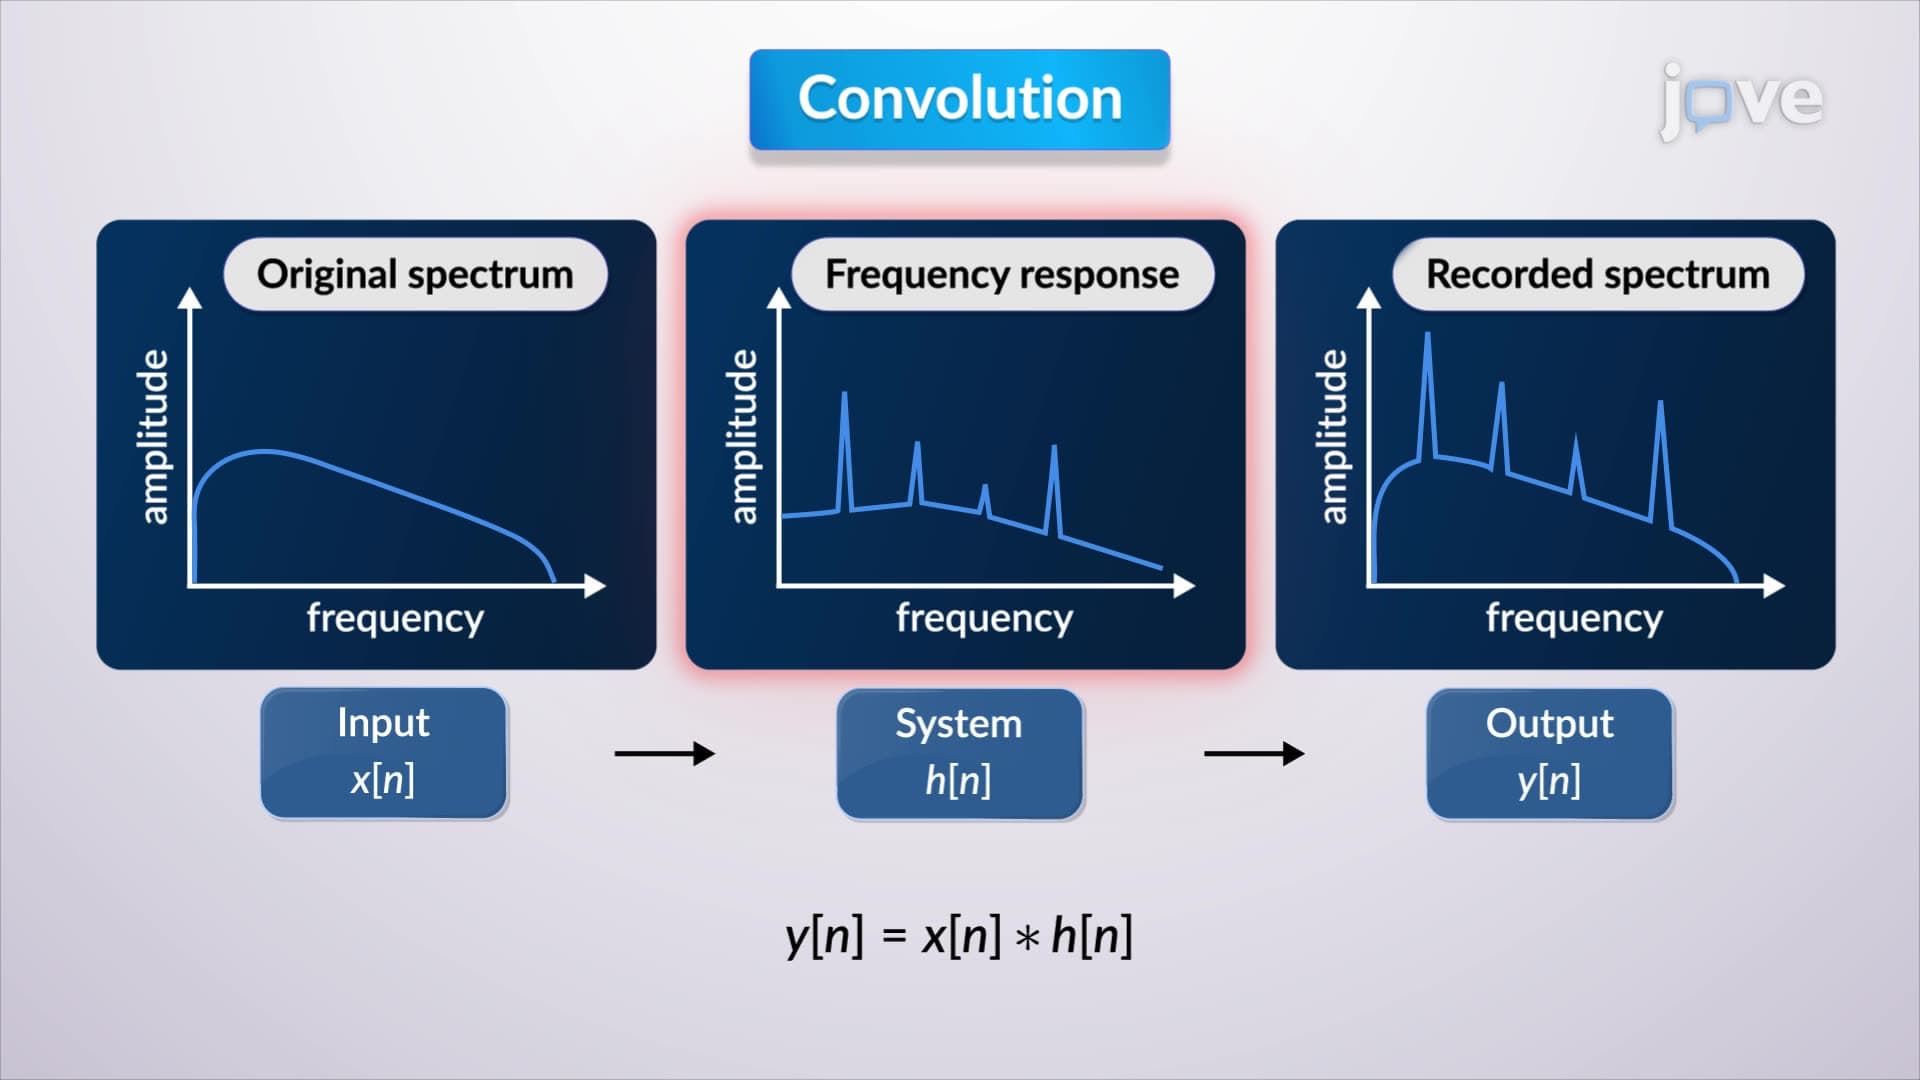
Deconvolution
Deconvolution involves several mathematical techniques to derive the impulse response. One common approach is polynomial division. In this method, the input and output sequences are treated as coefficients of...
 01:24
Vision
 01:15
Depth Perception and Spatial Vision