
インフルエンザにおける単一アミノ酸置換は,ヘマグルーチニンの受容体結合特異性を変化させます
Nature
|July 7, 1983

まとめ
インフルエンザウイルスのヘマグルチニン (HA) は,シアル酸受容体を通して細胞に結合する. HA1の位置226にある特定のアミノ酸の変化により,ウイルスがNeuAc alpha 2-3GalまたはNeuAc alpha 2-6Gal結合に結合するかどうかを決定します.
科学分野:
- ウイルス学 ウイルス学 ウイルス学
- グライコバイオロジーは,
- 構造生物学 構造生物学とは
背景:
- インフルエンザウイルスのヘマグルチニン (HA) は,宿主細胞のシアル酸受容体と結合することにより,ウイルスの侵入を媒介する.
- この相互作用の特異性は,異なるインフルエンザウイルス株によって異なります.
- HA結合特異性の正確な分子決定因子を特定することは,ウイルストロピズムを理解し,抗ウイルス薬の開発に不可欠です.
研究 の 目的:
- シアリック酸の結合に差異的に結合するヘマグルーチニン分子の内にある特定のアミノ酸残基を特定する.
- HAの配列変化と,異なる受容体結合特異性を相関させるため.
主な方法:
- シアリック酸の結合における既知の差異を持つインフルエンザウイルスからのヘマグルチニンのアミノ酸配列の比較分析.
- 特定された配列の変異をマッピングすることで,ヘマグルチニン分子の3次元構造にマッピングします.
主要な成果:
- NeuAc alpha 2-3Galと NeuAc alpha 2-6Galの結合のアミノ酸認識における有意な差異が観察されました.
- この差異は,HA1サブユニットの位置226の特定のアミノ酸置換と一貫して関連していました.
- 残基226は,受容体結合に関与する領域であるヘマグルチニンの遠端のポケットに位置しています.
結論:
- HA1のアミノ酸226は,インフルエンザウイルスにおけるシアル酸結合特異性の重要な決定因子である.
- この発見は,インフルエンザウイルスの宿主範囲と組織トロピズムにおける変動を理解するための分子基盤を提供します.
- 特定された結合部位は,治療的介入の潜在的なターゲットを提供します.
さらに関連する動画
 09:31
Fluorescence-based Neuraminidase Inhibition Assay to Assess the Susceptibility of Influenza Viruses to The Neuraminidase Inhibitor Class of Antivirals
Published on: April 15, 2017
 07:55
Generation of Escape Variants of Neutralizing Influenza Virus Monoclonal Antibodies
Published on: August 29, 2017
関連する概念動画
 00:36
Viral Mutations
A mutation is a change in the sequence of bases of DNA or RNA in a genome. Some mutations occur during replication of the genome due to errors made by the polymerase enzymes that replicate DNA or RNA. Unlike DNA polymerase, RNA polymerase is prone to errors because it is not capable of “proofreading” its work. Viruses with RNA-based genomes, like HIV, therefore accrue mutations faster than viruses with DNA-based genomes. Because mutation and recombination provide the raw material for adaptive...
 01:49
Conserved Binding Sites
Many proteins’ biological role depends on their interactions with their ligands, small molecules that bind to specific locations on the protein known as ligand-binding sites. Ligand-binding sites are often conserved among homologous proteins as these sites are critical for protein function.
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
Binding sites are often located in large pockets, and if their location on a protein’s surface is unknown, it can be predicted using various approaches. The energetic method computationally analyses the...
 02:28
Leaky Scanning
During most eukaryotic translation processes, the small 40S ribosome subunit scans an mRNA from its 5' end until it encounters the first start AUG codon. The large 60S ribosomal subunit then joins the smaller one to initiate protein synthesis. The location of the translation initiation is largely determined by the nucleotides near the start codon as there may be multiple translation initiation sites present on the mRNA. Marilyn Kozak discovered that the sequence RCCAUGG (where R stands for...
 01:30
Point and Frameshift Mutations
Point mutations are genetic alterations involving the change of a single nucleotide base pair in DNA. Depending on how the alteration affects protein synthesis, they can lead to various consequences.Point mutations fall into the following types:Silent mutations occur when a nucleotide change does not alter the amino acid sequence due to the redundancy of the genetic code. For instance, changing ACC to ACA still encodes threonine, leaving the protein function unaffected. This occurs because...
 01:27
Influenza
Influenza is an acute, highly communicable viral disease that affects the respiratory tract and is responsible for seasonal epidemics worldwide. Influenza A is the most prevalent type associated with widespread outbreaks and is subtyped based on two surface glycoproteins: hemagglutinin (H) and neuraminidase (N), as in H1N1. These glycoproteins are essential for viral infectivity, transmission, and immune recognition. Transmission occurs primarily through respiratory droplets and contaminated...
 01:25
Inhibitors Of Virion Release
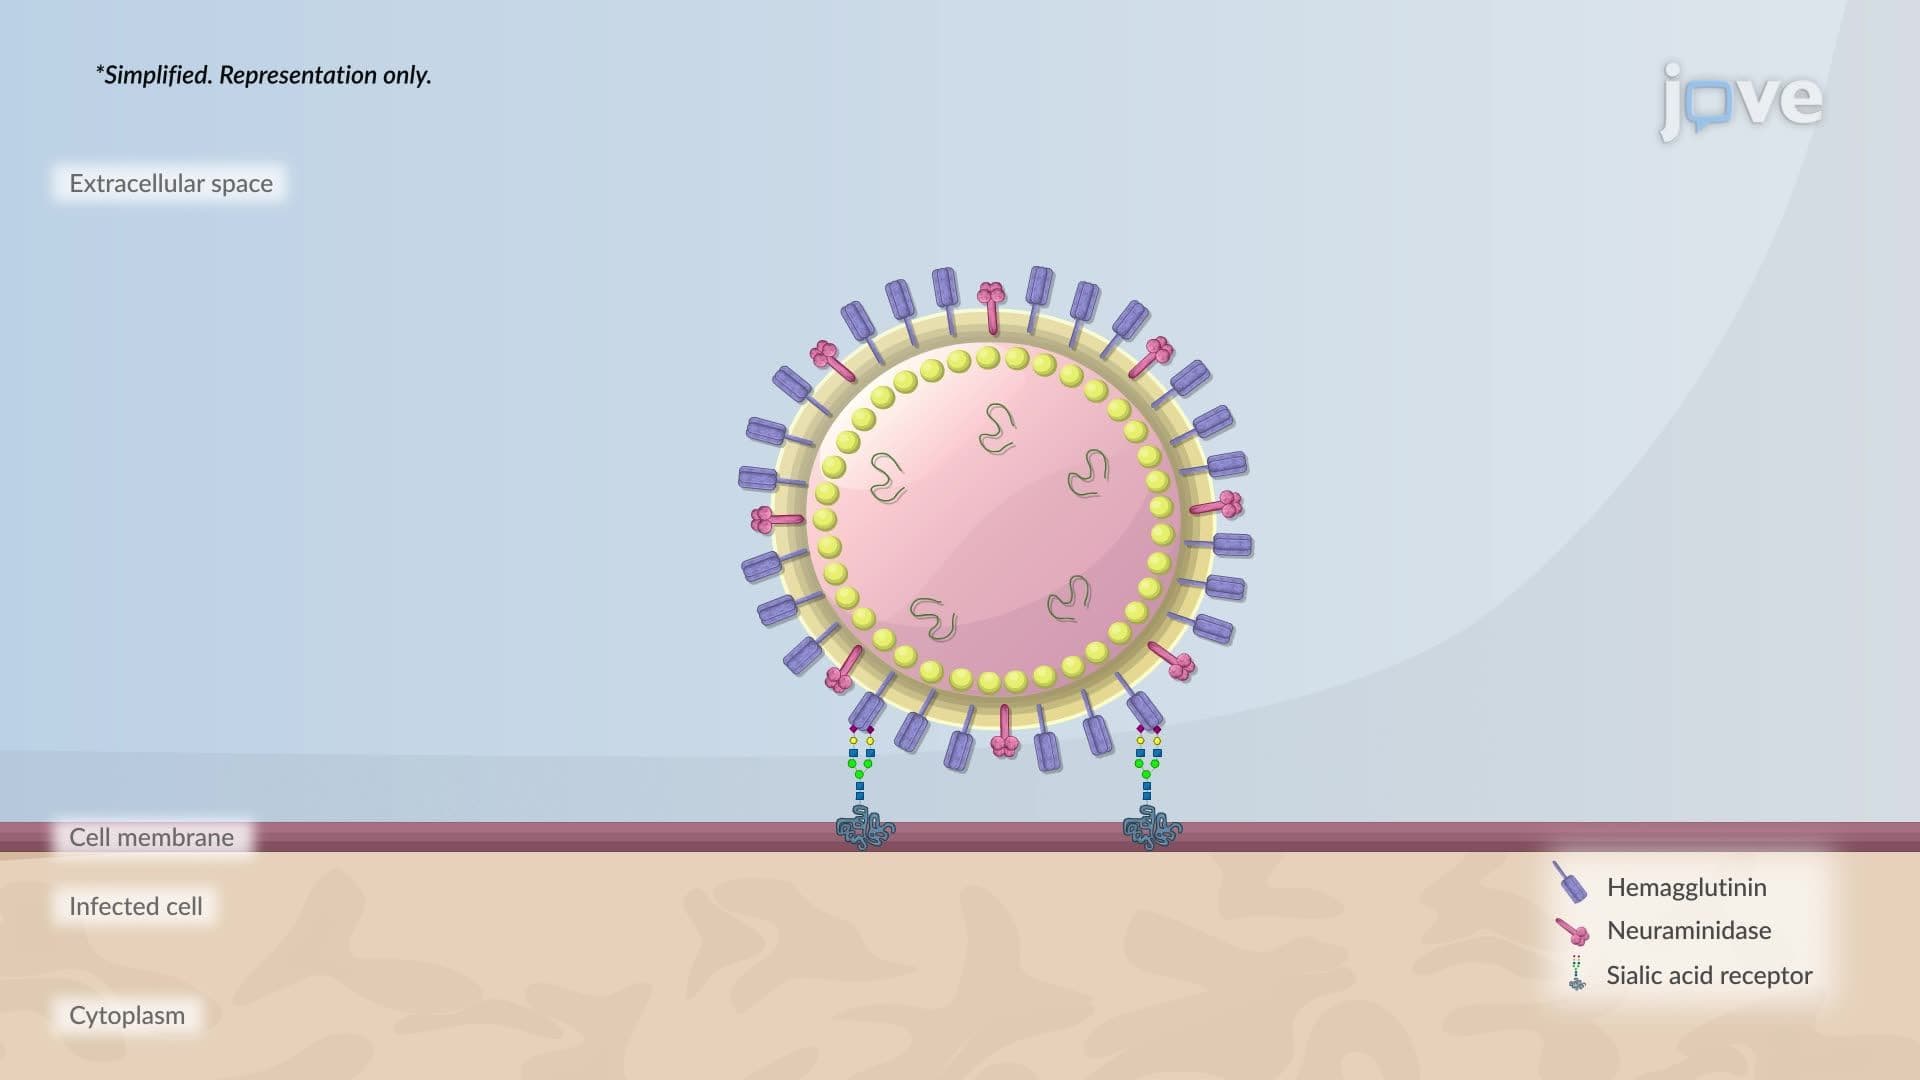
Viral replication and dissemination rely on efficient mechanisms for host cell entry, genome replication, assembly, and release. Influenza viruses, such as types A and B, are negative-sense single-stranded RNA viruses with a segmented genome, that depend on two critical surface glycoproteins to carry out these processes: hemagglutinin (HA) and neuraminidase (NA). HA initiates infection by binding to sialic acid residues on the surface of host epithelial cells, facilitating receptor-mediated...