
社会不平等中的沙堆普遍性:基尼和加尔各答的措施
Suchismita Banerjee1, Soumyajyoti Biswas2, Bikas K Chakrabarti1,3
1Economic Research Unit, Indian Statistical Institute, Kolkata 700108, India.
Entropy (Basel, Switzerland)
|May 27, 2023

概括
在激烈的竞争下,基尼 (g) 和加尔各答 (k) 指数的社会不平等指标汇聚到相似的值 (约为0.87). 这表明社会经济系统可能遵循自我组织的关键性原则.
科学领域:
- 社会经济学 社会经济学
- 复杂性科学 复杂性科学
- 统计物理 统计物理
背景情况:
- 社会不平等是普遍存在的,并趋向于一个普遍的界限.
- 标准的不平等指标包括吉尼 (g) 指数和加尔各答 (k) 指数.
- 卡尔卡塔指数 (k) 量化了财富分布,代表了人口的一小部分 (1-k) 所拥有的财富.
研究的目的:
- 审查和分析基尼和加尔各答指数在各种社会部门的行为.
- 在不受限制的竞争条件下调查这些不平等措施的趋同.
- 探索社会不平等动态和自我组织的批判性 (SOC) 之间的关系.
主要方法:
- 对吉尼 (g) 和加尔各答 (k) 指数进行了广泛的审查和数据分析.
- 检查不同社会机构 (市场,选举,体育等) 中的不平等措施. ) 的情况.
- 观察到的不平等模式与理论模型的比较,包括帕雷托定律和SOC.
主要成果:
- 随着竞争的加剧,吉尼 (g) 和加尔各答 (k) 指数都趋于相似的值 (约为0.87).
- 在缺乏福利机制的各种社会体系中观察到这种趋同.
- 这些发现与一般化的帕雷托80/20定律和SOC州的前体值一致.
结论:
- 交互的社会经济系统表现出与自我组织的关键性 (SOC) 相一致的动态.
- SOC模型为理解复杂的社会经济系统提供了一个框架.
- 这些结果为将SOC原则应用于社会不平等提供了定量支持.
相关概念视频
 01:06
Skewness
12.1K
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
12.1K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.7K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.7K
 01:08
Outliers and Influential Points
4.1K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.1K
 01:24
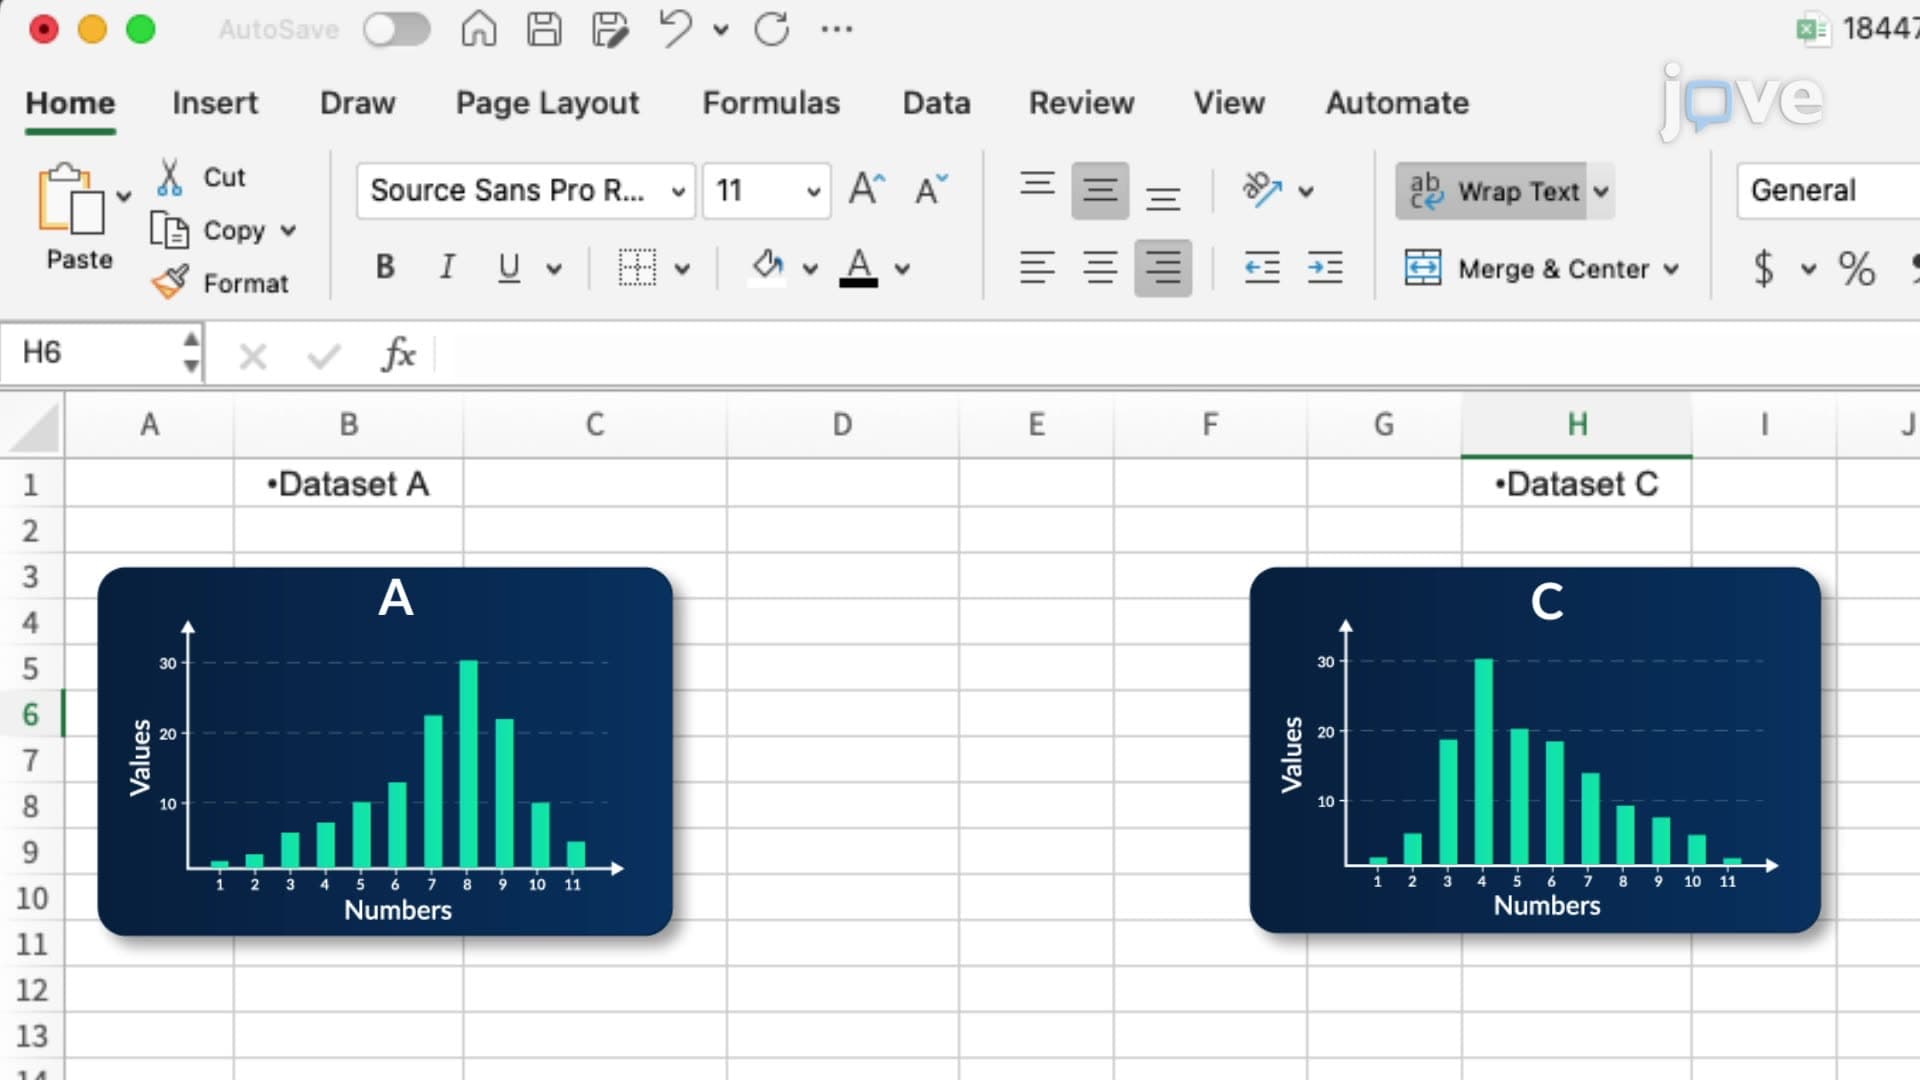
Microsoft Excel: Finding Central Tendency, Skew, and Kurtosis
224
Central tendency refers to the central point or typical value of a dataset. It summarizes the data set with a single value that represents the center of its distribution. The three main measures of central tendency are:
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
Mean: The arithmetic average of all data points. It is calculated by adding all the values together and dividing by the number of values. The mean is sensitive to extreme values (outliers).
Median: The middle value when the data points are arranged in ascending or descending...
224
 01:14
Wilcoxon Signed-Ranks Test for Median of Single Population
183
The Wilcoxon signed-rank test for the median of a single population is a nonparametric test used to evaluate whether the median of a population differs from a specified value. Unlike parametric tests, it does not require data to follow a normal distribution, making it suitable for non-normal or small samples. The test begins by calculating the difference (d) between each observation and the hypothesized median. The absolute values of these differences are ranked in ascending order, with ties...
183
 00:52
Pareto Chart
6.8K
A Pareto chart is a bar graph or a combination of both line and bar graphs. The bar lengths represent the individual values or the frequency, while the lines represent the cumulative total values. In this chart, the longest bars are arranged on the left and the shortest bars on the right, which makes it easier to read and interpret the data. It can also be called a Pareto diagram or Pareto analysis.
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
The Pareto chart is named after the Italian economist Vilfredo Pareto, who described the Pareto...
6.8K