通过社交网络分析,评估Twitter对新型COVID-19变种XBB.1.5的言论
Ikhwan Yuda Kusuma1, Hening Pratiwi2, Shafa Fitri Khairunnisa3,4
1Pharmacy Study Program, Faculty of Health, Universitas Harapan Bangsa, Purwokerto 53182, Indonesia.
Vaccine: X
|June 15, 2023

概括
对推特数据的社交网络分析显示,关键影响者正在讨论SARS-CoV-2 XBB.1.5 Omicron亚型. 大多数讨论都显示出积极的情绪,日本用户和科学来源占据了重要地位.
科学领域:
- 病毒学与公共卫生
- 社交网络分析 社交网络分析
- 计算社会科学 计算社会科学
背景情况:
- 这种SARS-CoV-2 Omicron亚型XBB.1.5呈现出增加的传染性和免疫逃避.
- 推特是信息传播和对新出现的COVID-19变种的公众评估的平台.
研究的目的:
- 分析社交网络动态,关键影响者,信息来源和围绕Twitter上COVID-19 XBB.1.5变种的情绪.
- 采用社交网络分析 (SNA) 来了解沟通模式,并识别XBB.1.5讨论中的有影响力的参与者.
主要方法:
- 使用关键字"XBB.1.5"和NodeXL.L.收集和清理推特数据
- 应用SNA指标 (中心性得分) 来识别关键用户和网络结构.
- 利用Gephi进行网络可视化和Azure机器学习进行情绪分析 (积极,消极,中立).
主要成果:
- 确定了43,394条与XBB.1.5相关的推文,其中"ojimakohei"作为一个高度核心的用户.
- 最重要的信息来源包括推特,日本网站 (.co.jp, .or.jp) 和科学存储库 (biorxiv.org,cdc.gov).
- 情绪分析显示主要是积极的 (61.35%),其次是中立的 (22.44%) 和负面的 (16.20%) 推文.
结论:
- 日本积极参与评估XBB.1.5变种,有影响力的用户发挥了重要作用.
- 偏爱经过验证的来源和积极的情绪表明使用者对健康的认识.
- 建议卫生组织,政府和影响者之间进行合作,以打击COVID-19错误信息.
相关概念视频
 01:18
Steps in Outbreak Investigation
155
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
155
 01:05
Single Nucleotide Polymorphisms-SNPs
15.3K
A single nucleotide polymorphism or SNP is a single nucleotide variation at a specific genomic position in a large population. It is the most prevalent type of sequence variation found in the human genome. Point mutations that occur in more than 1% of the population qualify as SNPs. These are present once every 1000 nucleotides on an average in the human genome. Replacement of a purine with another purine (A/G) or a pyrimidine with another pyrimidine (C/T) is known as a transition. In contrast,...
15.3K
 01:25
Statistical Methods for Analyzing Epidemiological Data
427
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
427
 01:29
Bias in Epidemiological Studies
380
Biases can arise at various stages of research, from study design and data collection to analysis and interpretation. Recognizing and addressing these biases is essential to ensure the validity and reliability of epidemiological findings.Broadly speaking, biases in epidemiology fall into three main categories: selection bias, information bias, and confounding. A more detailed description of possible biases is:
380
 01:11
Variability: Analysis
162
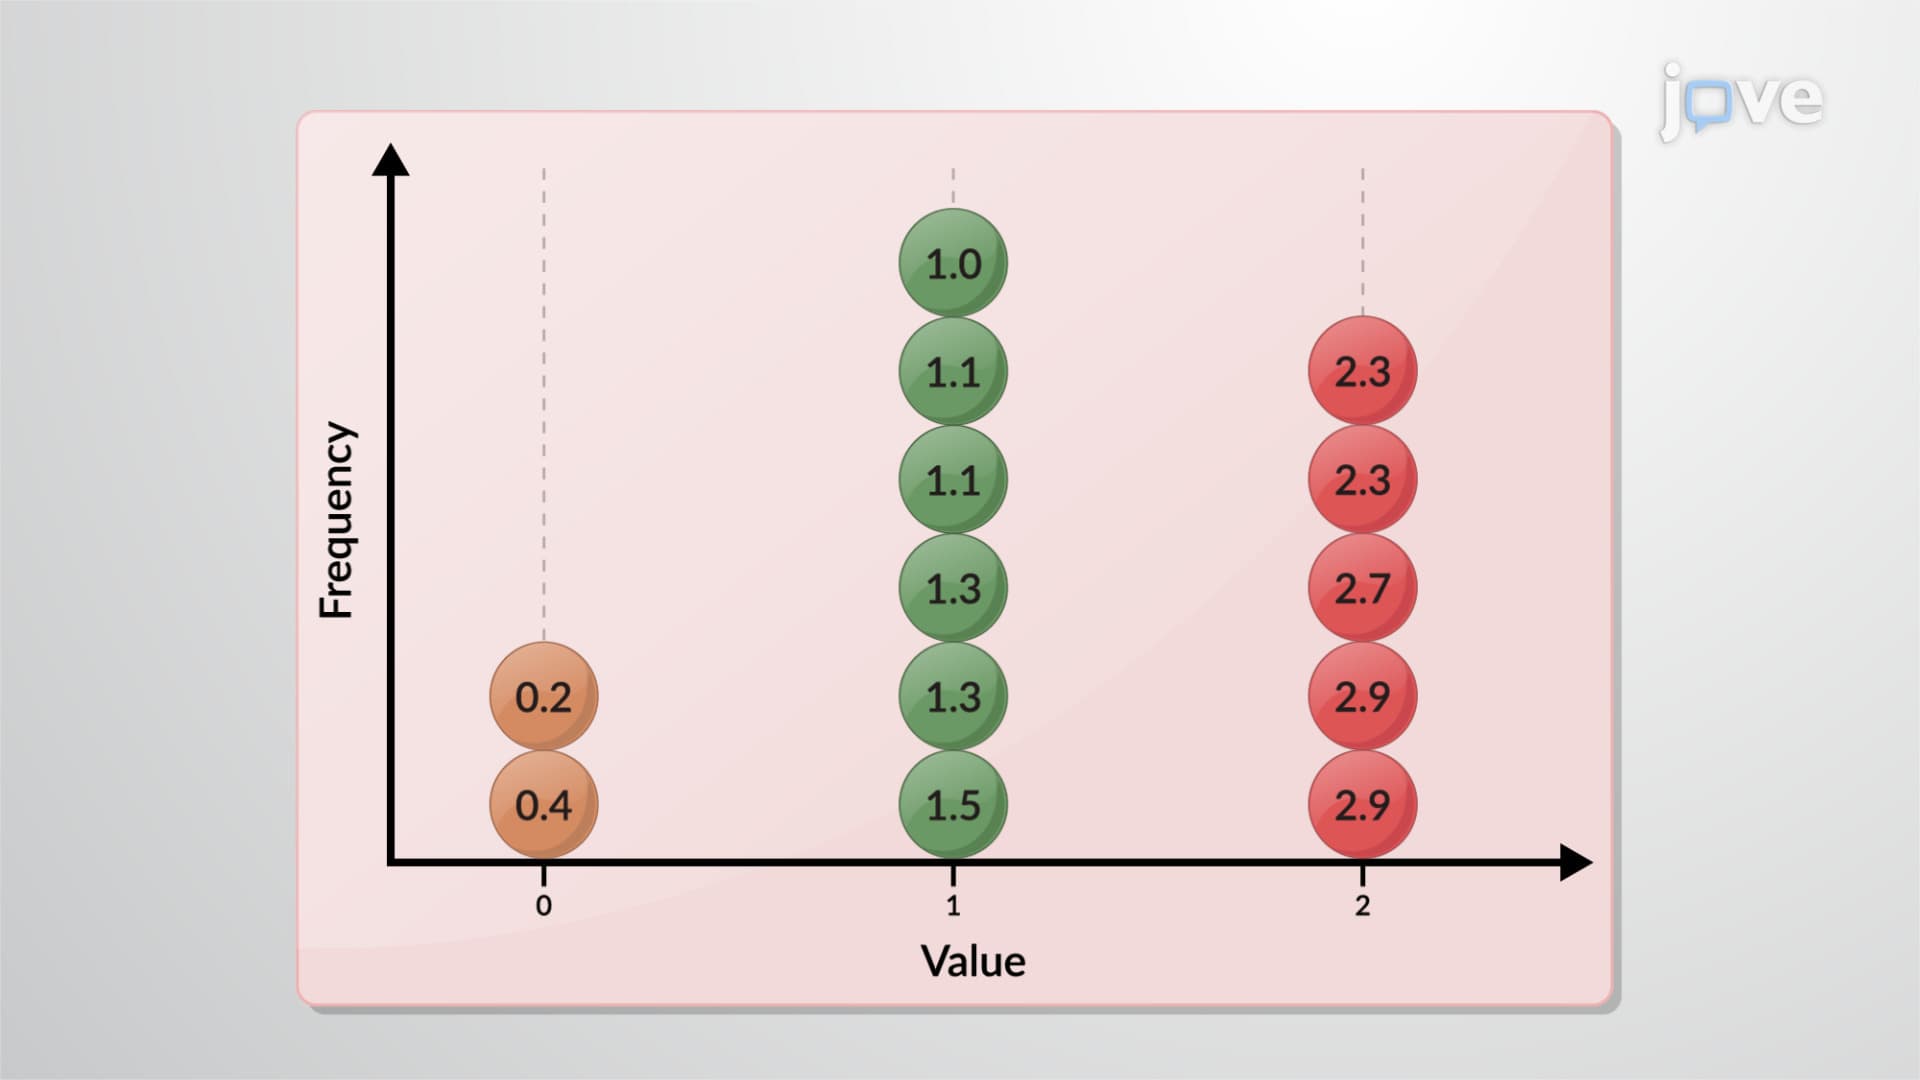
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
162
 01:21
Causality in Epidemiology
505
Causality or causation is a fundamental concept in epidemiology, vital for understanding the relationships between various factors and health outcomes. Despite its importance, there's no single, universally accepted definition of causality within the discipline. Drawing from a systematic review, causality in epidemiology encompasses several definitions, including production, necessary and sufficient, sufficient-component, counterfactual, and probabilistic models. Each has its strengths and...
505