

验证捷克语音残疾指数版本的验证
Jana Krtickova1, Jan G Svec2, Jiri Haviger3
1Department of Otorhinolaryngology and Head and Neck Surgery, University Hospital Hradec Kralove, Hradec Kralove, Czech Republic; Faculty of Medicine in Hradec Kralove, Charles University, Hradec Kralove, Czech Republic.

概括
捷克语音障碍指数 (VHI-CZ) 在评估语音障碍时表现出卓越的可靠性和构造有效性. 截止分数为13有效地区分了失声和非失声个体.
科学领域:
- 耳鼻喉科 耳鼻喉科 耳鼻喉科
- 语音语言病理学 语言病理学
- 心理测量 心理测量 心理测量
背景情况:
- 失声症显著影响生活质量.
- 验证的评估工具对于临床实践至关重要.
- 语音障碍指数 (VHI) 被广泛使用,但需要特定语言的验证.
研究的目的:
- 评估语音障碍指数 (VHI-CZ) 的捷克版本的可靠性和构造有效性.
- 建立一个切断分数来区分听障患者与健康个体.
主要方法:
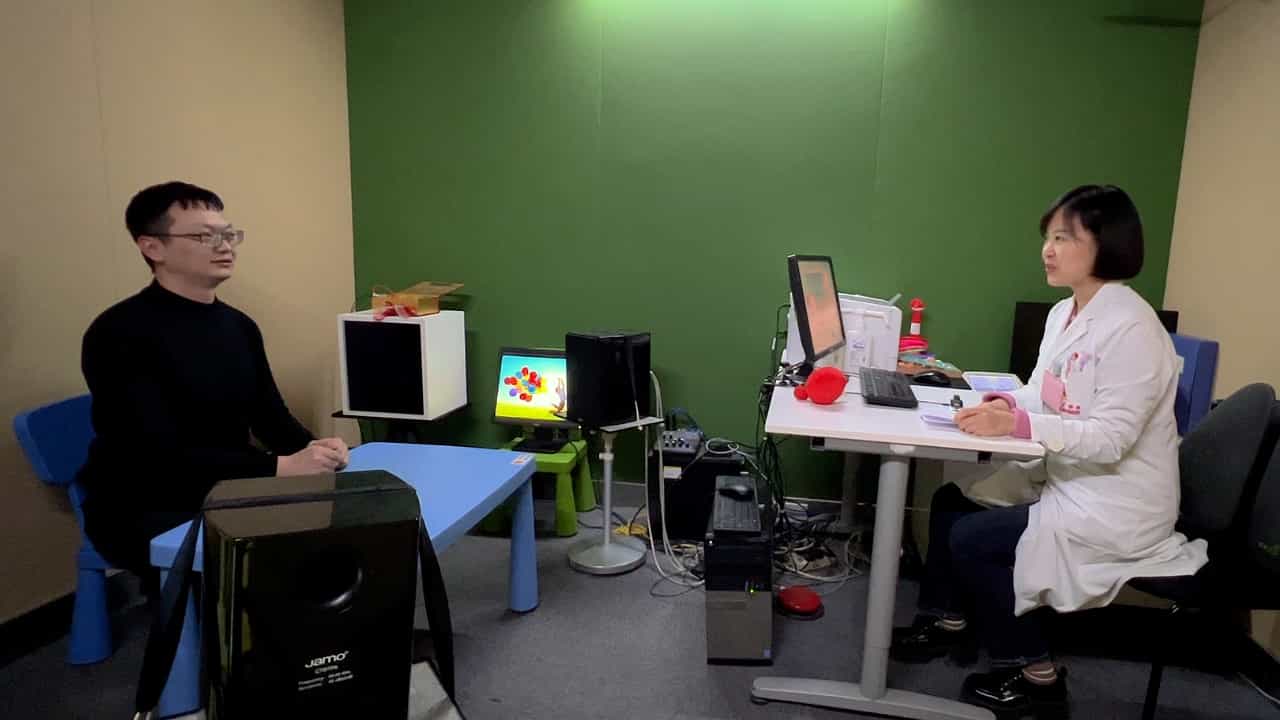
- 一项前性研究,共有151名参与者 (100名患有听力障碍,51名对照).
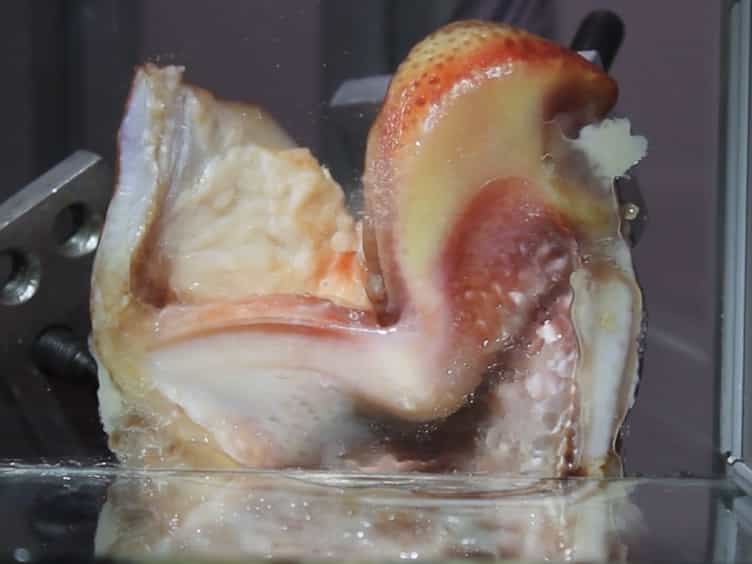
- 提供VHI-CZ,视频鼻喉透镜和统计分析,包括Cronbach的alpha和ICC.
- 评估了测试复试可靠性和构造有效性.
主要成果:
- 优异的内部一致性 (克朗巴赫的α=0.984) 和测试重试可靠性 (ICC=0.95).
- 自我评估严重程度和VHI-CZ得分之间存在强烈的相关性 (ρ = 0.877).
- 确定了13分的切断点数来区分失声个体.
结论:
- VHI-CZ是评估捷克语人口中语音障碍的可靠和有效工具.
- 它显示出出色的心理测量特性和临床实用性.
- 建立的切断值得分有助于预先选择患有听障症的患者.
相关概念视频
 02:07
Blind Procedures
10.7K
Ideally, the people who observe and record the children’s behavior are unaware of who was assigned to the experimental or control group, in order to control for experimenter bias. Experimenter bias refers to the possibility that a researcher’s expectations might skew the results of the study. Remember, conducting an experiment requires a lot of planning, and the people involved in the research project have a vested interest in supporting their hypotheses. If the observers knew which...
10.7K
 00:57
Behrens–Fisher Test
108
The Behrens-Fisher test is a statistical method designed to address the Behrens-Fisher problem, which arises when comparing the means of two normally distributed populations with unequal variances. Unlike the Student's t-test, which assumes equal variances, the Behrens-Fisher test allows for mean comparison without this restrictive assumption. This flexibility makes it particularly valuable in scenarios where two independent samples exhibit normality but lack variance homogeneity.
This test...
This test...
108
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.6K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.6K