重温电影经济成功的预测:随机森林应用于利
Thaís Luiza Donega E Souza1, Marislei Nishijima2, Ricardo Pires3
1Information Systems Department, University of São Paulo, 1000, Arlindo Béttio - Ermelino Matarazzo, 03828-000, Room: L1 - 327, São Paulo, SP Brazil.
Multimedia tools and applications
|June 26, 2023

概括
机器学习模型使用通货膨胀调整后的利和早期生产数据预测电影的经济成功. 随机森林获得了97%的准确性,超过了以前的研究,以更好的电影制作决策.
科学领域:
- *计算经济学和娱乐行业分析.
- * 机器学习在财务预测中的应用.
背景情况:
- *以前的机器学习 (ML) 研究旨在预测电影的成功,减少生产的不确定性.
- *现有的模型经常使用名义的票房收入和发布后可用的数据.
研究的目的:
- *通过解决先前研究的局限性来改善电影经济成功分类.
- *分析数据采样 (时间,释放类型) 对预测准确性的影响.
- *使用无通胀的利指标和发布前数据,以提供更实用的生产者指导.
主要方法:
- *使用了来自Box Office Mojo的3167部公开预算的电影 (1980-2019) 的数据集.
- *使用随机森林,支持向量机和神经网络分类器.
- *使用不同的基于时间的数据样本和释放类型 (总和宽) 进行模型性能比较.
主要成果:
- *随机森林分类器表现出卓越的性能,达到97%的准确性和F1分数.
- *经通货膨胀调整后的利比名义收入更准确地衡量经济成功.
- *使用生产时可用的功能增强了模型的实用性.
结论:
- * 机器学习,特别是随机森林,可以有效地利用早期数据和经通胀调整的利预测电影的经济成功.
- *这些发现为生产者提供了宝贵的见解,以减轻财务风险和优化决策.
- *与以前的方法相比,这项研究为预测电影成功提供了更强大和更实用的方法.
相关概念视频
 01:19
Survival Tree
117
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
117
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:07
Residual Plots
4.7K
A residual plot is a statistical representation of data used to analyze correlation and regression results. It helps verify the requirements for drawing specific conclusions about correlation and regression. To obtain the residual plot, first, the residual for each data value is calculated, which is simply the vertical distance between the observed and the predicted value obtained from the regression equation.
When the residual values are plotted against the variable x, it is called a residual...
When the residual values are plotted against the variable x, it is called a residual...
4.7K
 01:08
Outliers and Influential Points
4.1K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.1K
 01:18
Microsoft Excel: Regression Analysis
711
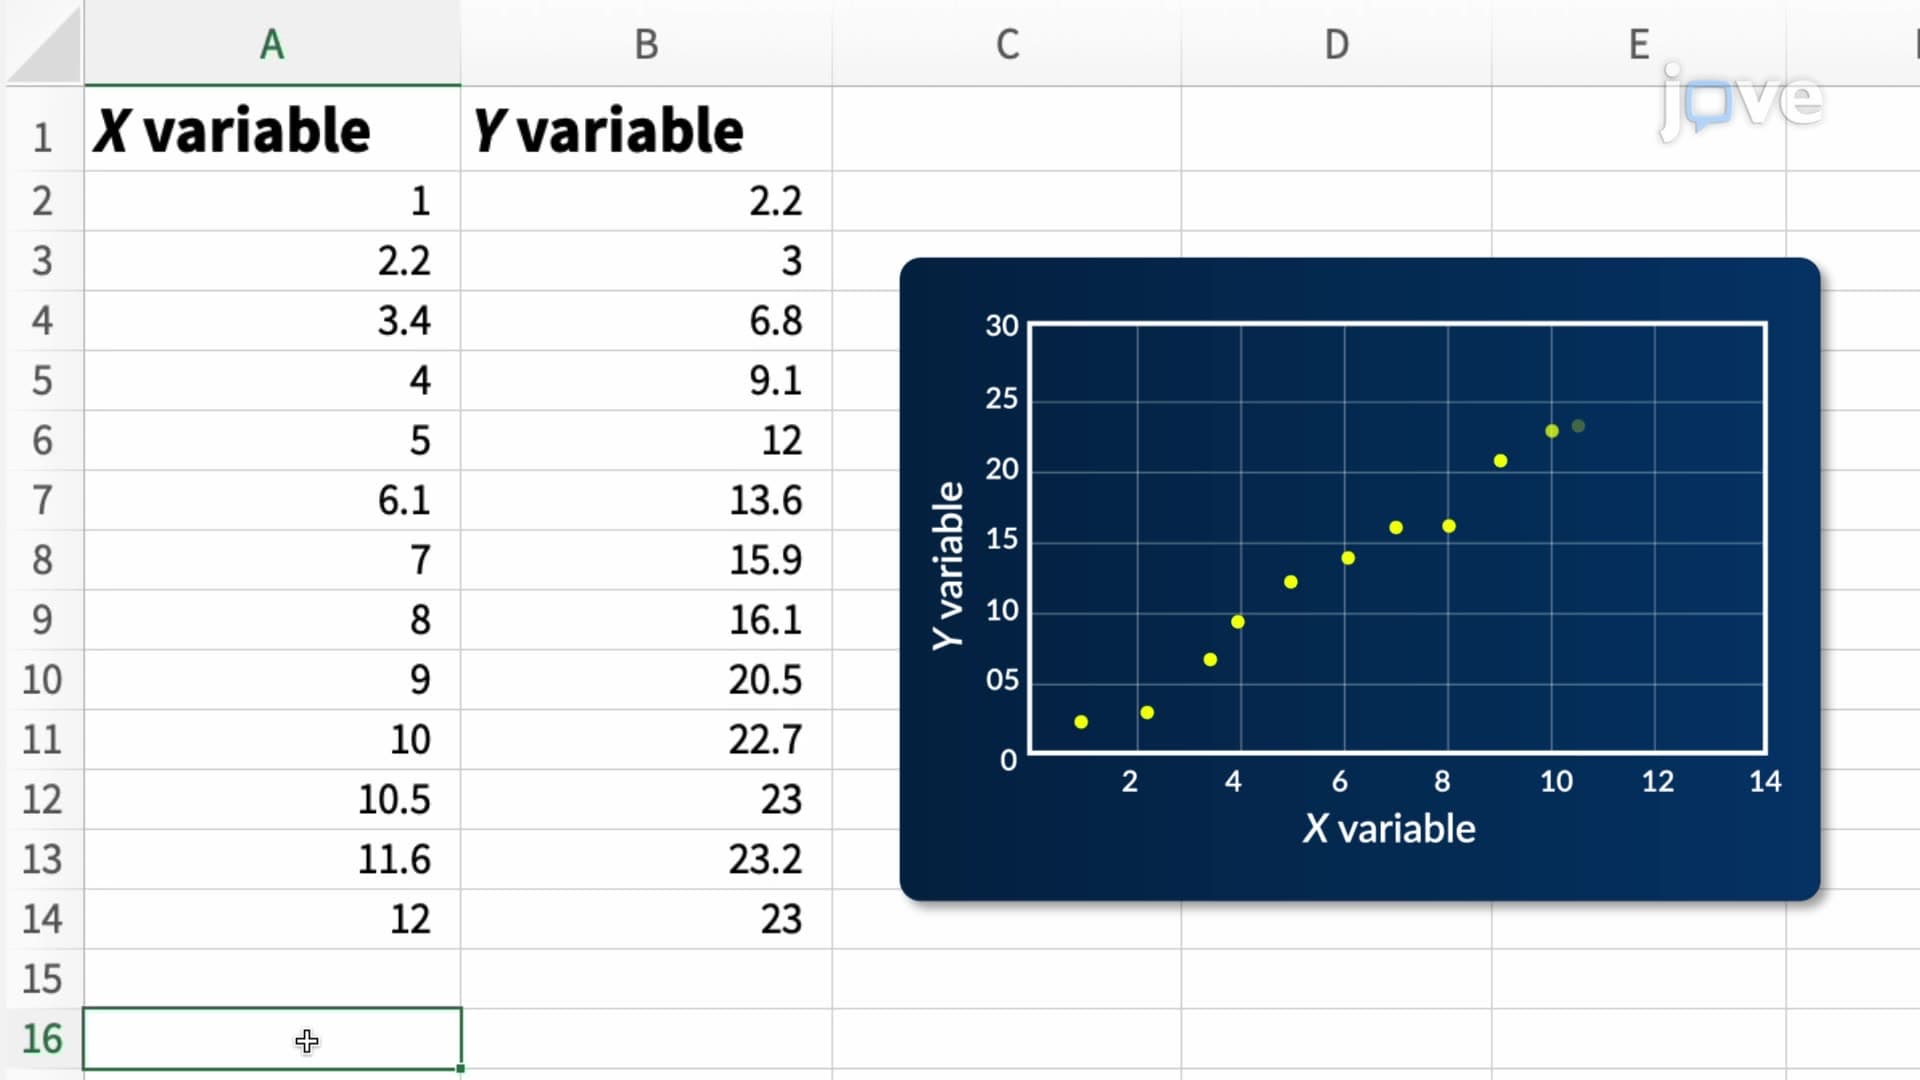
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
711