使用决策树,人工神经网络和物流回归对牛犊每日体重增加的分类
Wilhelm Grzesiak1, Daniel Zaborski1, Renata Pilarczyk1
1Department of Ruminants Science, West Pomeranian University of Technology, Klemensa Janickiego 29, 71-270 Szczecin, Poland.
Animals : an open access journal from MDPI
|June 28, 2023

概括
机器学习模型有效地对牛犊的每日体重增加进行分类. 关键预测因素包括大.
科学领域:
- 动物科学动物科学
- 机器学习 机器学习
- 预测分析是一种预测分析.
背景情况:
- 准确预测牛肉小牛的每日体重增加对于优化畜牧管理和经济结果至关重要.
- 传统方法可能无法完全捕捉影响小牛生长的因素的复杂相互作用.
研究的目的:
- 为了比较决策树,人工神经网络和物流回归的预测性能,用于分类牛犊的每日体重增加.
- 为了确定影响西蒙特尔和利莫辛品种断奶前每日体重增加的关键预测因素.
主要方法:
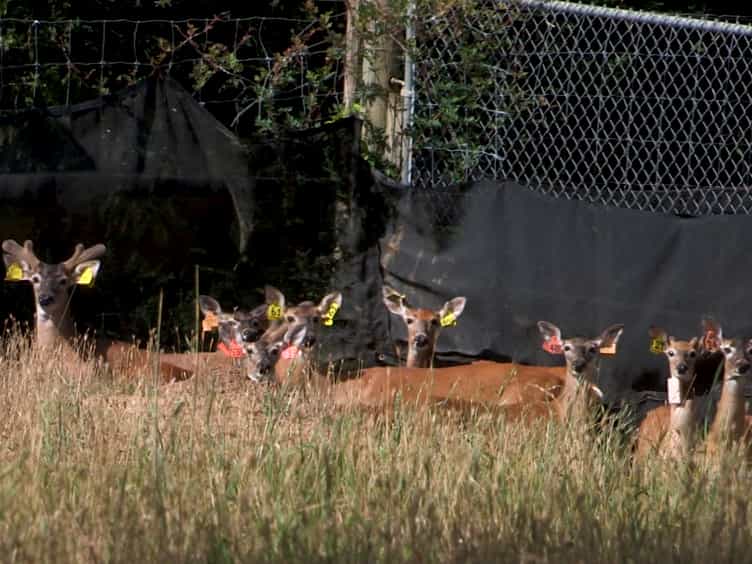
- 利用了2014年至2016年间肥的680头西蒙塔尔和373头利莫辛奶牛及其小牛的数据集.
- 开发并比较机器学习模型 (决策树,ANN,后勤回归,随机森林) 以将每日体重增加分为两个类别 (低于或高于品种/性别特定平均值).
- 在测试组上使用灵敏度,特异性,精度和AUC评估模型性能.
主要成果:
- 随机森林模型显示了Limousin (精度0.76,AUC 0.82) 和Simmental (精度0.78,AUC 0.81) 品种的强大预测性能.
- 重要的预测因素包括大自己的生长历史,以前的小牛表现,小牛的性别,大的牛奶产量,出生体重和大的身体特征.
结论:
- 机器学习模型,特别是随机森林,为分类牛犊每日体重增加提供了有效的工具.
- 鉴定的预测因素为育种计划和早期管理干预提供了宝贵的见解,以提高小牛的生长.
相关概念视频
 01:26
Classification of Systems-I
221
Linearity is a system property characterized by a direct input-output relationship, combining homogeneity and additivity.
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
221
 01:31
Classification of Systems-II
183
Continuous-time systems have continuous input and output signals, with time measured continuously. These systems are generally defined by differential or algebraic equations. For instance, in an RC circuit, the relationship between input and output voltage is expressed through a differential equation derived from Ohm's law and the capacitor relation,
183
 01:11
Regression Analysis
5.8K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.8K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:30
Classification of Signals
556
In signal processing, signals are classified based on various characteristics: continuous-time versus discrete-time, periodic versus aperiodic, analog versus digital, and causal versus noncausal. Each category highlights distinct properties crucial for understanding and manipulating signals.
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
556
 01:29
Aggregates Classification
350
Aggregate classification is generally based on its size, petrographic characteristics, weight, and source. Size classification ranges from coarse to fine aggregates, defined by the size of the particles. Coarse aggregates are particles that do not pass through ASTM sieve No. 4, and aggregates that pass through the sieve are fine aggregates.
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
Petrographic classification groups aggregates based on common mineralogical characteristics. Some of the common mineral groups found in aggregates are...
350