

COVID-19 ICU 死亡率预测:使用 SuperLearner 算法进行机器学习方法
Giulia Lorenzoni1, Nicolò Sella2, Annalisa Boscolo3
1Unit of Biostatistics, Epidemiology and Public Health, Department of Cardiac, Thoracic, Vascular Sciences, and Public Health, University of Padova, Padova, Italy.
Journal of anesthesia, analgesia and critical care
|June 29, 2023

概括
机器学习模型准确地预测了2019年冠状病毒病 (COVID-19) 患者的重症监护室 (ICU) 死亡率. 在所有开发的模型中,年龄是最重要的预测因素,为临床评估提供了可靠的工具.
科学领域:
- 关键护理医学 关键护理医学
- 医疗保健中的机器学习
- 传染病 流行病学 流行病学
背景情况:
- 由于诊断,治疗和预后的不确定性,COVID-19流行病的早期阶段强调了对预测模型的需求.
- 开发可靠的工具来预测患者的结果对于有效的资源分配和重症监护室 (ICU) 的临床决策至关重要.
研究的目的:
- 开发和验证用于预测COVID-19患者的ICU死亡率的机器学习模型.
- 确定关键临床参数,这些参数显著影响COVID-19重病患者的死亡风险.
主要方法:
- 一项观察性多中心队列研究招募了成年COVID-19患者,这些患者被录入VENETO ICU网络内的25个ICU.
- 超级学习机器学习算法用于模型开发,利用临床变量,如年龄,并发病症和器官支持.
- 内部验证使用训练集 (n=1293),外部验证使用两个独立的测试集 (n=124和n=199).
主要成果:
- 开发了三种不同的预测模型,证明了可比的预测性能,训练平衡精度从0.72到0.90.
- 交叉验证性能在0.75和0.85之间变化,这表明模型具有强大的通用性.
- 在所有开发的模型中,年龄成为ICU死亡率的最有影响力的预测因素.
结论:
- 该研究成功开发了一种可靠的机器学习工具,用于预测COVID-19患者的ICU死亡率.
- 年龄被确定为影响死亡风险的主要临床变量,强调其在风险分层中的重要性.

相关概念视频
 01:07
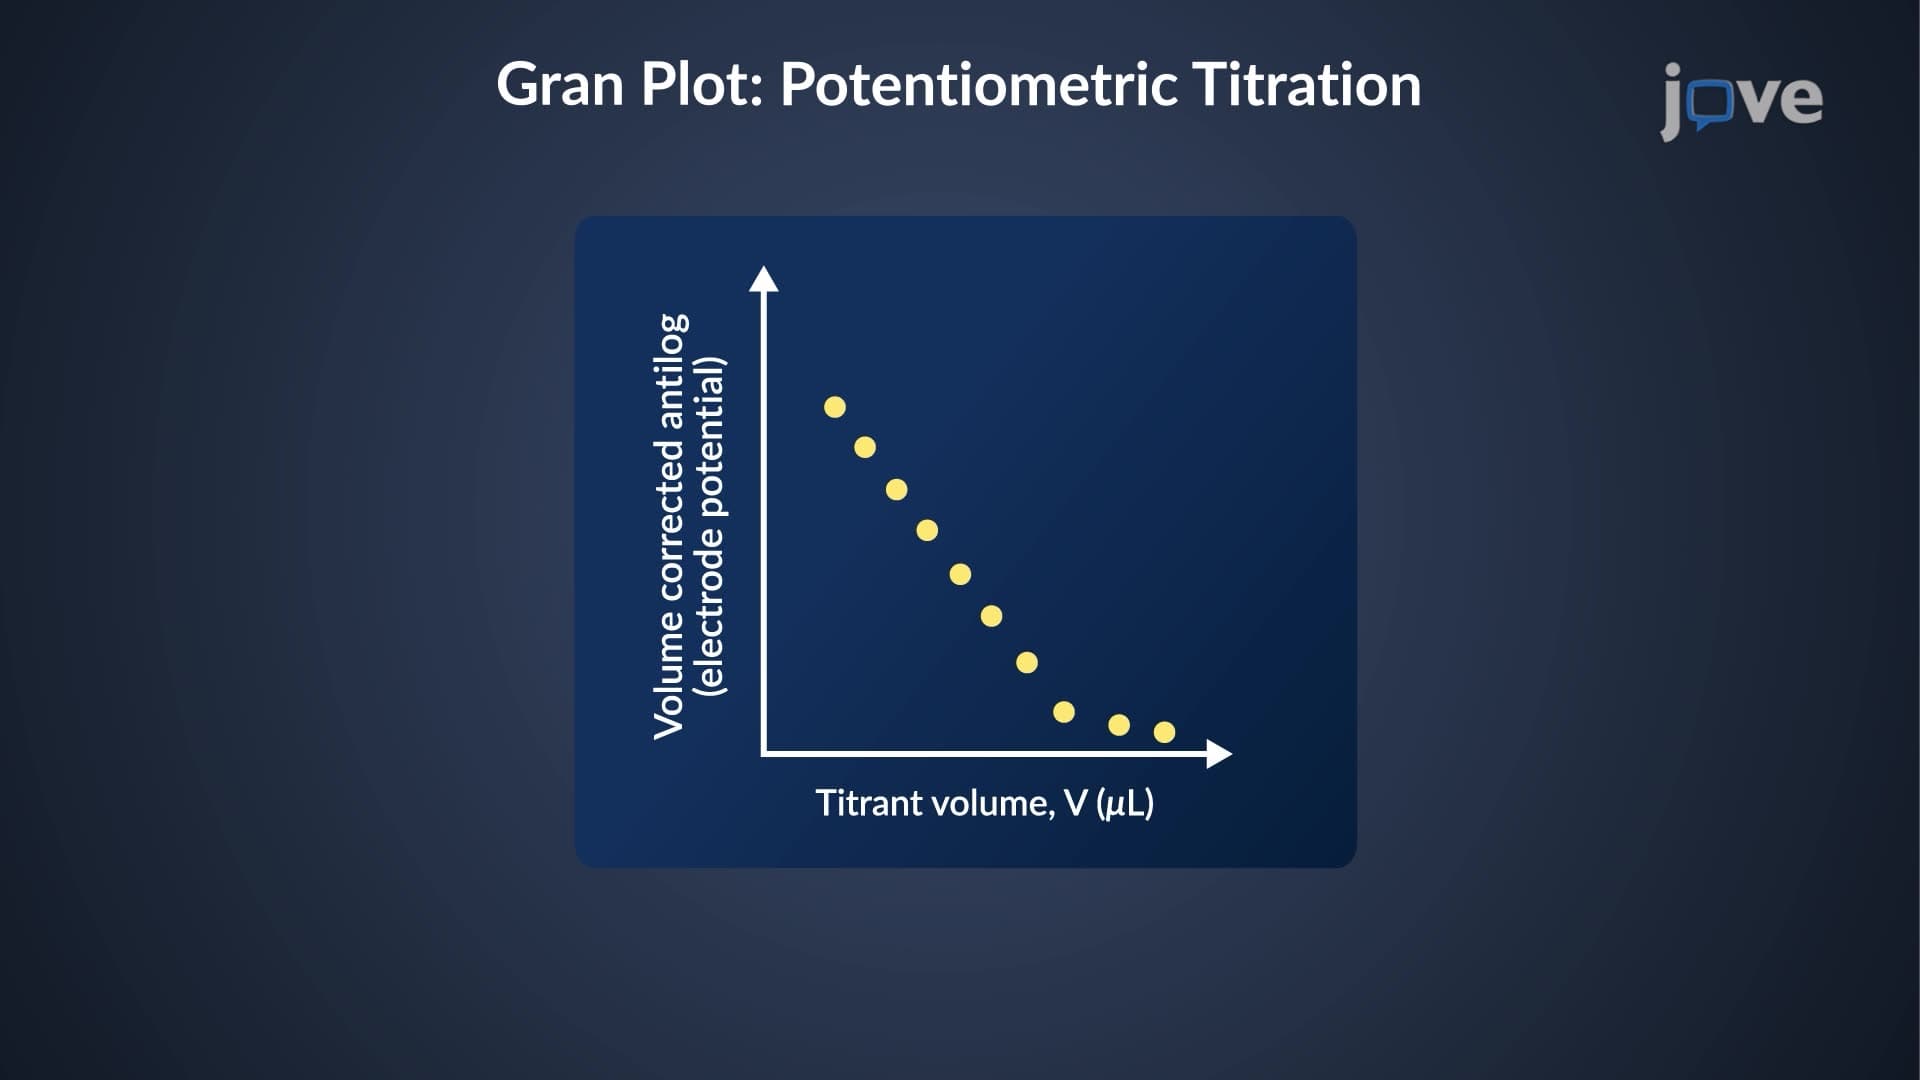
End Point Prediction: Gran Plot
388
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
388
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:21
Cancer Survival Analysis
397
Cancer survival analysis focuses on quantifying and interpreting the time from a key starting point, such as diagnosis or the initiation of treatment, to a specific endpoint, such as remission or death. This analysis provides critical insights into treatment effectiveness and factors that influence patient outcomes, helping to shape clinical decisions and guide prognostic evaluations. A cornerstone of oncology research, survival analysis tackles the challenges of skewed, non-normally...
397
 01:24
Kaplan-Meier Approach
190
The Kaplan-Meier estimator is a non-parametric method used to estimate the survival function from time-to-event data. In medical research, it is frequently employed to measure the proportion of patients surviving for a certain period after treatment. This estimator is fundamental in analyzing time-to-event data, making it indispensable in clinical trials, epidemiological studies, and reliability engineering. By estimating survival probabilities, researchers can evaluate treatment effectiveness,...
190
 01:15
Assumptions of Survival Analysis
157
Survival models analyze the time until one or more events occur, such as death in biological organisms or failure in mechanical systems. These models are widely used across fields like medicine, biology, engineering, and public health to study time-to-event phenomena. To ensure accurate results, survival analysis relies on key assumptions and careful study design.
157
 02:07
Improving Translational Accuracy
11.7K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
11.7K