
使用PFEEL算法与高斯过程回归模型进行撞击的概率检测
Yohanna MejiaCruz1, Juan M Caicedo1, Zhaoshuo Jiang2
1University of South Carolina, Columbia SC, 29208, United States.
Engineering structures
|June 30, 2023

概括
本研究引入了一种新的数据驱动方法,用于使用概率力估计和事件定位 (PFEEL) 算法识别人类活动. 增强的PFEEL方法提高了冲击力和事件位置的准确性,在各种应用中具有可量化的不确定性.
科学领域:
- 机械工程 机械工程
- 信号处理 信号处理
- 机器学习 机器学习
背景情况:
- 人类活动识别对于安全,事件检测,智能环境和健康监测至关重要.
- 现有的方法通常使用波传播或结构动力学,面临诸如多路径色等挑战.
- 基于力的方法,如PFEEL,通过估计冲击力和位置的不确定性来提供优势.
研究的目的:
- 介绍PFEEL算法的一种新型数据驱动实现.
- 利用高斯过程回归 (GPR) 来提高力和事件定位精度.
- 用实验性影响数据评估新的PFEEL实施的性能.
主要方法:
- 开发了一个使用高斯过程回归 (GPR) 的新PFEEL实现.
- 从一块板上收集的实验数据,经过81个不同的冲击点 (5厘米的距离).
- 通过将估计的撞击位置与各种概率级别的实际位置进行比较,分析了定位准确性.
主要成果:
- 数据驱动的PFEEL方法证明了有效的冲击力和事件定位.
- 结果量化了相对于不同概率值的实际冲击点的定位区域.
- 基于GPR的PFEEL提供了一定的不确定性,有助于精确确定实际应用.
结论:
- 基于GPR的PFEEL提供了一种强大而准确的方法,通过影响分析来识别人类活动.
- 这种方法解决了传统波传播方法的局限性.
- 定位的量化不确定性有助于分析师为特定的PFEEL应用选择合适的精度水平.
相关概念视频
 01:18
Steps in Outbreak Investigation
154
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
154
 01:09
Decision Making: P-value Method
5.5K
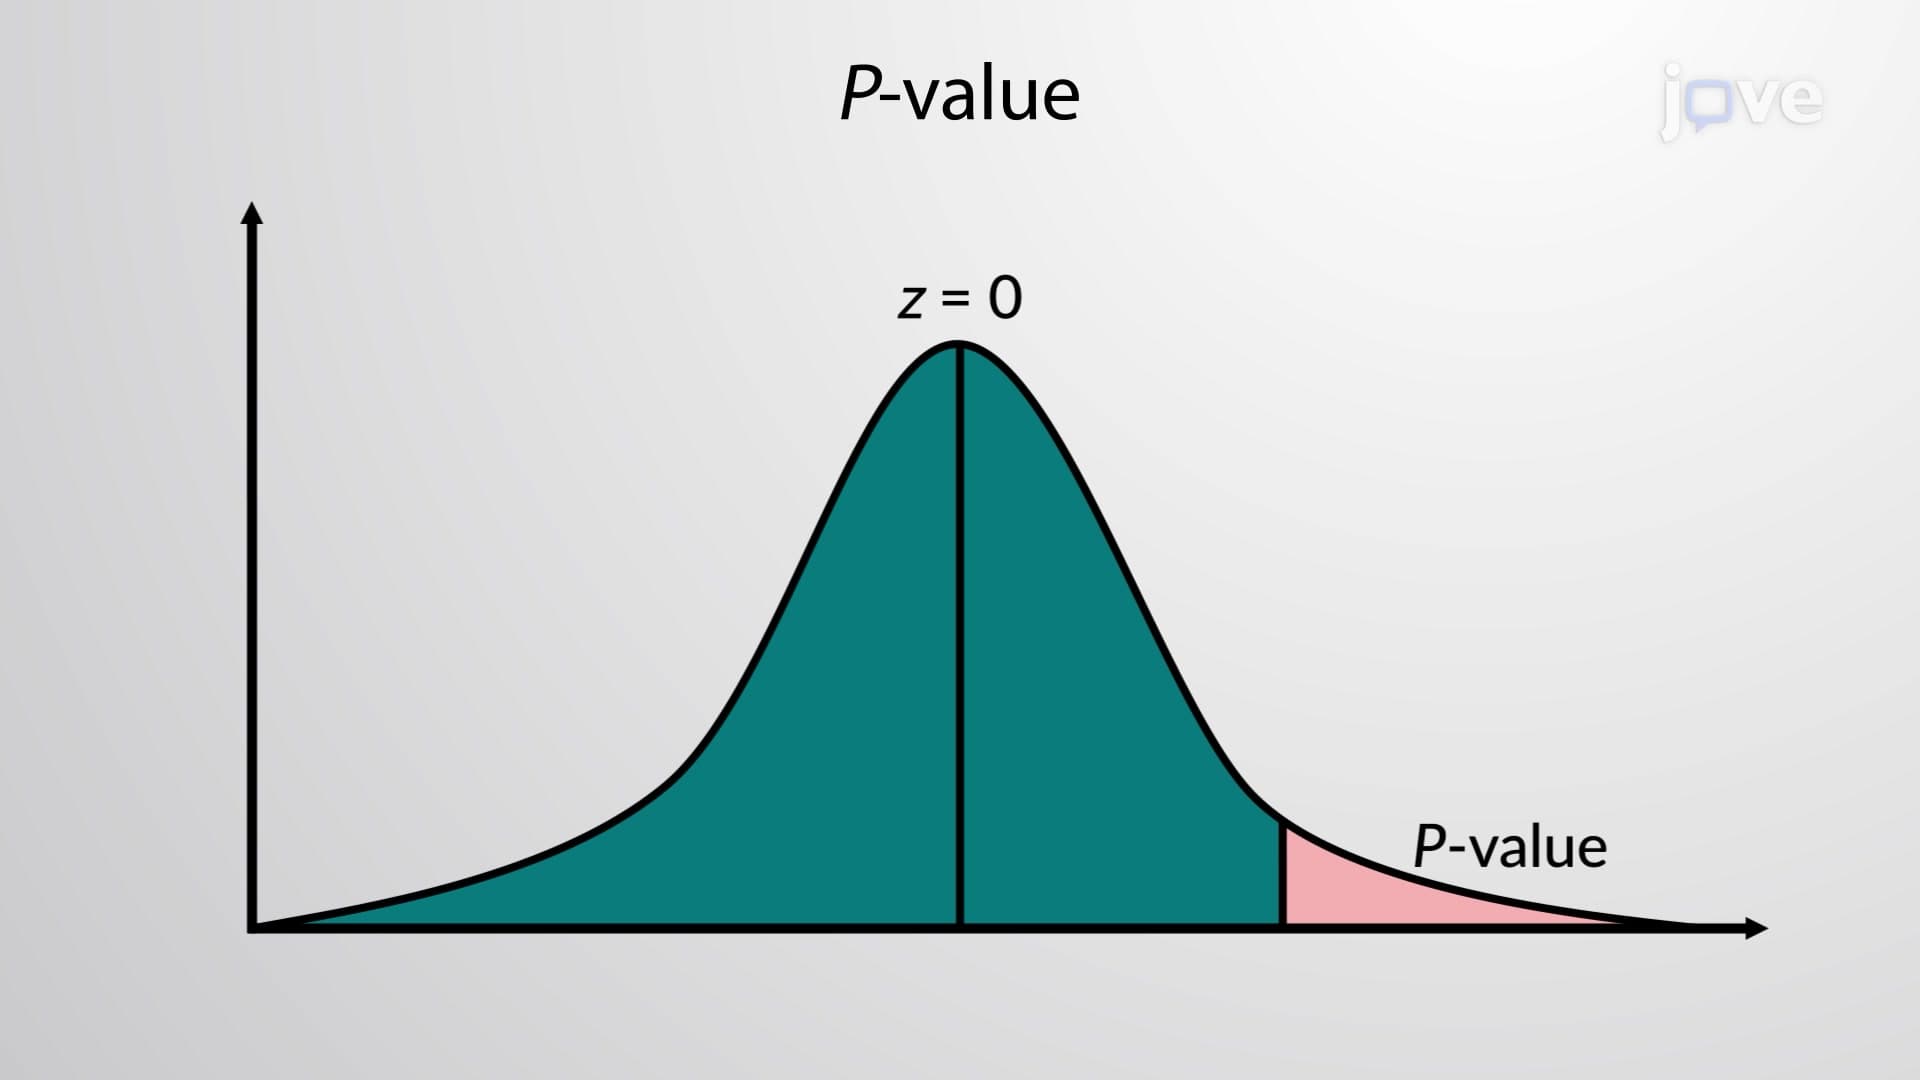
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
5.5K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.7K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.7K
 01:08
Determination of Expected Frequency
2.2K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.2K
 01:00
Detection of Gross Error: The Q Test
6.3K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.3K
 01:04
Random Error
932
Random or indeterminate errors originate from various uncontrollable variables, such as variations in environmental conditions, instrument imperfections, or the inherent variability of the phenomena being measured. Usually, these errors cannot be predicted, estimated, or characterized because their direction and magnitude often vary in magnitude and direction even during consecutive measurements. As a result, they are difficult to eliminate. However, the aggregate effect of these errors can be...
932