
监督学习和模型分析与组成数据
Shimeng Huang1, Elisabeth Ailer2, Niki Kilbertus2,3
1Department of Mathematical Sciences, University of Copenhagen, Copenhagen, Denmark.
PLoS computational biology
|June 30, 2023

概括
KernelBiome是一个新的机器学习框架,用于分析稀疏的组成微生物群数据. 它为复杂的生物信号提供了改进的预测和新的解释方法.
科学领域:
- 微生物组研究的研究.
- 机器学习 机器学习
- 生物信息学是一种生物信息学.
背景情况:
- 监督学习对于高通量测序数据分析至关重要,特别是在微生物组研究中.
- 现有的方法在组成和稀疏的数据上扎,缺乏可解释性或捕获复杂信号的能力.
- 线性日志对比模型和黑盒机器学习方法在处理这些数据特征方面存在局限性.
研究的目的:
- 引入KernelBiome,这是一个基于内核的非参数框架,用于组合数据的回归和分类.
- 解决微生物组数据分析中稀疏性和组成性的挑战.
- 提供一个框架,可以纳入先前的知识,如族系结构.
主要方法:
- KernelBiome使用基于内核的非参数方法,适用于稀疏的组成数据.
- 该框架结合了先前的知识,如家族遗传关系,以增强分析.
- 它捕获复杂的信号,包括零结构,并自适应地管理模型的复杂性.
主要成果:
- 与最先进的方法相比,KernelBiome在33个微生物组数据集中显示出具有竞争力或优异的预测性能.
- 提出了新的解释量,将线性模型的可解释性扩展到非参数设置.
- 该框架的内核和距离之间的连接促进了可解释性,并使数据驱动的嵌入成为可能.
结论:
- 核心生物组为分析稀疏的组成微生物组数据提供了一种强大而可解释的解决方案.
- 该框架提高了预测准确性,同时提供了对组件贡献的新见解.
- 作为一个开源的Python包,KernelBiome可用,促进了更广泛的采用和进一步的研究.
相关概念视频
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
65
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
65
 01:20
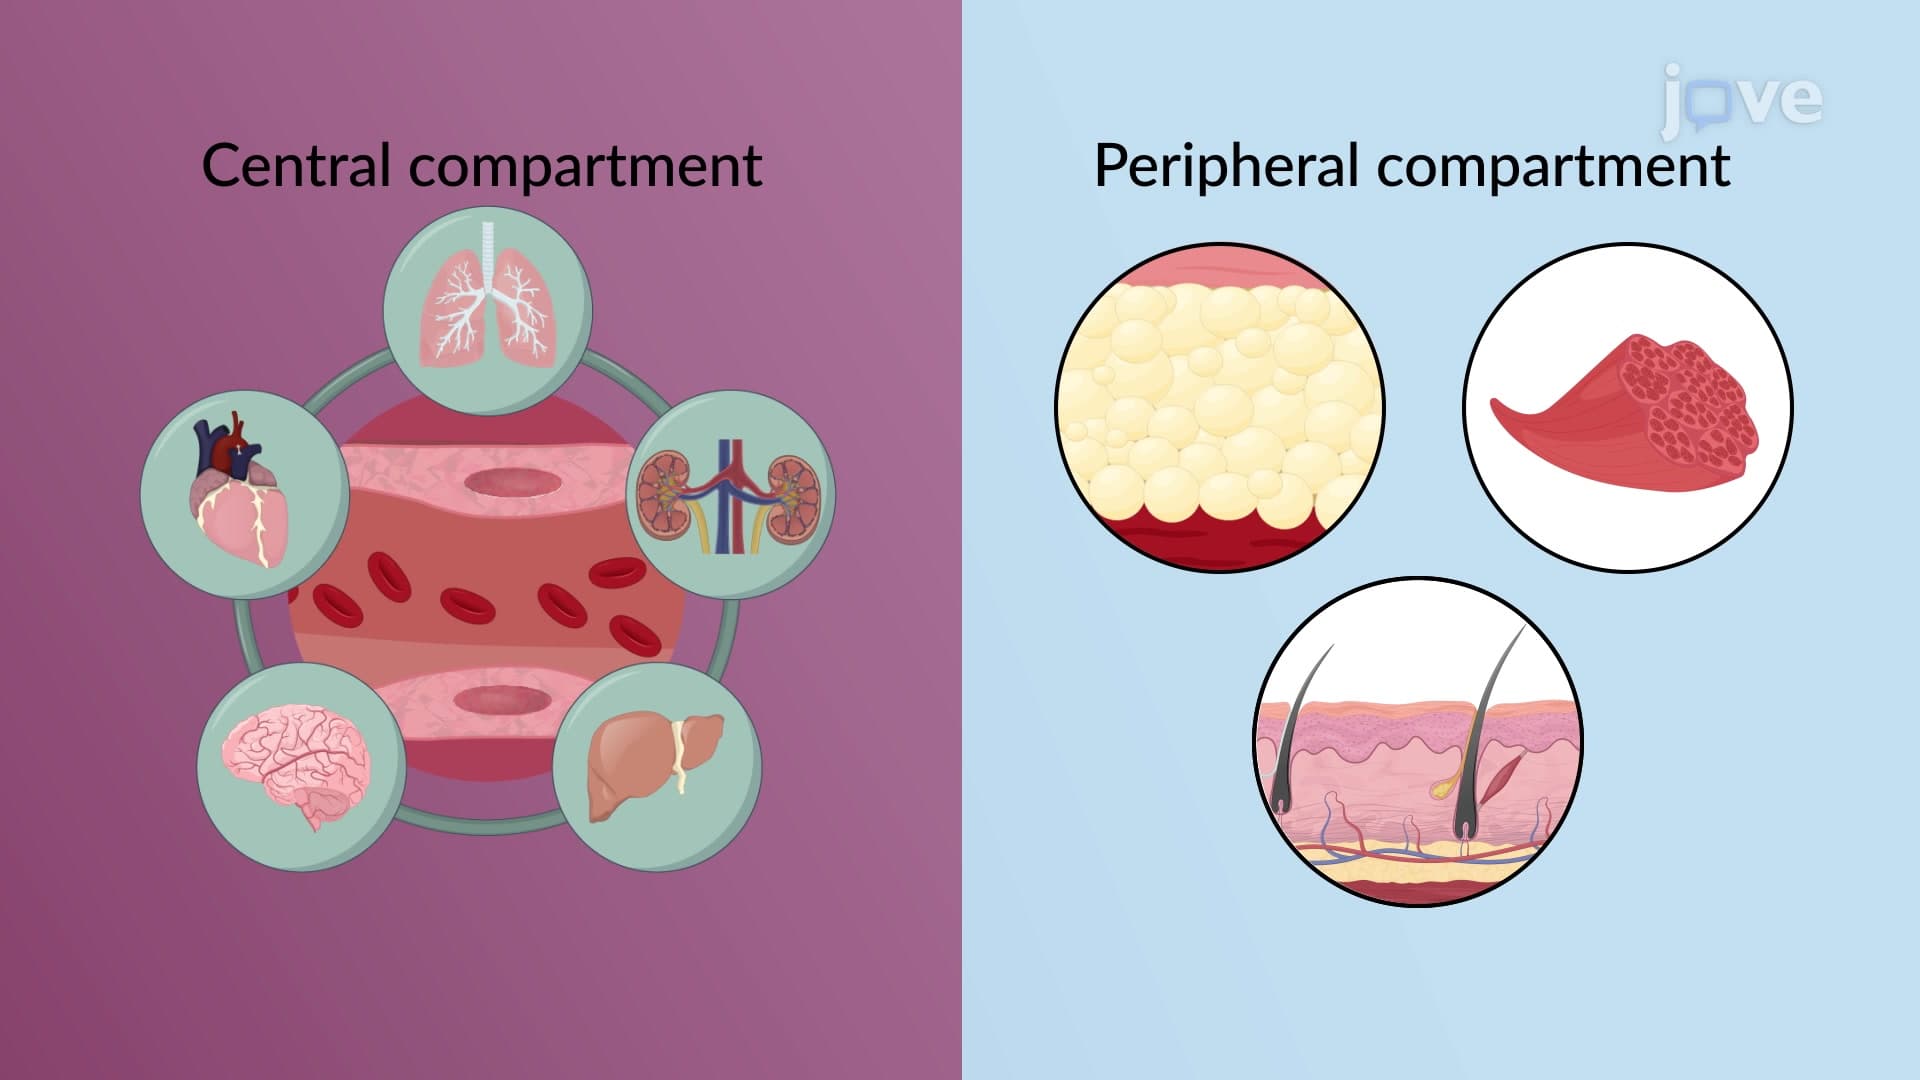
Compartment Models: Two-Compartment Model
5.7K
The two-compartment model divides the body into central and peripheral compartments to account for varying blood perfusion rates among organs and tissues, affecting drug distribution. The central compartment includes blood and highly perfused tissues with rapid drug distribution, while the peripheral compartment contains tissues with slower drug distribution. After a single IV bolus dose, the drug concentration is high in plasma and low in tissues. The drug distribution between compartments...
5.7K
 01:11
Regression Analysis
5.8K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.8K
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
81
Mechanistic models play a crucial role in algorithms for numerical problem-solving, particularly in nonlinear mixed effects modeling (NMEM). These models aim to minimize specific objective functions by evaluating various parameter estimates, leading to the development of systematic algorithms. In some cases, linearization techniques approximate the model using linear equations.
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
81
 01:14
Compartment Models: Single-Compartment Model
2.3K
The single-compartment model serves as a simplified representation of the human body. This model assumes that the body functions as a single, well-mixed open compartment. When a drug is administered intravenously, it enters the body and quickly distributes uniformly. The drug then undergoes biotransformation and elimination, ultimately leaving the body. The volume of this compartment is referred to as the apparent volume of distribution into which the drug can uniformly distribute. In this...
2.3K
 01:11
Statistical Analysis: Overview
6.7K
When we take repeated measurements on the same or replicated samples, we will observe inconsistencies in the magnitude. These inconsistencies are called errors. To categorize and characterize these results and their errors, the researcher can use statistical analysis to determine the quality of the measurements and/or suitability of the methods.
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
6.7K