

在经济理论的背景下预测比特币 (BTC) 价格:一种机器学习方法
Sahar Erfanian1, Yewang Zhou1, Amar Razzaq1
1Business School, Huanggang Normal University, No. 146 Xinggang 2nd Road, City Development Zone, Huanggang 438000, China.
Entropy (Basel, Switzerland)
|July 8, 2023

概括
这项研究使用机器学习和经济理论预测比特币 (BTC) 价格. 支持向量回归 (SVR) 证明在准确的BTC价格预测方面优越,优于传统模型.
科学领域:
- 金融经济学 金融经济学
- 计算金融是指计算金融.
- 计量经济学 计量经济学
背景情况:
- 比特币 (BTC) 是第一个加密货币,由于其分散和任意的性质,它面临着定价挑战,导致市场怀疑.
- 目前关于BTC价格预测的研究往往缺乏强大的分析和理论基础.
- 需要探索机器学习的潜力与准确的BTC价格预测的统计方法相比.
研究的目的:
- 通过将宏观经济和微观经济理论与先进的机器学习技术相结合,解决BTC价格预测问题.
- 根据既定的经济理论,研究宏观经济,微观经济,技术和区块链指标的预测能力.
- 为了比较各种机器学习模型 (Ensemble,SVR,MLP) 和传统方法 (OLS) 在BTC价格预测中的有效性.
主要方法:
- 使用普通最小平方 (OLS),合体学习,支持向量回归 (SVR) 和多层感知器 (MLP) 的比较分析.
- 利用基于经济理论的宏观经济,微观经济,技术和区块链指标.
- 对短期和长期BTC价格预测的评估模型性能.
主要成果:
- 技术指标被确定为BTC短期价格波动的重要预测指标,验证了技术分析.
- 宏观经济和区块链指标对长期BTC价格预测具有重要意义,支持供需和基于成本的定价理论.
- 与其他机器学习和传统模型相比,支持向量回归 (SVR) 显示出更高的性能.
结论:
- 该研究证实了经济理论在BTC价格预测中的预测能力,特别是通过SVR.
- 建议SVR作为比特币价格预测的优越模型,而不是传统的统计和其他机器学习方法.
- 调查结果为国际金融,资产定价,投资决策提供了宝贵的见解,并作为金融预测中机器学习的基准.
相关概念视频
 01:18
Microsoft Excel: Regression Analysis
706
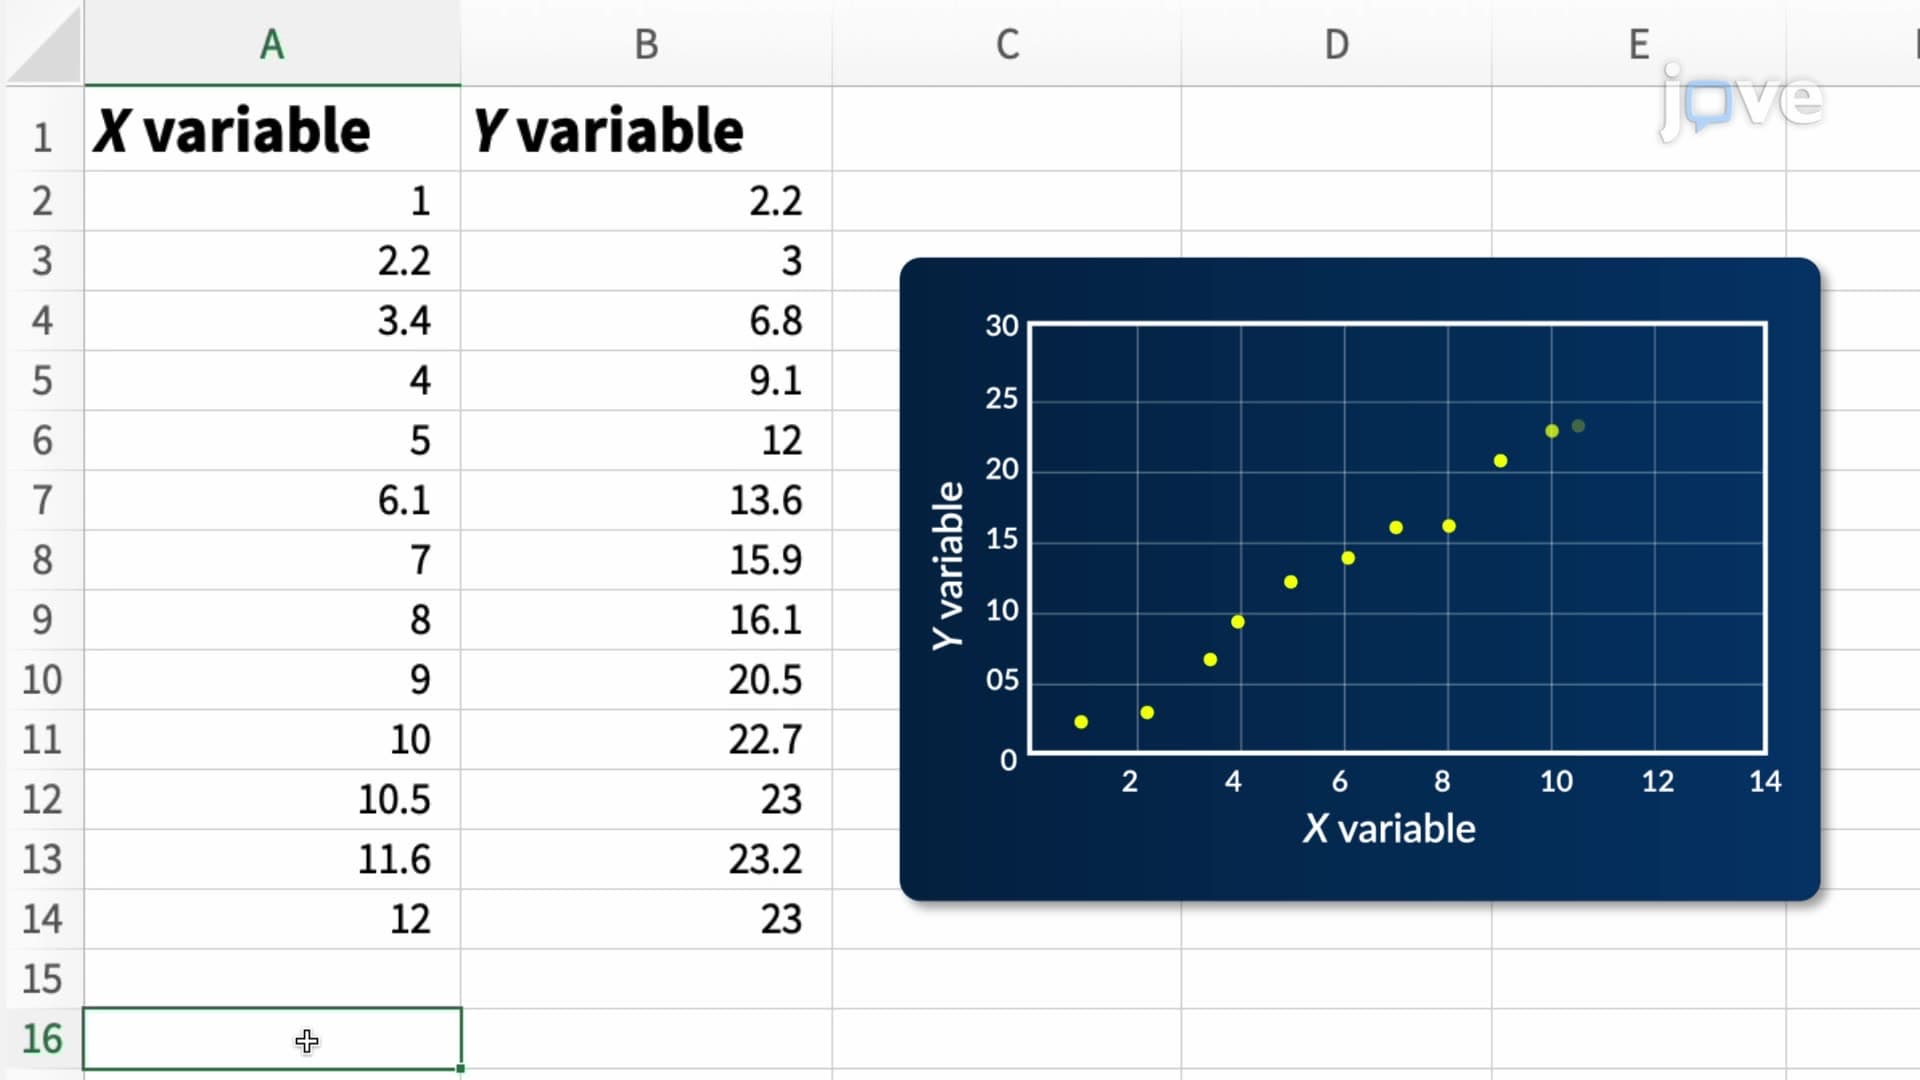
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
706
 01:15
Expected Value
4.0K
The expected value is known as the "long-term" average or mean. This means that over the long term of experimenting over and over, you would expect this average. The expected average is represented by the symbol μ. It is calculated as follows:
4.0K
 01:29
Econometric Views (EViews)
175
Econometric Views, often stylized as EViews, is a package that merges statistical analysis with econometric studies. It is designed to provide tools for time series analysis, forecasting, and econometric model simulation. The software originated from MicroTSP software and has evolved significantly since its inception in 1981. The history of EViews is marked by a continuous effort to enhance its computational speed and user interface. It was initially developed for large computing systems but...
175
 01:18
Steps in Outbreak Investigation
154
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
154
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K