相关实验视频
Updated: Jul 23, 2025

05:37

An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
2.1K
不确定性调整的建议通过矩阵因数分解与加权损失

概括
本研究引入了一种用于推系统 (RSs) 的新型矩阵因子化方法,该方法可以解释评级不确定性. 通过对不确定的评级进行加权,该方法可以提高对噪音数据集的预测准确性.
科学领域:
- 计算机科学 计算机科学
- 机器学习 机器学习
背景情况:
- 推系统 (RSs) 通常面临着杂的用户评分.
- 不平等的噪音水平可能源于用户行为或物品分裂性.
- 这种噪音可能会误导标准矩阵分解模型.
研究的目的:
- 开发一种基于核规范的矩阵因数分解方法,其中包含评级不确定性.
- 通过降低噪音等级来提高推系统的稳定性和准确性.
主要方法:
- 采用了基于核规范的矩阵分解方法.
- 使用了以评级不确定性估计形式的侧面信息.
- 引入了一个调整的微量规范调节器来处理加权损失函数.
主要成果:
- 拟议的方法在合成和现实世界数据集上展示了最先进的性能.
- 在各种评估指标中观察到绩效改善.
- 证实了辅助不确定性信息的有效使用.
结论:
- 将评级不确定性纳入矩阵分解显著提高推者系统性能.
- 调整后的微量标准规范化有效地处理加权损失,保持理论保证.
- 这种方法提供了一个强大的解决方案,用于处理推系统中的噪音数据.
更多相关视频
 08:51
Author Spotlight: Integrated Multi-Omics Analysis for Unveiling Multicellular Immune Signatures in Clinical Heart Attack Cohorts
Published on: September 20, 2024
1.3K
 07:15
Machine Learning Algorithms for Early Detection of Bone Metastases in an Experimental Rat Model
Published on: August 16, 2020
6.9K
相关概念视频
 00:54
Uncertainty: Confidence Intervals
4.1K
The confidence interval is the range of values around the mean that contains the true mean. It is expressed as a probability percentage. The interpretation of a 95% confidence interval, for instance, is that the statistician is 95% confident that the true mean falls within the interval. The upper and lower limits of this range are known as confidence limits. The confidence limits for the true mean are estimated from the sample's mean, the standard deviation, and the statistical factor...
4.1K
 01:24
Confidence Coefficient
7.7K
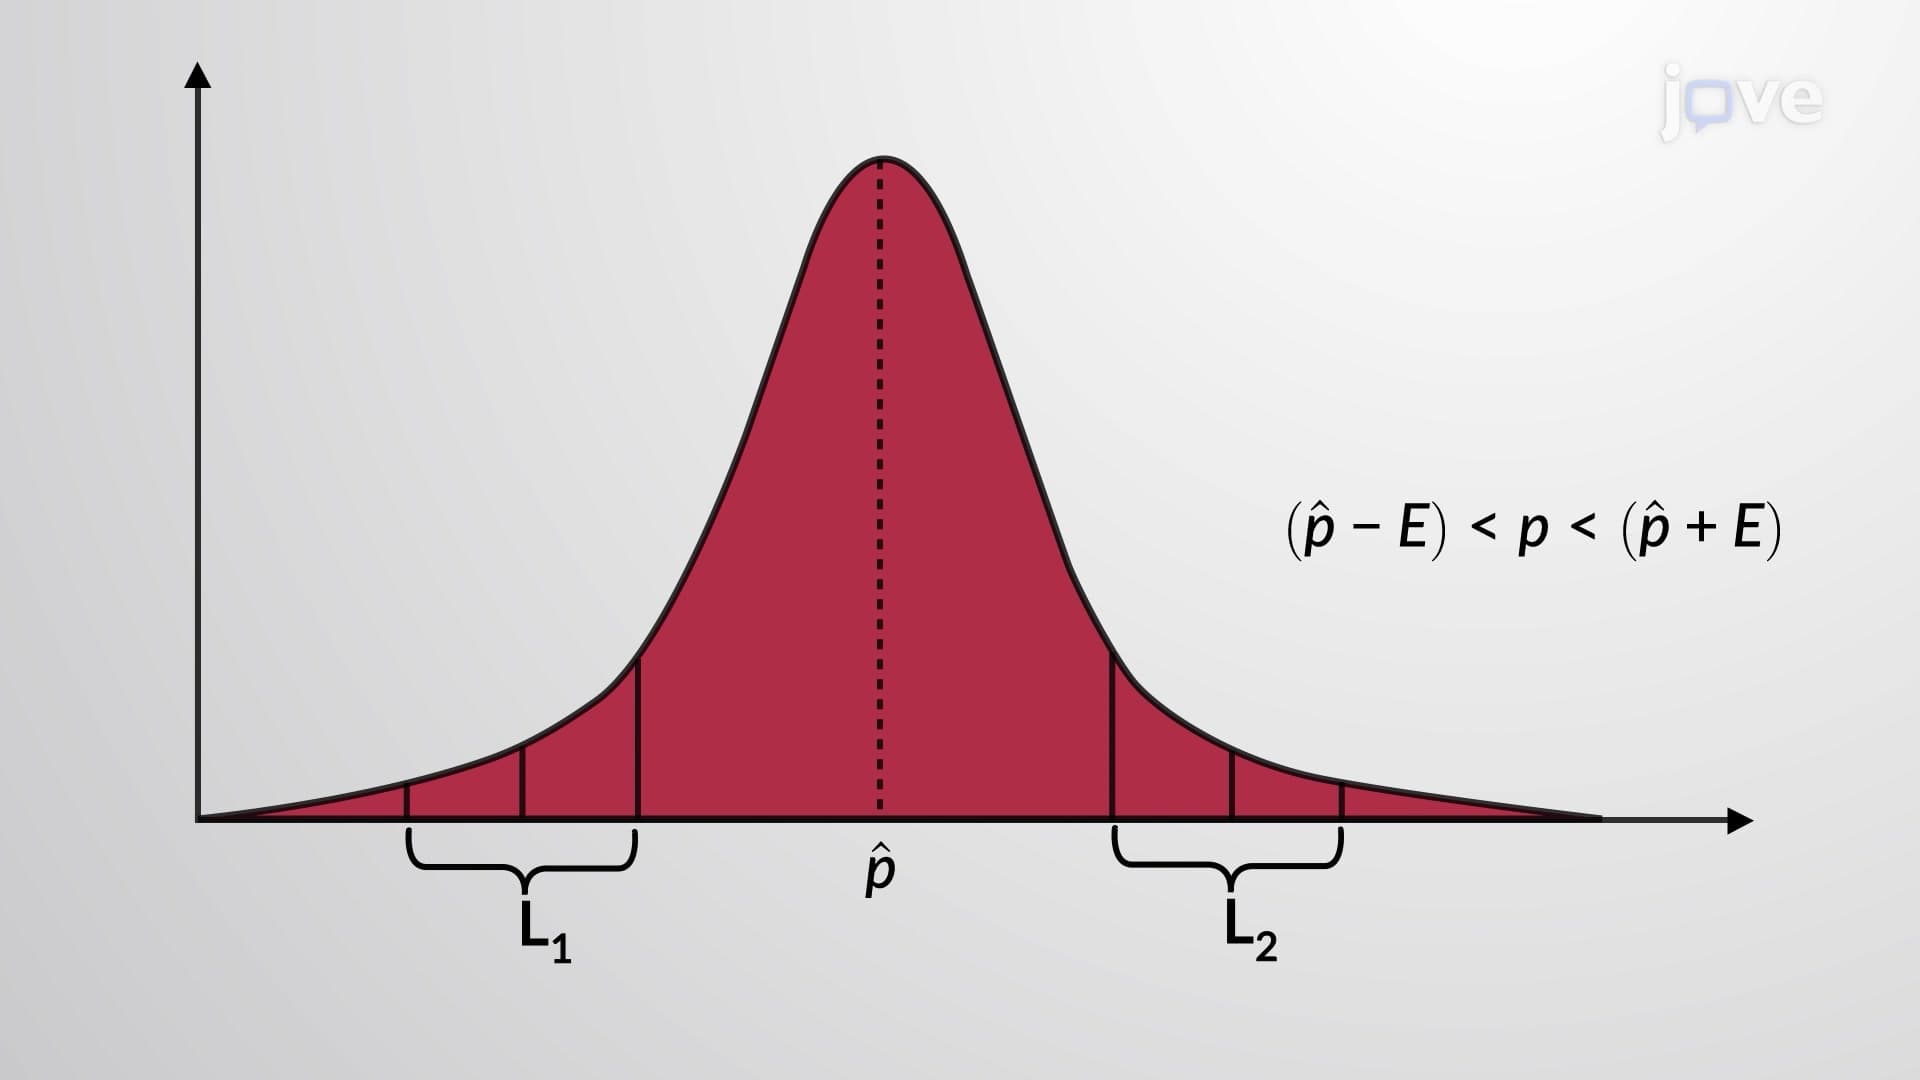
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.7K
 00:59
Uncertainty: Overview
601
In analytical chemistry, we often perform repetitive measurements to detect and minimize inaccuracies caused by both determinate and indeterminate errors. Despite the cares we take, the presence of random errors means that repeated measurements almost never have exactly the same magnitude. The collective difference between these measurements - observed values - and the estimated or expected value is called uncertainty. Uncertainty is conventionally written after the estimated or expected value.
601
 00:57
Weighted Mean
5.2K
While taking the arithmetic, geometric, or harmonic mean of a sample data set, equal importance is assigned to all the data points. However, all the values may not always be equally important in some data sets. An intrinsic bias might make it more important to give more weightage to specific values over others.
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
5.2K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 00:59
Propagation of Uncertainty from Random Error
731
An experiment often consists of more than a single step. In this case, measurements at each step give rise to uncertainty. Because the measurements occur in successive steps, the uncertainty in one step necessarily contributes to that in the subsequent step. As we perform statistical analysis on these types of experiments, we must learn to account for the propagation of uncertainty from one step to the next. The propagation of uncertainty depends on the type of arithmetic operation performed on...
731