
超短期风力发电预测方法结合了金融技术特征工程和XGBoost算法
Shijie Guan1,2, Yongsheng Wang1,2, Limin Liu1,2
1School of Data Science and Application, Inner Mongolia University of Technology, Hohhot 010080, China.
Heliyon
|July 24, 2023

概括
这项研究介绍了一种改进的XGBoost模型,用于超短期风力发电预测. 它使用金融技术指标和可变的群算法,在现实应用中进行更快,更准确的预测.
科学领域:
- 可再生能源系统可再生能源系统
- 机器学习应用 机器学习应用
- 时间序列分析时间序列分析
背景情况:
- 由于深度学习方法,现有的风力发电预测模型在特征表示和缓慢融合方面扎.
- 这些局限性阻碍了在动态生产环境中的实际应用.
研究的目的:
- 开发一个高效和准确的超短期风力发电预测模型.
- 解决当前基于深度学习的预测方法的局限性.
- 提高可解释性,减少对特征工程专家经验的依赖.
主要方法:
- 提出了一个XGBoost模型,将金融技术指标的特征工程纳入其中.
- 利用一个变异性群算法来优化指标参数.
- 将模型应用于Tennet风力发电数据集进行验证.
主要成果:
- 实现了0.859的平均绝对误差 (MAE) 和1.329.3的根平均平方误差 (RMSE).
- 演示了快速预测时间,仅在244毫秒内完成预测.
- 新型特征工程有效地将时间序列数据中的潜在关系缩小.
结论:
- 拟议的模型为超短期风力发电预测提供了显著的进步.
- 金融技术指标和生物算法的整合提高了预测的准确性和效率.
- 这种方法在运营环境中为传统的深度学习模型提供了可行的替代方案.

相关概念视频
 01:24
Wind Turbine Machine Models
170
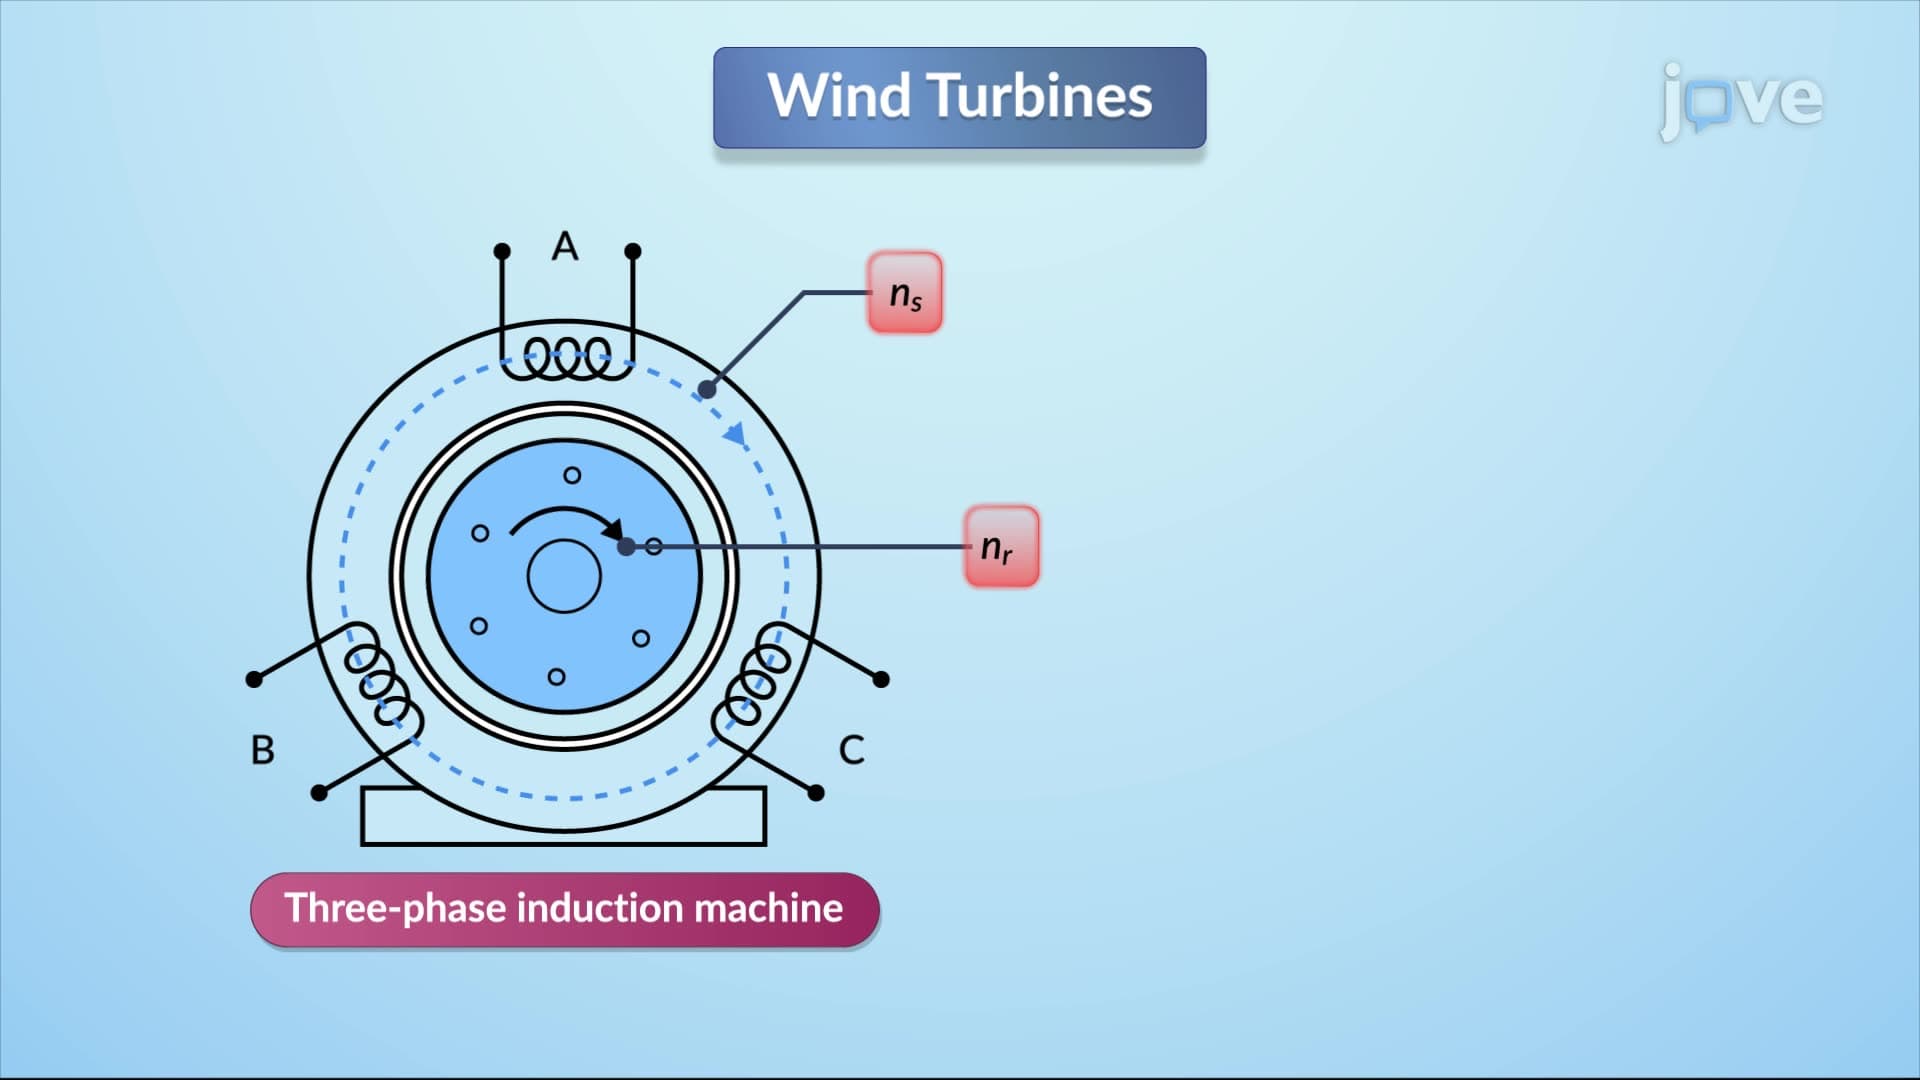
In the growing field of wind energy, incorporating wind turbine models into transient stability analysis is essential. Induction and synchronous machines are the primary models used, with induction machines being prevalent due to their simplicity and reliability.
Induction machines interact through the rotating magnetic field generated by the stator and the rotor. The key parameter is slip, which is the difference between synchronous speed and rotor speed relative to synchronous speed. Slip is...
Induction machines interact through the rotating magnetic field generated by the stator and the rotor. The key parameter is slip, which is the difference between synchronous speed and rotor speed relative to synchronous speed. Slip is...
170
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:07
End Point Prediction: Gran Plot
386
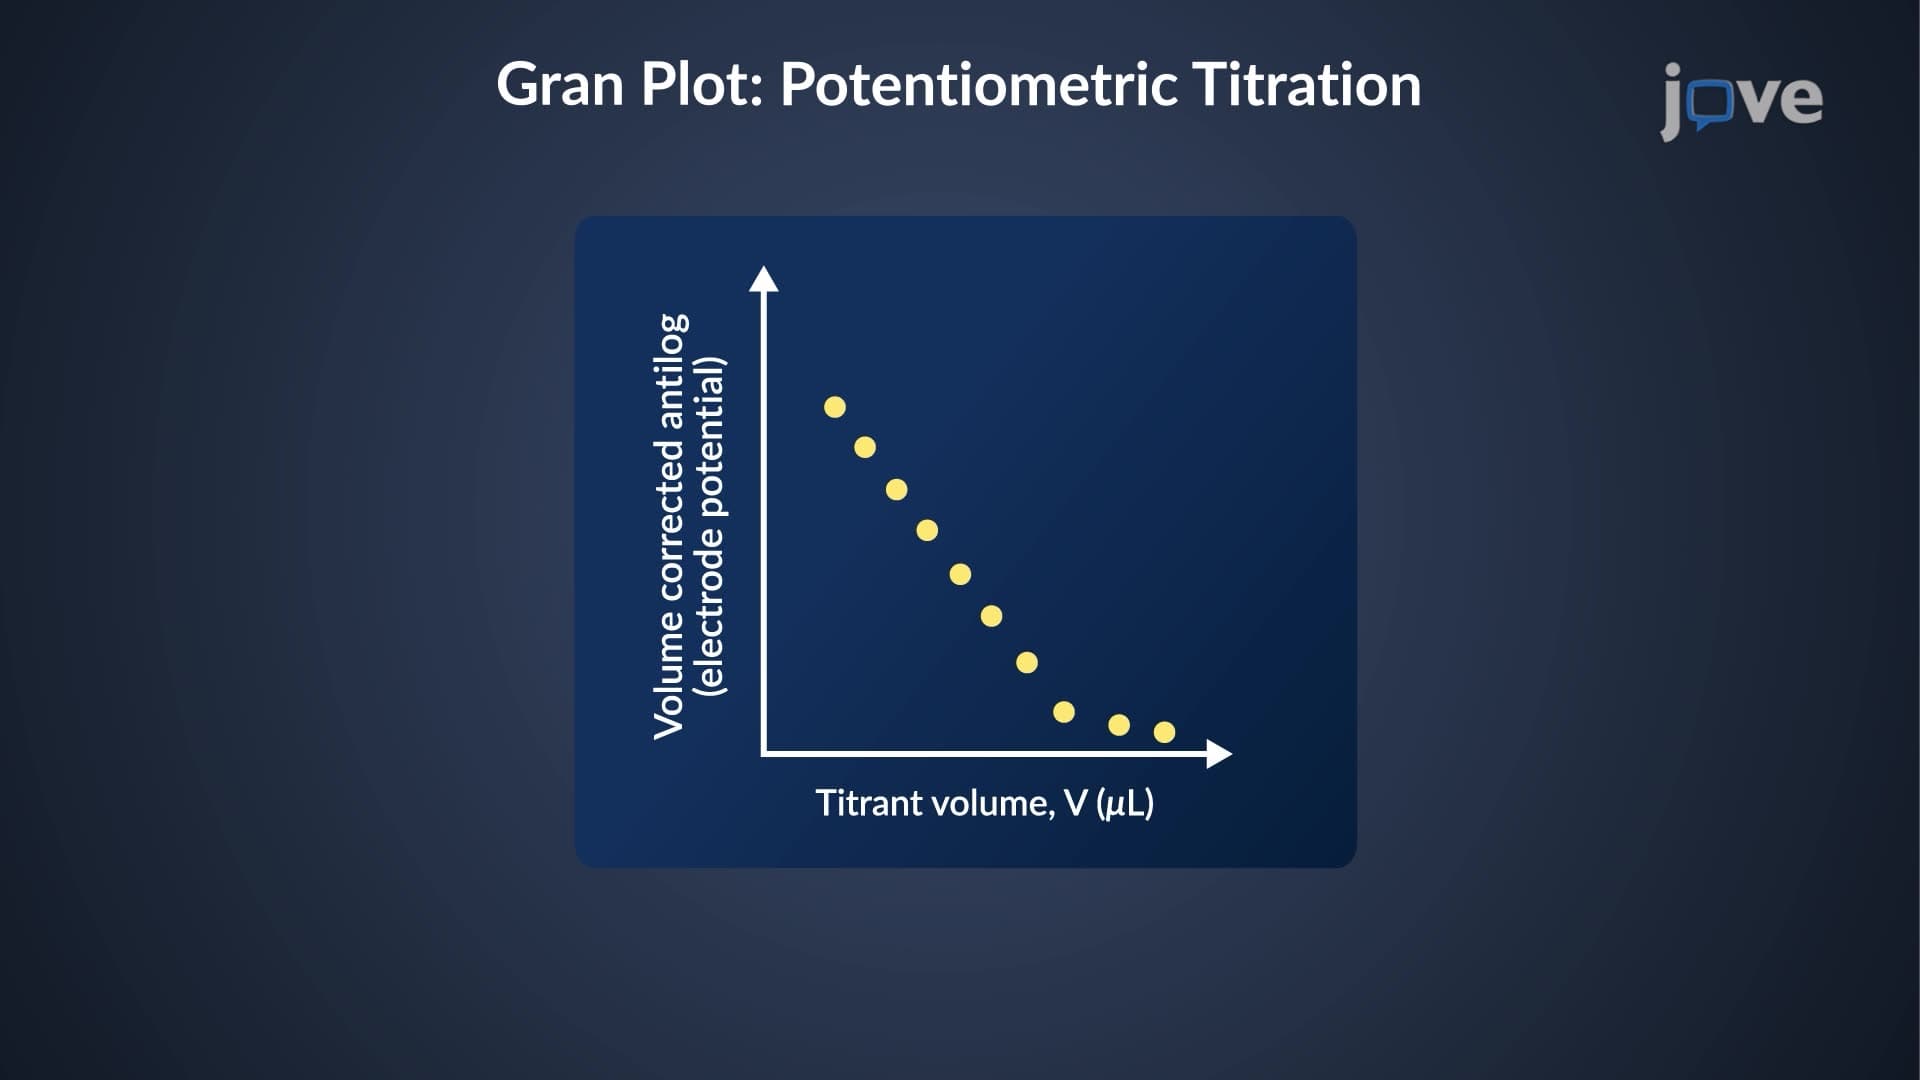
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
386
 01:17
Design Example: Calculating Safe Diameter for Wind-Exposed Disc
156
Assessing safety in wind-exposed installations is crucial to preventing potential failures. This example explores the calculation and design adjustments needed to mount a circular disc on a building facade, where wind forces are a primary concern. A 4-meter diameter disc was initially designed as an aesthetic feature facing winds at a velocity of 25 meters per second, with an air density of 1.25 kilograms per cubic meter. Given these conditions, the drag force on the disc was determined using...
156
 01:19
Survival Tree
115
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
115
 01:30
Classification of Signals
538
In signal processing, signals are classified based on various characteristics: continuous-time versus discrete-time, periodic versus aperiodic, analog versus digital, and causal versus noncausal. Each category highlights distinct properties crucial for understanding and manipulating signals.
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
A continuous-time signal holds a value at every instant in time, representing information seamlessly. In contrast, a discrete-time signal holds values only at specific moments, often denoted as x(n), where...
538