

随机项目斜率回归:一种替代的测量模型,可以考虑与单个项目相关的相似性和差异
Ed Donnellan1, Satoshi Usami2, Kou Murayama3
1Department of Experimental Psychology, University College London.
Psychological methods
|July 27, 2023

概括
研究人员可以使用随机项目斜率回归来更准确地分析心理数据. 这种方法解释了独立变量与个别测量项的不同关系,防止统计分析中的膨胀型I错误.
科学领域:
- 心理学 心理学 心理学
- 统计 统计 统计 统计
- 量化研究方法 量化研究方法
背景情况:
- 心理学研究经常使用来自多项测量的依赖变量 (DV) 的复合分数.
- 传统的聚合或共同因子模型可能会忽视独立变量 (IV) 和单个项目之间的不同关系.
研究的目的:
- 引入和验证混合效应模型,随机项目斜率回归,作为替代测量模型.
- 证明未解决的随机项目斜率对统计推理的影响,特别是I型错误率.
- 提供一种方法来解释心理研究中的项目异质性.
主要方法:
- 开发了一种混合效应模型:随机项目斜率回归.
- 利用数学证明和模拟来评估I型错误率.
- 分析了来自调查和反应时间任务的现实数据 (n=564).
主要成果:
- 随机的项目斜率可以膨胀I型错误率,特别是在更大的样本大小.
- 在现实世界的心理数据中检测到有问题的随机项目斜率水平.
- 标准的统计指数不足以诊断随机项目斜率的存在.
结论:
- 随机项目斜率回归为分析异质项目的共同因子模型提供了有价值的替代方案.
- 研究人员必须考虑随机项的斜率,以确保准确的统计结论.
- 未来的研究应该探索用于识别随机项目斜率的诊断工具.
更多相关视频
 10:46
A Method of Trigonometric Modelling of Seasonal Variation Demonstrated with Multiple Sclerosis Relapse Data
Published on: December 9, 2015
10.7K
 06:48
Lexical Decision Task for Studying Written Word Recognition in Adults with and without Dementia or Mild Cognitive Impairment
Published on: June 25, 2019
9.2K
相关概念视频
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:19
Variation
6.8K
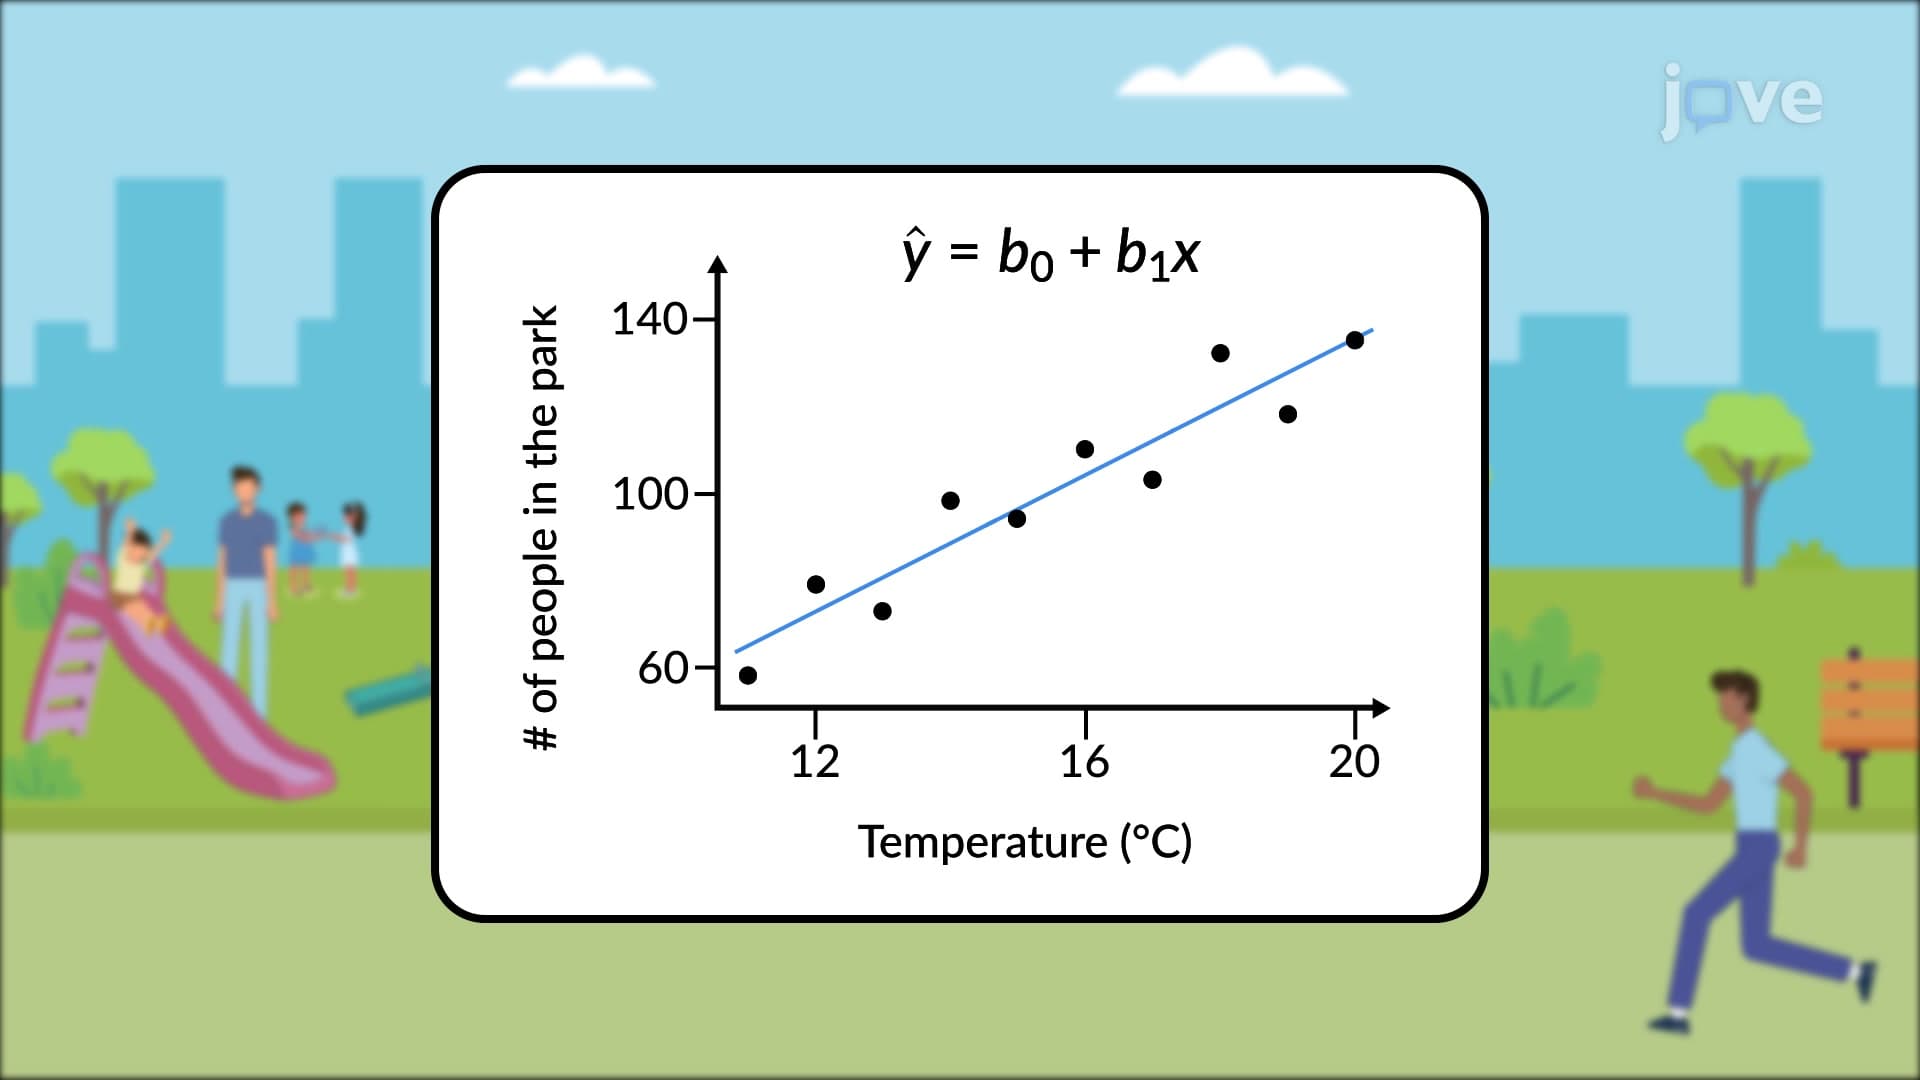
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.8K
 01:11
Regression Analysis
5.8K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.8K
 01:16
Response Surface Methodology
180
Response Surface Methodology (RSM) is a collection of statistical and mathematical techniques used to develop, improve, and optimize processes. It is particularly valuable when many input variables or factors potentially influence a response variable.
The process of RSM involves several key steps:
The process of RSM involves several key steps:
180