
在三臂非劣等性试验中,扩展科赫-罗梅尔设计的同时置信区间
Martin Scharpenberg1, Werner Brannath1
1Competence Center for Clinical Trials Bremen, University of Bremen, Bremen, Germany.
Statistical methods in medical research
|July 28, 2023

概括
这项研究通过结合适应性测试和同时置信区间来增强非劣势试验设计. 这些方法确保实验性治疗的可靠性,与已确定的,但可能不稳定的参考治疗相比.
科学领域:
- 生物统计学 生物统计学
- 临床试验设计 临床试验设计
- 药学研究 药学研究
背景情况:
- 当安慰剂使用是道德的,只有不稳定的参考治疗方法存在时,三臂非劣势试验至关重要.
- 现有的设计侧重于"测试灵敏度",但如果参考治疗在试验中无效,可能会失败.
- 确保实验治疗的有效性和参考治疗的有效性对于有意义的非劣等性主张至关重要.
研究的目的:
- 扩展科赫-罗梅尔设计的三臂非劣等性试验.
- 引入适应性测试,根据参考治疗的优越性来验证非劣等性主张.
- 为了补充适应性测试与兼容的同时置信区间,以进行可靠的试验分析.
主要方法:
- 扩展Koch-Röhmel适应性设计,包括同时的置信区间.
- 模拟研究用于比较不同的同时置信区间方法.
- 将开发的方法应用于现实世界的临床试验数据集.
主要成果:
- 拟议的自适应性测试策略确保了非劣等性主张的有效性,即使参考疗法显示出可变的疗效.
- 同时的置信区间为评估非劣势和优势假设提供了一个兼容的框架.
- 这些方法已成功应用于临床试验,证明了其实际效用.
结论:
- 增强的自适应设计与同时的置信区间加强了三臂非劣势试验的可靠性.
- 这种方法为药物开发提供了更强大的统计框架,特别是在不稳定的参考治疗中.
- 该研究提供了在非劣势试验环境中对监管提交的实际工具和验证.

相关概念视频
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
573
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
573
 01:19
Interpretation of Confidence Intervals
6.0K
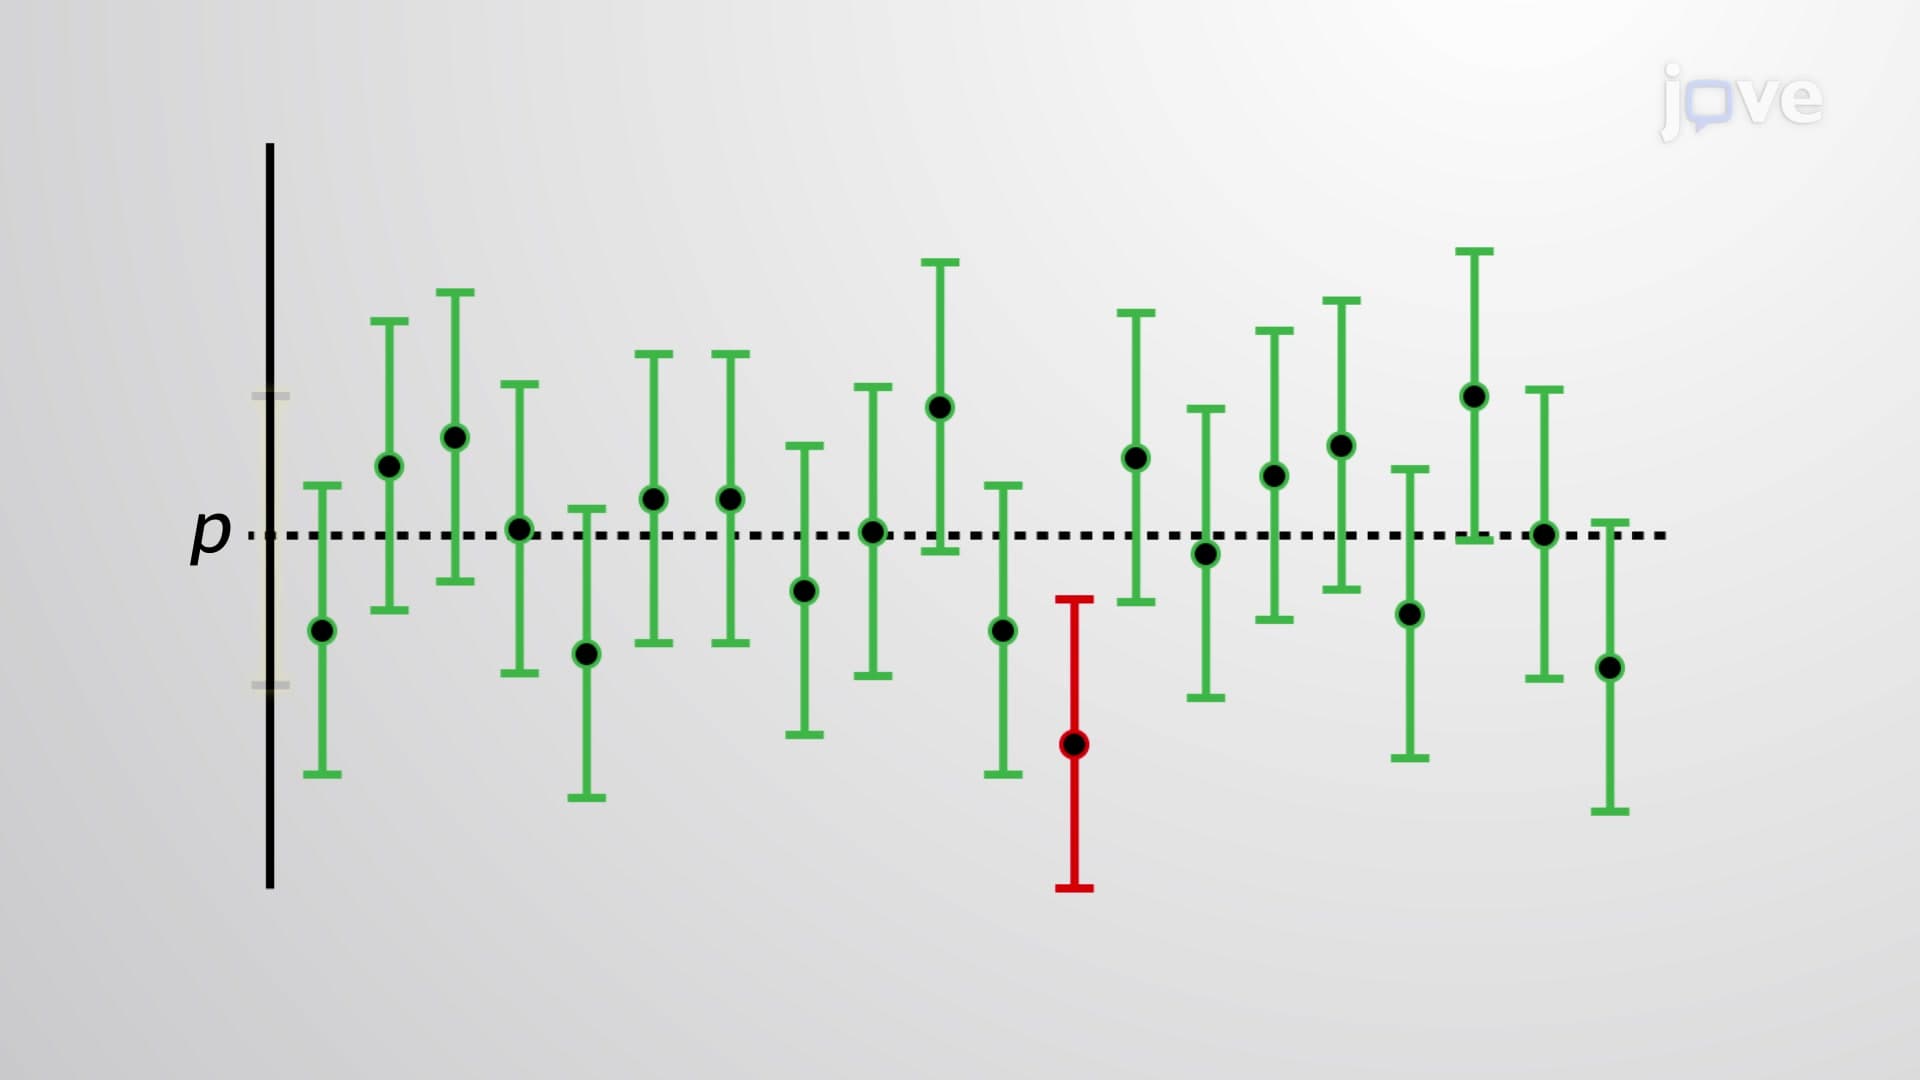
A confidence interval is a better estimate of the population than a point estimate, as it uses a range of values from a sample instead of a single value.
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
6.0K
 01:21
Confidence Intervals
6.6K
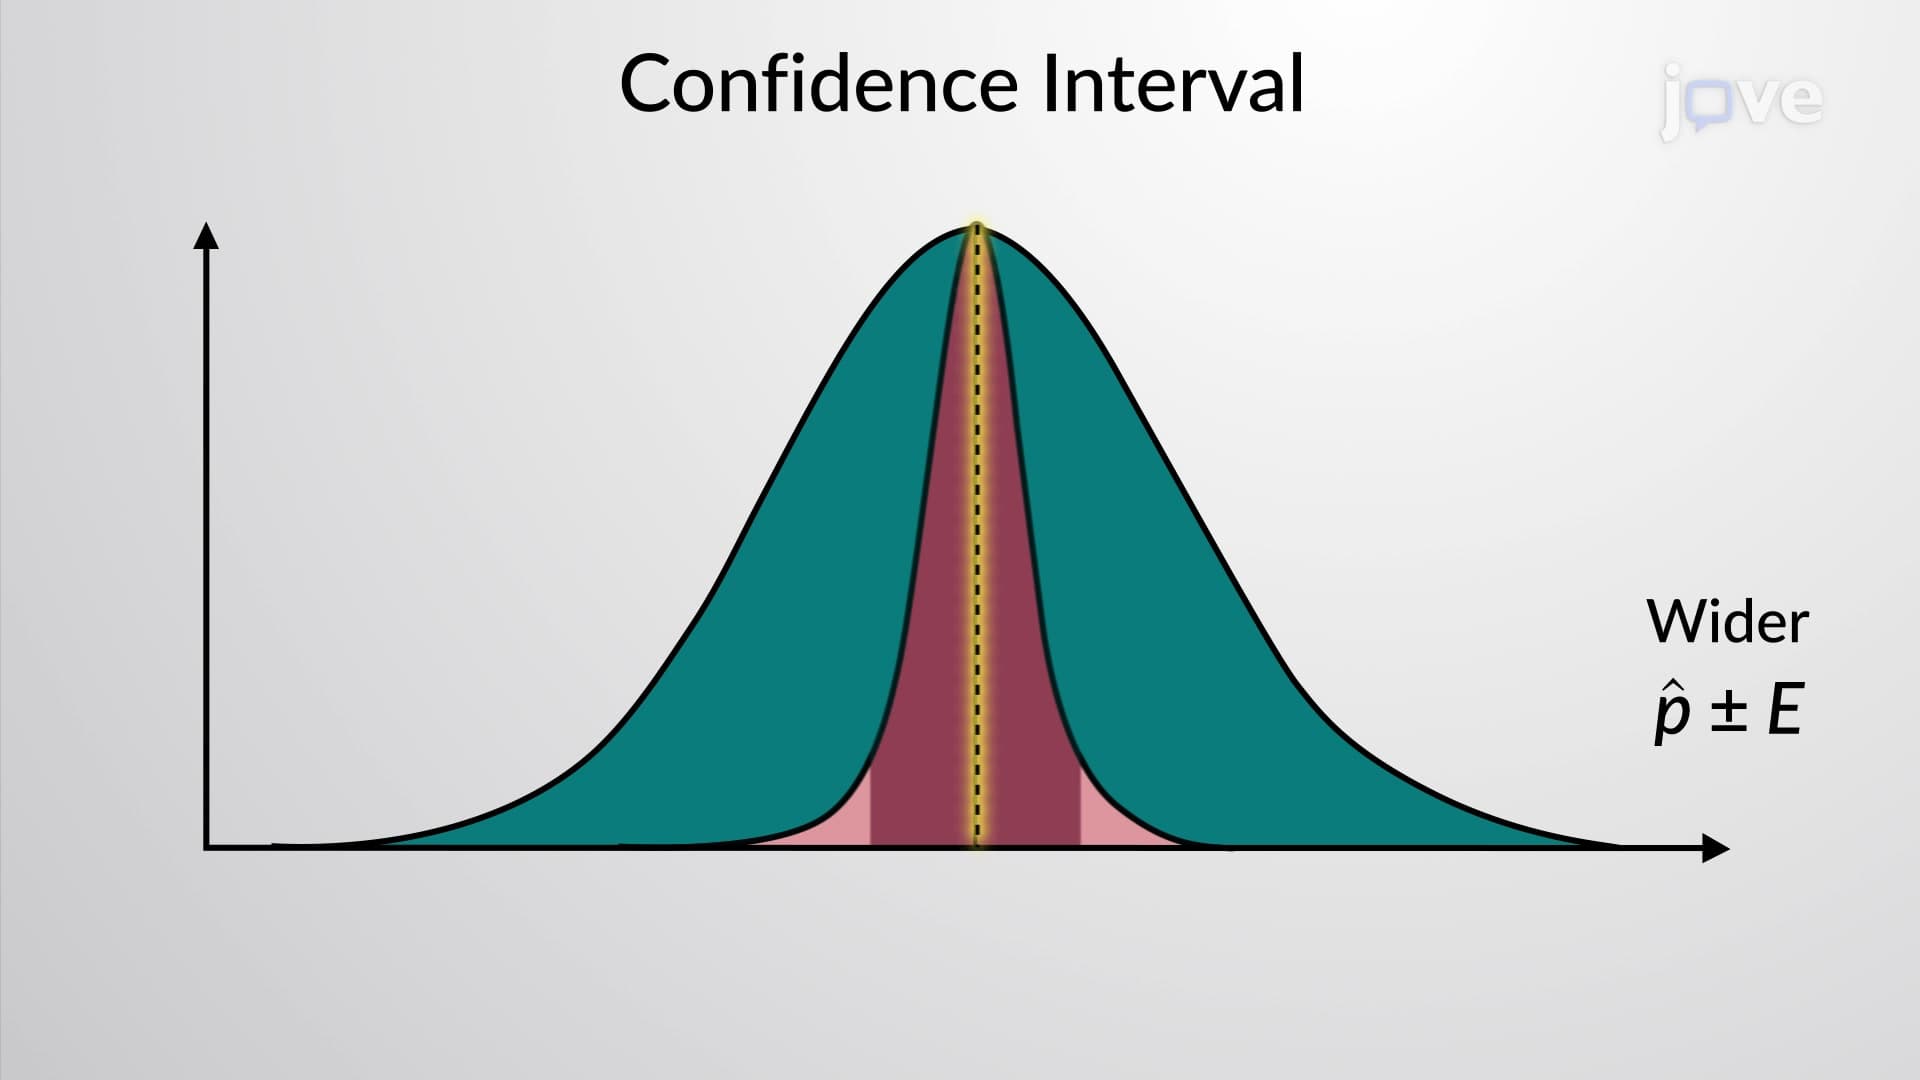
An unbiased point estimate is often insufficient to predict a population estimate, such as population mean or population proportion. In this scenario, a confidence interval is used. A confidence interval is an estimate similar to a sample proportion. However, unlike the point estimate which is a single value, the confidence interval contains a range of values. These values have lower and upper limits, known as confidence limits, and can be designated as L1 and L2, respectively.
A...
A...
6.6K
 01:15
One-Way ANOVA: Unequal Sample Sizes
5.8K
One-way ANOVA can be performed on three or more samples of unequal sizes. However, calculations get complicated when sample sizes are not always the same. So, while performing ANOVA with unequal samples size, the following equation is used:
5.8K
 01:10
Bonferroni Test
2.8K
The Bonferroni test is a statistical test named after Carlo Emilio Bonferroni, an Italian mathematician best known for Bonferroni inequalities. This statistical test is a type of multiple comparison test to determine which means are different than the rest. Bonferroni test can minimize the Type 1 error by reducing the significance level alpha, which otherwise increases with sample pairs.
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
2.8K
 01:21
Friedman Two-way Analysis of Variance by Ranks
242
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
242