

实现最佳KELM使用PSO-BOA优化策略与数据分类应用
Yinggao Yue1,2, Li Cao1, Haishao Chen1
1School of Intelligent Manufacturing and Electronic Engineering, Wenzhou University of Technology, Wenzhou 325035, China.
Biomimetics (Basel, Switzerland)
|July 28, 2023

概括
本研究介绍了一种用于多标签分类的新PSO-BOA-KELM算法,提高了Kernel极端学习机器 (KELM) 的性能. 它有效地优化了KELM参数,提高了复杂数据流的预测准确性.
科学领域:
- 机器学习 机器学习
- 数据挖掘 数据挖掘
- 人工智能的人工智能
背景情况:
- 由于高效的处理和性能,Kernel极端学习机器 (KELM) 是有效的批量多标签分类.
- 实际应用中的数据流存在诸如广度,速度,多标签和概念漂移等挑战,影响准确性和时空复杂性.
- 凯尔姆训练需要重复的独立运行来优化概括性能和隐藏层节点,这带来了计算挑战.
研究的目的:
- 提出一个优化的内核极端学习机 (KELM) 多标签分类方法.
- 解决传统KELM培训的局限性,特别是需要重复独立运行以优化概括和隐藏层节点.
- 为了提高KELM对动态数据流的预测准确性和效率.
主要方法:
- 提出了一种新的Kernel极端学习机器多标签数据分类方法,集成由粒子优化 (PSO) 优化的蝶算法 (BA).
- 拟议的PSO-BOA-KELM算法优化了模型概括能力和隐藏层节点的数量.
- 该方法可以同时训练多个KELM隐藏层网络,保持当前的时间复杂性并减少重复计算.
主要成果:
- 与PSO-KELM,BBA-KELM和BOA-KELM相比,PSOBOA-KELM算法显示出更高的性能.
- 它更有效地搜索最佳的Kernel极端学习机参数.
- 该算法在全球和本地性能之间实现了更好的平衡,从而产生了具有更高预测精度的KELM预测模型.
结论:
- 拟议的PSO-BOA-KELM算法有效地优化了KELM用于多标签分类任务.
- 这种方法解决了针对动态数据流的传统KELM培训的计算低效性.
- 增强的KELM模型提供了更好的预测准确性和参数优化功能.
相关概念视频
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
573
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
573
 01:31
Classification of Systems-II
178
Continuous-time systems have continuous input and output signals, with time measured continuously. These systems are generally defined by differential or algebraic equations. For instance, in an RC circuit, the relationship between input and output voltage is expressed through a differential equation derived from Ohm's law and the capacitor relation,
178
 01:09
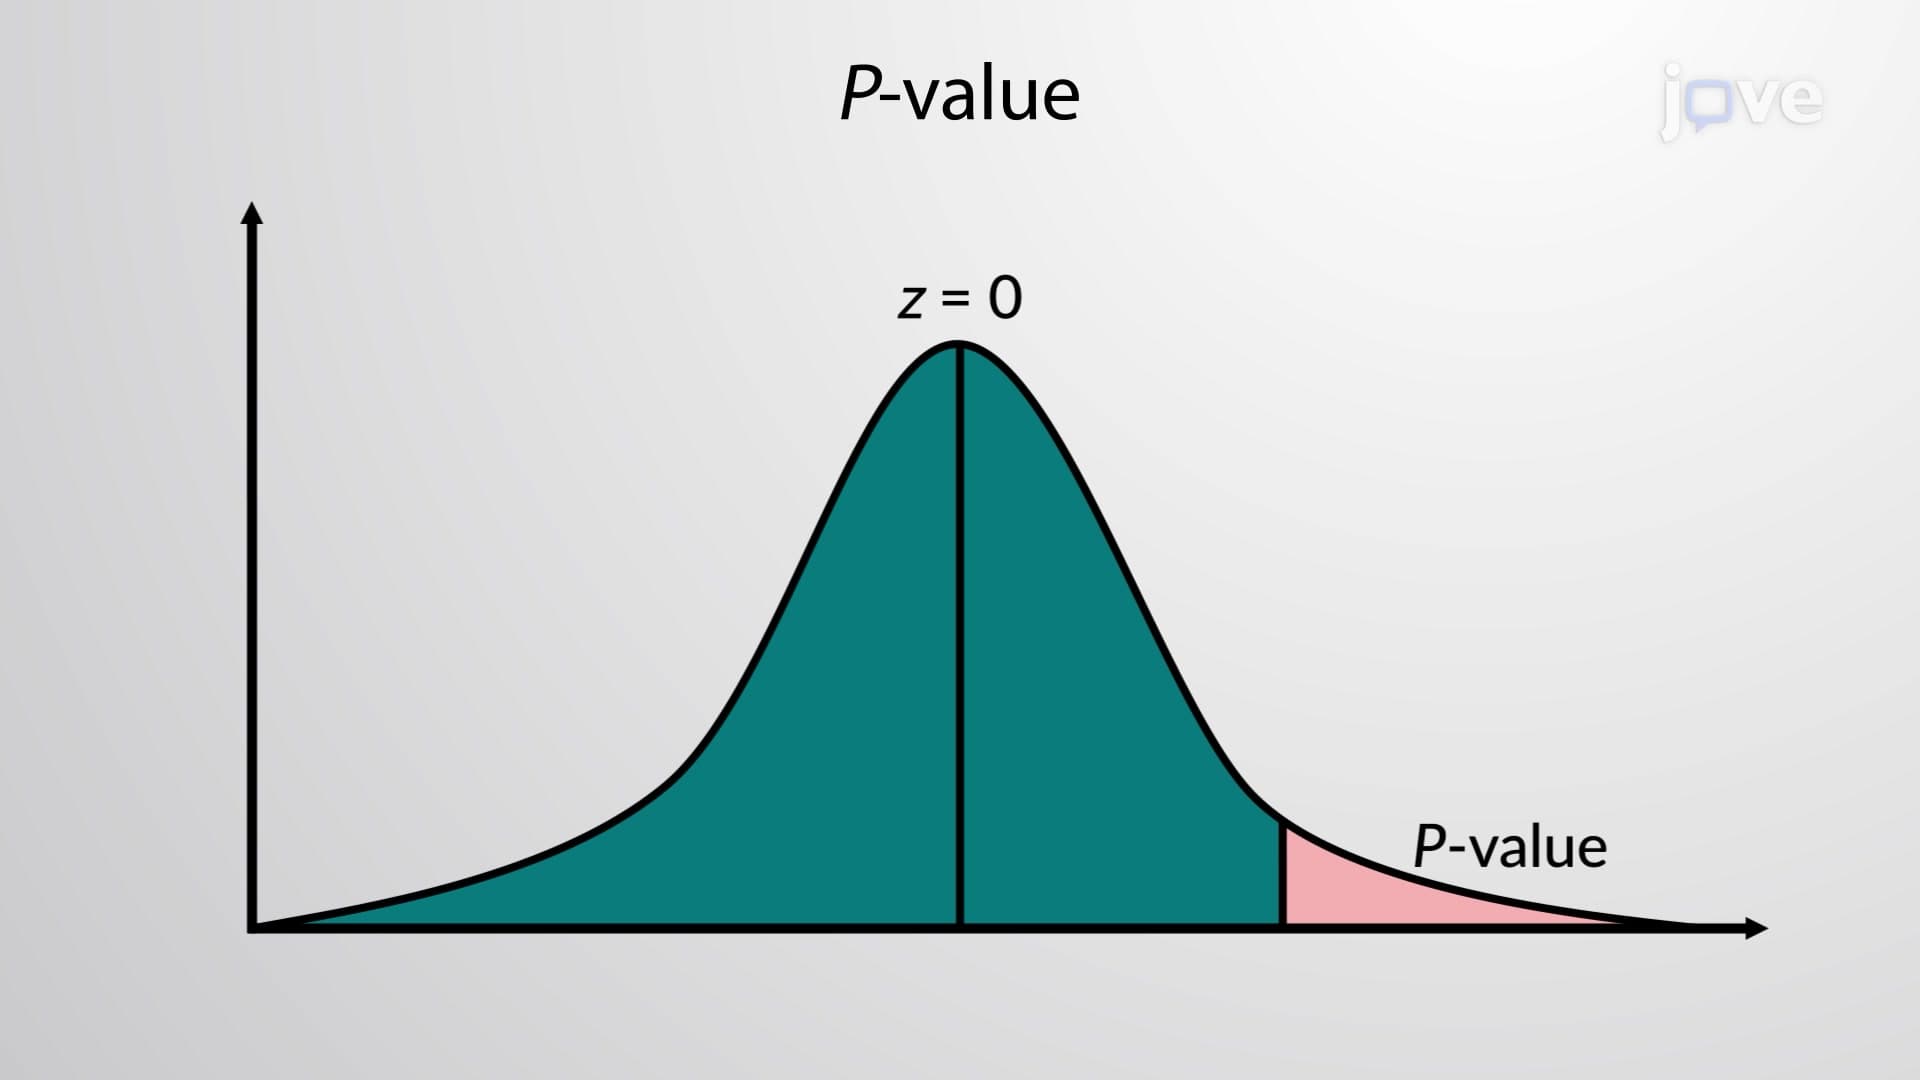
Decision Making: P-value Method
5.5K
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
5.5K
 01:26
Classification of Systems-I
215
Linearity is a system property characterized by a direct input-output relationship, combining homogeneity and additivity.
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
Homogeneity dictates that if an input x(t) is multiplied by a constant c, the output y(t) is multiplied by the same constant. Mathematically, this is expressed as:
215
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
81
Mechanistic models play a crucial role in algorithms for numerical problem-solving, particularly in nonlinear mixed effects modeling (NMEM). These models aim to minimize specific objective functions by evaluating various parameter estimates, leading to the development of systematic algorithms. In some cases, linearization techniques approximate the model using linear equations.
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
81
 01:20
Maxwell-Boltzmann Distribution: Problem Solving
1.6K
Individual molecules in a gas move in random directions, but a gas containing numerous molecules has a predictable distribution of molecular speeds, which is known as the Maxwell-Boltzmann distribution, f(v).
This distribution function f(v) is defined by saying that the expected number N (v1,v2) of particles with speeds between v1 and v2 is given by
This distribution function f(v) is defined by saying that the expected number N (v1,v2) of particles with speeds between v1 and v2 is given by
1.6K