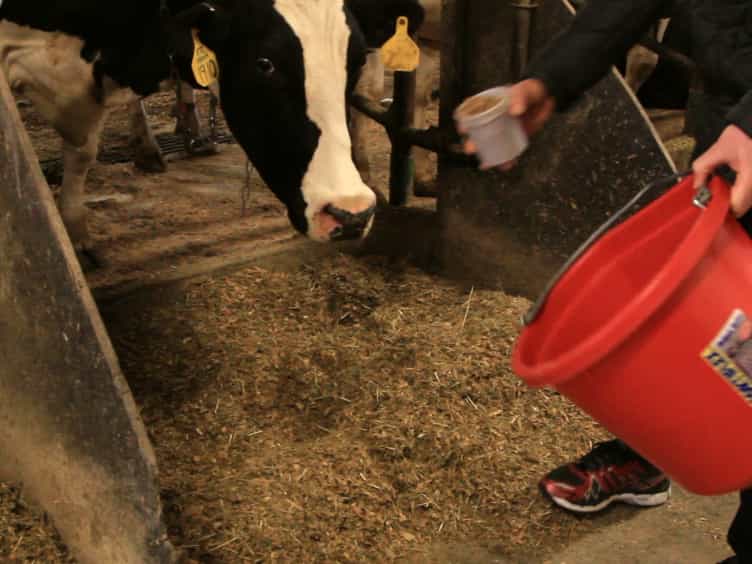

预测肉牛的干物质摄入量
Nathan E Blake1,2, Matthew Walker2,3,4, Shane Plum2
1School of Agriculture and Food, Davis College of Agriculture, Natural Resources and Design, West Virginia University, Morgantown, WV 26506, USA.
Journal of animal science
|August 10, 2023

概括
机器学习使用水摄入量和性能数据准确预测个体动物干物质摄入量 (DMI). 这项技术可以改善群体住房环境中的牲畜管理和效率.
科学领域:
- 动物科学动物科学
- 农业技术 农业技术
- 机器学习应用 机器学习应用
背景情况:
- 准确估计个体动物干物质摄入量 (DMI) 对畜牧生产效率至关重要.
- 目前用于监测DMI的方法在集体住房或牧场环境中通常是不切实际的.
- 使用代理变量的预测算法是需要在具有挑战性的环境中估计DMI的.
研究的目的:
- 通过水摄入量,动物表现和环境数据来确定机器学习是否可以预测DMI.
- 开发和评估DMI估计的预测算法,在集体养的牛群中.
- 将机器学习方法与用于DMI预测的传统统计方法进行比较.
主要方法:
- 使用随机森林回归 (RFR) 和重复测量随机森林 (RMRF) 机器学习模型.
- 收集的数据包括178头牛 (125头公牛,53头牛) 的每日DMI,水摄入量,体重和平均每日增益 (ADG).
- 记录了气候数据,并使用重复测量ANOVA (RMANOVA) 作为传统的比较.
主要成果:
- 该RMRF模型成功预测DMI,准确度为0.75公斤.
- 机器学习方法证明了在干旱牛中准确预测DMI的潜力.
- 开发的算法显示了未来在牧场环境中的应用的前景.
结论:
- 机器学习,特别是RMRF,为预测个体动物DMI提供了一种可行的方法.
- 准确的DMI预测可以提高畜牧管理和生产效率.
- 通过对各种数据集的进一步改进,这些预测算法将能够得到更广泛的应用.
更多相关视频
 07:46
Author Spotlight: Improving Beef Cattle Nutrition and Production with a Focus on Feed Efficiency and Meat Quality Traits Through Advanced Biochemical and Molecular Assays
Published on: July 12, 2024
576
 06:52
Lab-Scale Model to Evaluate Odor and Gas Concentrations Emitted by Deep Bedded Pack Manure
Published on: July 19, 2018
6.4K
相关概念视频
 01:10
Moisture Content and Bulking of Aggregate
178
The moisture content of aggregates is a crucial factor in construction, particularly in concrete mixing, as it influences the total water required in the mix. Moisture content represents the water coated on the exterior surface of the aggregate existing in a saturated and surface-dry condition. The total water content of a moist aggregate is the sum of its moisture content and water absorption.
When aggregates are exposed to rain or sit in stockpiles, they absorb moisture, which must be...
When aggregates are exposed to rain or sit in stockpiles, they absorb moisture, which must be...
178
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K