
一个改进的PBFT共识算法,基于分组和信用评级
Shannan Liu1, Ronghua Zhang2, Changzheng Liu3
1College of Information Science and Technology, Shihezi University, Shihezi, 832000, Xinjiang, China.
Scientific reports
|August 10, 2023

概括
本研究介绍了一种基于信用的拜占庭式容错共识算法 (CBFT),用于增强区块链网络. 与现有方法相比,CBFT显著改善吞吐量,减少延迟和通信开销,并增加故障容忍度.
科学领域:
- 区块链技术 区块链技术
- 分布式系统 分布式系统
- 计算机科学 计算机科学
背景情况:
- 实用拜占庭式故障宽容 (PBFT) 存在高通讯开销和有限的网络可扩展性问题.
- 现有的共识算法难以平衡效率,安全性和网络大小.
研究的目的:
- 提出一个增强的拜占庭式容错共识算法 (CBFT),解决PBFT的局限性.
- 为了提高通信效率,网络尺寸支持和区块链共识中的安全性.
主要方法:
- 开发了一种新的基于信用的拜占庭式容错 (CBFT) 共识算法.
- 实施了一个分组模型,将节点按响应速度划分,以获得分离的集团内部和集团内部共识.
- 整合了一个信用模型,为节点类型分配不同的责任,降低恶意主节点的概率.
主要成果:
- 与PBFT相比,CBFT的吞吐量是PBFT的3.1倍,与52个节点相比,GPBFT的1.5倍.
- 延迟时间减少到PBFT的7.4%,GPBFT的38.8%.
- 通讯开支减少到PBFT的6.4%,GPBFT的87.3%.
- 通过300个节点,拜占庭式故障耐受性提高了59.3%,随着网络规模的增加,收益增加了.
结论:
- 拟议的CBFT算法显著提高了区块链共识的效率和可扩展性.
- CBFT提供了比传统的PBFT更安全,更高性能的替代方案,特别是在大型网络中.
- 集团和信用模型有效地减少了通信开销,并减轻了与恶意节点相关的风险.
相关概念视频
 01:01
Group Polarization
34.3K
Group polarization is the strengthening of an original group attitude following the discussion of views within a group (Teger & Pruitt, 1967). That is, if a group initially favors a viewpoint, after discussion the group consensus is likely a stronger endorsement of the viewpoint. Conversely, if the group was initially opposed to a viewpoint, group discussion would likely lead to stronger opposition.
34.3K
 01:15
Types of Aggregate Grading
597
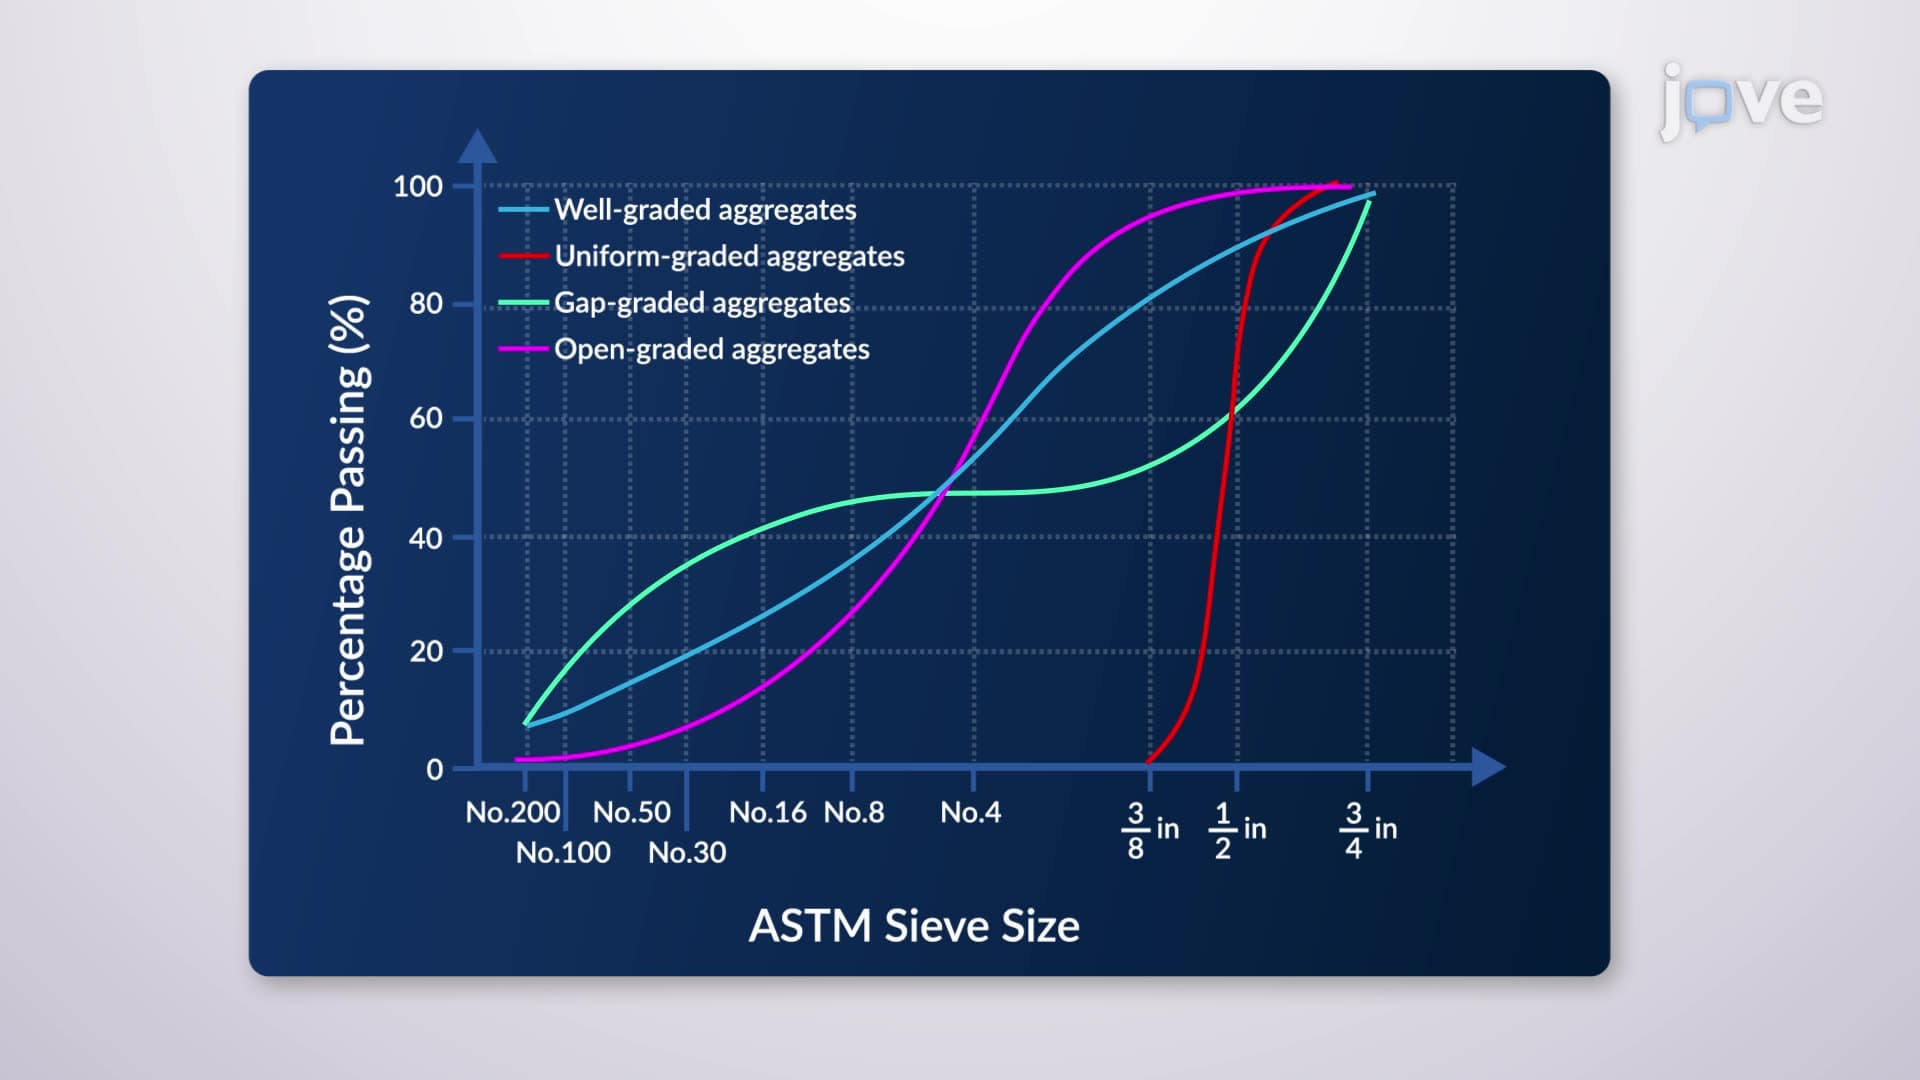
Aggregate grading is crucial in economically obtaining a concrete mix with adequate strength, reasonable workability, and minimal segregation. There are four types of aggregate gradation: well-graded, uniformly (or one-sized) graded, gap-graded, and open-graded.
Well-graded aggregates include a complete range of necessary size fractions that fit together to create a dense matrix with minimal voids, represented by a smooth, continuous gradation curve. This type of grading ensures good...
Well-graded aggregates include a complete range of necessary size fractions that fit together to create a dense matrix with minimal voids, represented by a smooth, continuous gradation curve. This type of grading ensures good...
597
 01:09
Decision Making: P-value Method
5.5K
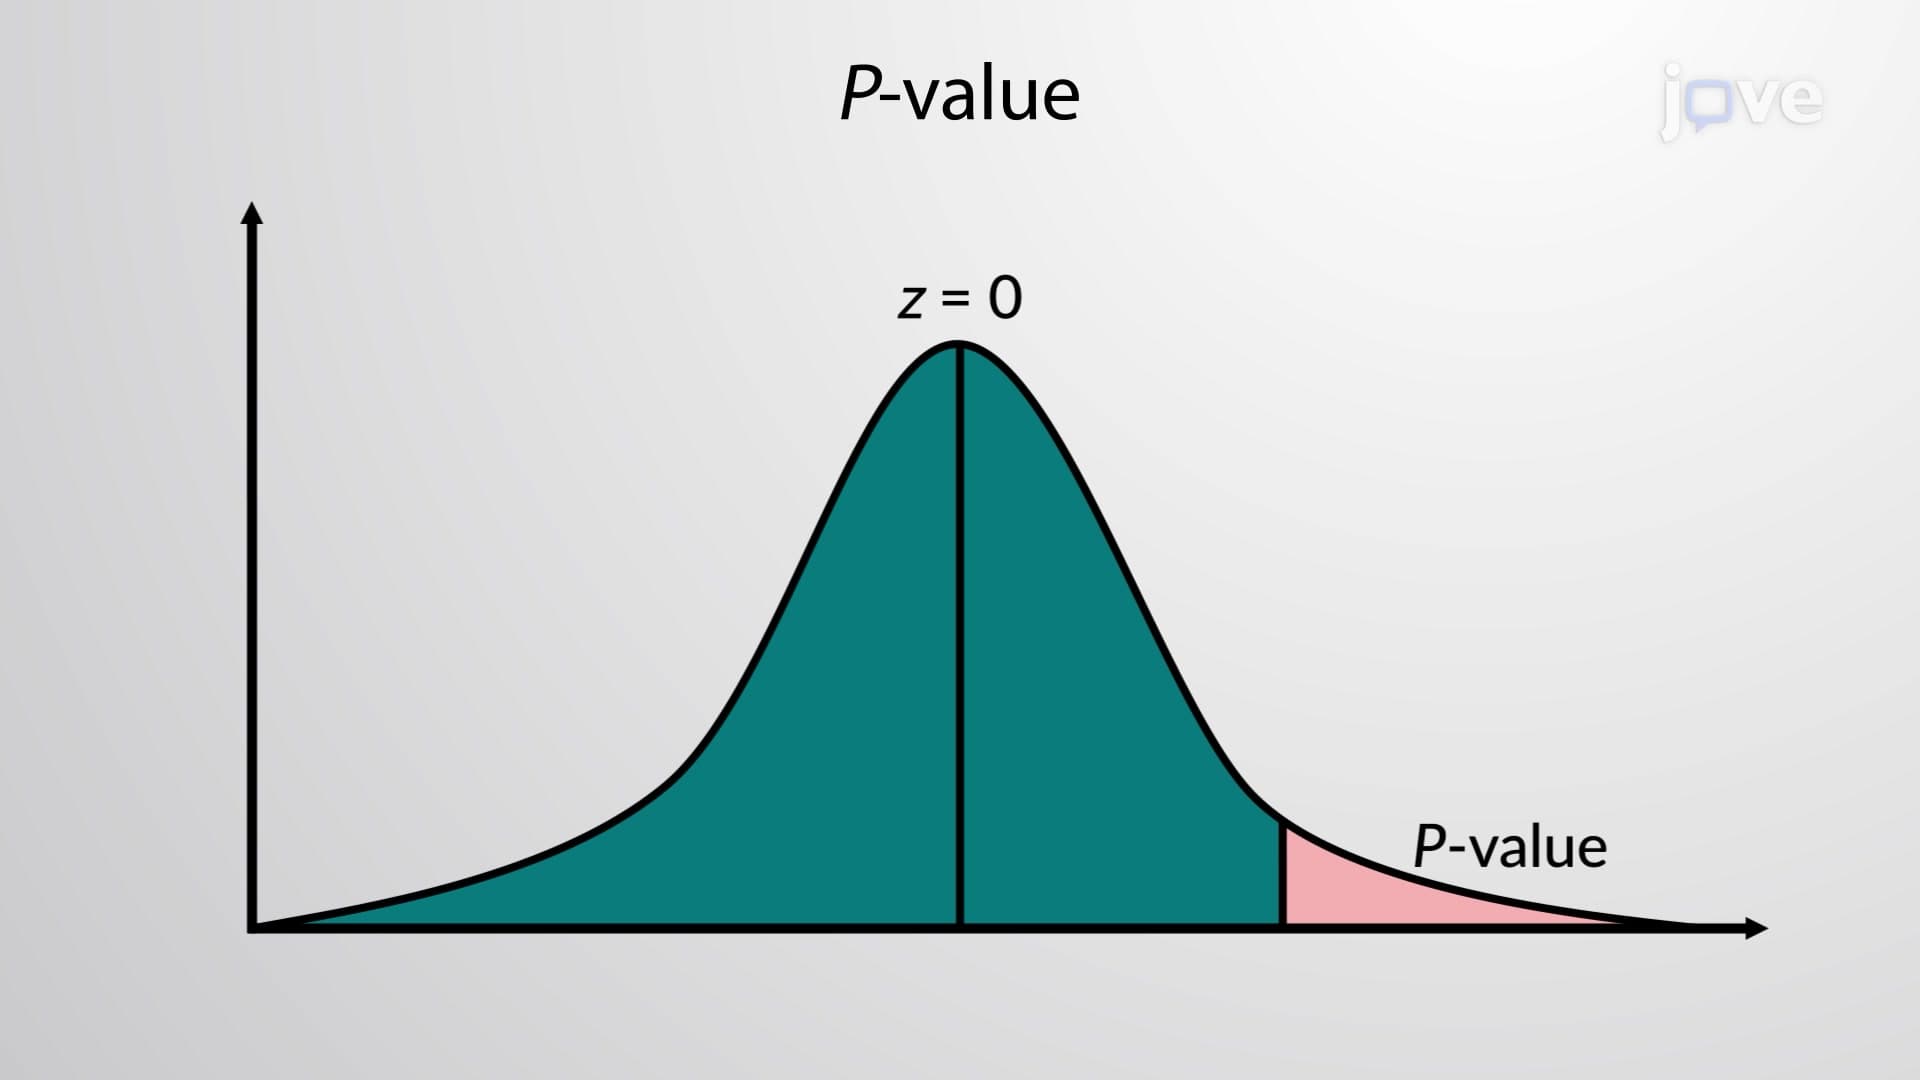
The process of hypothesis testing based on the P-value method includes calculating the P- value using the sample data and interpreting it.
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
First, a specific claim about the population parameter is proposed. The claim is based on the research question and is stated in a simple form. Further, an opposing statement to the claim is also stated. These statements can act as null and alternative hypotheses: a null hypothesis would be a neutral statement while the alternative hypothesis can...
5.5K
 01:10
Bonferroni Test
2.8K
The Bonferroni test is a statistical test named after Carlo Emilio Bonferroni, an Italian mathematician best known for Bonferroni inequalities. This statistical test is a type of multiple comparison test to determine which means are different than the rest. Bonferroni test can minimize the Type 1 error by reducing the significance level alpha, which otherwise increases with sample pairs.
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
The means of different samples are first paired in all possible combinations.
The null hypothesis of the...
2.8K
 01:19
Sieve Analysis and Grading Curves
415
Sieve analysis is a method used to determine the particle size distribution of aggregate materials. This process involves the following steps:
415
 01:24
Confidence Coefficient
7.7K
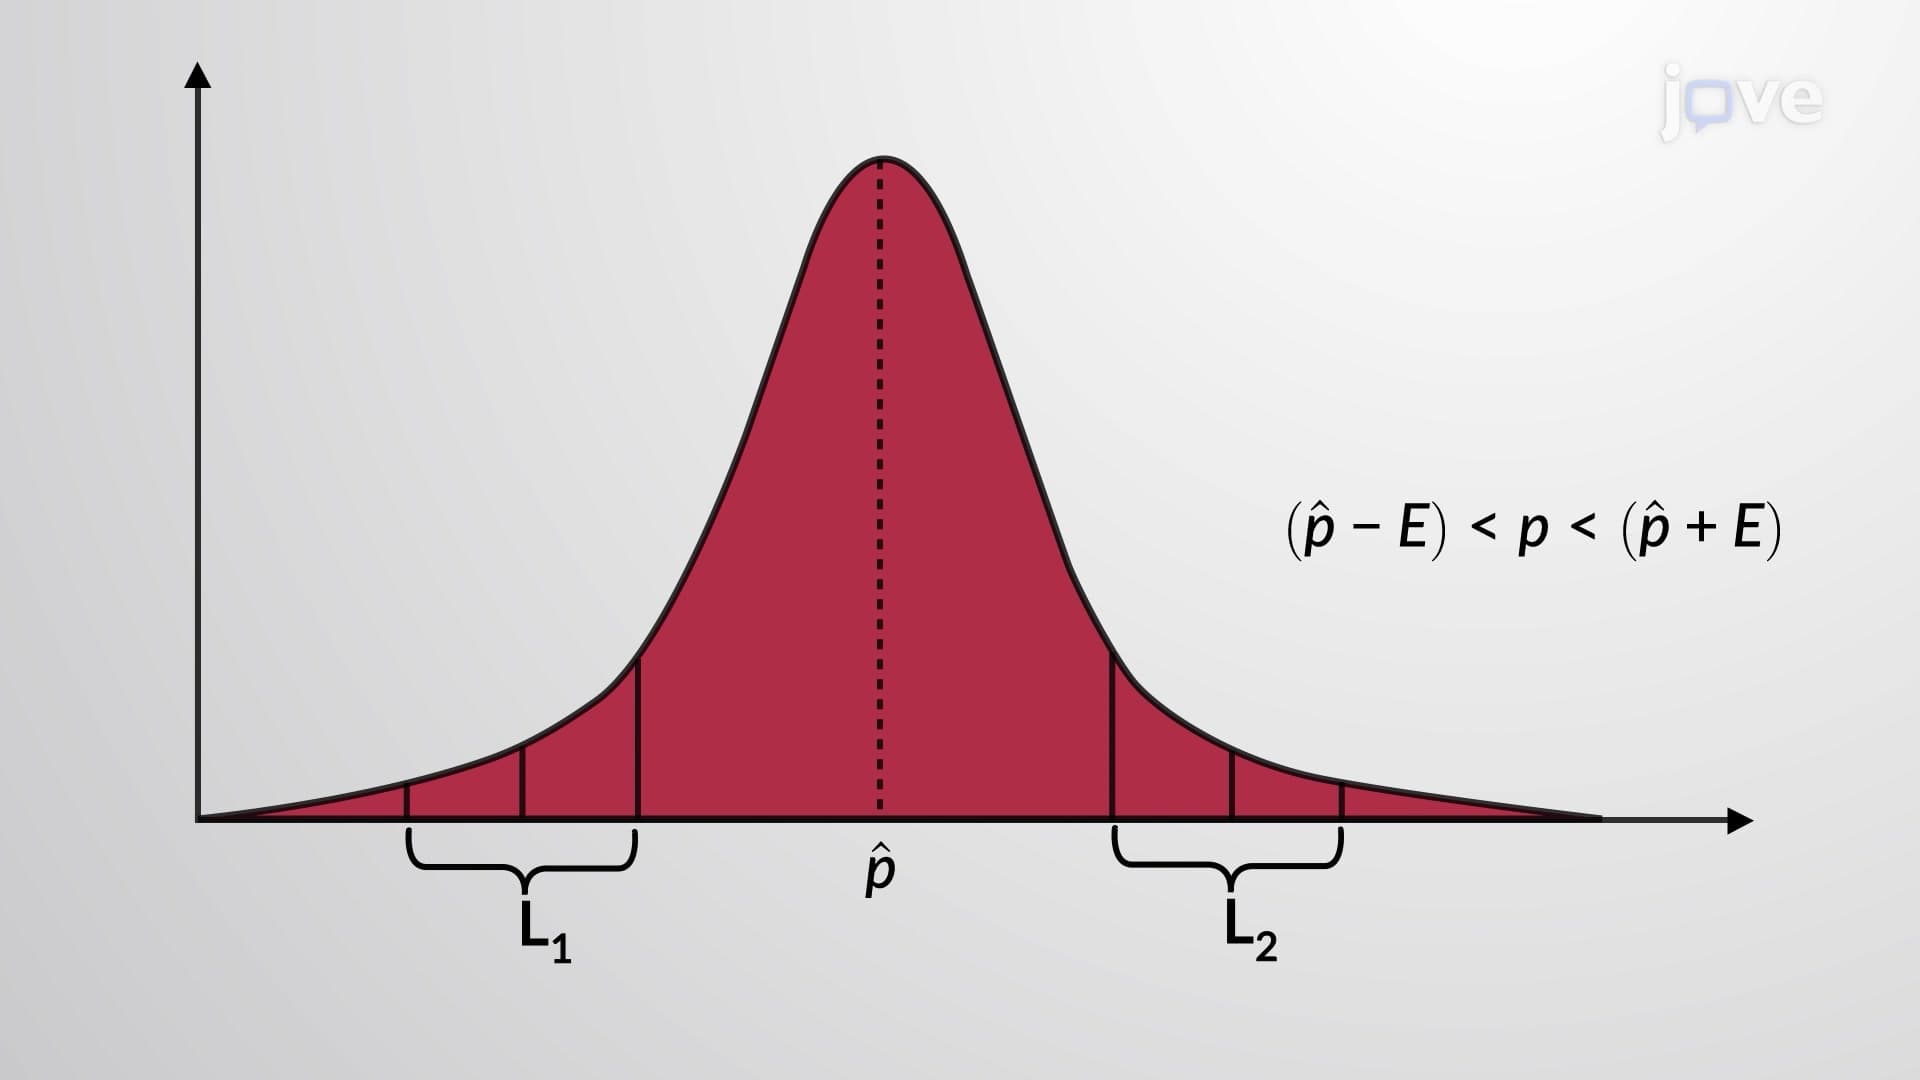
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.7K