
使用谷歌趋势测量足球运动员的受欢迎程度
Pilar Malagón-Selma1, Ana Debón1, Josep Domenech2
1Centro de Gestión de la Calidad y del Cambio, Universitat Politècnica de València, Valencia, Spain.
PloS one
|August 16, 2023

概括
这项研究引入了来自谷歌趋势的新人气指标,以预测足球运动员的市场价值. 这种新的方法在各种机器学习模型中提高了预测准确性,而低利息时期的玩家人气最具影响力.
科学领域:
- 运动分析 运动分析
- 数据科学数据科学数据科学
- 计算社会科学 计算社会科学
背景情况:
- 谷歌趋势是体育分析中未充分利用的资源,用于评估球员的受欢迎程度.
- 现有的球员估值方法往往忽视了人气指标.
- 准确的球员市场价值预测对于体育组织至关重要.
研究的目的:
- 开发和验证使用谷歌趋势来预测足球运动员市场价值的新型人气指标.
- 在不同的机器学习模型中比较这些指标的预测能力.
- 确定市场价值评估中最有影响力的受欢迎度指标.
主要方法:
- 利用谷歌趋势数据计算了六个不同的玩家受欢迎度指标.
- 开发了一种使用"人气层"来比较不平等人气的球员的方法.
- 应用累积转换因子来重新调整指标以获得统一的尺度.
- 将这些指标集成到多重线性回归,随机森林和梯度增强机器模型中.
主要成果:
- 提出的受欢迎度指标显著提高了对球员市场价值的预测.
- 将这些指标纳入所有测试的机器学习模型中减少了预测错误.
- 人气指标"Min",反映了玩家兴趣较低的时期,对市场价值产生了最实质性的影响.
结论:
- 来自谷歌趋势的新型人气指标对于预测玩家市场价值非常有价值.
- "Min"指标特别重要,突出了持续,即使较低,受欢迎程度的重要性.
- 该方法为体育分析和任何受欢迎程度影响价值的领域提供了实际应用.
相关概念视频
 00:57
Percentage Frequency Distribution
58.6K
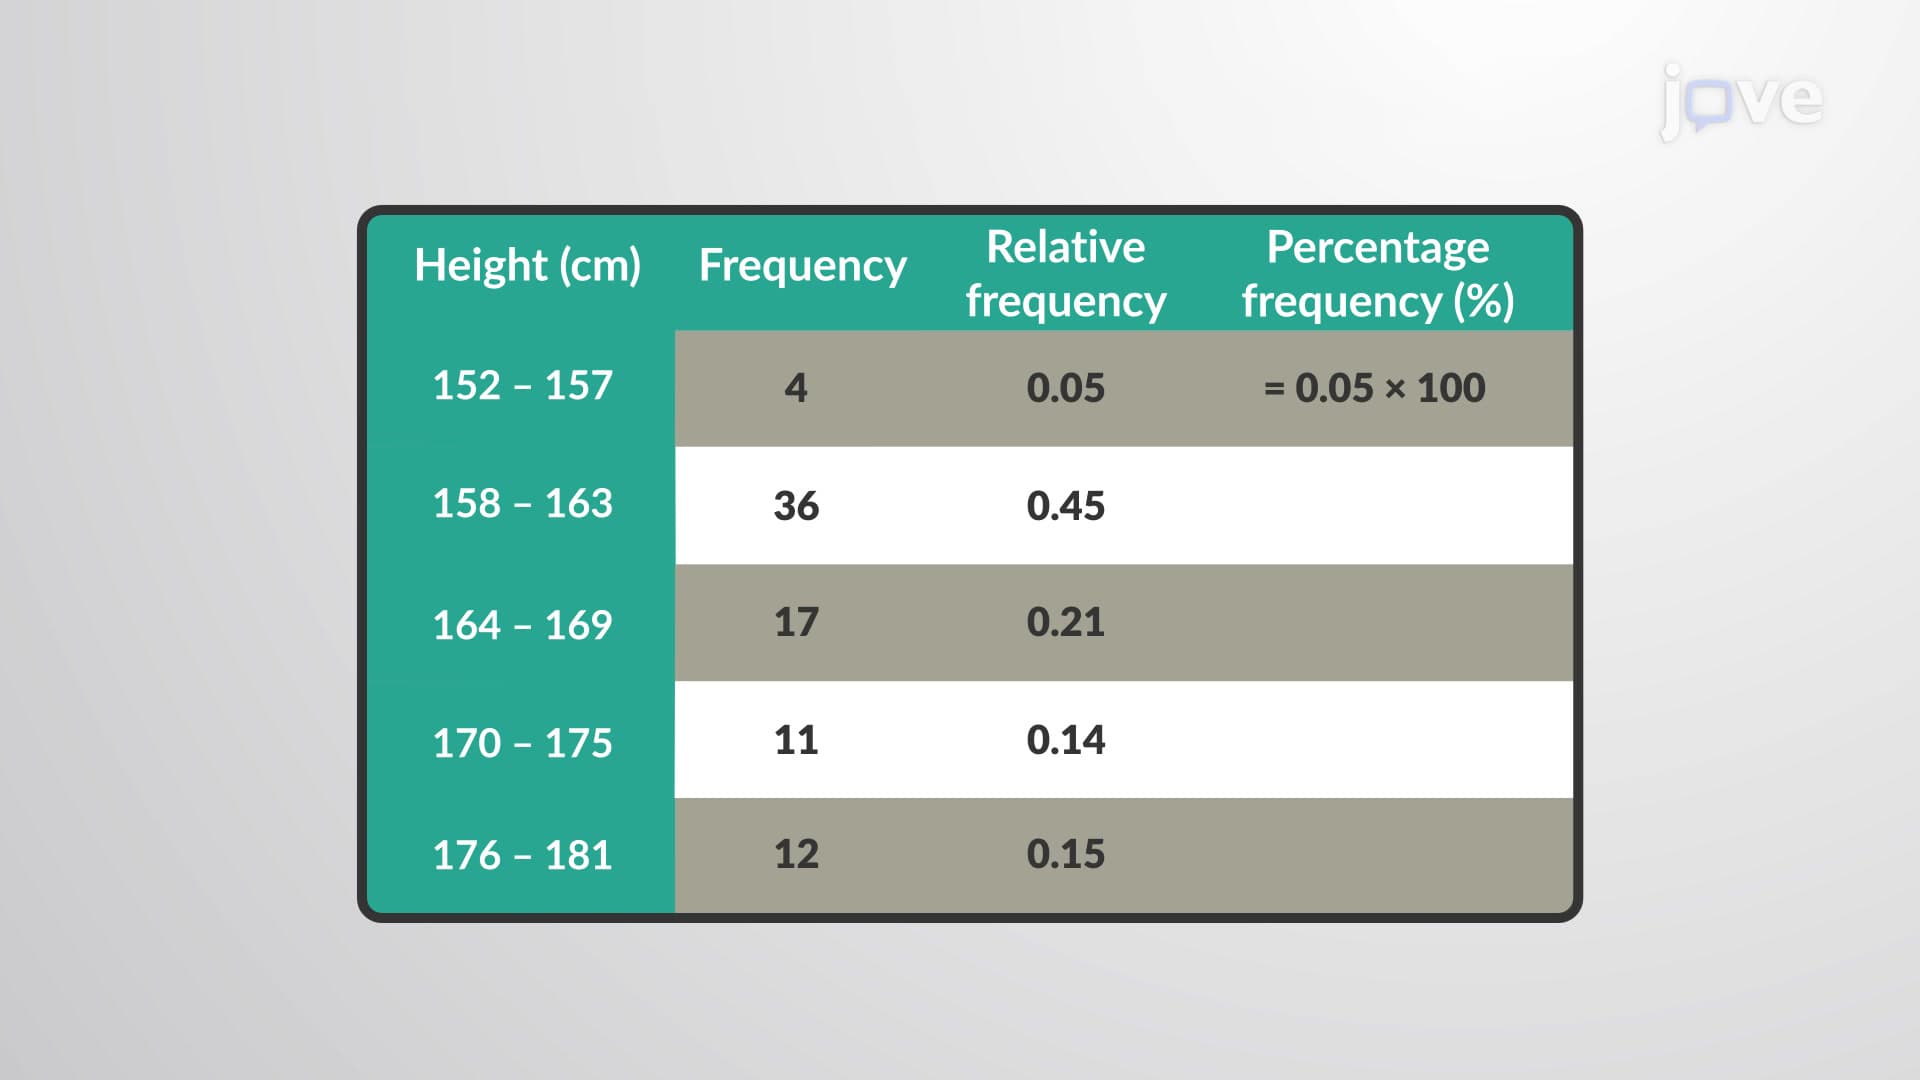
A percentage frequency distribution, in general, is a display of data that indicates the percentage of observations for each data point or grouping of data points. It is a commonly used method for expressing the relative frequency of survey responses and other data. The percentage frequency distributions are often displayed as bar graphs, pie charts, or tables.
The process of making a percentage frequency distribution involves the following few steps: note the total number of observations;...
The process of making a percentage frequency distribution involves the following few steps: note the total number of observations;...
58.6K
 00:55
Relative Frequency Distribution
11.0K
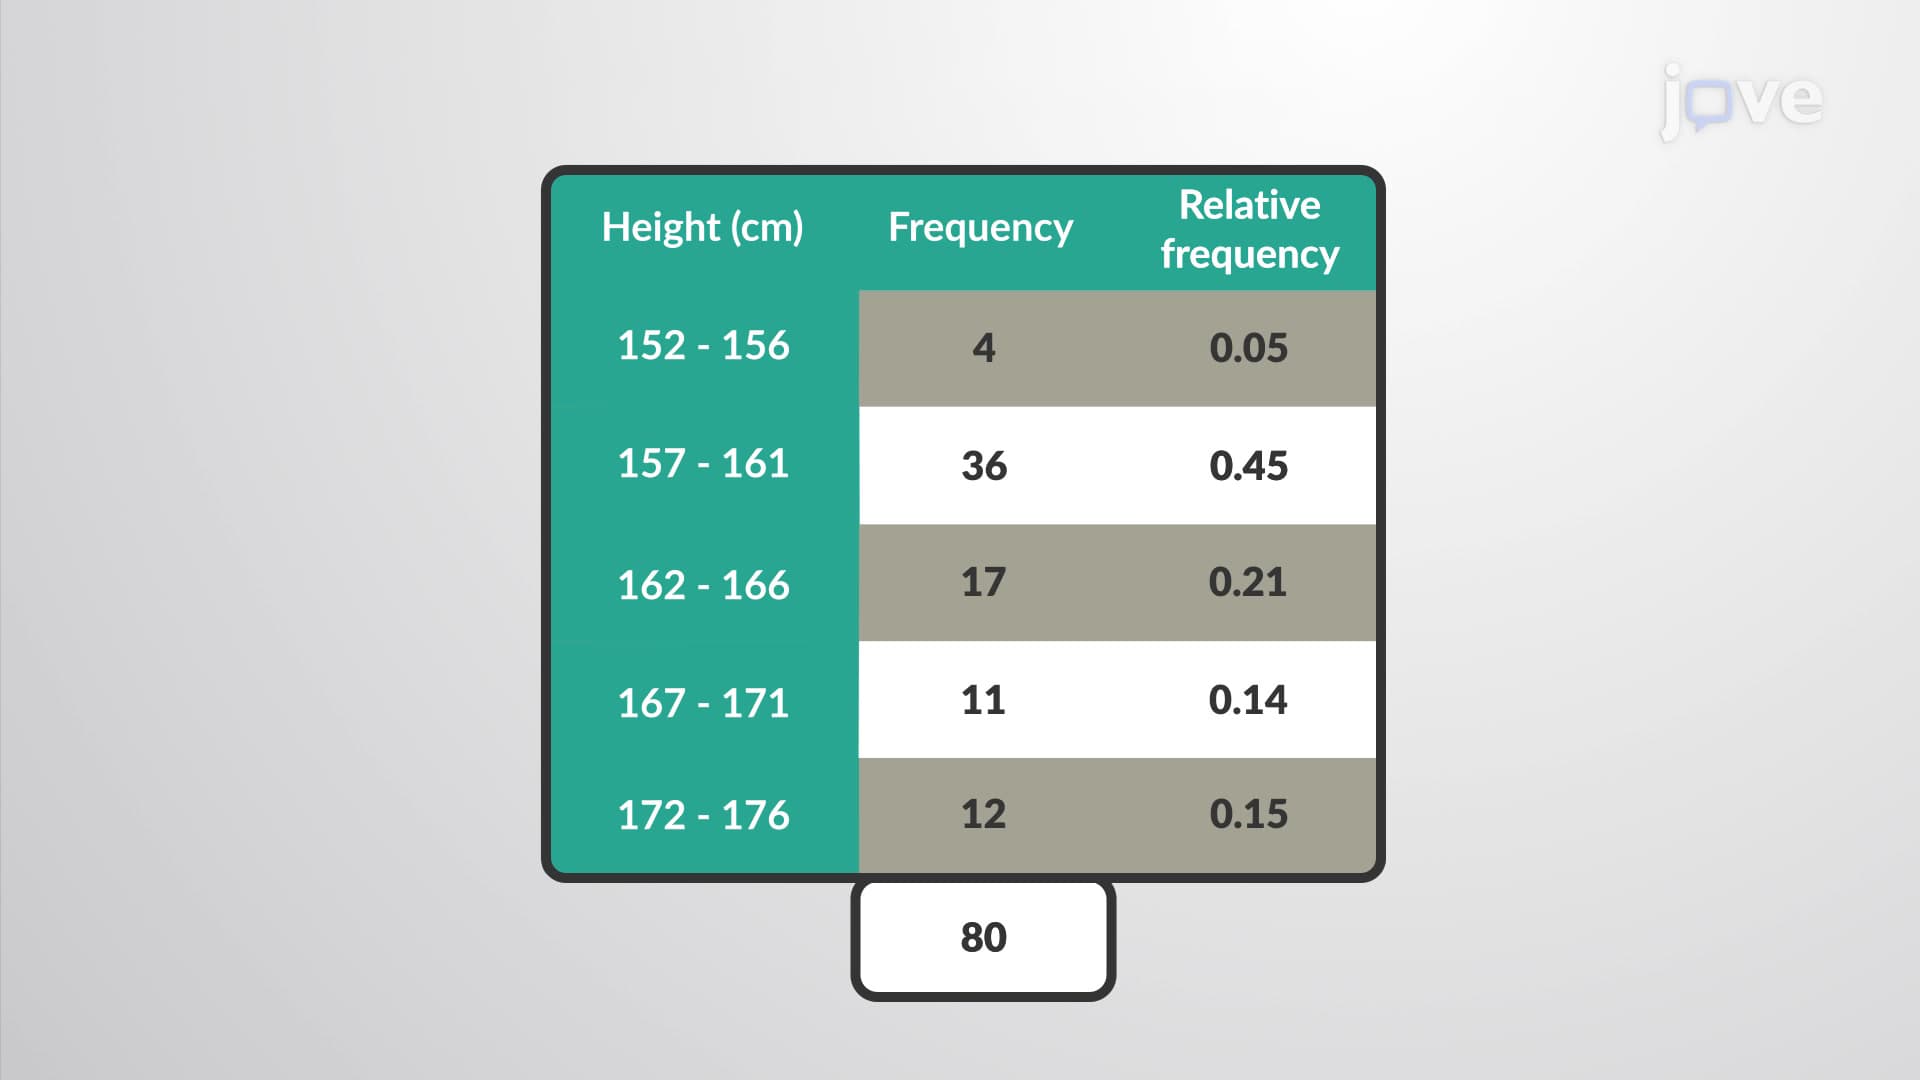
A relative frequency distribution is the proportion or fraction of times a value occurs in a data set. To find the relative frequencies, one can divide each frequency by the total number of data points in the sample. It is very similar to a regular frequency distribution, except that instead of reporting how many data values fall in a class, a relative frequency distribution reports the fraction of data values that fall in a class. These fractions or proportions are called relative frequencies...
11.0K
 01:10
Standard Deviation
16.8K
The most commonly used measure of variation is the standard deviation. It is a numerical value measuring how far data values are from their mean. The standard deviation value is small when the data are concentrated close to the mean, exhibiting slight variation or spread. The standard deviation value is never negative, it is either positive or zero. The standard deviation is larger when the data values are more spread out from the mean, which means the data values are exhibiting more variation.
16.8K
 01:02
Ranks
261
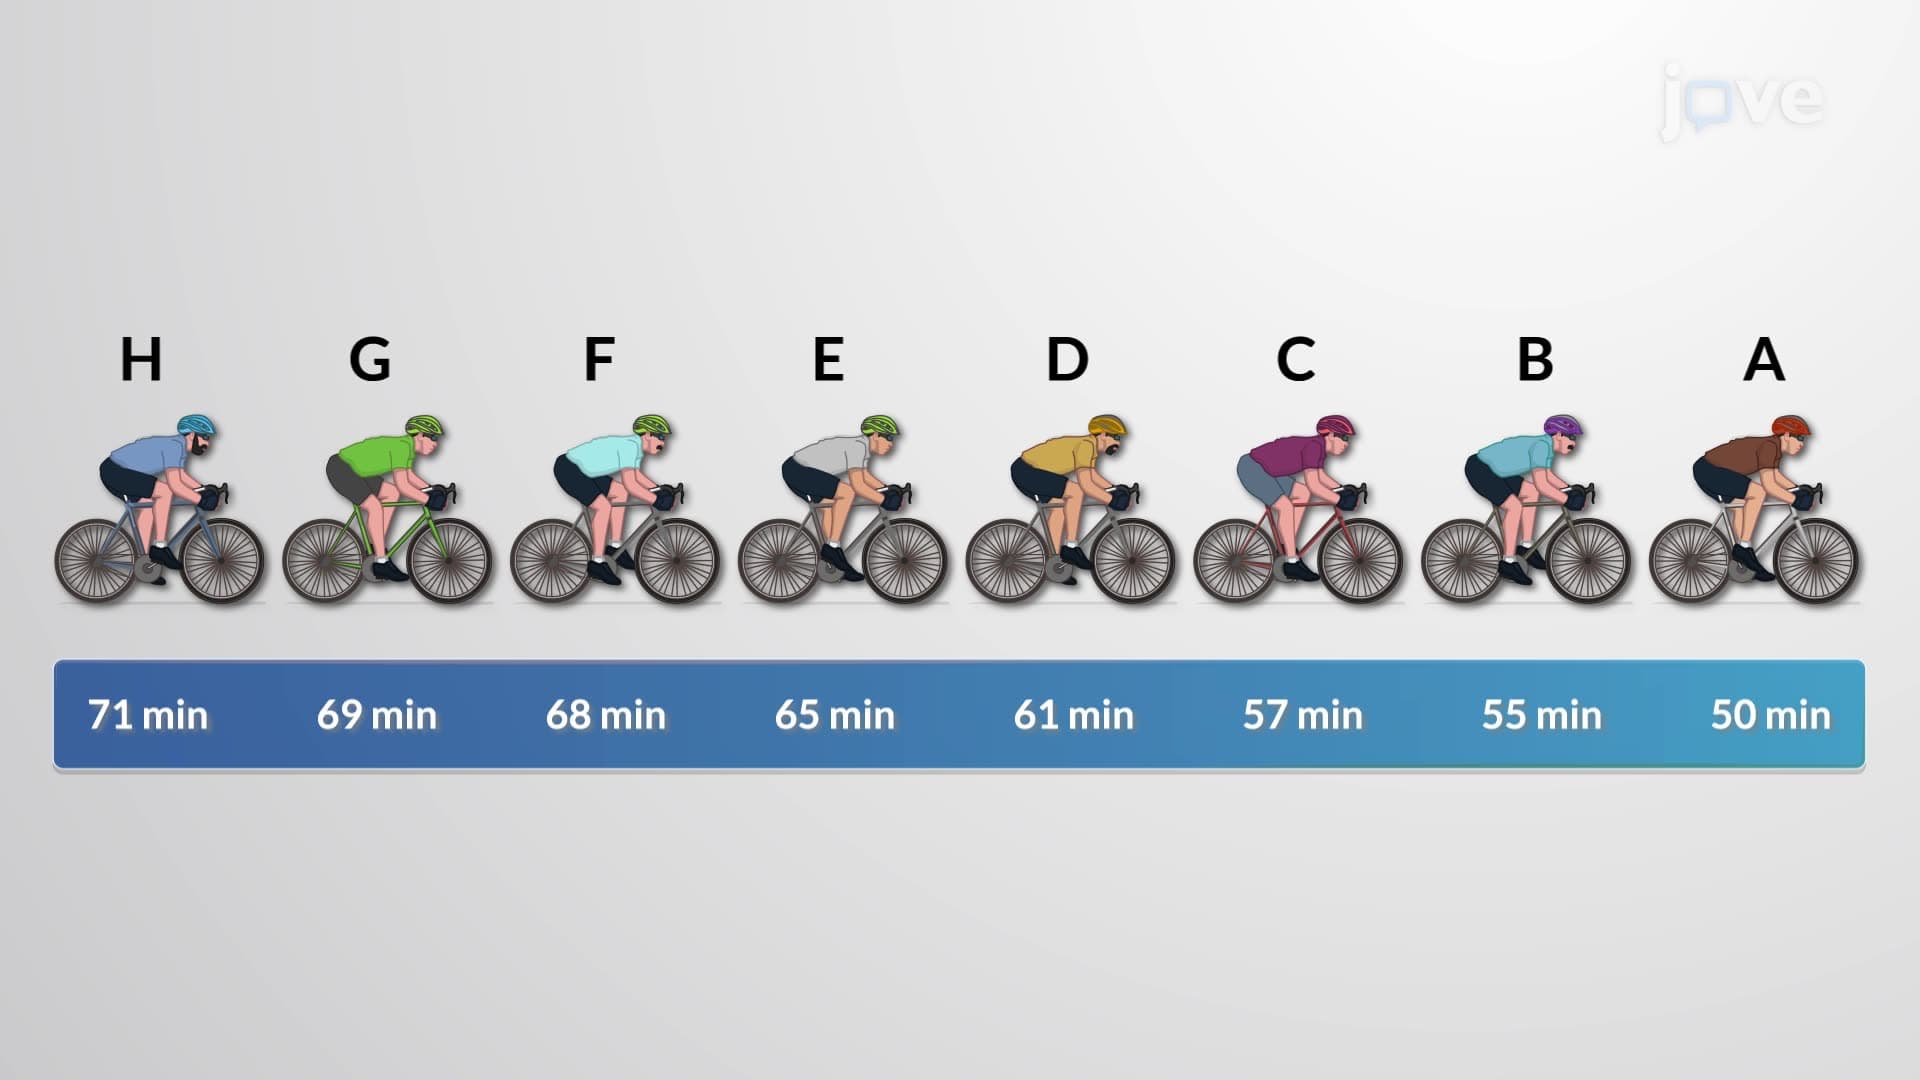
Unlike parametric methods, nonparametric statistics are ideal for nominal and ordinal data, requiring fewer assumptions about the population's nature or distribution. This makes nonparametric methods easier to apply and interpret, as they do not depend on parameters like mean or standard deviation. One common approach in nonparametric analysis is to sort data according to a specific criterion. For instance, we might arrange weather data from hottest to coldest days in a month or rank cities...
261
 01:12
Boxplot
8.5K
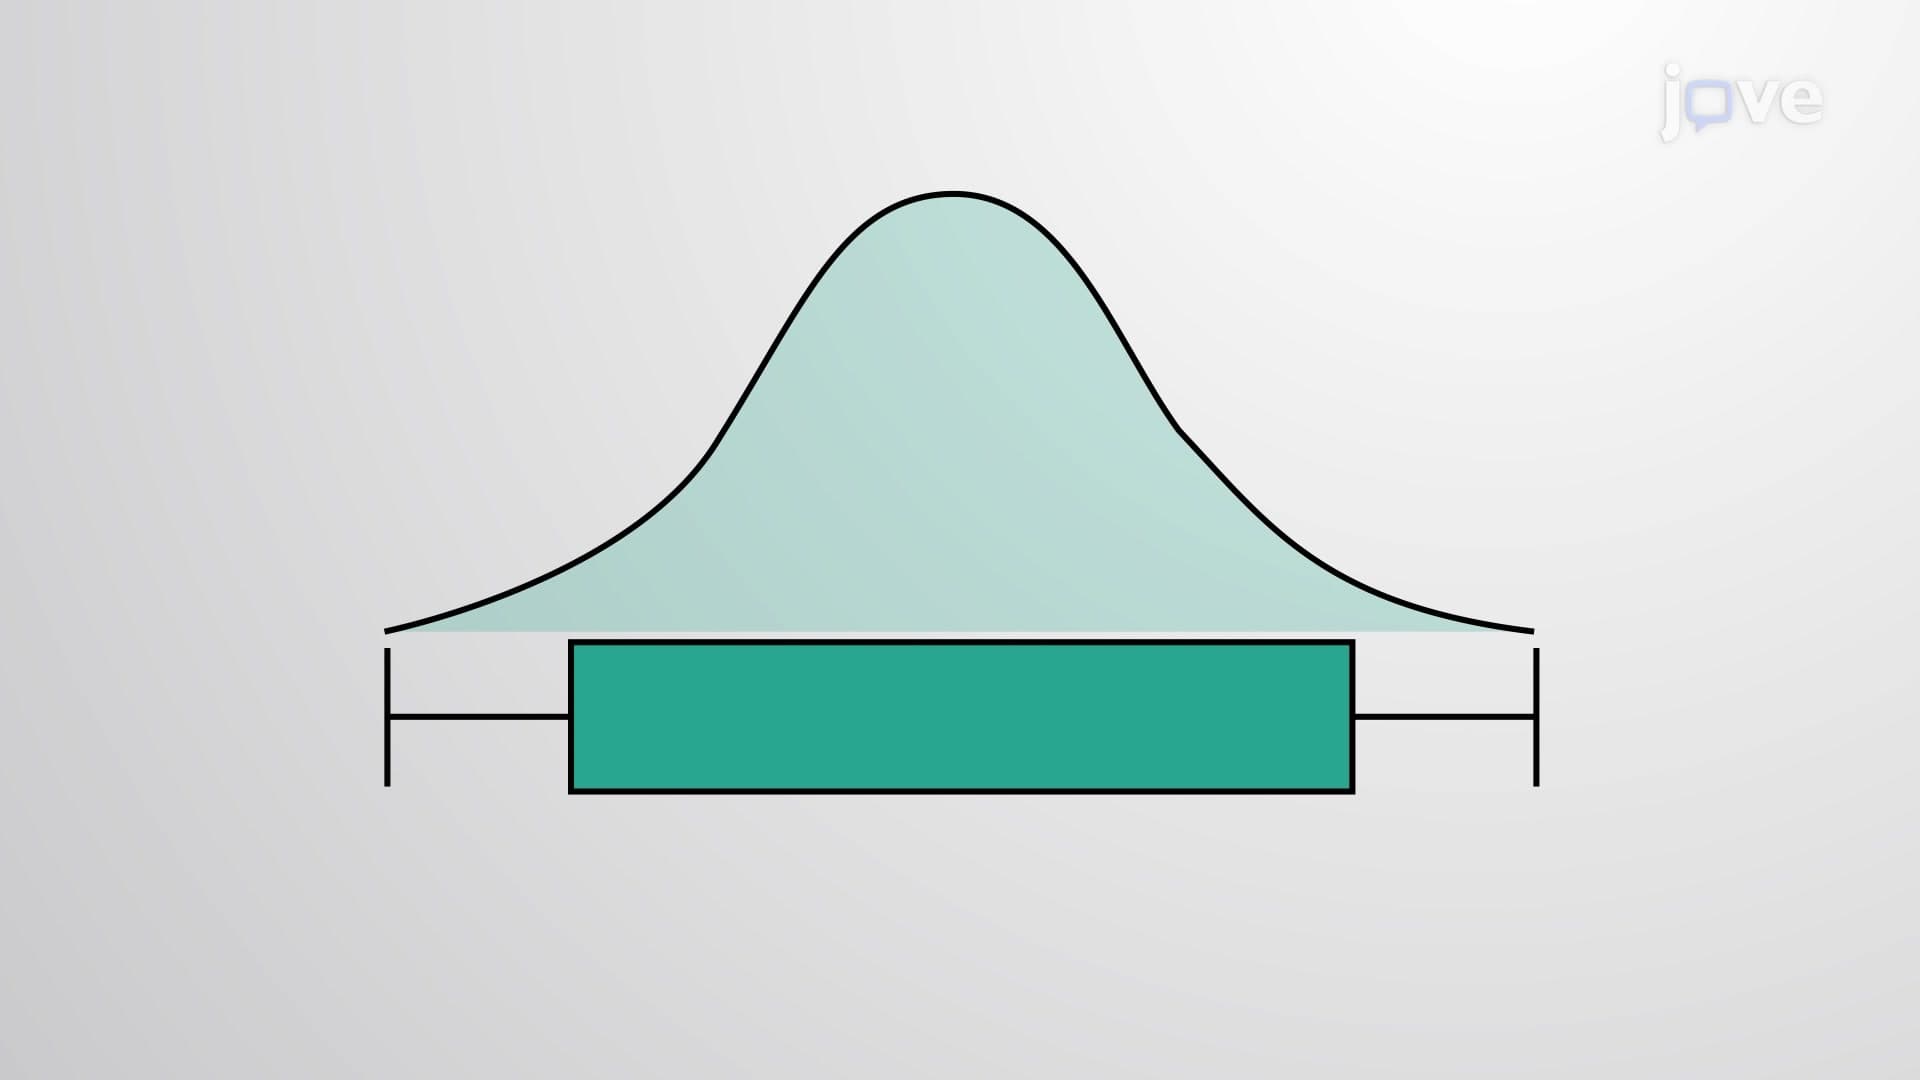
Box plots (also called box-and-whisker plots or box-whisker plots) give an excellent graphical image of the concentration of the data. They also show how far the extreme values are from most data. A box plot is constructed from five values: the minimum value, the first quartile, the median, the third quartile, and the maximum value. We use these values to compare how close other data values are to them. To construct a box plot, use a horizontal or vertical number line and a rectangular box. The...
8.5K
 01:05
Estimation of the Physical Quantities
4.4K
On many occasions, physicists, other scientists, and engineers need to make estimates of a particular quantity. These are sometimes referred to as guesstimates, order-of-magnitude approximations, back-of-the-envelope calculations, or Fermi calculations. The physicist Enrico Fermi was famous for his ability to estimate various kinds of data with surprising precision. Estimating does not mean guessing a number or a formula at random. Instead, estimation means using prior experience and sound...
4.4K