模糊的库尔巴克-莱布勒分歧用于模糊数据中概率分布的估计参数:用于分类越南草本叶的一种应用
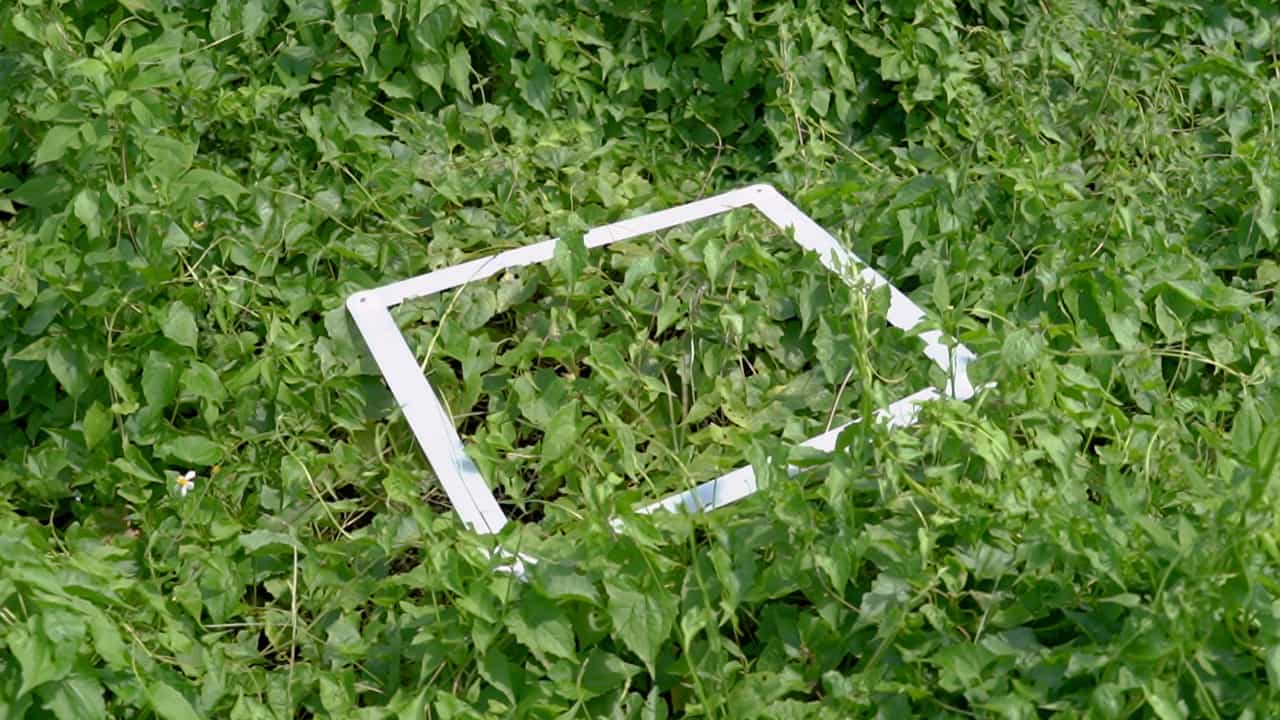
Hoa Le1, Vu Ngoc Thanh Sang2, Le Nhi Lam Thuy2
1University of Economics and Law and Vietnam National University, Ho Chi Minh City, Vietnam.
Scientific reports
|September 4, 2023

概括
本研究引入了模糊参数和贝叶斯统计学,以改善对真实数据的概率分布估计. 新方法提高了分类任务的灵活性和准确性,例如识别越南草药叶.
科学领域:
- 统计 统计 统计 统计
- 机器学习 机器学习
- 数据科学数据科学数据科学
背景情况:
- 基于参数的概率分布估计容易出现错误,并且无法捕捉现实世界的数据复杂性.
- 现实世界的数据集往往表现出混合的概率分布,子数据集中的信息不完整.
研究的目的:
- 提出一种新的方法来描述通过贝叶斯统计学估计的参数.
- 通过引入模糊参数来提高分类问题的灵活性.
- 为复杂数据集提供更强大的概率分布估计.
主要方法:
- 在贝叶斯统计框架内引入模糊参数.
- 使用模糊扩展的库尔巴克-莱布勒分歧评估概率分布相似性.
- 在越南草本叶子分类中的应用和验证.
主要成果:
- 与传统方法相比,拟议的方法提供了更强大的概率分布估计.
- 纳入模糊参数可以提高分类任务的灵活性.
- 在现实应用中成功演示 (越南草本叶分类).
结论:
- 模糊参数与贝叶斯统计学相结合,为估计复杂的概率分布提供了一个强大的方法.
- 该方法提高了分类的准确性和灵活性,特别是对于信息不完整的数据集.
- 这种方法对各种数据分析和机器学习应用有重大影响.
更多相关视频
 05:56
Objectification of Tongue Diagnosis in Traditional Medicine, Data Analysis, and Study Application
Published on: April 14, 2023
2.5K
 07:29
HPLC Coupled with Chemical Fingerprinting for Multi-Pattern Recognition for Identifying the Authenticity of Clematidis Armandii Caulis
Published on: November 11, 2022
2.1K
相关概念视频
 02:46
Chi-square Analysis
38.3K
The chi-square test is a statistical hypothesis test. It is used to check whether there is a significant difference between an expected value and an observed value. In the context of genetics, it enables us to either accept or reject a hypothesis, based on how much the observed values deviate from the expected values.
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
The chi-square test was developed by Pearson in 1990.
The first step of performing a Chi-square analysis is to establish a null hypothesis, which assumes that there is no real...
38.3K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.6K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.6K
 01:19
F Distribution
3.7K
The F distribution was named after Sir Ronald Fisher, an English statistician. The F statistic is a ratio (a fraction) with two sets of degrees of freedom; one for the numerator and one for the denominator. The F distribution is derived from the Student's t distribution. The values of the F distribution are squares of the corresponding values of the t distribution. One-Way ANOVA expands the t test for comparing more than two groups. The scope of that derivation is beyond the level of this...
3.7K
 01:30
Classification of Leukocytes
2.0K
Leukocytes are classified into two groups based on the presence or absence of cytoplasmic granules. Granular leukocytes, which contain granules, belong to the myeloid lineage and are divided into three subtypes: neutrophils, eosinophils, and basophils. These cells are roughly spherical and characterized by the granules in their cytoplasm.
Neutrophils are the most abundant type of granular leukocytes, comprising 50-70% of all leukocytes. They feature small, evenly distributed granules and a...
Neutrophils are the most abundant type of granular leukocytes, comprising 50-70% of all leukocytes. They feature small, evenly distributed granules and a...
2.0K
 01:32
Probability Distributions
7.2K
The probability of a random variable x is the likelihood of its occurrence. A probability distribution represents the probabilities of a random variable using a formula, graph, or table. There are two types of probability distribution– discrete probability distribution and continuous probability distribution.
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
A discrete probability distribution is a probability distribution of discrete random variables. It can be categorized into binomial probability distribution and Poisson...
7.2K
 01:06
Model Approaches for Pharmacokinetic Data: Distributed Parameter Models
96
Pharmacokinetic models are mathematical constructs that represent and predict the time course of drug concentrations in the body, providing meaningful pharmacokinetic parameters. These models are categorized into compartment, physiological, and distributed parameter models.
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
The distributed parameter models are specifically designed to account for variations and differences in some drug classes. This model is particularly useful for assessing regional concentrations of anticancer or...
96