彩票大奖存在于预训练模型中

IEEE transactions on pattern analysis and machine intelligence
|September 5, 2023

概括
发现"彩票大奖",在没有体重训练的预训练模型中发现的稀疏子网络. 这些高效的彩票大奖大大降低了网络复杂性,同时保持了高性能,使神经网络的修剪速度更快.
科学领域:
- 人工智能的人工智能
- 计算机科学 计算机科学
- 机器学习 机器学习
背景情况:
- 网络修剪可以减少模型的复杂性,但往往需要广泛的培训或广泛的网络.
- 现有的方法在计算上昂贵,并且限制了网络修剪的实际应用.
研究的目的:
- 在没有重量训练的情况下,在预先训练的模型中识别高性能,稀疏的子网络 (彩票大奖).
- 为了提高搜索这些彩票大奖的效率.
- 分析和优化彩票大奖搜索过程.
主要方法:
- 在没有修改权重的情况下,在预训练模型中识别稀疏的子网络 (彩票大奖).
- 利用基于大小的修剪来初始化稀疏的面具,降低搜索成本.
- 提出一种新的短限制方法,以稳定掩码搜索并改善收.
主要成果:
- 一个拥有10%VGGNet-19参数的彩票大奖子网络在没有重量训练的情况下在CIFAR-10上实现了原始性能.
- 基于大小的剪裁初始化至少减少了3倍的彩票大奖搜索成本.
- 一个ResNet-50彩票大奖在ImageNet上实现了>70%的top-1准确度,仅在5个搜索时代就消除了90%的重量.
结论:
- 高性能稀疏子网络 (彩票大奖) 存在于预训练模型中,提供高效的网络压缩.
- 优化的搜索策略,包括基于大小的初始化和短限制,显著提高了找到彩票大奖的效率.
- 这种方法可以在最小的性能损失下进行大量的模型压缩,使网络修剪更容易获得.


相关概念视频
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:09
Random Variables
12.3K
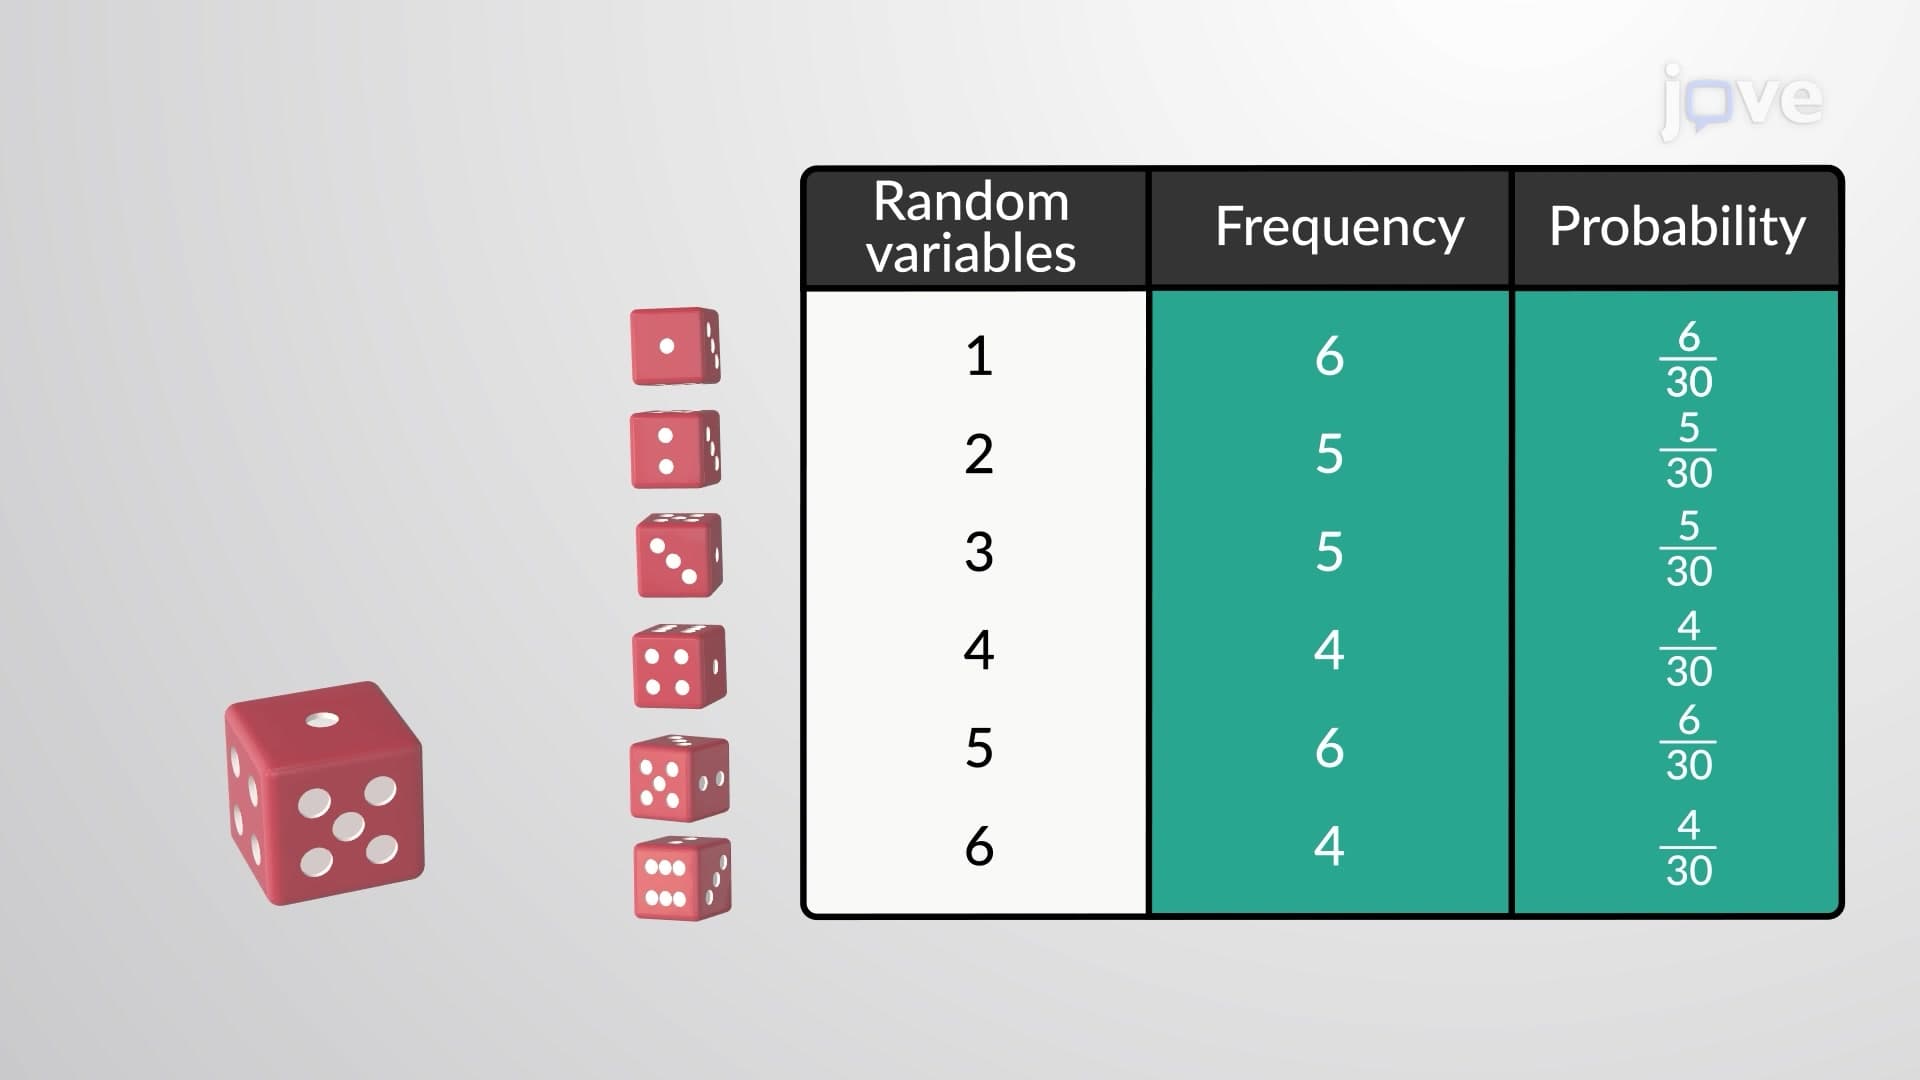
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
12.3K
 02:07
Improving Translational Accuracy
11.6K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
11.6K
 01:07
End Point Prediction: Gran Plot
377
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
377
 01:19
Survival Tree
109
Survival trees are a non-parametric method used in survival analysis to model the relationship between a set of covariates and the time until an event of interest occurs, often referred to as the "time-to-event" or "survival time." This method is particularly useful when dealing with censored data, where the event has not occurred for some individuals by the end of the study period, or when the exact time of the event is unknown.
Building a Survival Tree
Constructing a...
Building a Survival Tree
Constructing a...
109
 01:13
Randomized Experiments
7.0K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
7.0K