二次分解在通过机器学习准确预测每日大规模臭氧污染中的重要性
Xinyue Du1, Zibing Yuan1, Daojian Huang2
1School of Environment and Energy, South China University of Technology, Guangzhou 510006, China.
The Science of the total environment
|September 11, 2023

概括
这项研究改进了臭氧污染的预测,使用了一种新的二次分解机器学习模型. 这种新方法显著提高了每天8小时平均最大臭氧 (MDA8 O3) 水平和未达到水平的预测的准确性.
科学领域:
- 环境科学 环境科学
- 大气化学 大气化学
- 机器学习应用 机器学习应用
背景情况:
- 机器学习 (ML) 模型在预测环境污染方面是有效的,但由于复杂的影响因素,它们在每天8小时的最大平均臭氧 (MDA8 O3) 方面遇到了困难.
- 在MDA8 O3水平的不规则波动是由 synoptic 条件,局部光化学和远程传输驱动的,这给准确的预测带来了挑战.
- 准确的MDA8 O3预测对于污染的评估,管理和及时启动控制措施至关重要.
研究的目的:
- 开发和评估一种新的二次分解ML模型框架,以提高MDA8 O3预测准确度.
- 评估模型在预测O3污染未达到的效率方面的有效性,这是控制策略的关键指标.
- 调查珍珠河三角洲 (PRD) 地区预测准确度的空间变化.
主要方法:
- 开发了一种二次分解 ML 模型,将完整集体实证模式分解与自适应噪声 (CEEMDAN) 和变化模式分解 (VMD) 集成在一起.
- 在数据分解后进行预测时采用了Gate Recurrent Unit (GRU) ML模型.
- 将模型框架应用于中国珍珠河三角洲 (PRD) 的MDA8 O3预测.
主要成果:
- 二次分解ML模型显著提高了MDA8 O3预测准确度,从R2的0.46降至0.91,并将RMSE从30.4降至12.6μg/m3.
- 对O3污染的预测准确度大幅增加,从14.9%提高到72.5%.
- 由于局部污染动态,西南PRD观察到非实现的更高的预测准确性.
结论:
- 二次分解对于准确预测每日O3度和未达到的O3度至关重要.
- 开发的ML框架在O3污染预测和管理方面取得了重大进展.
- 这种方法可以扩展到全球其他地区,以加强O3预测并支持污染控制工作.
更多相关视频
 09:46
Production and Measurement of Organic Particulate Matter in the Harvard Environmental Chamber
Published on: November 18, 2018
7.3K
 10:25
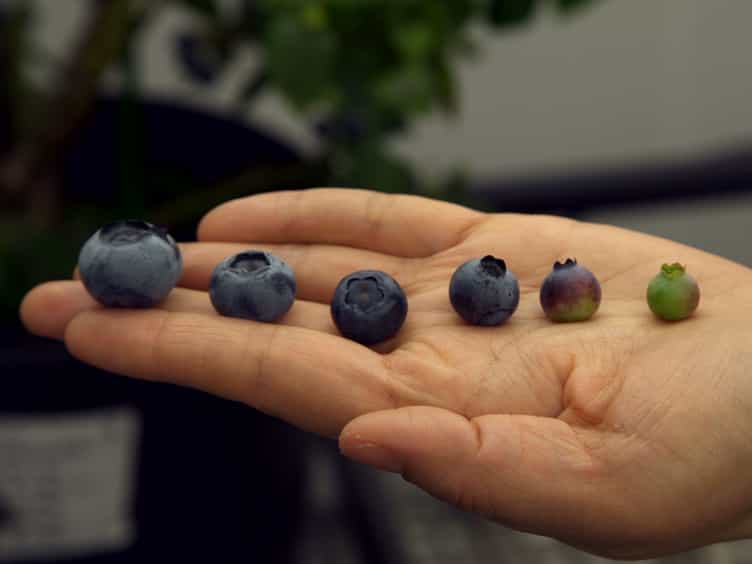
Construction of Models for Nondestructive Prediction of Ingredient Contents in Blueberries by Near-infrared Spectroscopy Based on HPLC Measurements
Published on: June 28, 2016
10.7K
相关概念视频
 02:24
Predicting Reaction Outcomes
8.5K
Kinetics describes the rate and path by which a reaction occurs. In contrast, thermodynamics deals with state functions and describes the properties, behavior, and components of a system. It is not concerned with the path taken by the process and cannot address the rate at which a reaction occurs. Although it does provide information about what can happen during a reaction process, it does not describe the detailed steps of what appears on an atomic or a molecular level. On the other hand,...
8.5K
 01:11
Regression Analysis
5.8K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.8K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
64
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
64
 01:18
Steps in Outbreak Investigation
152
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
152
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K