
这是谁的电话? 评估猜测谁在电话上的准确性
Helané Wahbeh1, Cedric Cannard1, Dean Radin1
1Research, Institute of Noetic Sciences, Petaluma, CA, USA.
Explore (New York, N.Y.)
|September 14, 2023

概括
这项研究探讨了识别呼叫者的心理能力. 在预先选择的试验中,准确性高于偶然性,表明潜在的psi现象,但在后选择的试验中没有. 遗传关系和通信频率影响了准确性.
科学领域:
- 心理学 心理学 心理学
- 帕拉心理学是一门学科.
背景情况:
- 事声称知道谁在打电话,没有传统的手段存在.
- 对这种能力的受控实验证据是混合的.
研究的目的:
- 使用受控实验设计,调查识别来电呼叫者的准确性.
- 探索遗传关系,情感亲密,沟通频率和身体距离对准确度的影响.
主要方法:
- 一项涉及三位一体的横截面研究进行了两种试验设计:心灵感应/预先选择和前认知/后选择.
- 用多层混合效应物流回归来分析准确性预测指标.
主要成果:
- 精度明显高于偶然性 (50.0%对33.3%) 在心灵感应/预先选择的试验 (p<.001).
- 在前认知/后选择试验 (p=.61) 中,准确性与偶然性没有显著差异 (31.9%与33.3%对比).
- 基因相关性 (25%相关性) 和通信频率显著预测了准确性 (P < .05).
结论:
- 结果支持了psi假设,尽管不能完全排除传统解释.
- 遗传亲属关系和通信频率似乎是影响呼叫者识别准确性的因素.
- 需要使用改进的方法进行进一步的研究,以了解机制和缓解因素.

相关概念视频
 01:00
Detection of Gross Error: The Q Test
6.2K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.2K
 01:28
Accuracy, limits, and approximation
474
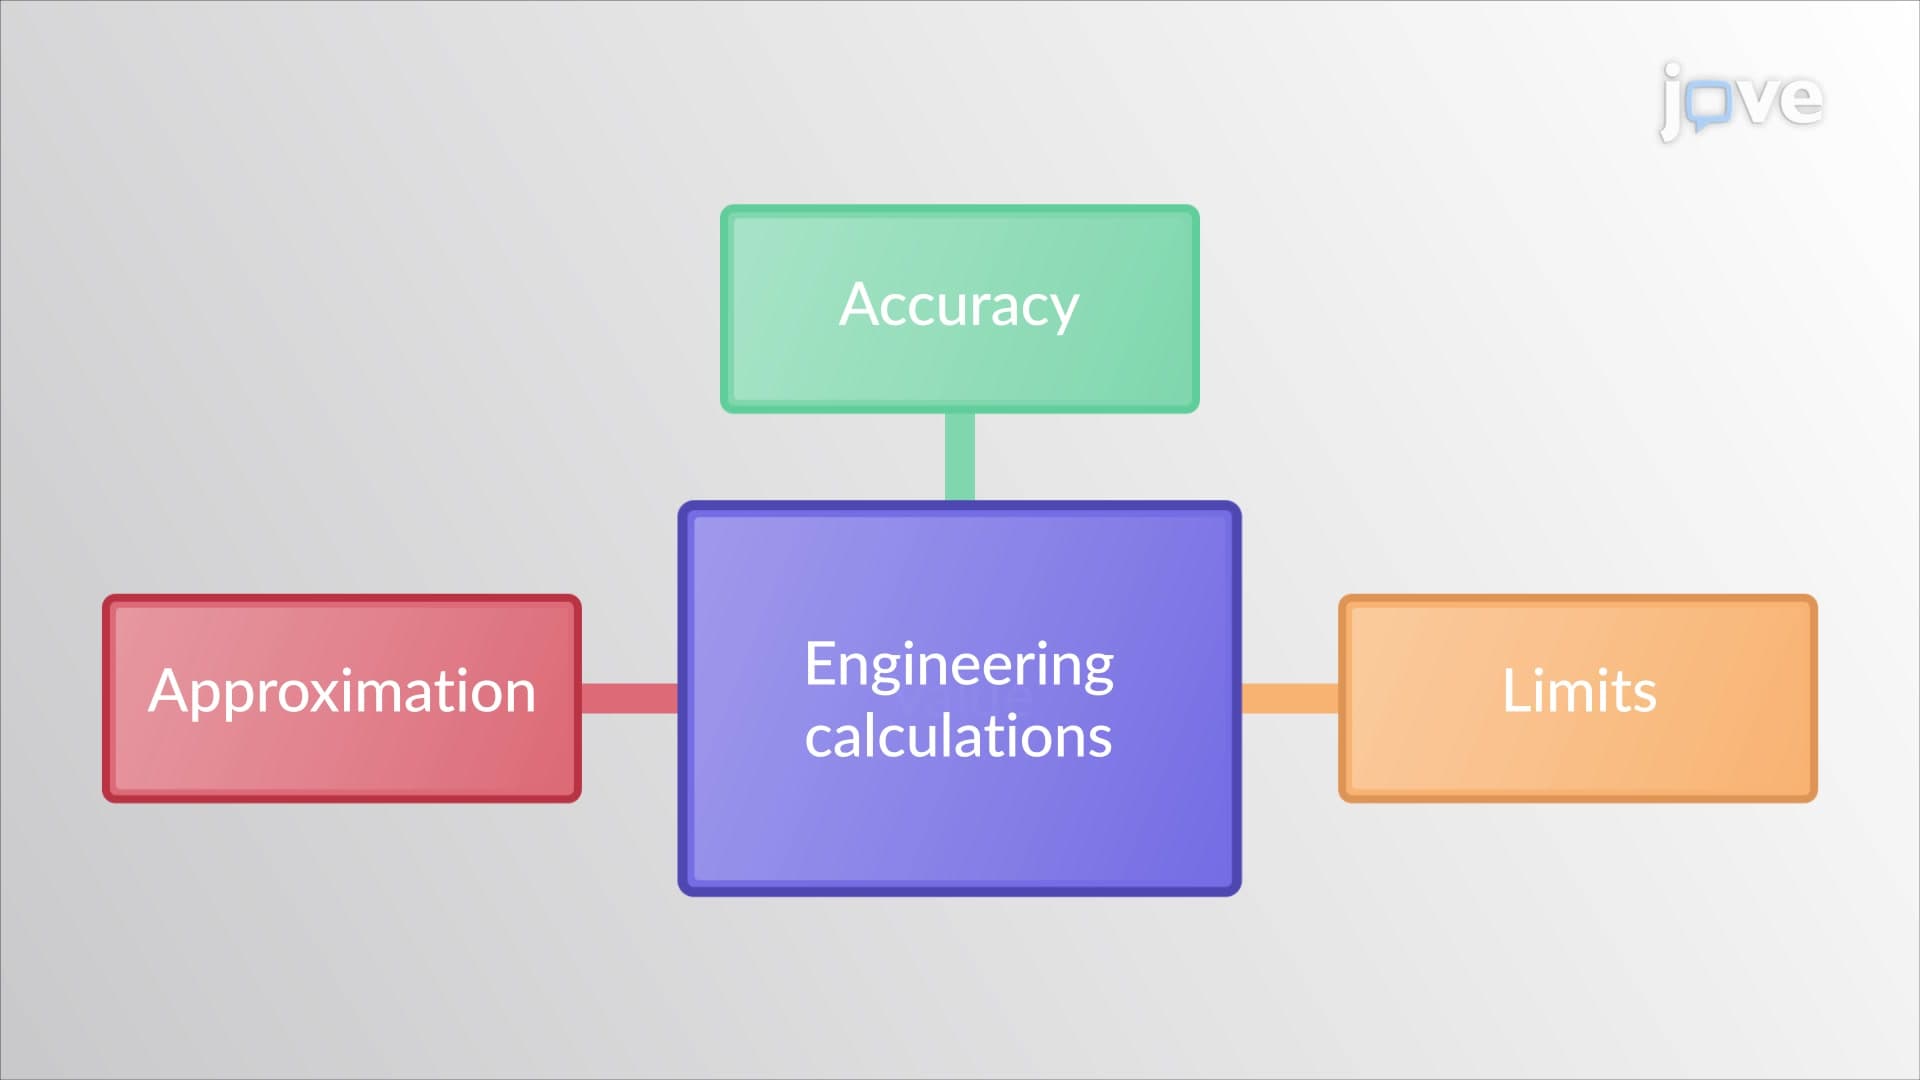
Accuracy, limits, and approximations are common in many fields, especially in engineering calculations. These concepts are imperative for ensuring that a given value is as close as possible to its true value.
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
Accuracy is defined as the closeness of the measured value to the true or actual value. In engineering mechanics, repeated measurements are taken during theoretical or experimental analyses to ensure that the result is precise and accurate.
The accuracy of any solution is based on the...
474
 02:13
The Representativeness Heuristic
15.8K
The representative heuristic describes a biased way of thinking, in which you unintentionally stereotype someone or something. For example, you may assume that your professors spend their free time reading books and engaging in intellectual conversation, because the idea of them spending their time playing volleyball or visiting an amusement park does not fit in with your stereotypes of professors.
15.8K
 01:13
Accuracy and Errors in Hypothesis Testing
220
Hypothesis testing is a fundamental statistical tool that begins with the assumption that the null hypothesis H0 is true. During this process, two types of errors can occur: Type I and Type II. A Type I error refers to the incorrect rejection of a true null hypothesis, while a Type II error involves the failure to reject a false null hypothesis.
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
220
 01:31
Confirmation Biases
5.5K
The confirmation bias is the tendency to focus on information that confirms our existing beliefs and ignore information that is inconsistent with our expectations. For example, if you think that your professor is not very nice, you notice all of the instances of rude behavior exhibited by the professor while ignoring the countless pleasant interactions he is involved in on a daily basis. Have you ever fallen prey to the confirmation bias, either as the source or target of such bias?
5.5K
 01:24
Confidence Coefficient
7.7K
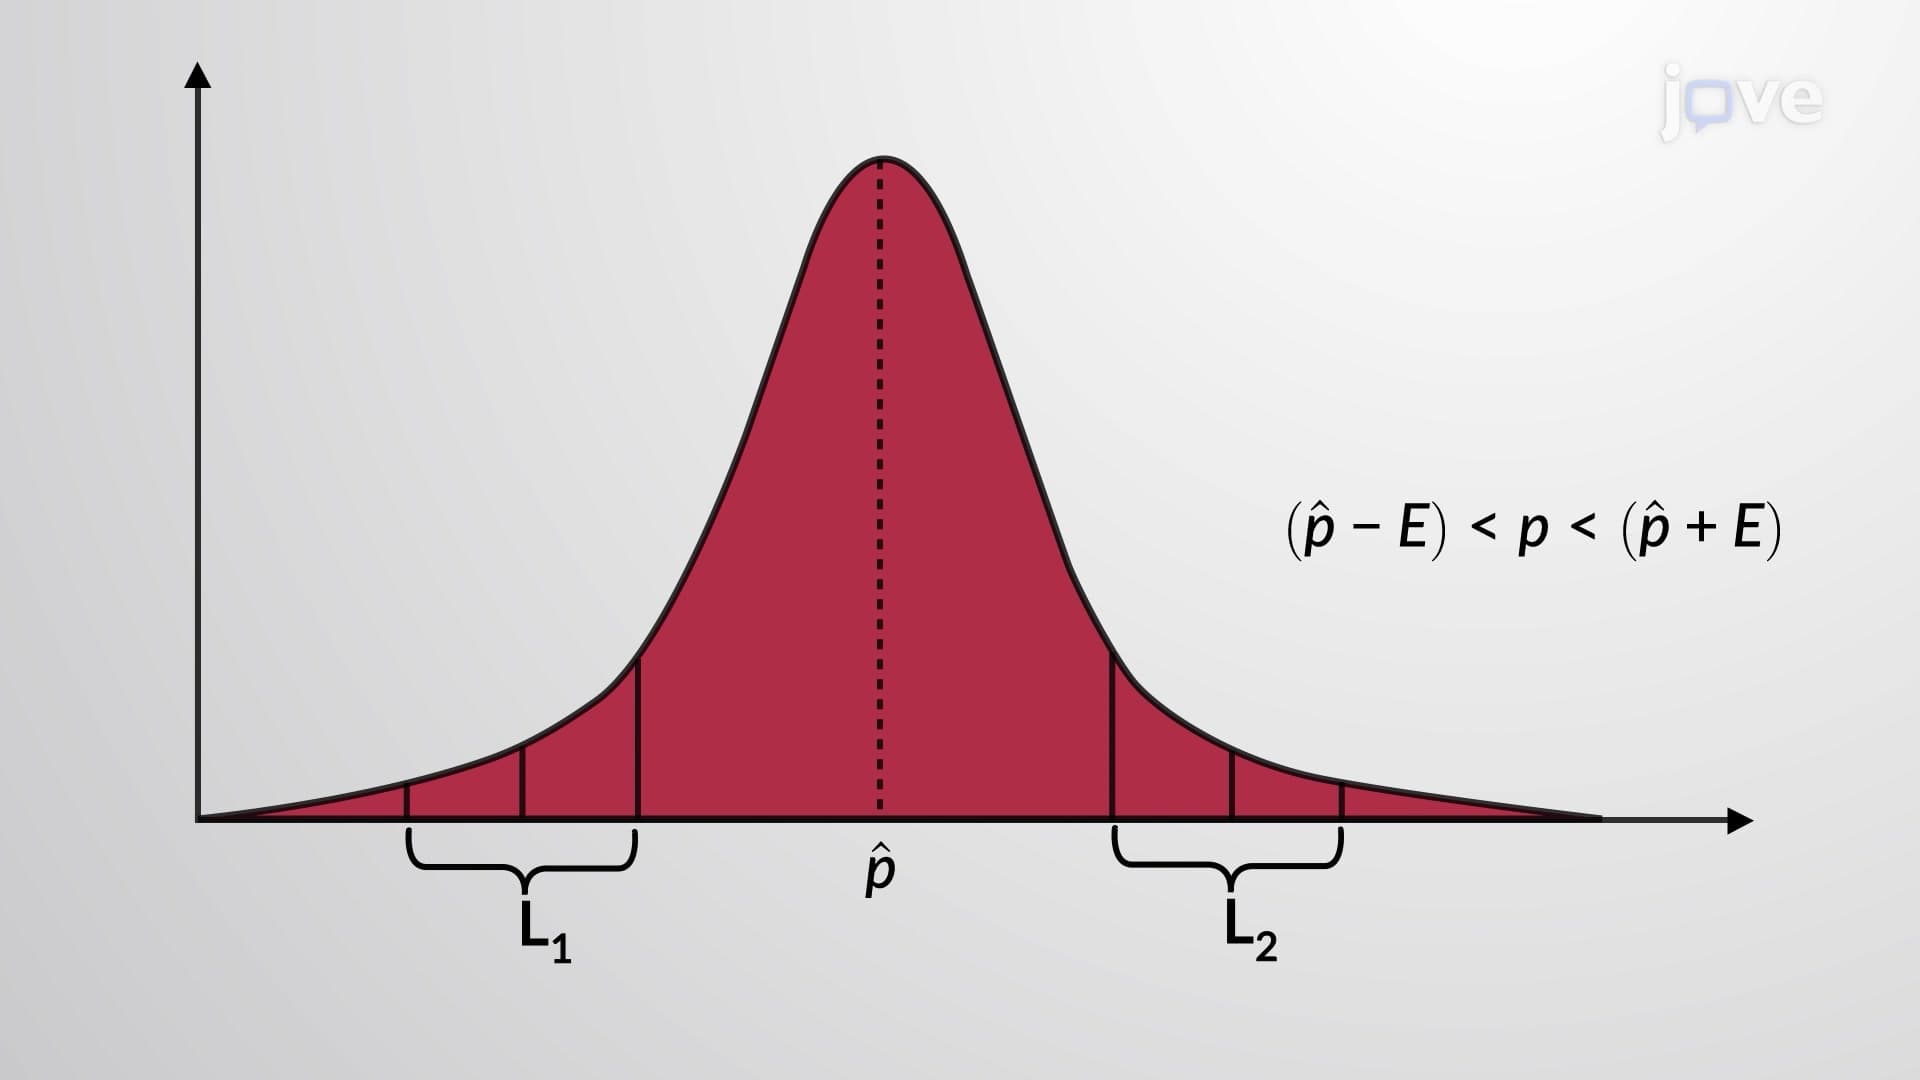
The confidence coefficient is also known as the confidence level or degree of confidence. It is the percent expression for the probability, 1-α, that the confidence interval contains the true population parameter assuming that the confidence interval is obtained after sufficient unbiased sampling; for example, if the CL = 90%, then in 90 out of 100 samples the interval estimate will enclose the true population parameter. Here α is the area under the curve, distributed equally under...
7.7K