
可靠的预测间隔与直接优化的诱导性合规回归用于深度学习
Haocheng Lei1, Anthony Bellotti1
1School of Computer Science, University of Nottingham Ningbo China, 199 Taikang East Road, Ningbo, 315100, Zhejiang, China.

概括
本研究引入了直接优化的诱导形式回归 (DOICR),以在深度学习中创建更窄的预测间隔 (PI). DOICR有效地控制了预测不确定性,同时确保了回归任务的准确数据覆盖.
科学领域:
- 机器学习 机器学习
- 人工智能的人工智能
- 统计 统计 统计 统计
背景情况:
- 深度学习回归模型需要准确的预测间隔 (PI) 来量化不确定性.
- 现有的方法往往减少PI宽度,但不能保证实际数据的覆盖.
- 归纳型合规预测器 (ICP) 可以保证覆盖范围,但没有针对最小PI宽度进行优化.
研究的目的:
- 在深度学习回归中开发一种新的方法来产生高质量的PI.
- 为了优化PI的狭窄宽度和保证数据覆盖.
- 提高深度学习预测的可靠性和精度.
主要方法:
- 为神经网络提出直接优化感应形式回归 (DOICR).
- 在优化过程中使用平均PI宽度作为唯一的损失函数.
- 确保PI通过捕获预设比例的真实标签来保持理论有效性.
主要成果:
- DOICR有效地将PI宽度降至最低,同时保持覆盖率保证.
- 拟议的方法的性能优于现有的最先进的算法.
- 在表格和图像数据集上,DOICR表现出卓越的性能.
结论:
- DOICR提高了深度学习回归中预测间隔的质量.
- 该方法提供了一个强大的方法,用于AI预测中的不确定性量化.
- 对于可靠的深度学习应用来说,DOICR是一个重大进步.

相关概念视频
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:21
Confidence Intervals
6.4K
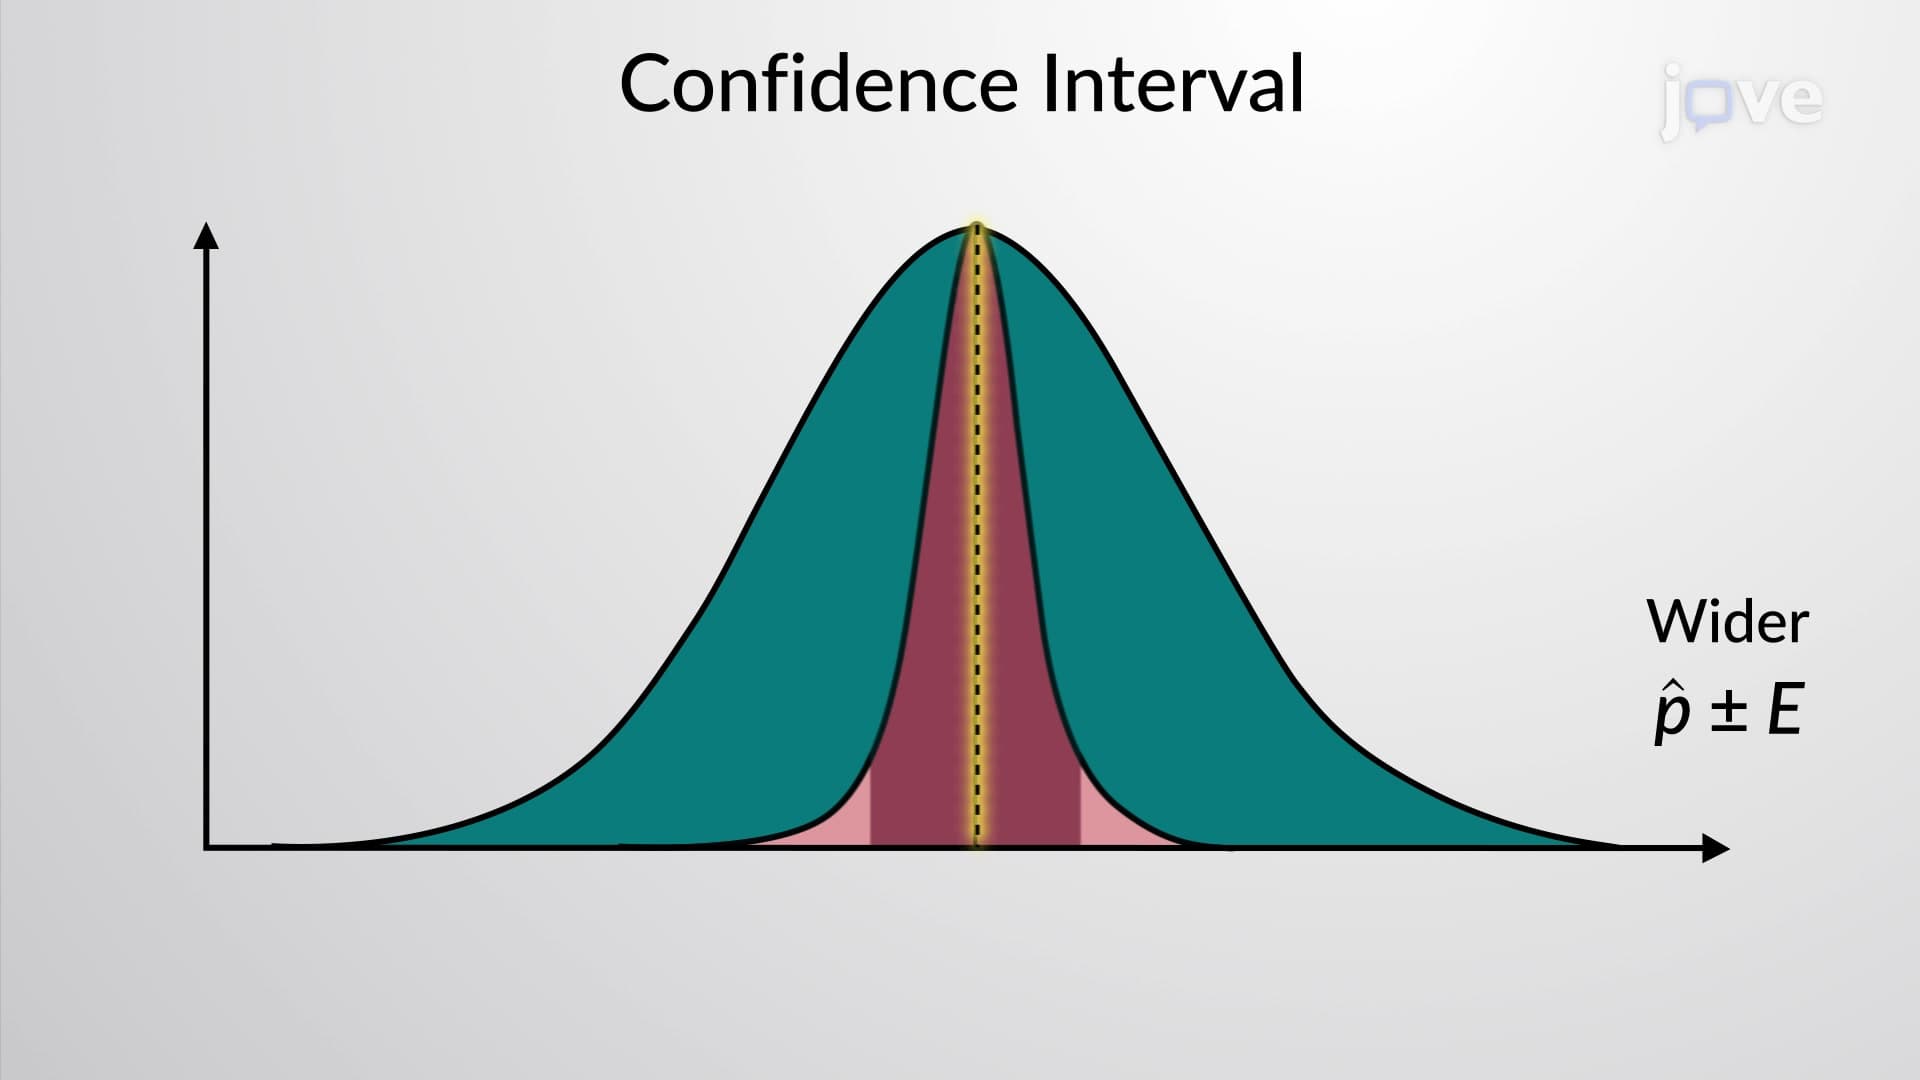
An unbiased point estimate is often insufficient to predict a population estimate, such as population mean or population proportion. In this scenario, a confidence interval is used. A confidence interval is an estimate similar to a sample proportion. However, unlike the point estimate which is a single value, the confidence interval contains a range of values. These values have lower and upper limits, known as confidence limits, and can be designated as L1 and L2, respectively.
A...
A...
6.4K
 01:07
End Point Prediction: Gran Plot
369
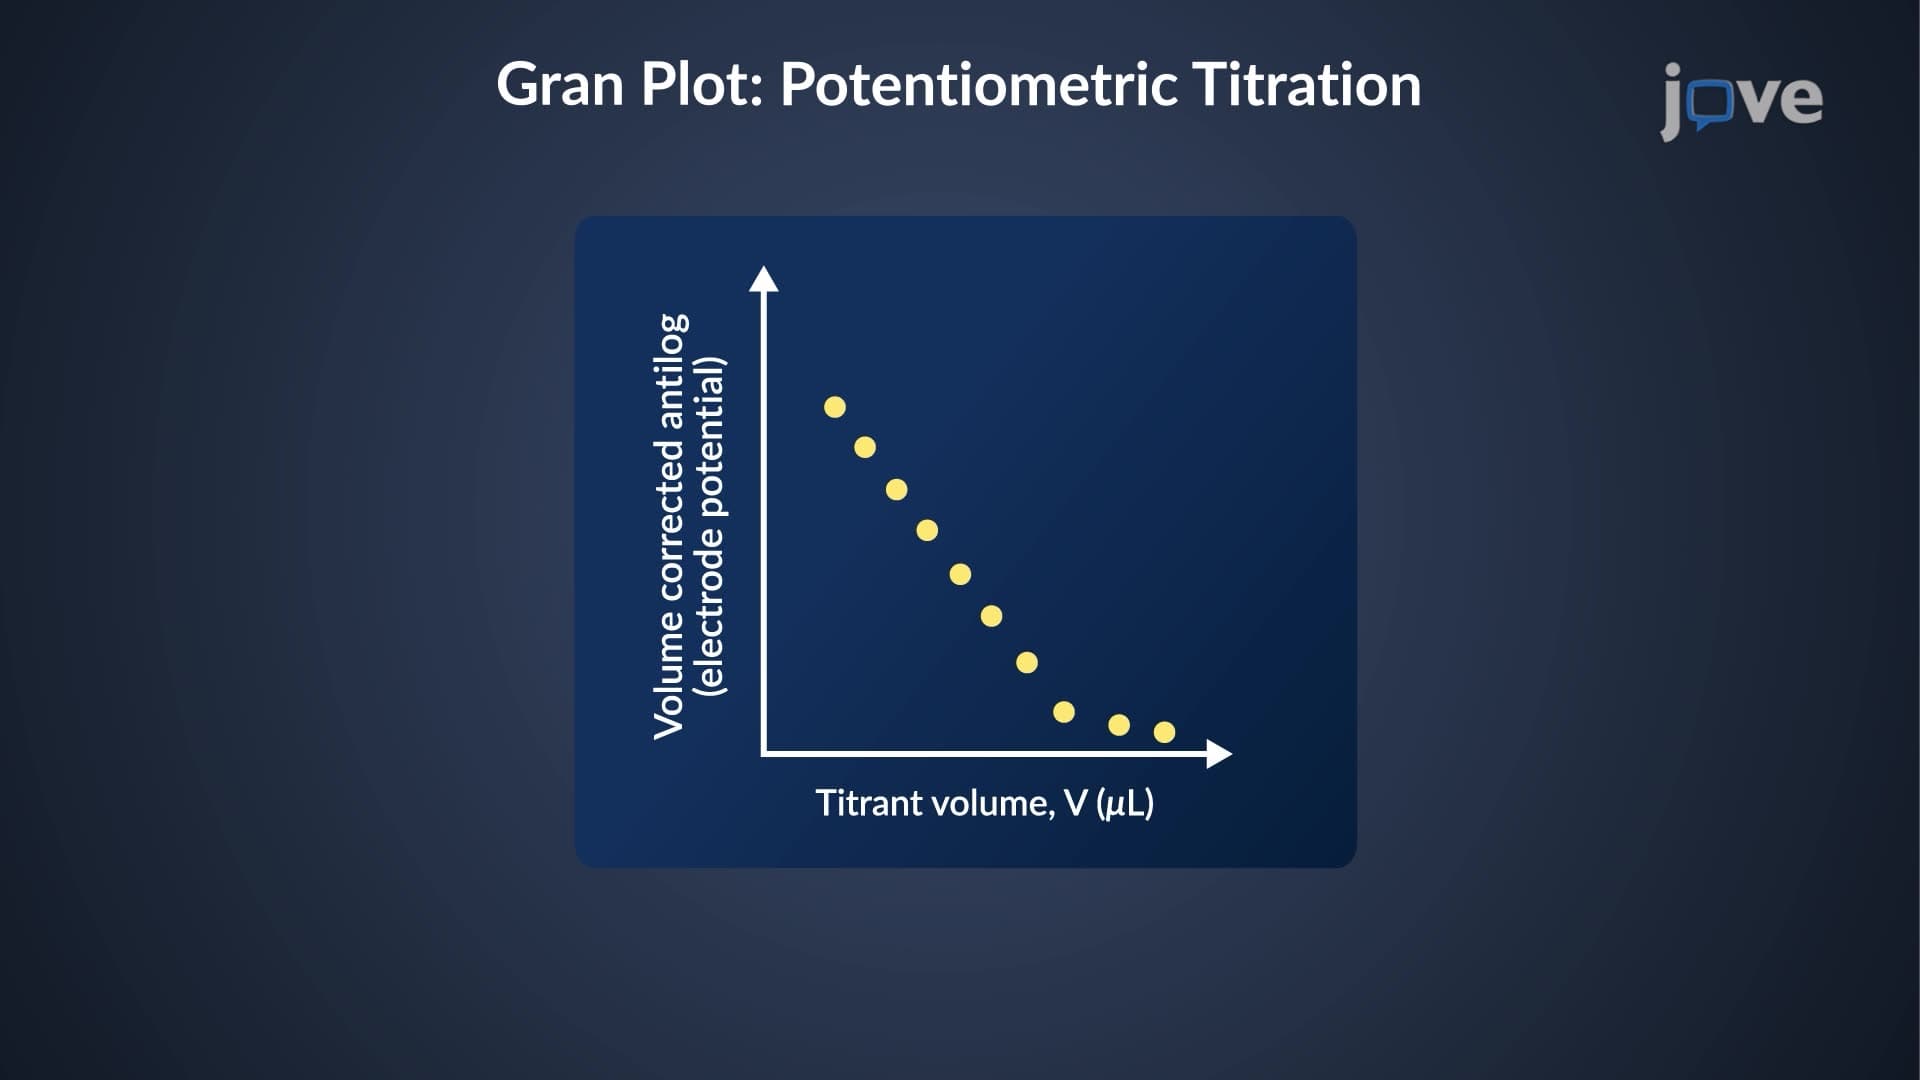
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
369
 01:20
Calibration Curves: Linear Least Squares
1.4K
A calibration curve is a plot of the instrument's response against a series of known concentrations of a substance. This curve is used to set the instrument response levels, using the substance and its concentrations as standards. Alternatively, or additionally, an equation is fitted to the calibration curve plot and subsequently used to calculate the unknown concentrations of other samples reliably.
For data that follow a straight line, the standard method for fitting is the linear...
For data that follow a straight line, the standard method for fitting is the linear...
1.4K
 01:21
Linear Approximation in Time Domain
96
Nonlinear systems often require sophisticated approaches for accurate modeling and analysis, with state-space representation being particularly effective. This method is especially useful for systems where variables and parameters vary with time or operating conditions, such as in a simple pendulum or a translational mechanical system with nonlinear springs.
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length,...
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length,...
96
 02:07
Improving Translational Accuracy
11.5K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
11.5K