

使用国家行政卫生数据的FREM (骨折风险评估模型) 的增强版本:用于开发和验证多变量预测模型的分析协议
Simon Bang Kristensen1,2,3, Anne Clausen1,2, Michael Kriegbaum Skjødt1,4
1Research Unit OPEN, Department of Clinical Research, University of Southern Denmark, Heden 16, Odense C, 5000, Denmark.
Diagnostic and prognostic research
|October 2, 2023

概括
本研究概述了一种新的骨质疏松骨折风险模型,通过结合药物数据和先进统计数据来增强骨折风险评估模型 (FREM),以更好地识别高风险患者.
科学领域:
- 医疗信息学 医疗信息学
- 流行病学 流行病学
- 生物统计学 生物统计学
背景情况:
- 骨质疏松症是一个日益严重的公共卫生问题,治疗差距很大,导致诊断不足和治疗不足.
- 患有骨质疏松症的患者由于诊断和干预延迟而面临骨折的高风险.
- 现有的骨质疏松病例发现工具,如骨折风险评估模型 (FREM),重点关注迫在眉的骨折风险,但可以改进.
研究的目的:
- 开发一个增强的预测模型,FREM的修改版,以更好地识别患有骨质疏松性骨折的高迫在眉风险的个人.
- 为了更准确的风险评估,将药物暴露和先进的统计方法纳入模型.
- 记录和证明数据管理和统计分析选择的透明度和有效性.
主要方法:
- 该模型将使用逻辑回归开发,以分组LASSO规范化作为主要方法.
- 将使用梯度增强分类树作为二次统计方法.
- 将进行无监督数据审查,以调查超参数选择,计算考虑和多对线性,以及测试分析代码的稳定性.
主要成果:
- 无监督的数据审查证实了计划的统计方法与现有数据的可行性和兼容性.
- 研究了用分组LASSO和梯度增强树进行后勤回归的计算考虑和超参数选择.
- 在远程环境中测试了分析代码的速度和稳定性,并以盲目的方式对分析计划进行了调整.
结论:
- 本协议详细介绍了增强骨质疏松症骨折风险预测工具的开发,确保透明度并提高模型有效性.
- 无监督数据审查表明,拟议的统计方法适合数据,支持模型开发的可行性.
- 改进的模型旨在改善识别高迫在眉的骨折风险的患者,解决骨质疏松症管理当前的治疗缺口.

相关概念视频
 01:25
Statistical Methods for Analyzing Epidemiological Data
400
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
400
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 00:59
Model-Independent Approaches for Pharmacokinetic Data: Noncompartmental Analysis
87
Noncompartmental analyses offer an alternative method for describing drug pharmacokinetics without relying on a specific compartmental model. In this approach, the drug's pharmacokinetics are assumed to be linear, with the terminal phase log-linear. This assumption allows for simplified analysis and interpretation of the drug's behavior in the body.
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...
One important characteristic of noncompartmental analyses is that drug exposure increases proportionally with increasing doses. This...
87
 01:12
Analysis of Population Pharmacokinetic Data
282
Analysis of population pharmacokinetic data involves studying the behavior of drugs within diverse populations to understand their pharmacokinetic parameters. Traditional pharmacokinetic methods typically involve collecting samples from a few individuals and estimating these parameters. While these methods are commonly used, they have limitations in capturing the variability in drug response among individuals or heterogeneous populations. Population pharmacokinetics is employed to address these...
282
 01:17
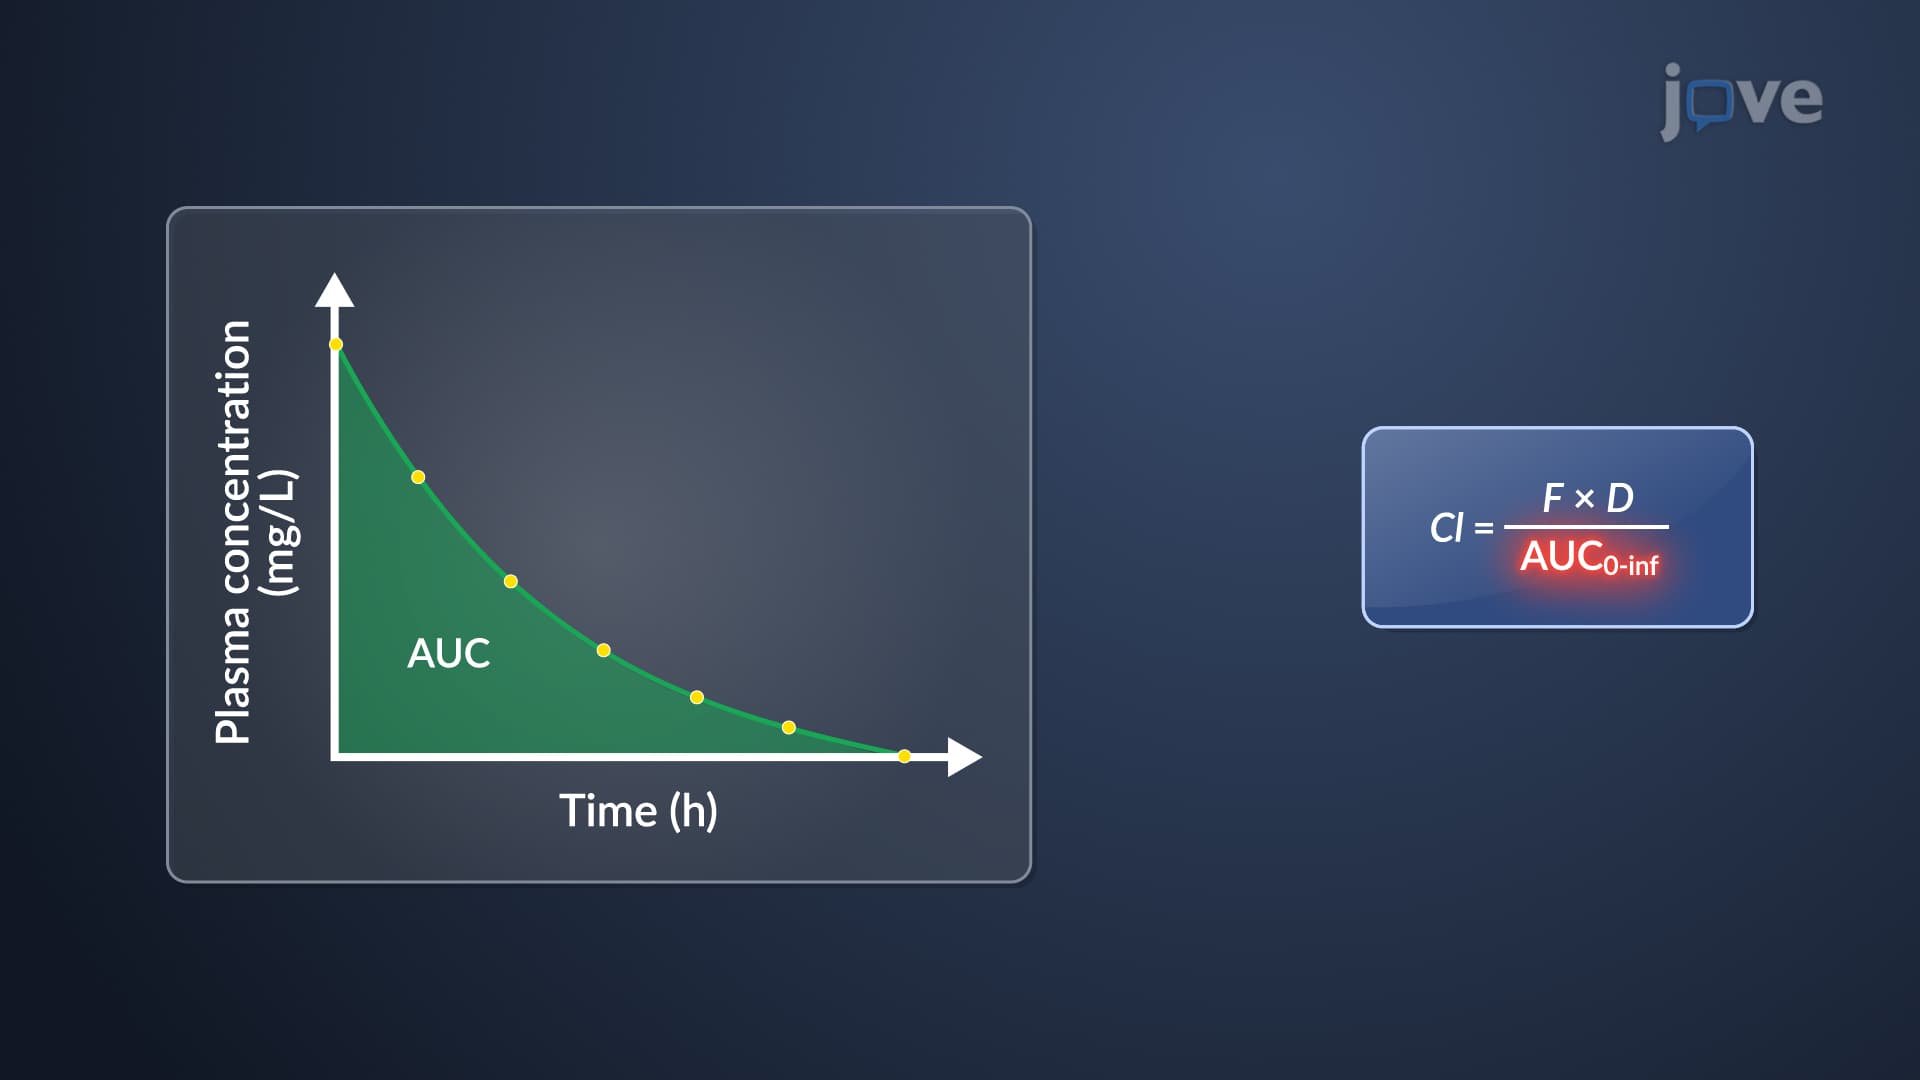
Clearance Models: Noncompartmental Models
74
Clearance is a pharmacokinetic parameter traditionally defined by compartment models, signifying the rate at which a drug is expelled from the body. However, a noncompartmental model offers an alternative method for assessing clearance, primarily employing empirical data obtained after administering a single drug dose.
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
74
 01:13
Sensitivity, Specificity, and Predicted Value
481
In healthcare diagnostics, laboratory tests play a crucial role in identifying and diagnosing a wide range of medical conditions. However, interpreting test results is not always straightforward. An abnormal test result does not always confirm the presence of a disease, just as a normal result does not guarantee its absence. To assess the reliability of these diagnostic tools, healthcare practitioners rely on two key statistical indicators: sensitivity and specificity.
Sensitivity is the...
Sensitivity is the...
481