
clrDV:基于偏斜正常分布的RNA-Seq数据的差异变异性测试
Hongxiang Li1, Tsung Fei Khang1,2
1Institute of Mathematical Sciences, Universiti Malaya, Kuala Lumpur, Malaysia.
PeerJ
|October 4, 2023

概括
研究人员开发了clrDV,这是一种新的统计方法,用于在组之间找到具有不同表达变异性的基因. 该方法改进了现有的RNA-Seq数据分析技术,有助于发现与疾病相关的基因.
科学领域:
- 基因组学和生物信息学
- 统计遗传学 统计遗传学
- 计算生物学 计算生物学
背景情况:
- 病理条件可以改变基因表达变异与对照组相比.
- 识别具有差异性表达变异的基因对于治疗点的发现至关重要.
- 目前在RNA-Seq数据中进行差异变异性测试的方法受到负二项式模型中平均变异依赖的挑战.
研究的目的:
- 引入clrDV,一种用于识别两种种群体之间表现出差异变异性的基因的新型统计方法.
- 为了解决当前RNA-Seq差异变异性分析的局限性.
主要方法:
- 开发了clrDV,一种用于检测基因表达的差异变异性的统计方法.
- 利用斜正态分布来建模以基因为导向的零分布,以中心的逻辑比率转换组成的RNA-Seq数据.
主要成果:
- 与现有方法相比,clrDV在控制虚假发现率和II型错误方面表现出具有竞争力或优异的性能.
- clrDV提供比可比方法更快的计算时间,在越来越大的样本大小中性能稳定.
- 将clrDV应用于神经退行性疾病的RNA-Seq数据集,成功识别了已知与阿尔茨海默病相关的基因.
结论:
- clrDV是一种有效和高效的统计工具,用于检测RNA-Seq数据中的差异基因表达变异性.
- 该方法在阿尔茨海默氏症等复杂疾病中确定新的治疗点方面表现有前途.
相关概念视频
 01:10
Chi-square Distribution
3.7K
How does one determine if bingo numbers are evenly distributed or if some numbers occurred with a greater frequency? Or if the types of movies people preferred were different across different age groups or if a coffee machine dispensed approximately the same amount of coffee each time. These questions can be addressed by conducting a hypothesis test. One distribution that can be used to find answers to such questions is known as the chi-square distribution. The chi-square distribution has...
3.7K
 02:26
Comparing Copy Number Variations and SNPs
17.7K
Sequencing of the human genome has opened up several best-kept secrets of the genome. Scientists have identified thousands of genome variations that exist within a population. These variations can be a single nucleotide or a larger chromosomal variation.
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
Copy number variations or CNVs are the structural variations that cover more than 1kb of DNA sequence. The single nucleotide polymorphism (SNP), on the other hand, is a single nucleotide change or a point mutation that is found in more than 1%...
17.7K
 02:32
Variation: Normal Distribution, Range, and Standard Deviation
22.3K
In the field of psychology, there are several ways to organize measurements of a trait, feature, or characteristic (i.e., variables). Qualitative data, such as ethnicity, can be tabulated into a frequency count to provide information about the proportion, as well as the variety of groups in a sample or population. On the other hand, researchers can perform a wider set of calculations on quantitative data. The mean, mode, and median, for instance, are central tendency measures to identify a...
22.3K
 01:09
Types of Skewness
12.3K
If the frequency distribution of a data set is more inclined towards smaller or larger values, the distribution is said to be skewed. If data values are skewed to the right, then the distribution is called positively skewed. Conversely, if the plot is skewed to the left, the distribution is called negatively skewed.
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
12.3K
 01:23
Test for Homogeneity
2.0K
The goodness–of–fit test can be used to decide whether a population fits a given distribution, but it will not suffice to decide whether two populations follow the same unknown distribution. A different test, called the test for homogeneity, can be used to conclude whether two populations have the same distribution. To calculate the test statistic for a test for homogeneity, follow the same procedure as with the test of independence. The hypotheses for the test for homogeneity can...
2.0K
 01:06
Skewness
11.7K
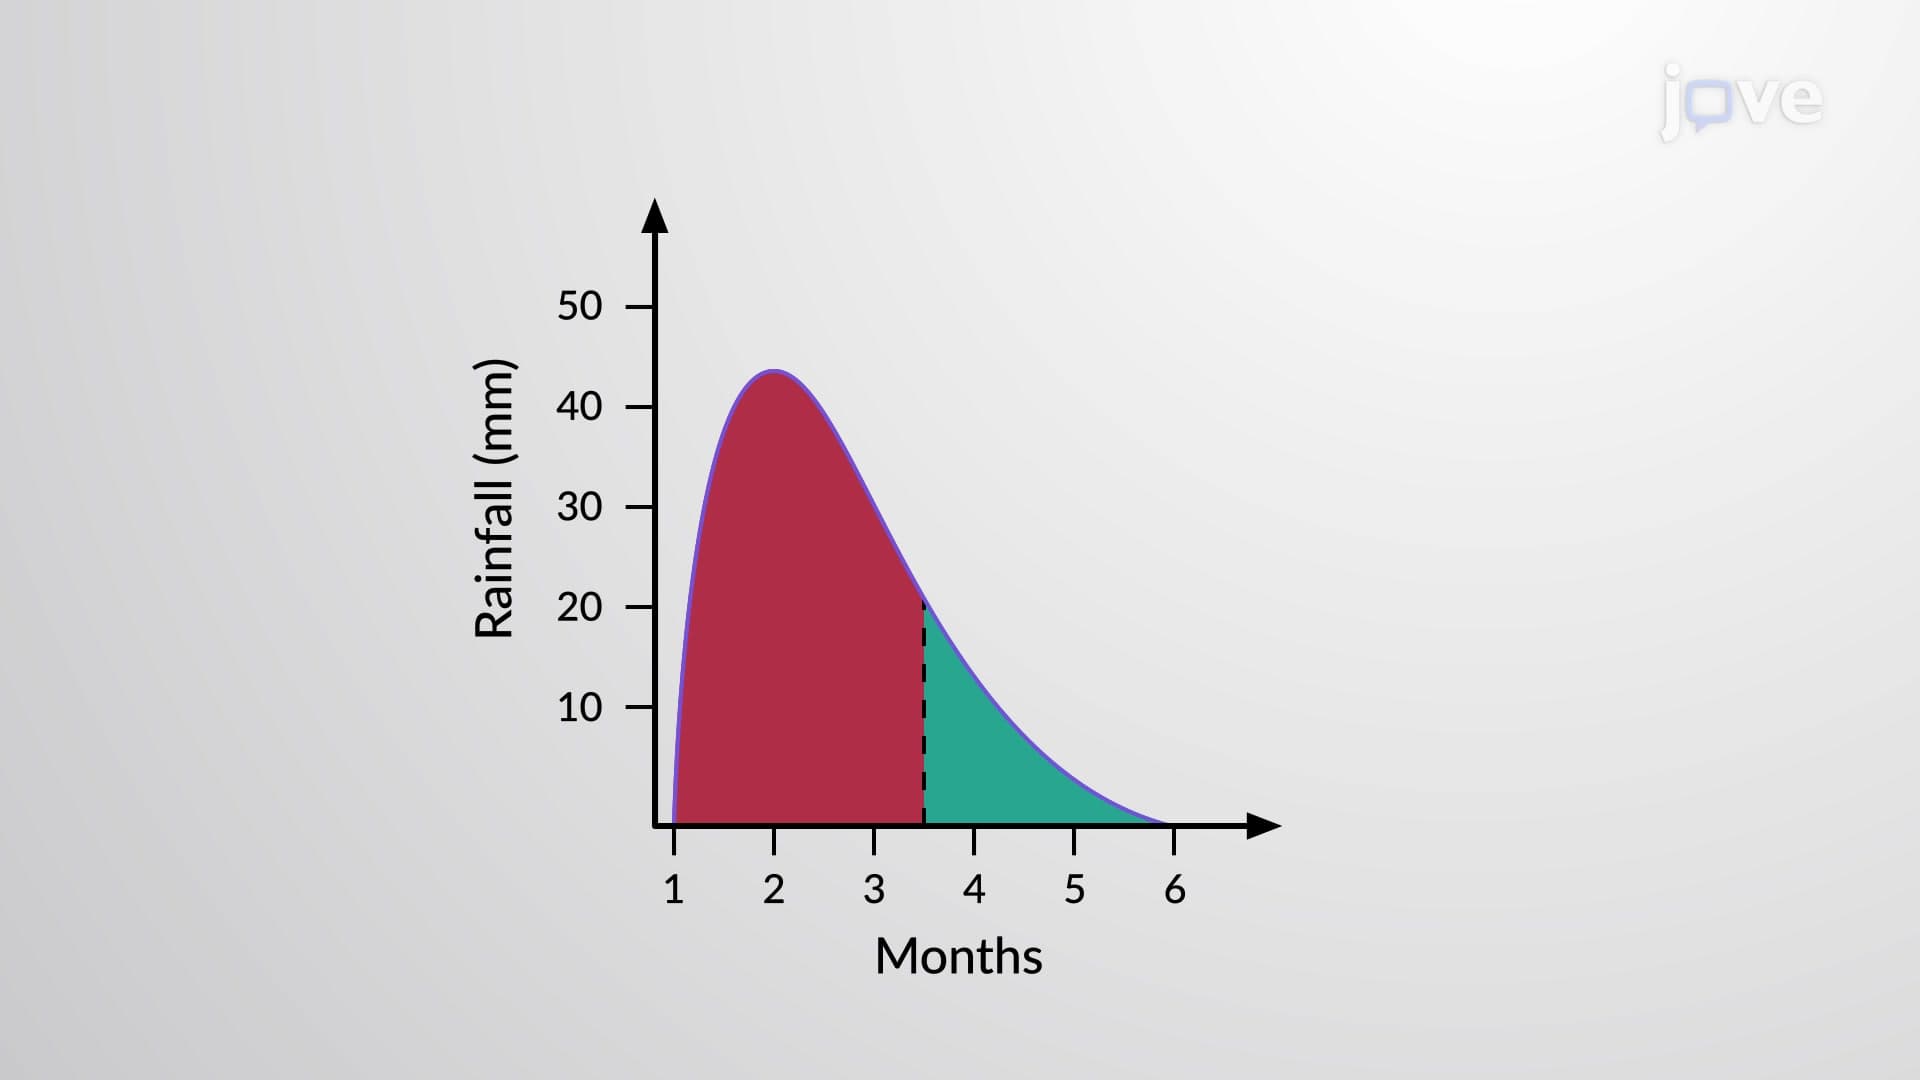
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
11.7K