

评估监督机器学习算法对钻石定价模型的预测性能
Samuel Njoroge Kigo1, Evans Otieno Omondi2,3, Bernard Oguna Omolo1,4,5
1Institute of Mathematical Sciences, Strathmore University, P.O Box 59857-00200, Nairobi, Kenya.
Scientific reports
|October 12, 2023

概括
随机森林 (RF) 模型准确预测钻石价格,优于其他机器学习算法. 这项研究突出了RF频率.
科学领域:
- 机器学习应用 机器学习应用
- 数据科学数据科学数据科学
- 计量经济学 计量经济学
背景情况:
- 钻石定价是复杂的,原因是卡拉特,切割,清晰度,表格和深度等特征之间的非线性关系.
- 准确的价格预测对钻石行业至关重要,影响定价策略和市场分析.
- 监督机器学习为建模这些复杂的关系提供了潜在的解决方案.
研究的目的:
- 为准确的钻石价格预测,全面分析和比较多个监督机器学习模型 (回归器和分类器).
- 确定最有效的模型来预测钻石价格,考虑回归和分类方法.
- 提供关于数据预处理技术对于提高预测模型性能的重要性的见解.
主要方法:
- 数据预处理包括异常值处理 (四分位数范围),标准化,缺失值的中位数归算和多对线性解析.
- 特征工程涉及"切割"变量和基于关联的特征选择的等宽分区.
- 评估的模型包括随机森林 (RF),多层感知器 (MLP),XGBoost,增强决策树,K-最近邻居 (KNN),线性回归和支持向量回归.
主要成果:
- 随机森林 (RF) 回归器实现了最低的根平均平方误差 (RMSE) 523.50和最高的R平方得分0.985.50.
- 射频分类器表现出完美的性能,曲线下的面积 (AUC) 为1.00.
- 其他模型,如MLP,XGBoost和增强决策树,显示出不同程度的有效性,而KNN,线性回归和支持矢量回归的性能不那么准确.
结论:
- 随机森林 (RF) 模型是准确预测钻石价格的最佳选择,在回归和分类任务中表现出色.
- 该研究强调了强大的数据预处理技术在提高价格预测机器学习模型准确性的重要性.
- 这些发现为钻石行业提供了有价值的工具和见解,有助于定价策略,市场趋势分析和知情决策.
更多相关视频
 04:09
Predicting Treatment Response to Image-Guided Therapies Using Machine Learning: An Example for Trans-Arterial Treatment of Hepatocellular Carcinoma
Published on: October 10, 2018
8.3K
 12:18
A Machine Learning Approach to Design an Efficient Selective Screening of Mild Cognitive Impairment
Published on: January 11, 2020
7.6K
相关概念视频
 01:19
Testing a Claim about Standard Deviation
2.5K
A complete procedure to test a claim about population standard deviation or population variance is explained here.
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...
2.5K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:07
Residual Plots
4.6K
A residual plot is a statistical representation of data used to analyze correlation and regression results. It helps verify the requirements for drawing specific conclusions about correlation and regression. To obtain the residual plot, first, the residual for each data value is calculated, which is simply the vertical distance between the observed and the predicted value obtained from the regression equation.
When the residual values are plotted against the variable x, it is called a residual...
When the residual values are plotted against the variable x, it is called a residual...
4.6K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:08
Outliers and Influential Points
4.1K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.1K
 01:18
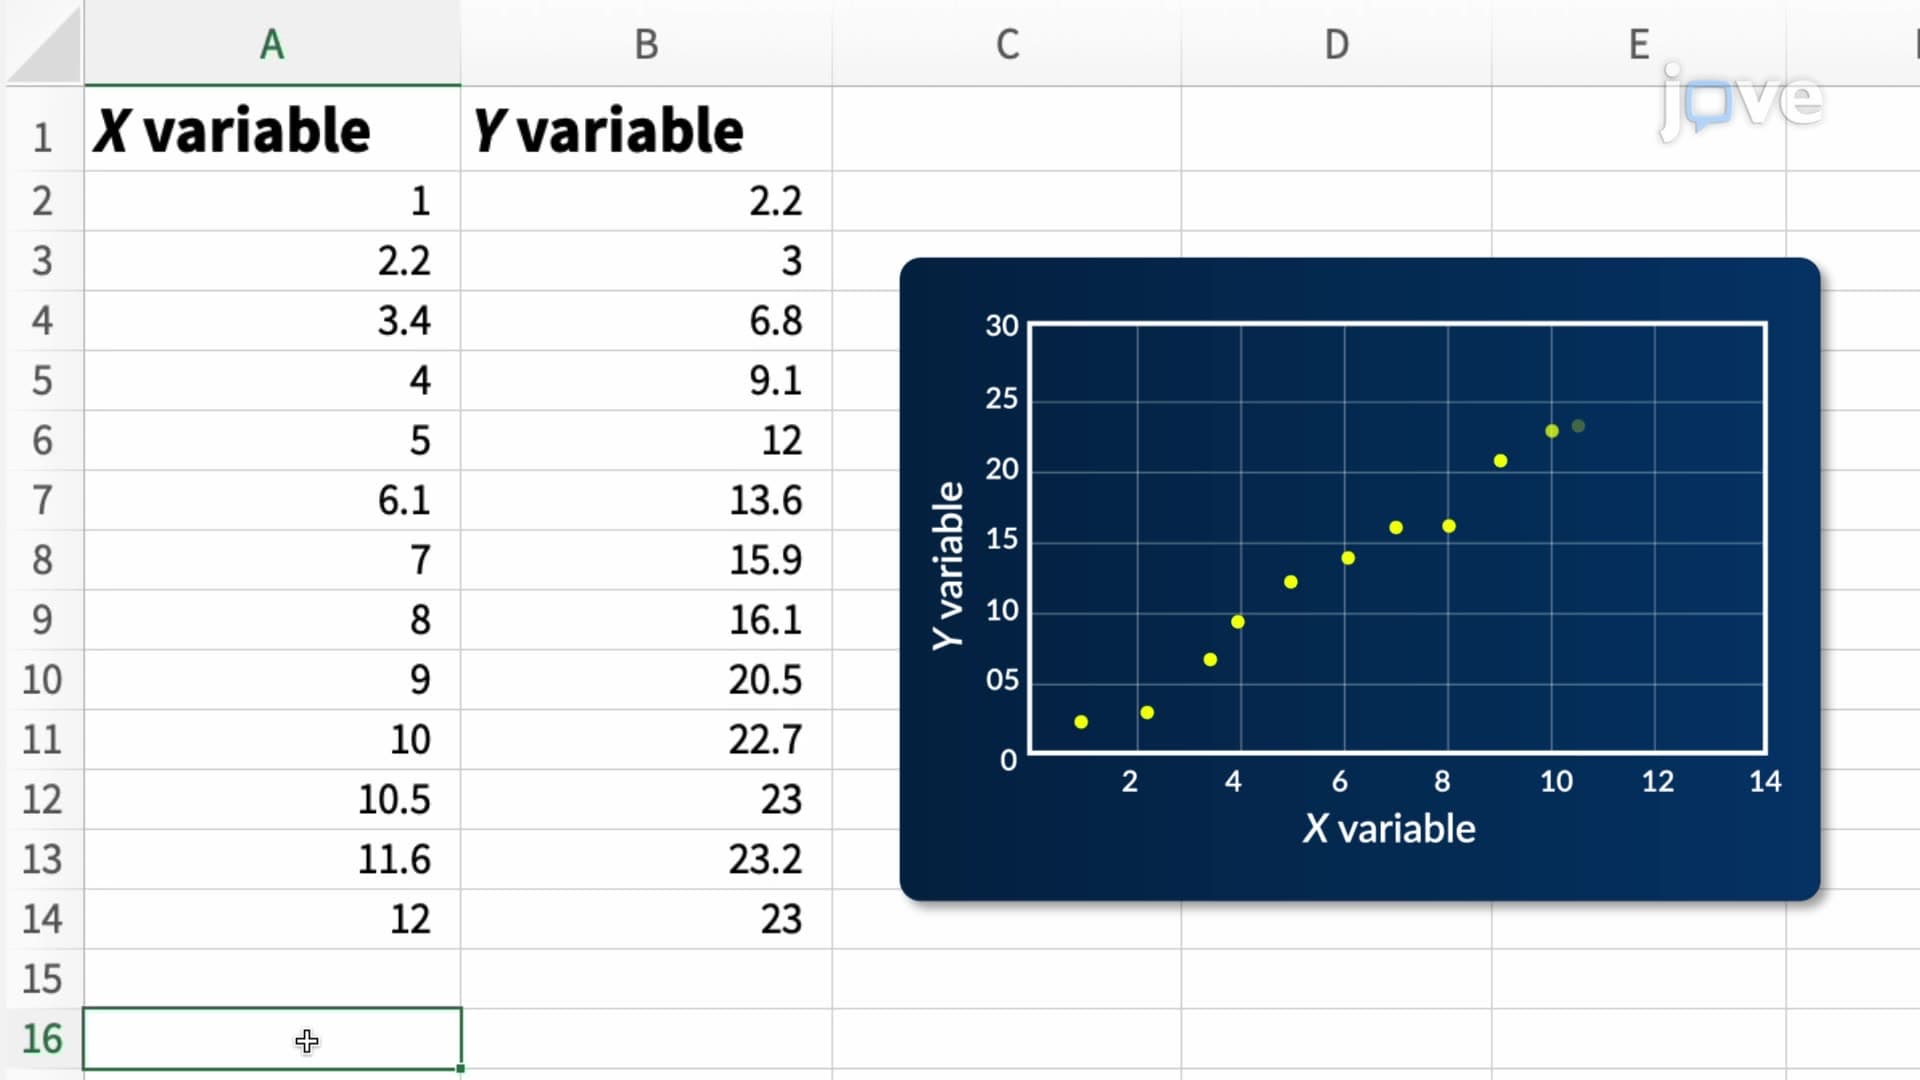
Microsoft Excel: Regression Analysis
627
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
627