

在倾向分数分布的尾部表征不平衡
American journal of epidemiology
|October 13, 2023

概括
确定与极端倾向分数 (PS) 相关的患者特征对于观察性研究至关重要. 这种方法有助于确定驱动不寻常PS值的变量,潜在地改善研究设计并避免数据修剪.
科学领域:
- 生物统计学 生物统计学
- 流行病学 流行病学
- 医疗保健服务研究 医疗服务研究
背景情况:
- 倾向性得分 (PS) 对于观察性研究中的因果推断至关重要,特别是在逆治疗概率加权 (IPTW) 和基于PS的方法中.
- 了解与极端PS值相关的患者特征对于强大的研究设计和准确的估计至关重要.
研究的目的:
- 提出一种新的方法来识别对极端倾向分数负责的关键共变量.
- 为了说明这种方法在各种研究场景中的应用,包括模拟和真实世界的临床数据.
主要方法:
- 这项研究使用了使用国家门诊医疗保健调查的等离子体模拟,并分析了两个现实世界队列:在COVID-19患者中启动德克萨米他松和雷梅西维尔.
- 倾向性得分模型是使用基线共变量来拟合的,极端PS值由第一个和第99个百分点定义.
- 在调整共变量值以确定有影响力的变量后,应用了模型无关的变量重要性测量.
主要成果:
- 变量重要性和可视化技术有效地确定了驱动极端倾向得分的共变量.
- 该方法成功地突出了可能表明不适合纳入研究的患者特征,例如非标签药物使用.
- 识别这些变量可以指导样本子集或限制,可能会否定修剪或重叠权重的需要.
结论:
- 这种方法为了解和解决与观察性研究中极端倾向得分相关的问题提供了有价值的工具.
- 通过识别有影响力的共变量,研究人员可以改进研究人群,提高因果估计的有效性,提高统计分析的效率.
更多相关视频
 16:23
Automated, Quantitative Cognitive/Behavioral Screening of Mice: For Genetics, Pharmacology, Animal Cognition and Undergraduate Instruction
Published on: February 26, 2014
14.4K
 10:50
Using the FishSim Animation Toolchain to Investigate Fish Behavior: A Case Study on Mate-Choice Copying In Sailfin Mollies
Published on: November 8, 2018
10.9K
相关概念视频
 01:22
Bias
4.3K
Bias refers to any tendency that prevents a question from being considered unprejudiced. In research, bias occurs when one outcome or answer is selected or encouraged over others in sampling or testing. Bias can occur during any research phase, including study design, data collection, analysis, and publication.
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...
In statistics, a sampling bias is created when a sample is collected from a population, and some members of the population are not as likely to be chosen as others (remember, each member...
4.3K
 01:25
Choosing Between z and t Distribution
2.8K
The z and the Student t distribution estimate the population mean using the sample mean and standard deviation. However, to decide which distribution to use for a calculation, one needs to determine the sample size, the nature of the distribution, and whether the population standard deviation is known. If the population standard deviation is known and the population is normally distributed, or if the sample size is greater than 30, the z distribution is preferred. The Student t distribution is...
2.8K
 01:06
Skewness
11.7K
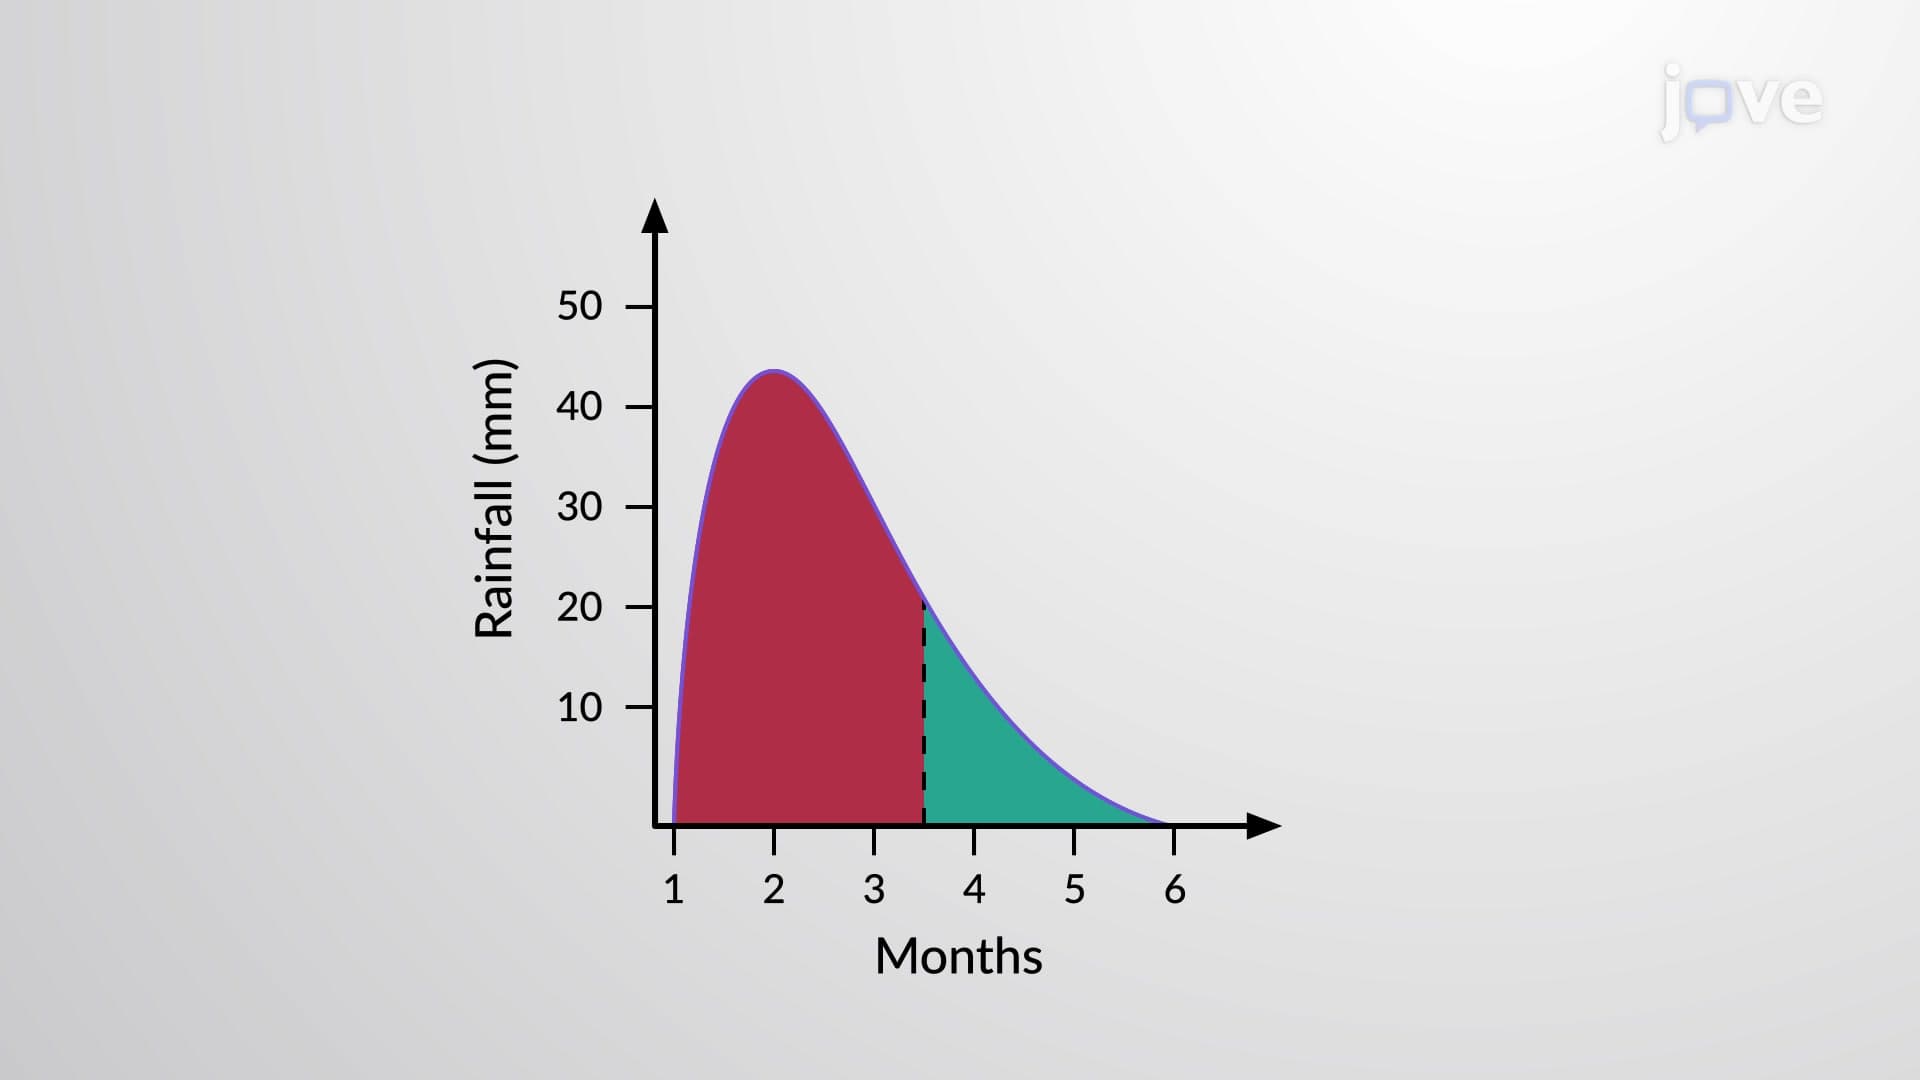
The measures of central tendency calculated from a data set may not reveal much about its intrinsic distribution. If a plot is made of the data set’s values, the mean and the median may not only differ, but also the plot may have more values on one side of the central tendencies. Such a data set is said to be skewed towards that side.
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
The longer the tail of the plot on one side, the more skewed it is. The skewness of a data set’s values suggests that the measures of central tendency...
11.7K
 01:26
Distributions to Estimate Population Parameter
4.1K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
4.1K
 01:15
One-Way ANOVA: Unequal Sample Sizes
5.8K
One-way ANOVA can be performed on three or more samples of unequal sizes. However, calculations get complicated when sample sizes are not always the same. So, while performing ANOVA with unequal samples size, the following equation is used:
5.8K
 01:15
One-Way ANOVA: Equal Sample Sizes
3.3K
One-Way ANOVA can be performed on three or more samples with equal or unequal sample sizes. When one-way ANOVA is performed on two datasets with samples of equal sizes, it can be easily observed that the computed F statistic is highly sensitive to the sample mean.
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
Different sample means can result in different values for the variance estimate: variance between samples. This is because the variance between samples is calculated as the product of the sample size and the variance between the...
3.3K