共同的机构投资者和管理收入预测的质量-经验和机器学习证据
相关实验视频
Updated: Jul 13, 2025
05:37
An R-Based Landscape Validation of a Competing Risk Model
Published on: September 16, 2022
2.1K
Shanshan Yang1, Xiaohan Li2, Zhenhua Jiang3
1Business School, Chengdu University, Chengdu, China.
PloS one
|October 16, 2023

概括
共同的机构投资者通过提供外部监管来提高管理收入预测的准确性. 这提高了风险警告,并促进了中国的可持续信息披露.
科学领域:
- 金融经济学 金融经济学
- 公司治理 公司治理
- 信息不对称性是一种信息不对称性.
背景情况:
- 管理层利预测对于资本市场效率至关重要.
- 机构投资者对影响预测质量的作用需要进一步研究.
- 管理层和投资者之间的信息不对称可能会扭曲市场信号.
研究的目的:
- 检查普通机构投资者对管理收入预测质量的影响.
- 探索普通机构投资者对收益预测准确性的缓和作用.
- 应用像图形神经网络这样的先进方法来预测预测质量.
主要方法:
- 利用了中国A股上市公司 (2014-2021) 的数据.
- 采用多重线性回归分析.
- 嵌入式图形神经网络用于预测准确性的预测建模.
主要成果:
- 常见的机构投资者对收益预测的准确性有重大和积极的影响.
- 机构投资者充当外部监管机构,限制过于广泛的预测范围.
- 这种监督提高了风险预警功能和管理层信息披露的可持续性.
结论:
- 共同的机构投资者通过加强监管来提高管理收益预测的质量.
- 这些发现有助于对机构股权的经济后果的文献.
- 建议机构投资者加强信息共享,以减少信息不对称.
相关概念视频
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:29
Econometric Views (EViews)
146
Econometric Views, often stylized as EViews, is a package that merges statistical analysis with econometric studies. It is designed to provide tools for time series analysis, forecasting, and econometric model simulation. The software originated from MicroTSP software and has evolved significantly since its inception in 1981. The history of EViews is marked by a continuous effort to enhance its computational speed and user interface. It was initially developed for large computing systems but...
146
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:09
Empirical Method to Interpret Standard Deviation
5.3K
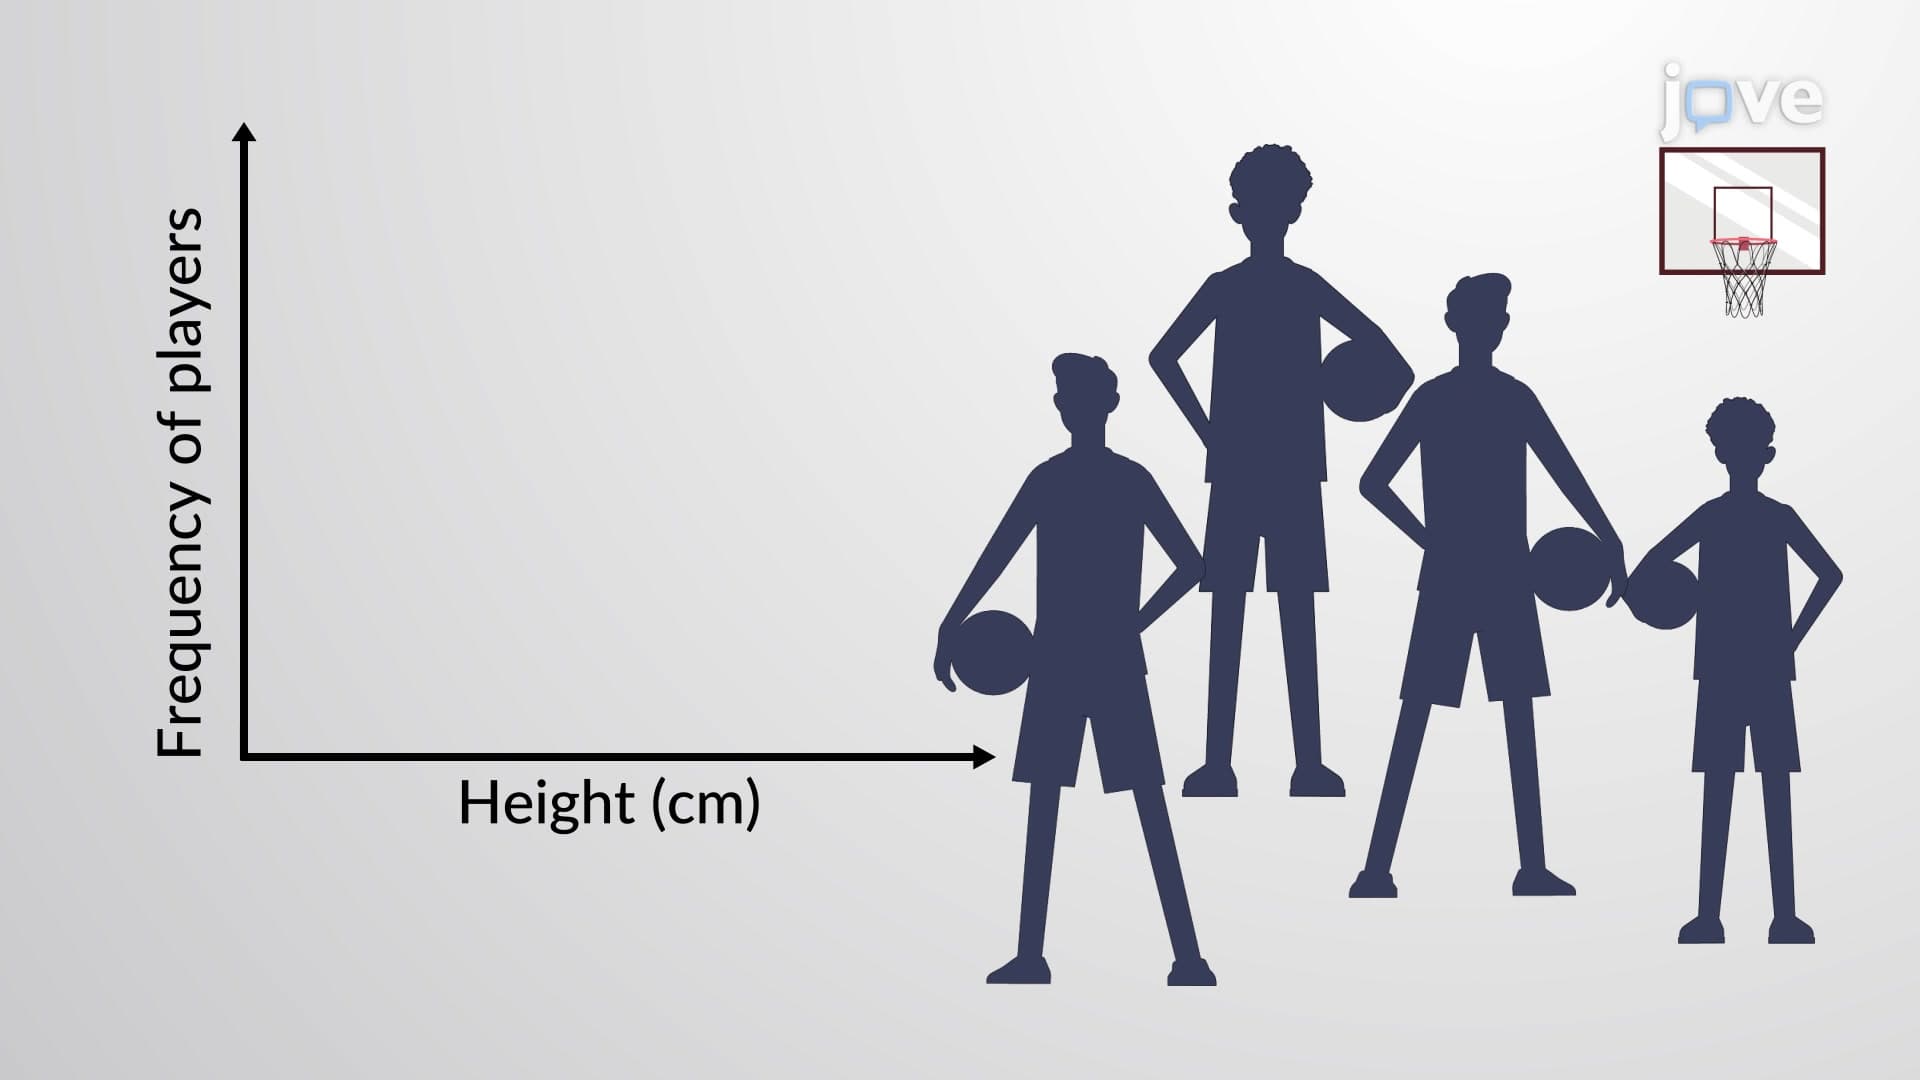
The empirical rule, also known as the three-sigma rule, allows a statistician to interpret the standard deviation in a normally distributed dataset. The rule states that 68% of the data lies within one standard deviation from the mean, 95% lies within two standard deviations from the mean, and 99.7% lies within three standard deviations from the mean. Additionally, this rule is also called the 68-95-99.7 rule.
This rule is used widely in statistics to calculate the proportion of data values...
This rule is used widely in statistics to calculate the proportion of data values...
5.3K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:16
Goodness-of-Fit Test
3.4K
The goodness-of-fit test is a type of hypothesis test which determines whether the data "fits" a particular distribution. For example, one may suspect that some anonymous data may fit a binomial distribution. A chi-square test (meaning the distribution for the hypothesis test is chi-square) can be used to determine if there is a fit. The null and alternative hypotheses may be written in sentences or stated as equations or inequalities. The test statistic for a goodness-of-fit test is given as...
3.4K