修改了利回归不连续性模型,用于含有模糊变量的设置

Portia K Mafukidze1, Samuel M Mwalili2, Thomas Mageto2
1Department of Mathematics, The Pan African University, Institute for Basic Sciences, Technology and Innovation, Nairobi, Kenya. portiamafukidze@gmail.com.
BMC research notes
|October 18, 2023

概括
这项研究引入了一个修改的尖回归不连续性模型来预测艾滋病毒/艾滋病患者的酒精消费. 该模型有效地使用模糊变量,表明咨询改善了CD4计数等健康结果.
科学领域:
- 因果推理因果推理
- 统计建模 统计建模
- 公共卫生 公共卫生
背景情况:
- 以前对回归不连续性模型中模糊变量的研究是有限的,专注于单独依赖或独立的变量.
- 在了解模糊的依赖和独立变量之间在预测健康结果中的相互作用方面存在差距.
- 酒精消费是影响人类免疫缺陷病毒 (HIV) 和获得性免疫缺陷综合征 (AIDS) 进展的重要因素.
研究的目的:
- 开发和验证一个修改的利回归不连续性 (RDD) 模型,能够处理模糊的依赖变量和独立变量.
- 预测人类免疫缺陷病毒 (HIV) 和获得免疫缺陷综合征 (AIDS) 感染者饮酒模式.
- 解决因果推理中对模糊依赖和独立变量的同时分析的研究缺口.
主要方法:
- 开发了一种新的统计模型,即修改的急性回归不连续性 (RDD) 模型.
- 模型方程的数值解决方法使用参数估计技术.
- 通过模拟研究验证,评估平均因果效应估计器的一致性.
主要成果:
- 修改后的Sharp RDD模型表明,随着样本大小的增加,真实值的概率趋同,证实了估计器的一致性.
- 咨询显示了显著的平均因果效应 (约. 0.199) 关于酒精使用侦探识别测试 (AUDIT) 在严格的RDD框架内对合规者进行评分.
- 六个月的辅导导致AUDIT分数下降,分化集群4 (CD4) 计数增加,以及艾滋病毒/艾滋病感染者病毒载荷减少.
结论:
- 修改的Sharp RDD是一种强大的方法,用于与模糊变量进行因果推理,增强回归不连续性设计.
- 该研究成功地将先进的RDD方法应用于涉及不确定的数据的真实世界健康场景.
- 研究结果强调了咨询干预措施在控制酒精消费和改善艾滋病毒/艾滋病感染者健康状况方面的有效性.

相关概念视频
 01:13
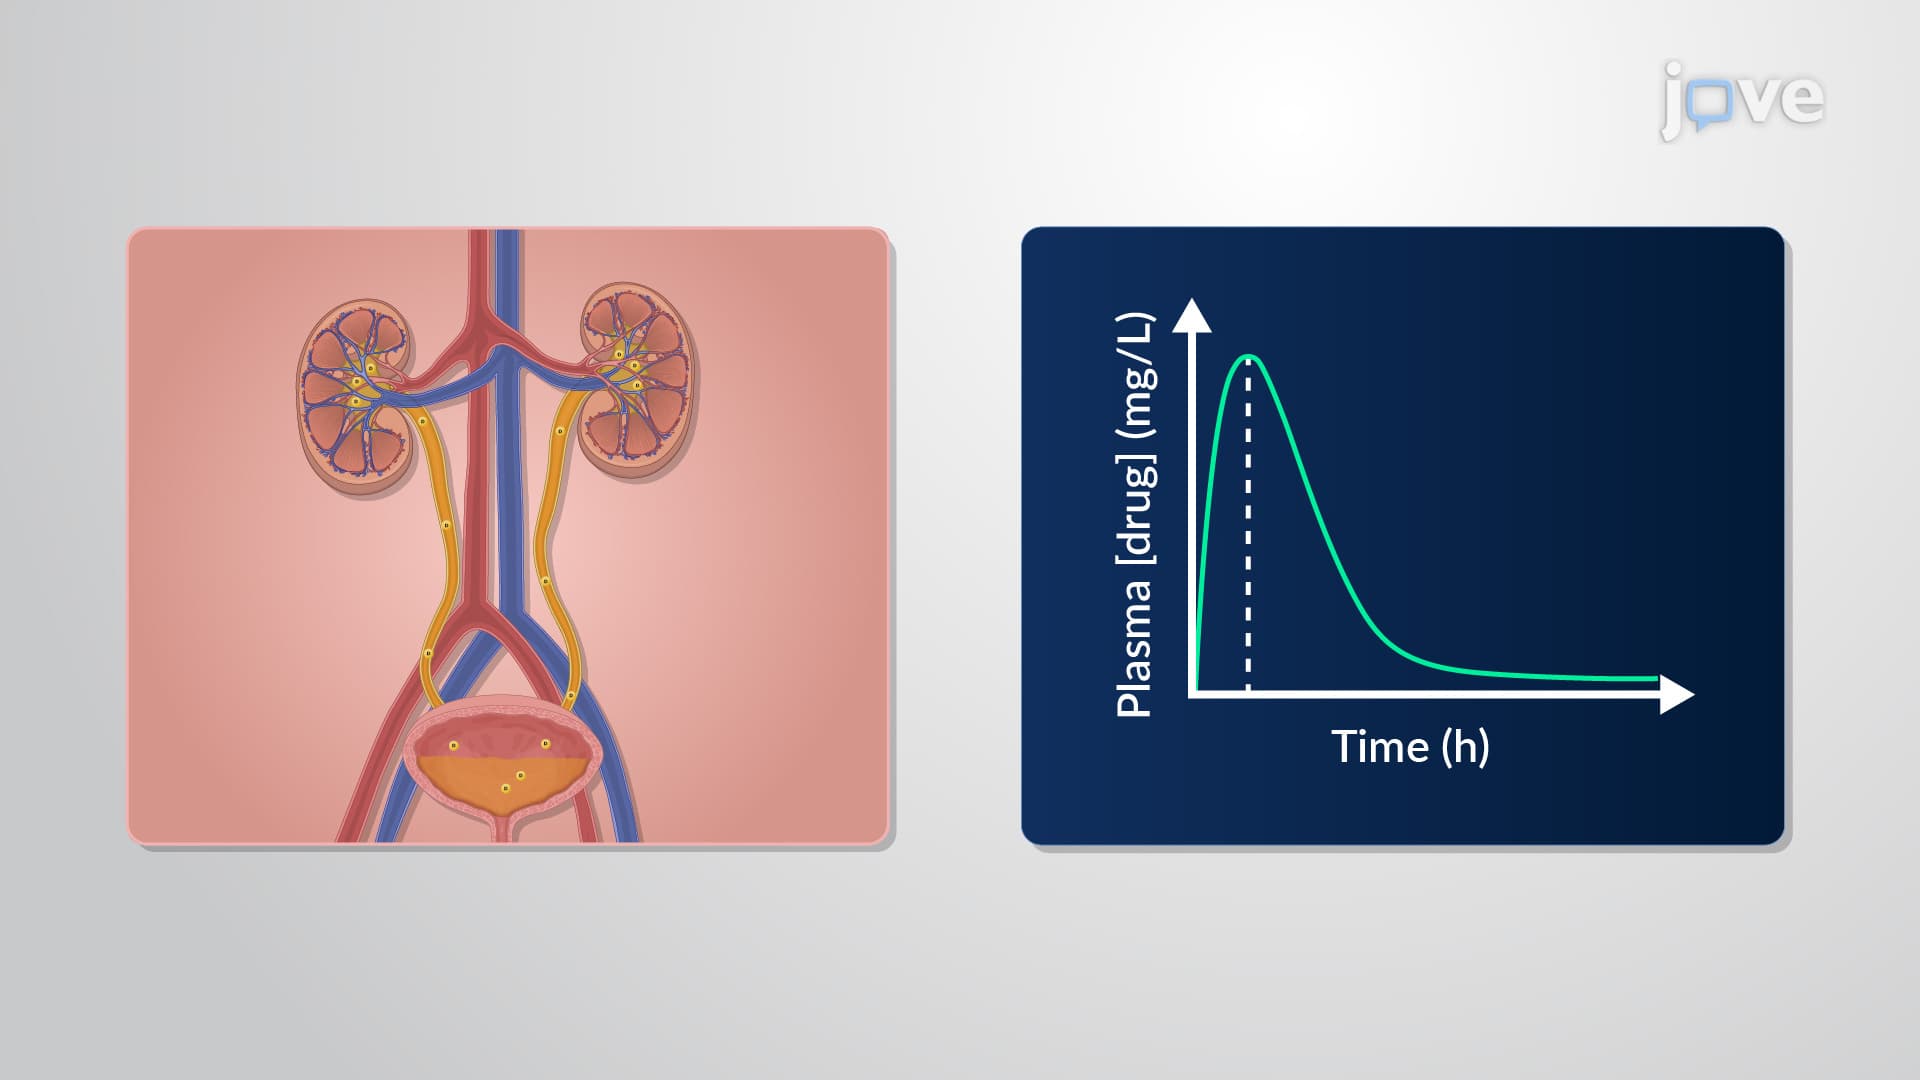
Parameters Affecting Nonlinear Elimination: Zero-Order Input, First-Order Absorption and Two-Compartment Model
70
Drugs administered through various routes can lead to nonlinear elimination, resulting in complex pharmacokinetic behaviors crucial to understanding efficacious drug dosing.
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
When a drug is administered through a constant intravenous infusion and eliminated via nonlinear pharmacokinetics, it follows zero-order input. For example, oral drugs undergo first-order absorption upon administration and are eliminated through nonlinear pharmacokinetics.
In the case of subcutaneously administered drugs,...
70
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:21
Friedman Two-way Analysis of Variance by Ranks
208
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
208
 01:17
Clearance Models: Noncompartmental Models
63
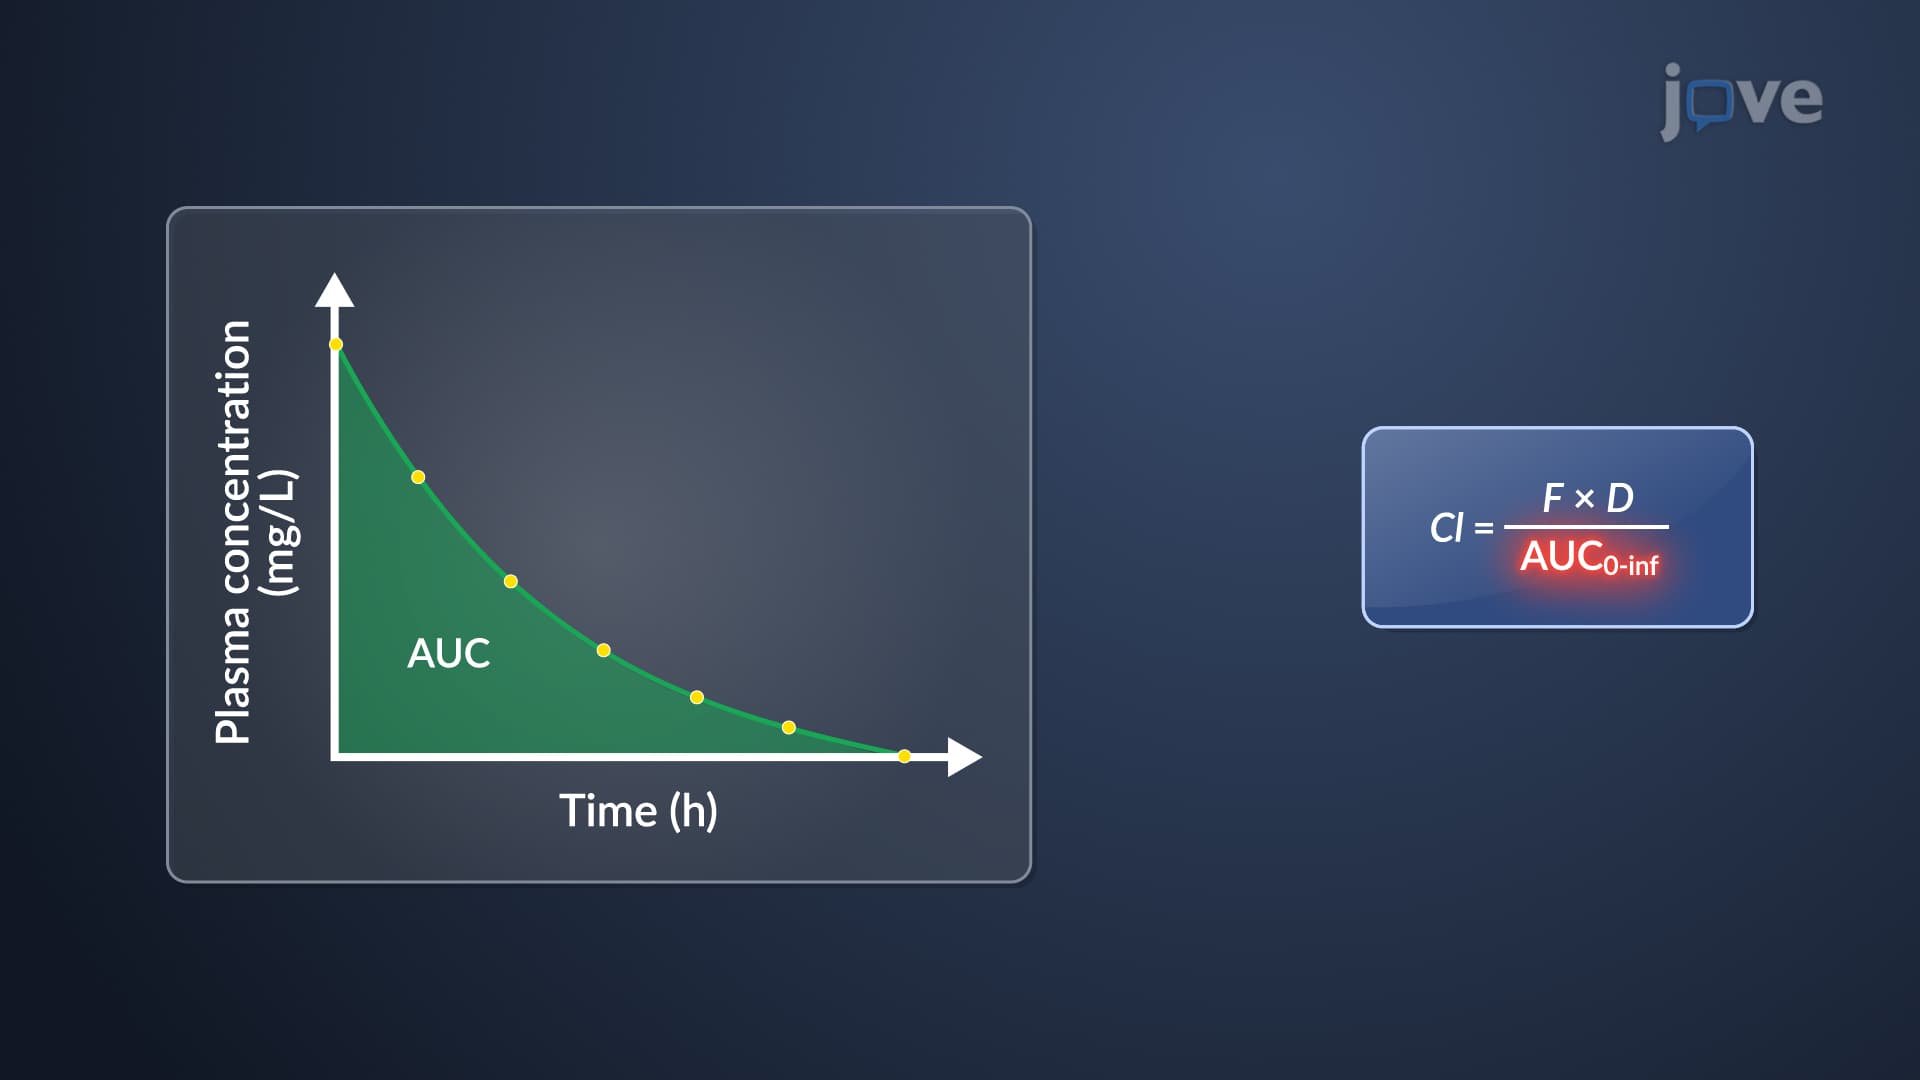
Clearance is a pharmacokinetic parameter traditionally defined by compartment models, signifying the rate at which a drug is expelled from the body. However, a noncompartmental model offers an alternative method for assessing clearance, primarily employing empirical data obtained after administering a single drug dose.
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
63