
在贝叶斯框架中使用有条件的相互信息估计全球可识别性
Sahil Bhola1, Karthik Duraisamy2
1Department of Aerospace Engineering, University of Michigan, Ann Arbor, MI, 48109, USA. sbhola@umich.edu.
Scientific reports
|October 26, 2023

概括
本研究引入了一种新的信息理论方法,用于评估贝叶斯统计模型的可识别性,而不需要数据. 该方法量化参数信息获取,识别可识别的参数子集,以提高模型确定性.
科学领域:
- 统计 统计 统计 统计
- 信息理论 信息理论
- 计算建模 计算建模
背景情况:
- 在贝叶斯统计模型中评估参数的可识别性对于可靠的推断至关重要.
- 现有的方法通常依赖于数据或特定的模型结构,限制了它们的适用性.
- 全球实际识别对于理解模型行为和参数估计确定性至关重要.
研究的目的:
- 提出一种新的信息理论方法来评估贝叶斯统计模型的全球实际可识别性.
- 开发一个独立于模型结构和先前分布的参数信息获取估计器.
- 识别可识别的参数子集并分析参数依赖关系.
主要方法:
- 使用有条件的相互信息来估计每个模型参数获得的信息.
- 开发一个数据独立的估计器,用于实际的识别性分析.
- 扩展框架,以确定参数对 (可识别子集) 之间的功能关系.
主要成果:
- 拟议的方法量化了全球的实际可识别性,而不需要控制实验或数据.
- 该方法考虑了各种不确定性,包括模型形式,参数和测量不确定性.
- 可以识别的参数子集在线性高斯模型和非线性动力学模型中均成功识别,证明了估计的高后置确定性.
结论:
- 新的信息理论方法为评估贝叶斯模型可识别性提供了一个强大的和多功能工具.
- 该方法有助于识别可靠估计的参数或参数子集.
- 该框架增强了对模型行为的理解,并有助于模型缩小和实验设计.
相关概念视频
 00:54
Uncertainty: Confidence Intervals
4.1K
The confidence interval is the range of values around the mean that contains the true mean. It is expressed as a probability percentage. The interpretation of a 95% confidence interval, for instance, is that the statistician is 95% confident that the true mean falls within the interval. The upper and lower limits of this range are known as confidence limits. The confidence limits for the true mean are estimated from the sample's mean, the standard deviation, and the statistical factor...
4.1K
 01:19
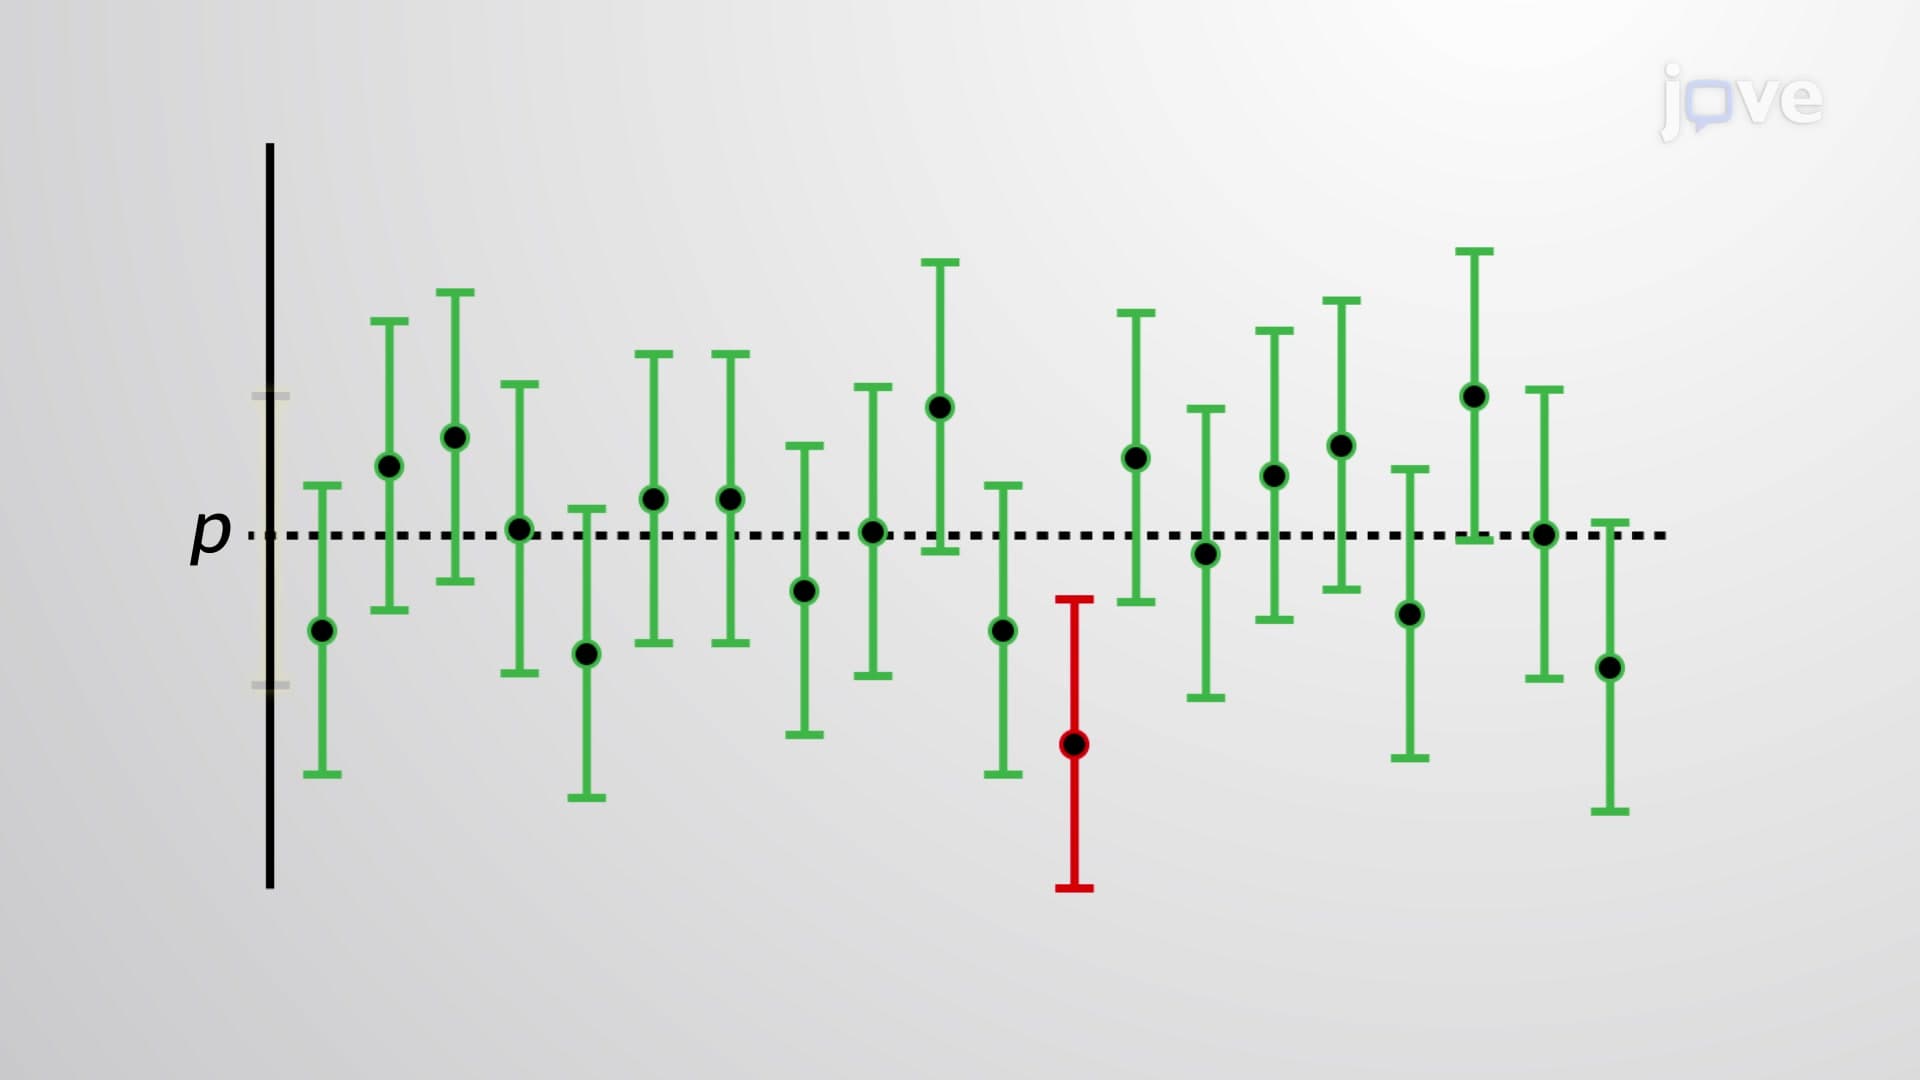
Interpretation of Confidence Intervals
5.8K
A confidence interval is a better estimate of the population than a point estimate, as it uses a range of values from a sample instead of a single value.
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
5.8K
 01:10
Propagation of Uncertainty from Systematic Error
534
The atomic mass of an element varies due to the relative ratio of its isotopes. A sample's relative proportion of oxygen isotopes influences its average atomic mass. For instance, if we were to measure the atomic mass of oxygen from a sample, the mass would be a weighted average of the isotopic masses of oxygen in that sample. Since a single sample is not likely to perfectly reflect the true atomic mass of oxygen for all the molecules of oxygen on Earth, the mass we obtain from this...
534
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:24
One-Compartment Open Model: Wagner-Nelson and Loo Riegelman Method for ka Estimation
531
This lesson introduces two critical methods in pharmacokinetics, the Wagner-Nelson and Loo-Riegelman methods, used for estimating the absorption rate constant (ka) for drugs administered via non-intravenous routes. The Wagner-Nelson method relates ka to the plasma concentration derived from the slope of a semilog percent unabsorbed time plot. However, it is limited to drugs with one-compartment kinetics and can be impacted by factors like gastrointestinal motility or enzymatic degradation.
On...
On...
531
 00:59
Propagation of Uncertainty from Random Error
704
An experiment often consists of more than a single step. In this case, measurements at each step give rise to uncertainty. Because the measurements occur in successive steps, the uncertainty in one step necessarily contributes to that in the subsequent step. As we perform statistical analysis on these types of experiments, we must learn to account for the propagation of uncertainty from one step to the next. The propagation of uncertainty depends on the type of arithmetic operation performed on...
704