对异常值和有影响力的数据检测的统一方法 - - 信息的回顾价值
1Department of Statistics, Penn State University, University Park, PA, U.S.
Stat (International Statistical Institute)
|November 1, 2023

概括
本研究引入了一种新的,可解释的方法来识别有影响力的和偏远的数据点. 该方法通过区分预期和惊人的影响来增强数据分析,改善未来的数据收集和模型可靠性.
科学领域:
- 统计 统计 统计 统计
- 数据科学数据科学数据科学
- 机器学习 机器学习
背景情况:
- 识别有影响力的和偏远的数据对于有效的数据收集和利用至关重要.
- 现有的异常发现和影响分析方法往往缺乏解释性和灵活性.
研究的目的:
- 开发一种统一,可解释和灵活的方法来检测异常值和影响分析.
- 为了更好地理解,将数据影响分解为杆和边缘效应.
- 在各种决策问题上应用该方法,包括估计,预测和假设测试.
主要方法:
- 提出的方法是基于信息概念的价值.
- 它将数据影响分解为杆 (预期影响) 和外围 (令人惊的影响) 影响.
- 研究信息量值的理论性质,并与线性回归中的经典测量相关.
主要成果:
- 开发了一种统一的方法来检测异常值和影响分析.
- 与现有技术相比,该方法提供了更好的解释性和灵活性.
- 该方法被证明适用于线性回归,通用线性混合模型和假设测试.
结论:
- 新的信息价值方法为识别有影响力和边缘数据提供了一个强大的框架.
- 这种方法提高了对数据影响的理解,有助于为未来的数据收集和分析做出更好的决策.
- 该方法在不同统计模型和决策问题上的多功能性突显了其实际实用性.
更多相关视频
 07:35
Selecting Multiple Biomarker Subsets with Similarly Effective Binary Classification Performances
Published on: October 11, 2018
7.5K
 08:51
Author Spotlight: Integrated Multi-Omics Analysis for Unveiling Multicellular Immune Signatures in Clinical Heart Attack Cohorts
Published on: September 20, 2024
1.3K
相关概念视频
 01:08
Outliers and Influential Points
4.1K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.1K
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.6K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.6K
 01:00
Detection of Gross Error: The Q Test
6.1K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.1K
 01:12
What Are Outliers?
3.9K
Outliers are observed data points that are far from the least squares line. They have unusual values and need to be examined carefully. Though an outlier may result from erroneous data, at other times, it may hold valuable information about the population under study and should be included in the data. Hence, it is crucial to examine what causes a data point to be an outlier.
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
3.9K
 00:57
Modified Boxplots
9.8K
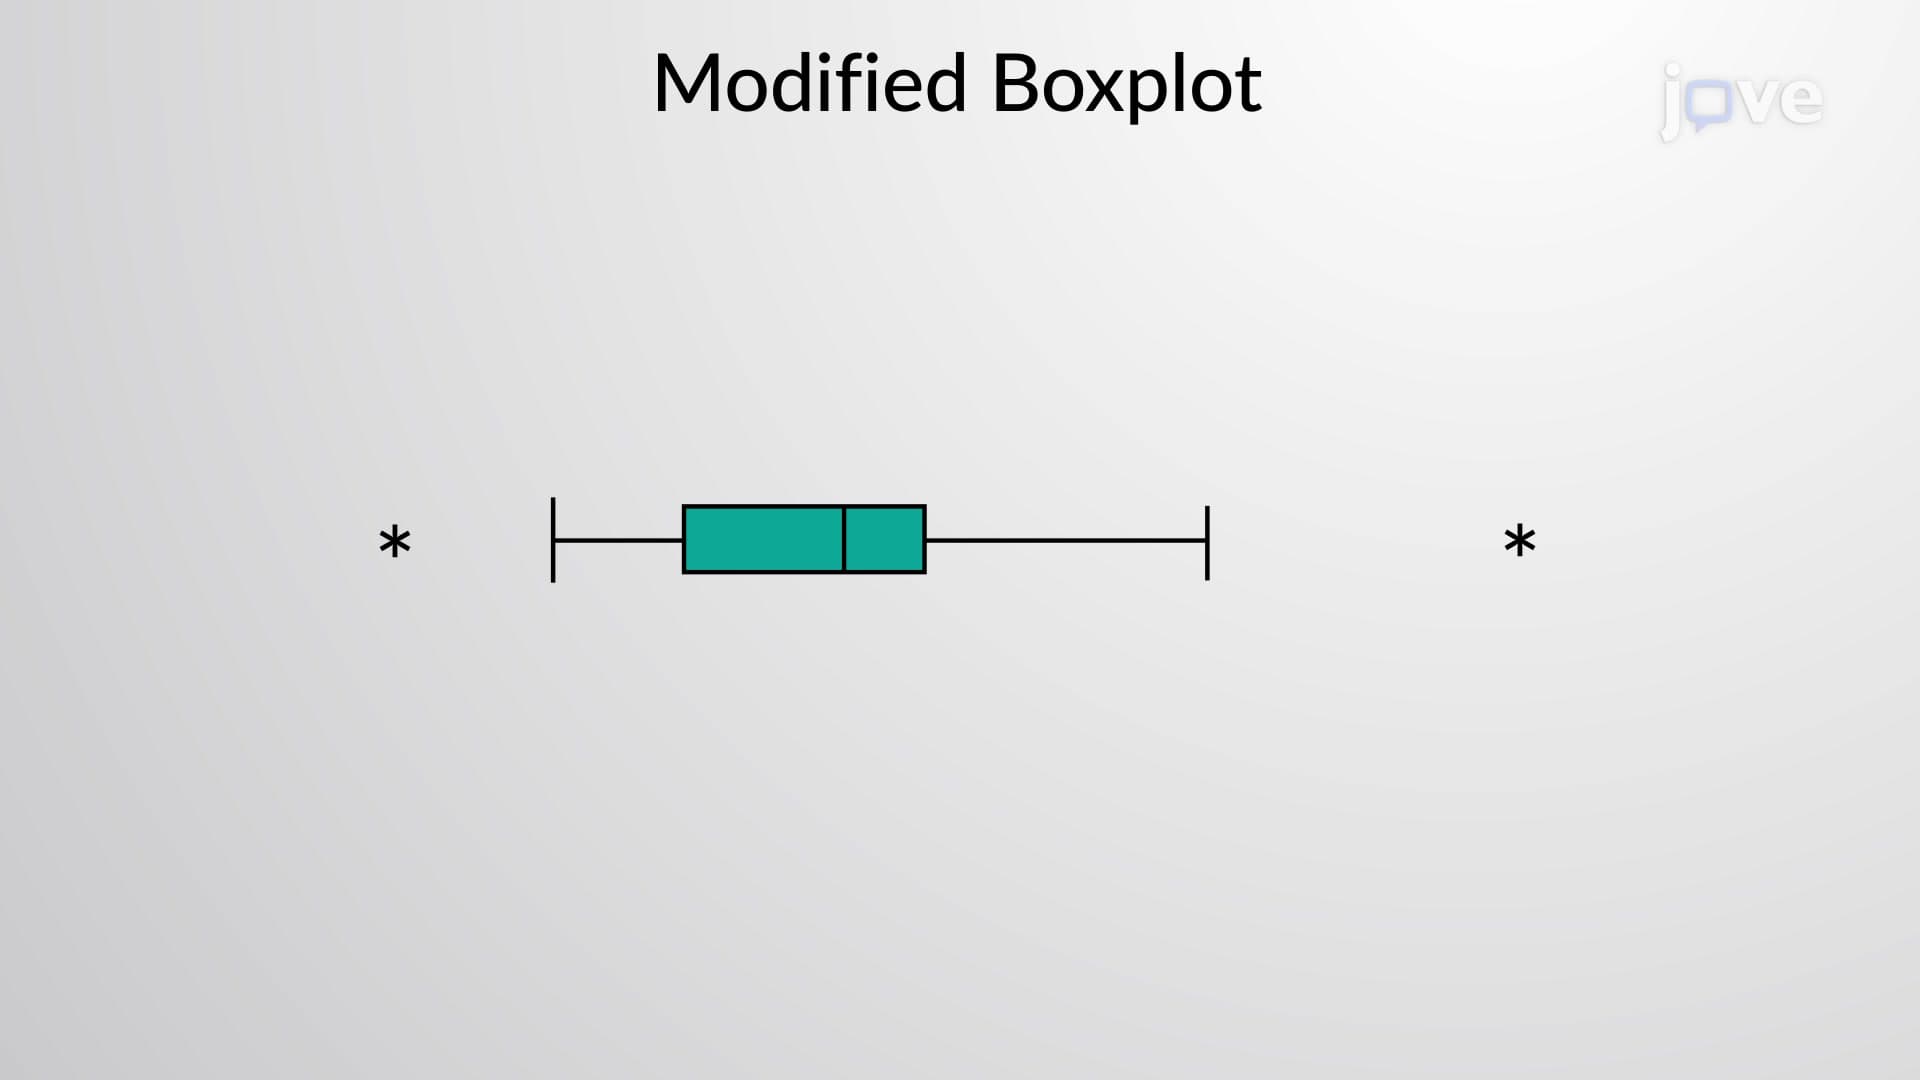
A standard box and whisker plot informs us about the spread of the data in a given sample. One can identify the minimum value, maximum value, first quartile value, second quartile or median value, and third quartile.
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
9.8K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K