在元分析中避免常见的错误:了解Q,I平方,tau平方和预测间隔在报告异质性的不同作用
1Biostat, Inc., Englewood, New Jersey, USA.
Research synthesis methods
|November 8, 2023

概括
常见的元分析统计数据,如Q值,p值和I平方,不能准确地测量效应大小的变化. 研究人员应该使用预测间隔来理解异质性和干预措施在不同人群中的真正影响.
科学领域:
- 生物统计学 生物统计学
- 医学研究方法学 医学研究方法学
背景情况:
- 分析需要报告效应分散与平均效应一起,以了解干预变化.
- 通常使用的异质统计数据 (Q值,p值,I平方) 往往被误解.
- 对异质性的错误分类可能会导致对干预效益的不准确结论.
研究的目的:
- 在元分析中澄清传统异质统计的局限性.
- 引入预测间隔作为效果大小变化的更具信息性的衡量标准.
- 引导研究人员准确评估不同人群的干预影响.
主要方法:
- 批判性地评估Q值,p值和I平方统计所提供的信息.
- 解释预测间隔的统计性质和解释.
- 将预测间隔的实用性与传统的异质性措施进行对比.
主要成果:
- Q值,p值和I平方并不能量化效果大小变化的程度.
- 这些统计数据不足以准确地对异质性进行分类.
- 预测间隔可以直接衡量效果大小的变化,解决关键的临床问题.
结论:
- 在元分析中,传统的异质统计通常是误导性的.
- 预测间隔对于理解干预效应的范围至关重要.
- 对异质性的准确评估对于临床实践中基于证据的决策至关重要.
更多相关视频
 08:36
Author Spotlight: Evaluating the Adjuvant Efficacy and Safety of Angong Niuhuang Pill in Viral Encephalitis Treatment
Published on: April 19, 2024
571
 06:26
Meta-analysis of Voxel-Based Neuroimaging Studies using Seed-based d Mapping with Permutation of Subject Images SDM-PSI
Published on: November 27, 2019
71.1K
相关概念视频
 01:23
Test for Homogeneity
2.0K
The goodness–of–fit test can be used to decide whether a population fits a given distribution, but it will not suffice to decide whether two populations follow the same unknown distribution. A different test, called the test for homogeneity, can be used to conclude whether two populations have the same distribution. To calculate the test statistic for a test for homogeneity, follow the same procedure as with the test of independence. The hypotheses for the test for homogeneity can...
2.0K
 01:13
Accuracy and Errors in Hypothesis Testing
203
Hypothesis testing is a fundamental statistical tool that begins with the assumption that the null hypothesis H0 is true. During this process, two types of errors can occur: Type I and Type II. A Type I error refers to the incorrect rejection of a true null hypothesis, while a Type II error involves the failure to reject a false null hypothesis.
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
In hypothesis testing, the probability of making a Type I error, denoted as α, is commonly set at 0.05. This significance level indicates a 5%...
203
 01:11
Statistical Analysis: Overview
6.6K
When we take repeated measurements on the same or replicated samples, we will observe inconsistencies in the magnitude. These inconsistencies are called errors. To categorize and characterize these results and their errors, the researcher can use statistical analysis to determine the quality of the measurements and/or suitability of the methods.
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
6.6K
 01:00
Detection of Gross Error: The Q Test
6.1K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.1K
 01:19
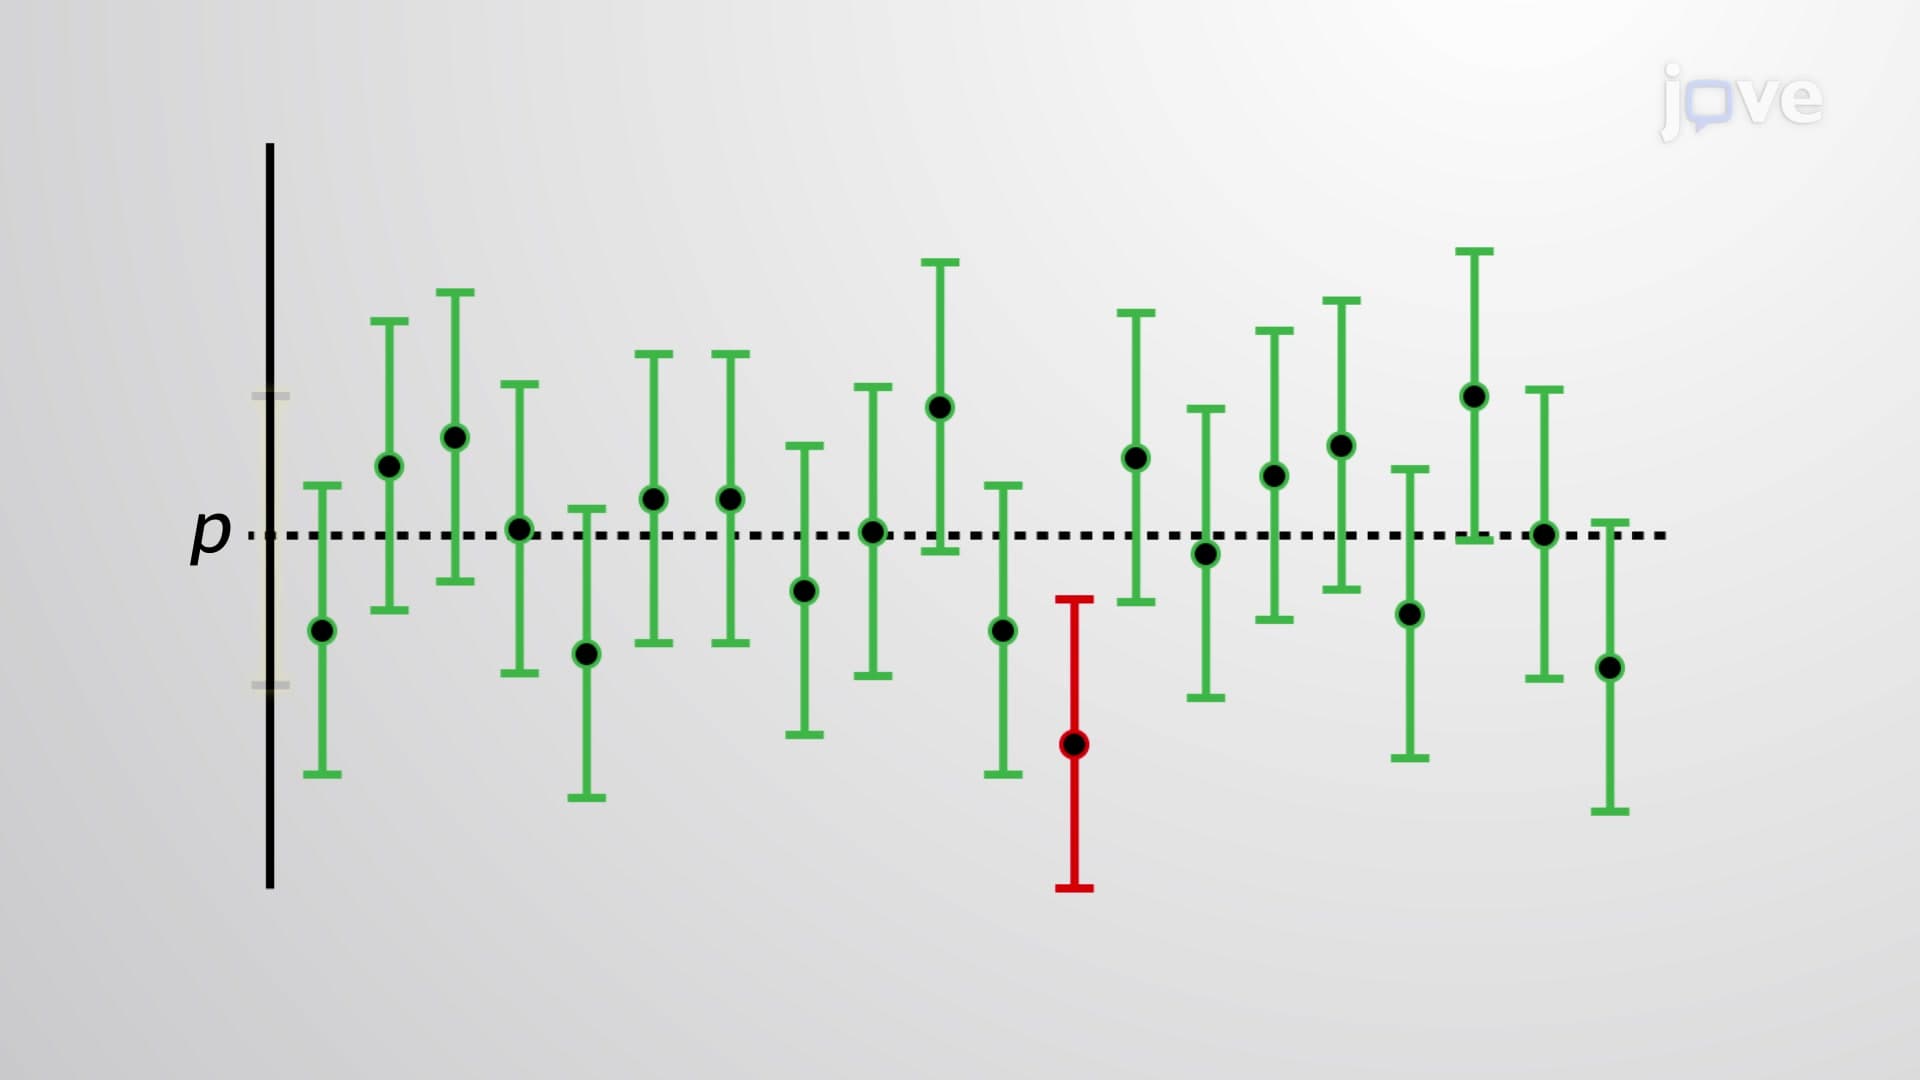
Interpretation of Confidence Intervals
5.8K
A confidence interval is a better estimate of the population than a point estimate, as it uses a range of values from a sample instead of a single value.
Confidence intervals have confidence coefficients that are crucial for their interpretation. The most common confidence coefficients are 0.90, 0.95, and 0.99, which can be written as percentages–90%, 95%, and 99%, respectively.
Suppose a person calculates a confidence interval with a confidence coefficient of 0.95. In that case, they can...
5.8K
 01:04
Significance Testing: Overview
3.4K
Significance testing is a set of statistical methods used to test whether a claim about a parameter is valid. In analytical chemistry, significance testing is used primarily to determine whether the difference between two values comes from determinate or random errors. The effect of a particular change in the measurement protocol, analyst, or sample itself can cause a deviation from the expected result. In the case of a suspected deviation/outlier, we need to be able to confirm mathematically...
3.4K