
基于收缩的随机局部时钟,具有可扩展的推理
Alexander A Fisher1, Xiang Ji2, Akihiko Nishimura3
1Department of Statistical Science, Duke University, Durham, NC, USA.
Molecular biology and evolution
|November 11, 2023

概括
我们开发了一种新的贝叶斯模型,用于分子时钟的进化,提高了分歧时间估计的可扩展性和准确性. 这种收缩时钟方法有效地处理大型的基因树和复杂的进化速率.
科学领域:
- 计算生物学 计算生物学
- 人类遗传学 是一个学科.
- 进化生物学 进化生物学
背景情况:
- 分子时钟模型对于估计进化生物学中的分歧时间至关重要.
- 现有的局部时钟模型面临着可扩展性,模型错误规格的局限性,并且需要先前了解时钟位置.
- 有效而准确的分子时钟推断对于理解进化历史至关重要.
研究的目的:
- 提出一种新的自相关的贝叶斯模型,用于遗传时钟速率进化,克服当前方法的局限性.
- 开发一种高效的计算方法,用于将分子时钟推理扩展到大型遗传树上.
- 将新模型应用于推断哺乳动物和流感病毒系的进化速率.
主要方法:
- 开发了一个自相关的贝叶斯模型,用于遗传时钟速率进化.
- 实现了一种高效的哈密尔顿式蒙特卡洛采样器,并使用闭式梯度计算来实现可扩展性.
- 将"收缩钟"模型应用于模拟的数据集,哺乳动物类型和流感A病毒表面糖蛋白.
主要成果:
- 收缩时钟模型与随机局部时钟方法相比显示出显著的加快速度,特别是在大型数据集中.
- 该模型成功地恢复了动物和哺乳动物的已知局部时钟结构.
- 启用了对流感A病毒表面糖蛋白演变的计算密集分析,没有先前的时钟位置假设.
结论:
- 拟议的收缩时钟模型为分子时钟推断提供了一个可扩展和准确的方法.
- 这种方法推进了对分歧时间的估计和对进化速率变化的理解.
- 在BEAST公开可用的实现促进了在进化和遗传学研究中的更广泛应用.
相关概念视频
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 00:59
Propagation of Uncertainty from Random Error
703
An experiment often consists of more than a single step. In this case, measurements at each step give rise to uncertainty. Because the measurements occur in successive steps, the uncertainty in one step necessarily contributes to that in the subsequent step. As we perform statistical analysis on these types of experiments, we must learn to account for the propagation of uncertainty from one step to the next. The propagation of uncertainty depends on the type of arithmetic operation performed on...
703
 01:13
Randomized Experiments
7.0K
The randomization process involves assigning study participants randomly to experimental or control groups based on their probability of being equally assigned. Randomization is meant to eliminate selection bias and balance known and unknown confounding factors so that the control group is similar to the treatment group as much as possible. A computer program and a random number generator can be used to assign participants to groups in a way that minimizes bias.
Simple randomization
Simple...
Simple randomization
Simple...
7.0K
 01:09
Random Sampling Method
11.2K
Sampling is a technique to select a portion (or subset) of the larger population and study that portion (the sample) to gain information about the population. Data are the result of sampling from a population. The sampling method ensures that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest. Among the various sampling methods used by...
11.2K
 01:09
Random Variables
12.3K
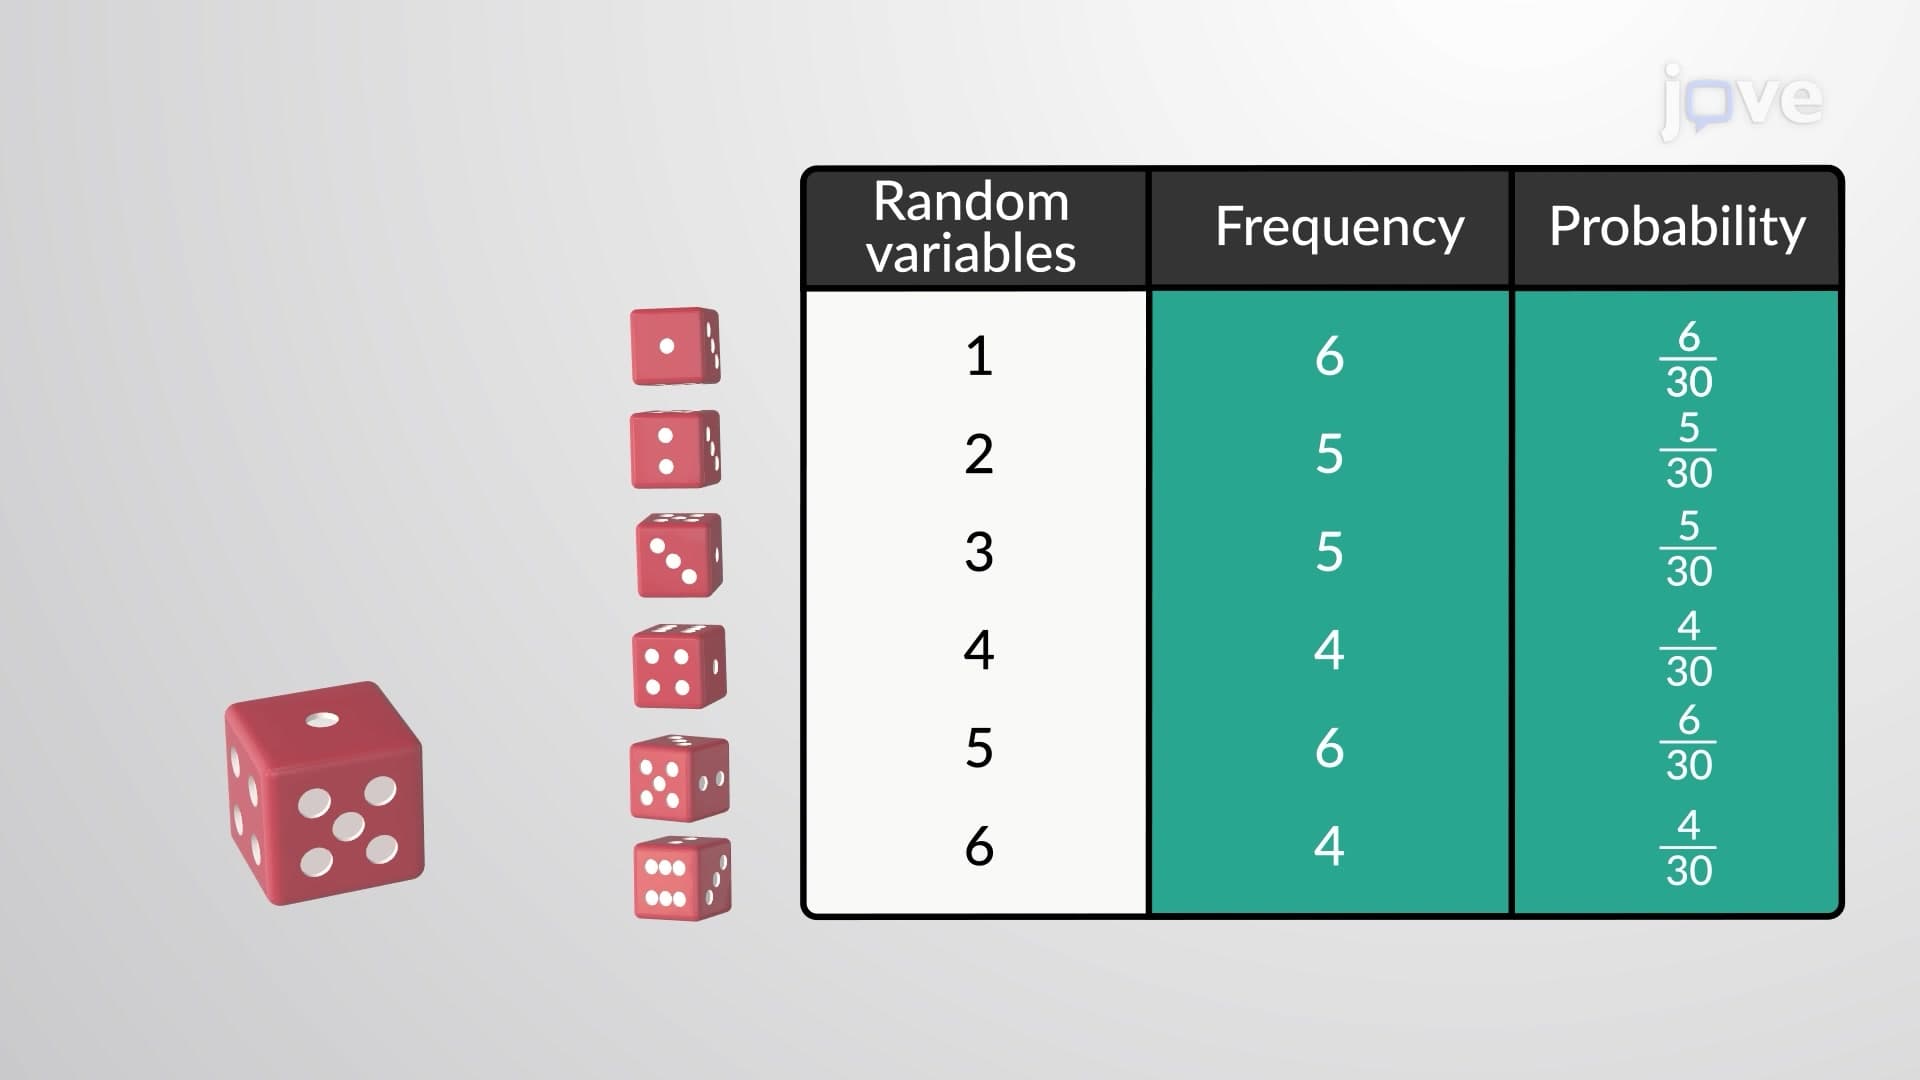
A random variable is a single numerical value that indicates the outcome of a procedure. The concept of random variables is fundamental to the probability theory and was introduced by a Russian mathematician, Pafnuty Chebyshev, in the mid-nineteenth century.
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
Uppercase letters such as X or Y denote a random variable. Lowercase letters like x or y denote the value of a random variable. If X is a random variable, then X is written in words, and x is given as a number.
For example, let X = the...
12.3K
 01:04
Random Error
896
Random or indeterminate errors originate from various uncontrollable variables, such as variations in environmental conditions, instrument imperfections, or the inherent variability of the phenomena being measured. Usually, these errors cannot be predicted, estimated, or characterized because their direction and magnitude often vary in magnitude and direction even during consecutive measurements. As a result, they are difficult to eliminate. However, the aggregate effect of these errors can be...
896