

基于节点嵌入的图形自编码器异常值检测,用于不良妊娠结果
Wasif Khan1, Nazar Zaki2,3, Amir Ahmad4
1Department of Computer Science and Software Engineering, College of Information Technology, United Arab Emirates University, P.O. Box 15551, Al Ain, United Arab Emirates.
Scientific reports
|November 14, 2023

概括
这项研究引入了一种新的图形异常检测方法,使用节点嵌入来预测不良妊娠结果,如低出生体重 (LBW) 和早产 (PTB),显著提高预测准确性.
科学领域:
- 医疗信息学 医疗信息学
- 机器学习 机器学习
- 公共卫生 公共卫生
背景情况:
- 不良的妊娠结果,包括低出生体重 (LBW) 和早产 (PTB),对母亲和婴儿的健康构成重大风险.
- 早期预测对于有效的预防策略至关重要.
- 传统的机器学习模型与不平衡的医疗数据和复杂的关系作斗争.
研究的目的:
- 开发和评估一种基于嵌入节点的新型图形异常点检测算法,用于预测不良妊娠结果.
- 解决现有机器学习方法在处理不平衡数据集和复杂数据结构方面的局限性.
主要方法:
- 从精心策划的阿联人口数据集构建了一个知识图.
- 采用了两个节点嵌入算法和一个图形自编码器 (GAE).
- 根据GAE重建困难,确定了不良妊娠结果作为异常值.
主要成果:
- 将节点嵌入式纳入GAE模型显著提高了预测性能.
- 与传统的GAE模型相比,实现了12%更高的AUC-ROC.
- 对LBW,PTB和非常PTB数据集的预测准确度得到了改进.
结论:
- 节点嵌入和图形异常值检测是改善不良妊娠结果预测的有效策略.
- 这种方法对精心策划的人口数据集有希望.
- 突出了先进的机器学习技术在围产期健康方面的潜力.
相关概念视频
 01:02
Quantifying and Rejecting Outliers: The Grubbs Test
1.6K
Sometimes, a data set can have a recorded numerical observation that greatly deviates from the rest of the data. Assuming that the data is normally distributed, a statistical method called the Grubbs test can be used to determine whether the observation is truly an outlier. To perform a two-tailed Grubbs test, first, calculate the absolute difference between the outlier and the mean. Then, calculate the ratio between this difference and the standard deviation of the sample. This...
1.6K
 01:12
What Are Outliers?
3.9K
Outliers are observed data points that are far from the least squares line. They have unusual values and need to be examined carefully. Though an outlier may result from erroneous data, at other times, it may hold valuable information about the population under study and should be included in the data. Hence, it is crucial to examine what causes a data point to be an outlier.
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
The z score is used to find outliers or unusual values. It should be noted that any values beyond -2 and +2 are...
3.9K
 01:08
Outliers and Influential Points
4.1K
An outlier is an observation of data that does not fit the rest of the data. It is sometimes called an extreme value. When you graph an outlier, it will appear not to fit the pattern of the graph. Some outliers are due to mistakes (for example, writing down 50 instead of 500), while others may indicate that something unusual is happening. Outliers are present far from the least squares line in the vertical direction. They have large "errors," where the "error" or residual is the...
4.1K
 01:07
End Point Prediction: Gran Plot
344
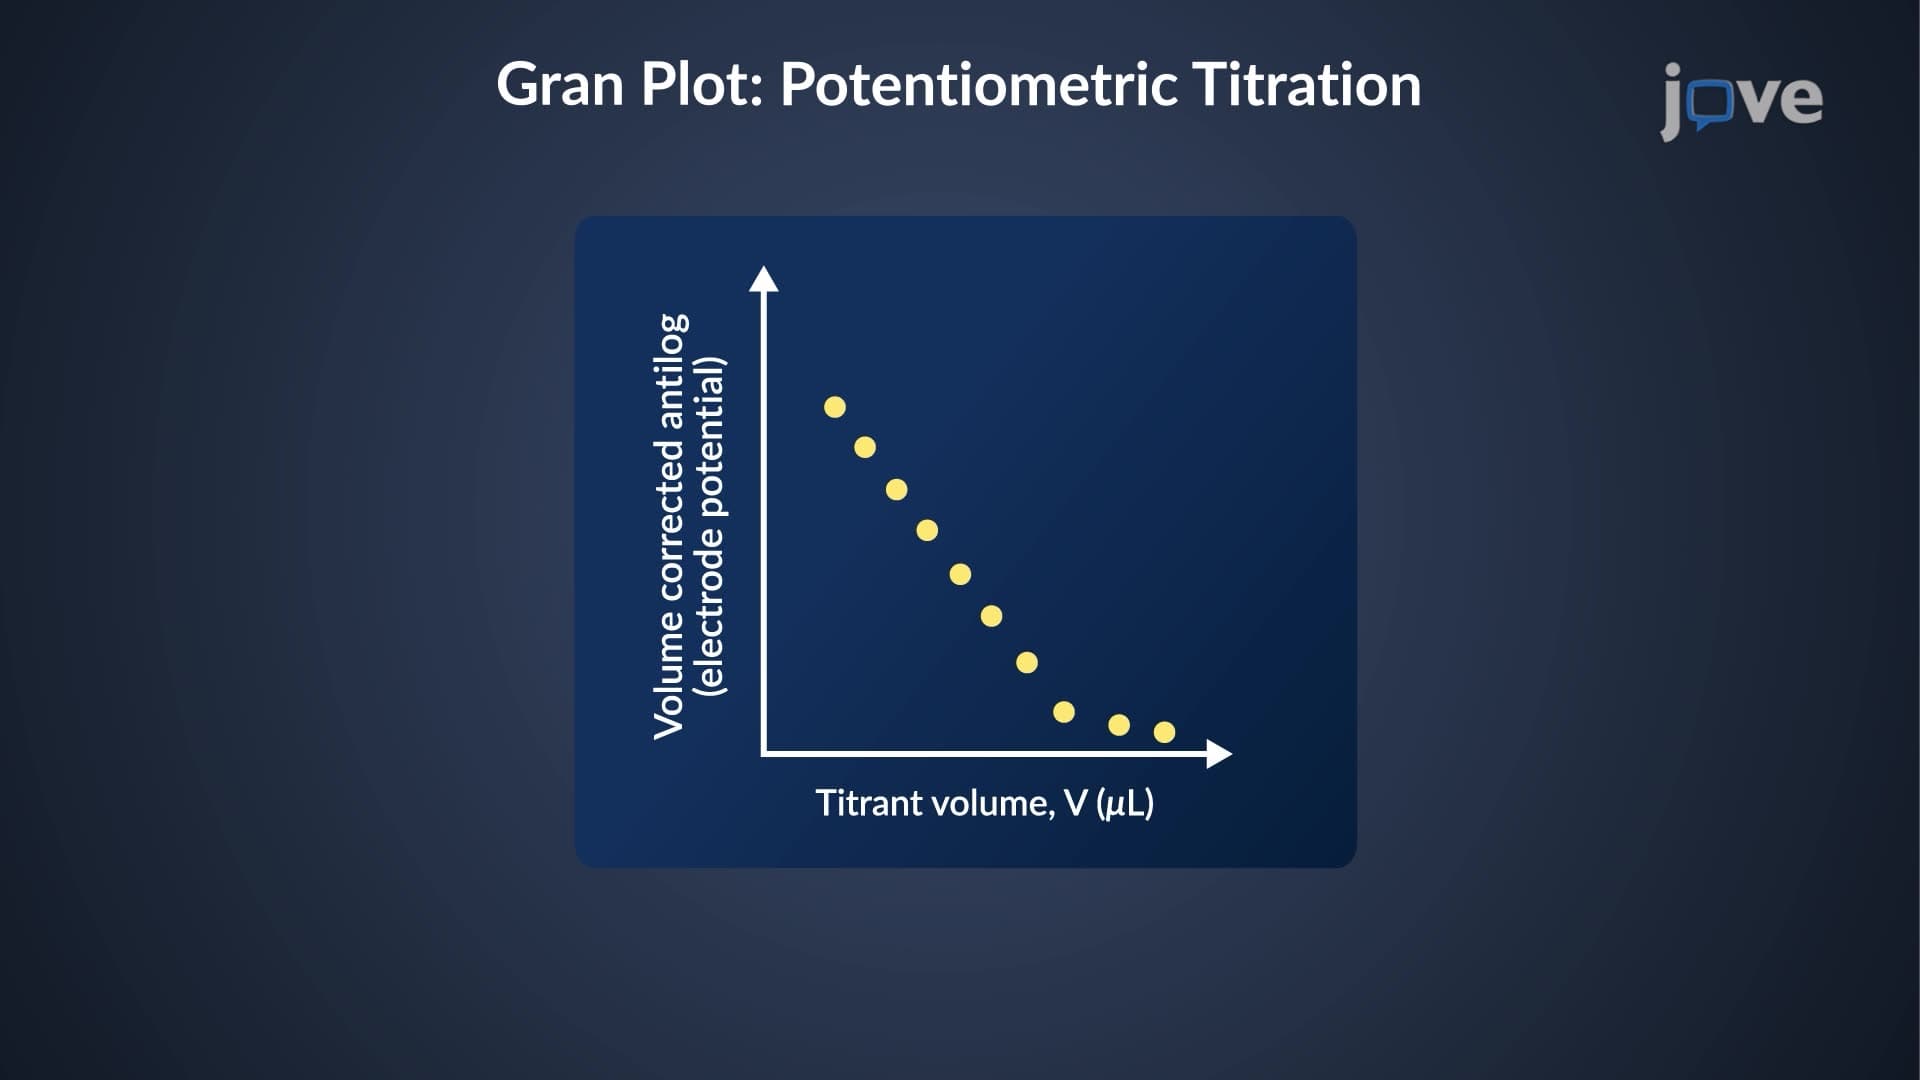
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
344
 01:00
Detection of Gross Error: The Q Test
6.1K
When one or more data points appear far from the rest of the data, there is a need to determine whether they are outliers and whether they should be eliminated from the data set to ensure an accurate representation of the measured value. In many cases, outliers arise from gross errors (or human errors) and do not accurately reflect the underlying phenomenon. In some cases, however, these apparent outliers reflect true phenomenological differences. In these cases, we can use statistical methods...
6.1K
 01:25
Statistical Methods for Analyzing Epidemiological Data
382
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
382