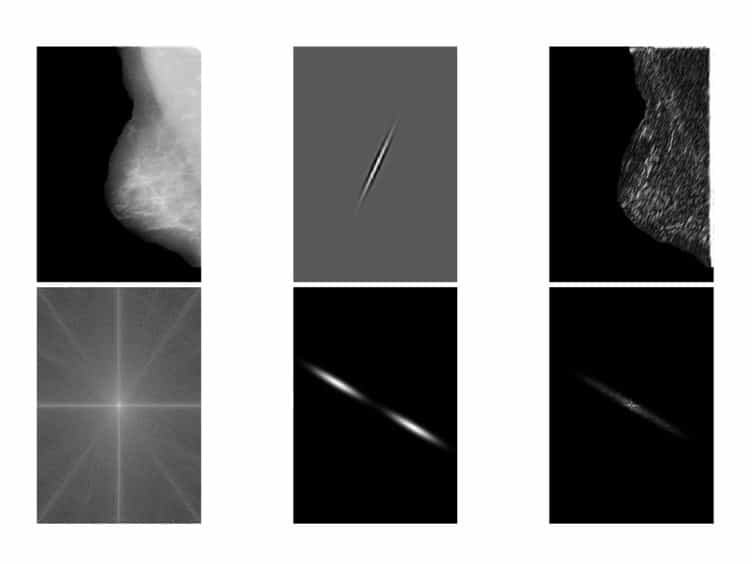

在频域群众分析的通用特征函数损失
IEEE transactions on pattern analysis and machine intelligence
|November 23, 2023

概括
本研究引入了一种新的频率域方法来进行人群分析,使用通用特征函数损失 (GCFL) 来更好地监督人群密度图的学习. 这种方法提高了人群计数和本地化任务的准确性.
科学领域:
- 计算机视觉 计算机视觉
- 机器学习 机器学习
- 信号处理 信号处理
背景情况:
- 现有的人群密度图学习方法依赖于空间信息,这些信息通常是松散的组织和分散的.
- 空间领域的监管限制了从人群地图中提取全面的监管信息.
研究的目的:
- 为群众分析开发一种新的损失函数,利用频率域进行改进的监督.
- 为了解决人群密度地图学习中的空间域监督的局限性.
主要方法:
- 为群众分析设计了一个通用的特征性功能损失 (GCFL).
- 从密度或点图转换空间信息到频率域使用扩展特征函数.
- 基于地图的精心组织的频率内容计算的损失.
主要成果:
- 与分散的空间信息相比,频域表示提供了组织良好的层次信息.
- GCFL在人群计数,人群定位和杂人群计数任务中表现出有效性.
- 对基准数据集的实证结果显示,GCFL在最先进的 (SOTA) 损失和SOTA方法的竞争力方面的优势.
结论:
- 在频率领域的监管为人群分析提供了更有效的方法.
- 对于各种人群分析任务,GCFL提供了一种强大而可适应的工具,其性能优于现有的方法.
相关概念视频
 01:25
Network Function of a Circuit
294
Frequency response analysis in electrical circuits provides vital insights into a circuit's behavior as the frequency of the input signal changes. The transfer function, a mathematical tool, is instrumental in understanding this behavior. It defines the relationship between phasor output and input and comes in four types: voltage gain, current gain, transfer impedance, and transfer admittance. The critical components of the transfer function are the poles and zeros.
294
 01:26
Linear Approximation in Frequency Domain
93
Linear systems are characterized by two main properties: superposition and homogeneity. Superposition allows the response to multiple inputs to be the sum of the responses to each individual input. Homogeneity ensures that scaling an input by a scalar results in the response being scaled by the same scalar.
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
93
 01:08
Determination of Expected Frequency
2.2K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.2K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:11
Mean From a Frequency Distribution
16.8K
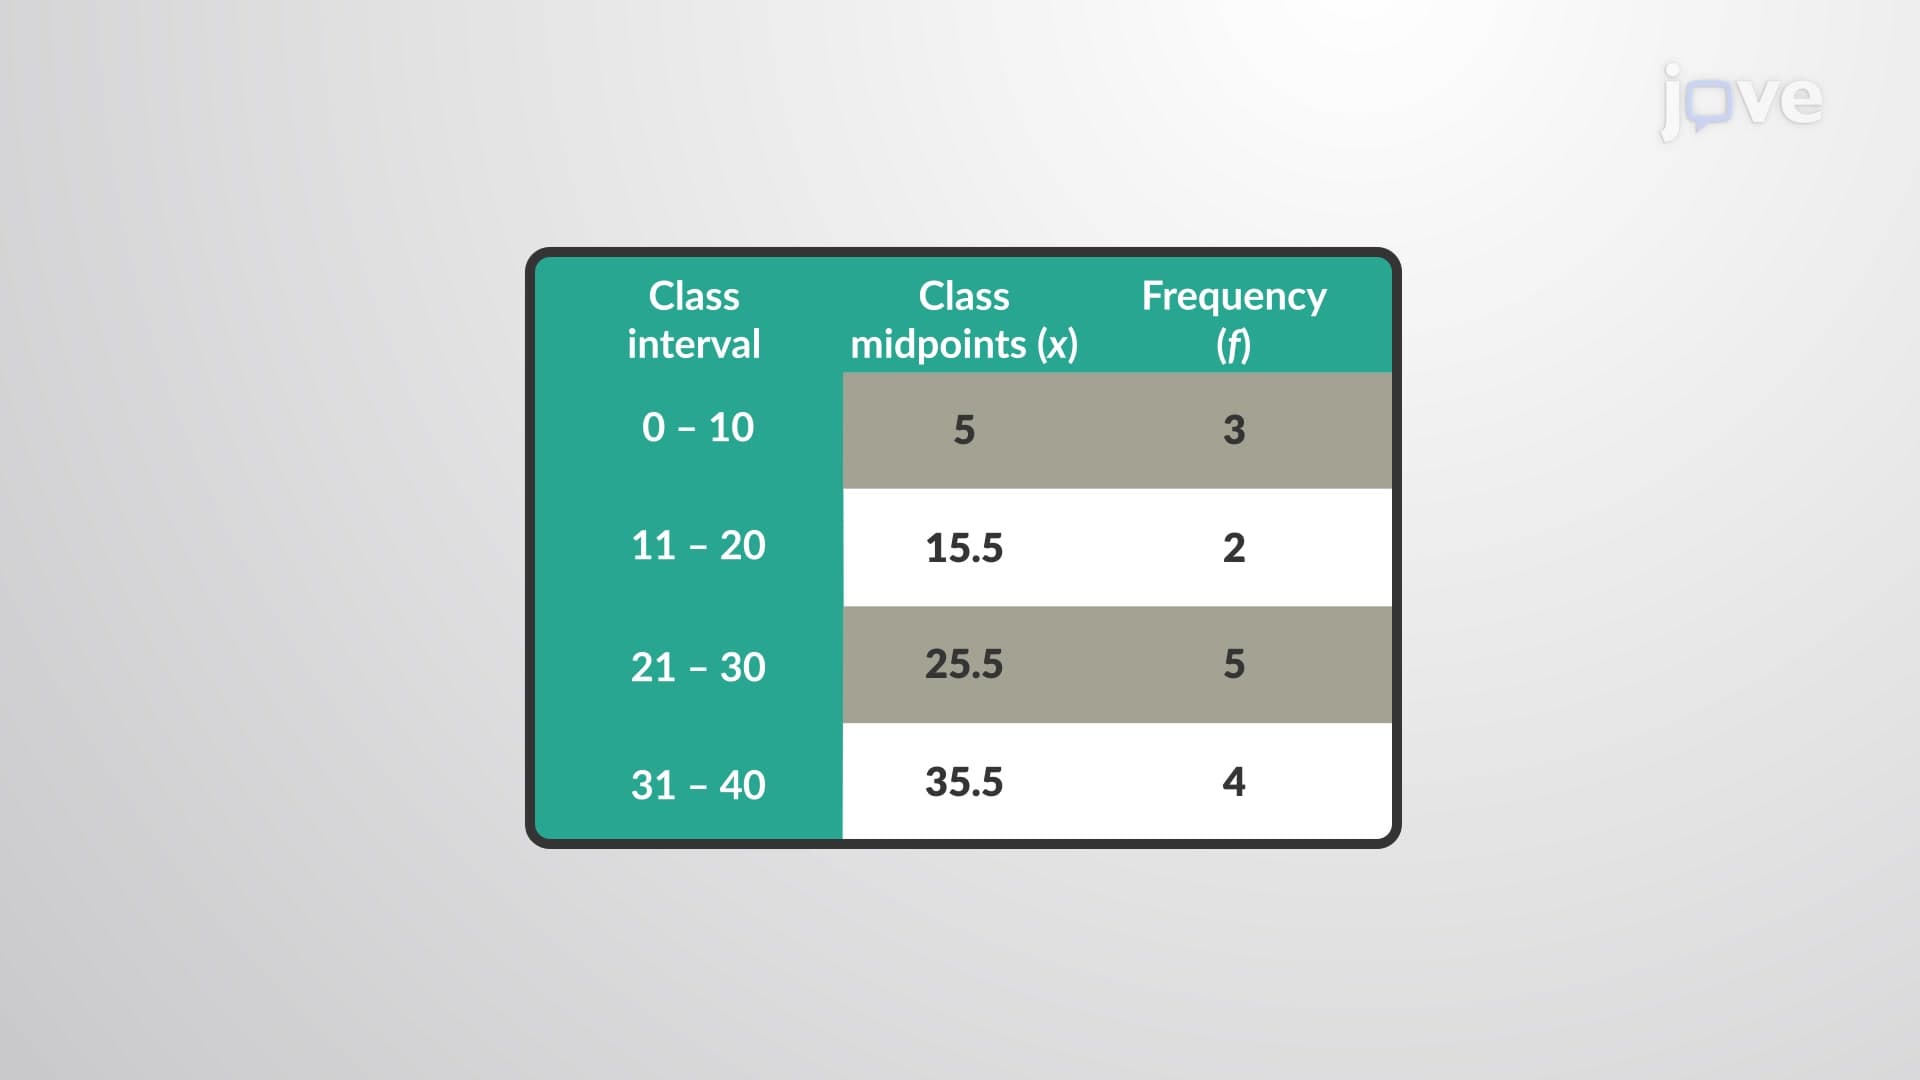
Sometimes, data gathered from an experiment on a large sample or population are organized into concise tables. In such cases, the frequency of the quantitative data set is plotted in the form of a table. Or else, the data values are grouped into the quantity’s intervals, which form classes, and their respective frequencies are known. That is, the data values are distributed over different categories or classes. This is known as frequency distribution.
When such a data set is encountered,...
When such a data set is encountered,...
16.8K
 00:55
Relative Frequency Distribution
11.0K
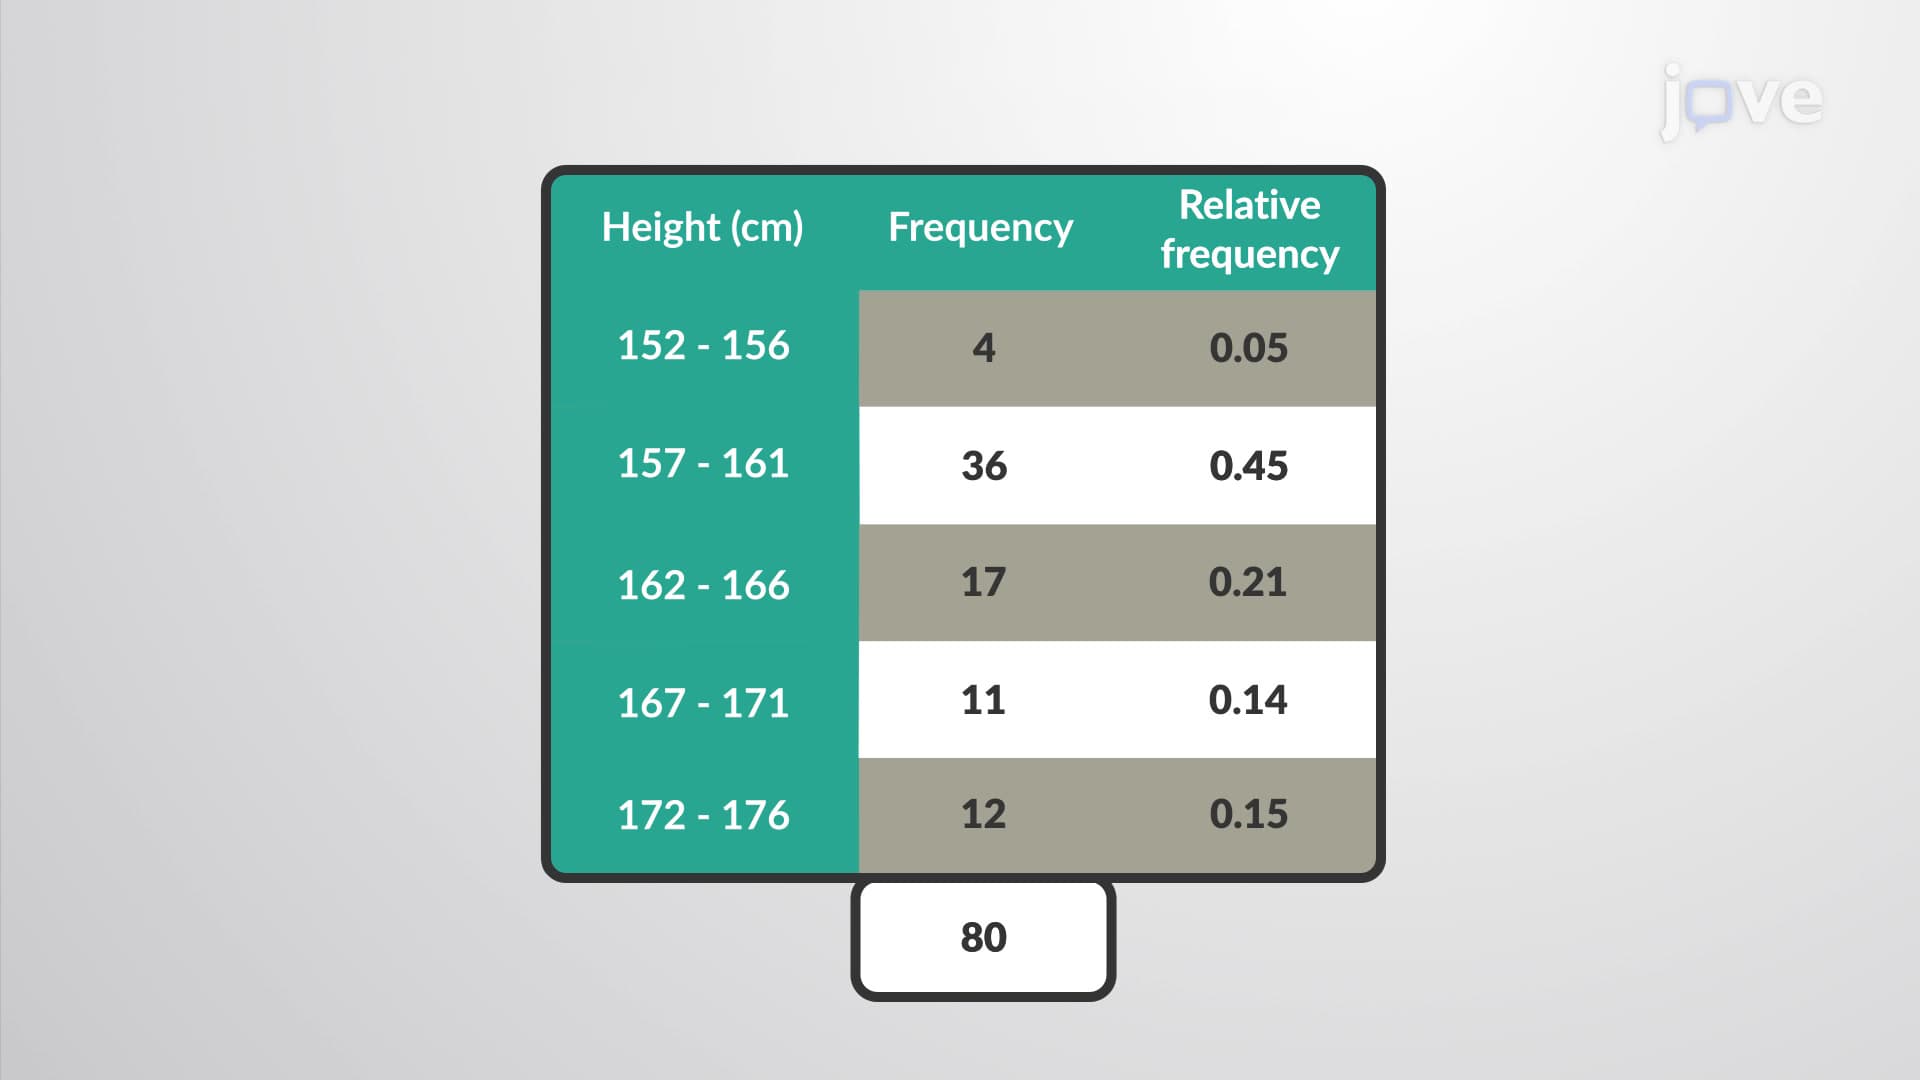
A relative frequency distribution is the proportion or fraction of times a value occurs in a data set. To find the relative frequencies, one can divide each frequency by the total number of data points in the sample. It is very similar to a regular frequency distribution, except that instead of reporting how many data values fall in a class, a relative frequency distribution reports the fraction of data values that fall in a class. These fractions or proportions are called relative frequencies...
11.0K