
使用权重线性预测估计索普拉诺唱歌的元音的形式频率
Eduardo Barrientos1, Edson Cataldo1
1Postgraduate Program in Electrical and Telecommunications Engineering (PPGEET), R. Passo da Pátria, Niterói, RJ, Brazil.
Journal of voice : official journal of the Voice Foundation
|November 24, 2023

概括
一种新的方法,适应高音唱歌声的加权线性预测 (WLP-HPSV),准确地估计了索普拉诺歌唱中的形式频率. 这种技术优于传统方法,在各种音调中提供了强大的声乐分析.
科学领域:
- 声学 声学 在声学方面
- 语音科学 语言科学
- 生物声学是一种生物声学.
背景情况:
- 准确的形式频率估计对于理解语音产生至关重要.
- 高调的歌声对传统的光谱分析方法构成独特的挑战.
- 像线性预测编码 (LPC) 这样的现有方法可能会与歌唱元音的复杂性作斗争.
研究的目的:
- 引入和评估一种新的方法,适应高调歌声的加权线性预测 (WLP-HPSV),用于精确的形式频率估计.
- 将WLP-HPSV的性能与已建立的线性预测编码 (LPC) 方法进行比较.
- 为了研究唱歌中音调和声道/状管特征之间的关系.
主要方法:
- 开发了适应高音唱歌声 (WLP-HPSV) 的加权线性预测方法.
- 在WLP分析框架内的集成零频过 (ZFF) 技术.
- 评估WLP-HPSV使用合成 /u/母音和自然 /a/和 /u/歌词母音.
- 将WLP-HPSV结果与从LPC方法获得的结果进行比较.
主要成果:
- 与LPC相比,WLP-HPSV在准确捕捉光谱特征方面表现出卓越的性能.
- 该方法准确地估计了合成和自然唱歌元音的形式频率.
- 观察到近闭阶段 (QCP) 参数与音调的变化,表明声道和喉相互作用.
- WLP-HPSV在估计各种音高的形式频率方面表现出强大.
结论:
- WLP-HPSV是一种高效的方法,用于在高调的唱歌声中准确估计形式频率.
- WLP-HPSV方法比传统的LPC分析提供了更好的稳定性和准确性.
- 这项研究提供了对高音,声道配置和高源特征在高唱歌唱期间的动态关系的见解.
相关概念视频
 01:26
Linear Approximation in Frequency Domain
93
Linear systems are characterized by two main properties: superposition and homogeneity. Superposition allows the response to multiple inputs to be the sum of the responses to each individual input. Homogeneity ensures that scaling an input by a scalar results in the response being scaled by the same scalar.
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
In contrast, nonlinear systems do not inherently possess these properties. However, for small deviations around an operating point, a nonlinear system can often be approximated as linear....
93
 01:08
Determination of Expected Frequency
2.2K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.2K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:21
Linear Approximation in Time Domain
83
Nonlinear systems often require sophisticated approaches for accurate modeling and analysis, with state-space representation being particularly effective. This method is especially useful for systems where variables and parameters vary with time or operating conditions, such as in a simple pendulum or a translational mechanical system with nonlinear springs.
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length,...
For a simple pendulum with a mass evenly distributed along its length and the center of mass located at half the pendulum's length,...
83
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:11
Mean From a Frequency Distribution
16.8K
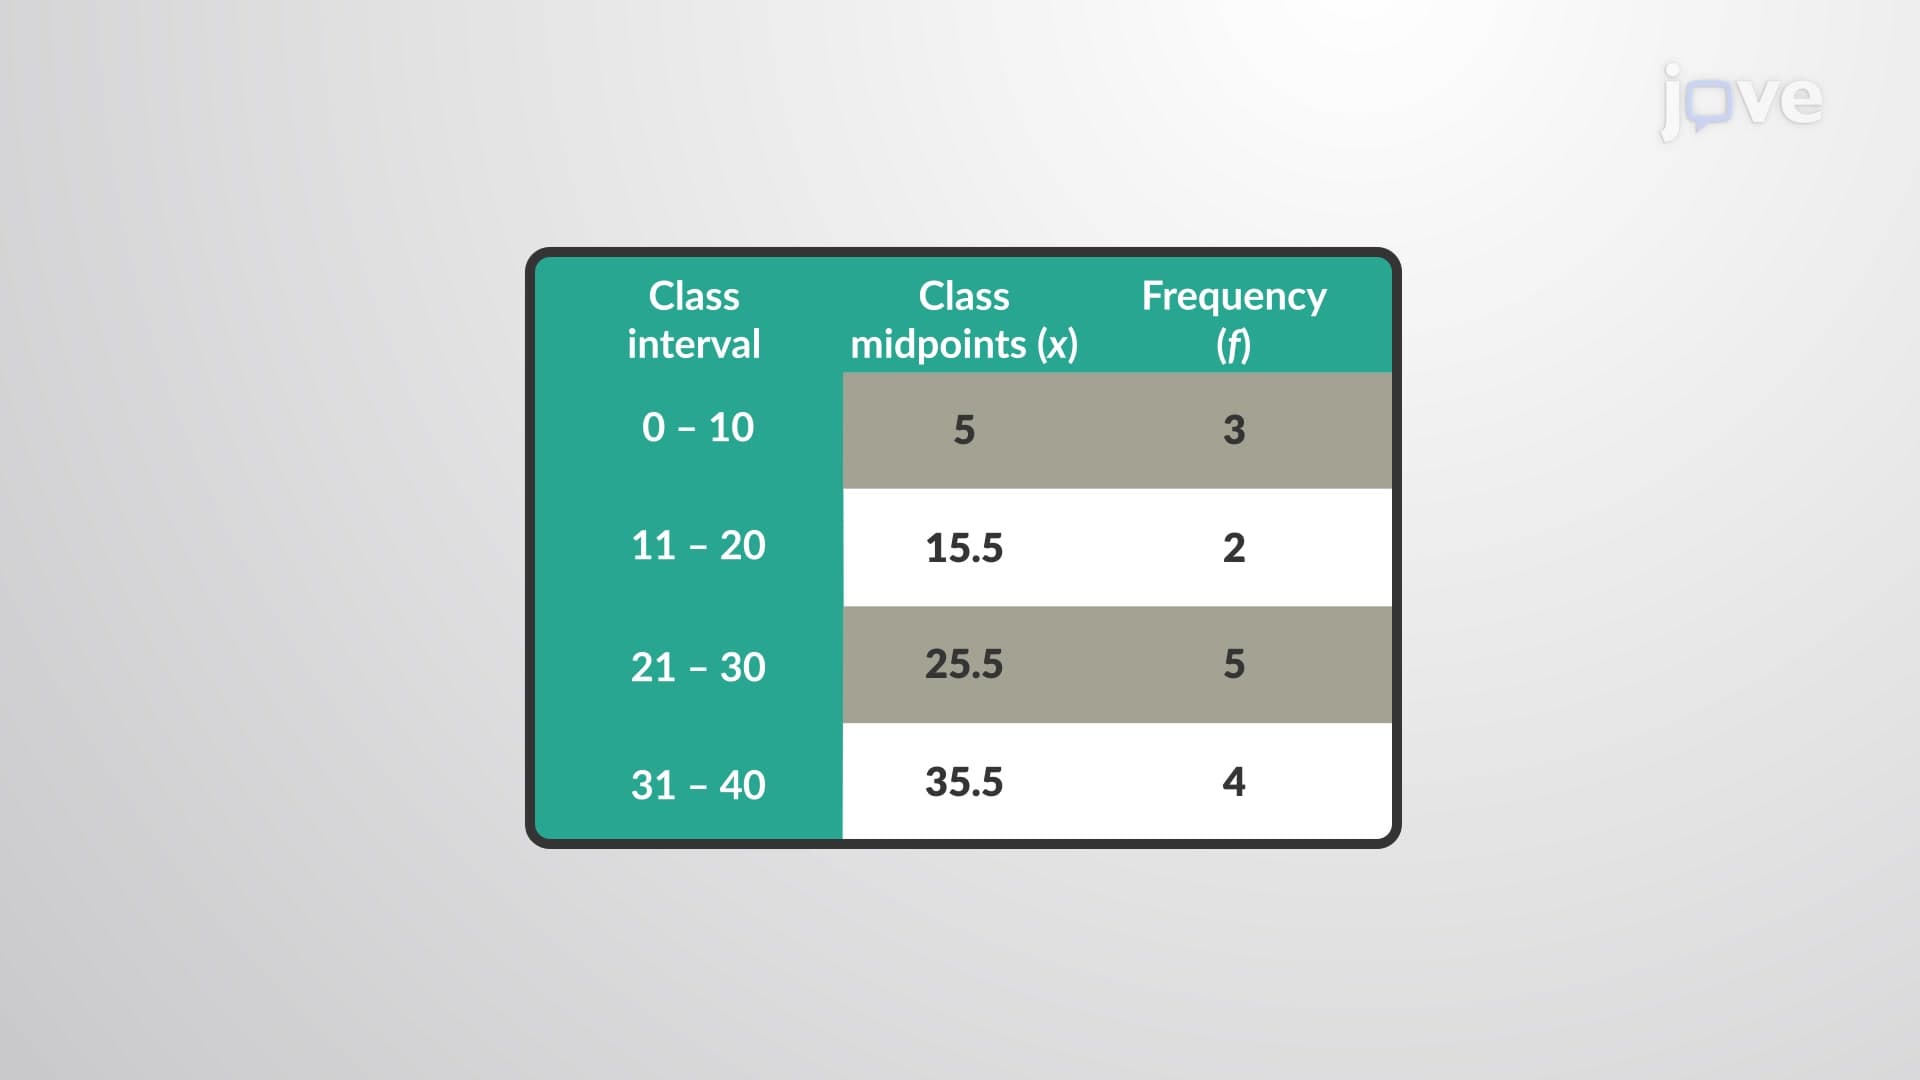
Sometimes, data gathered from an experiment on a large sample or population are organized into concise tables. In such cases, the frequency of the quantitative data set is plotted in the form of a table. Or else, the data values are grouped into the quantity’s intervals, which form classes, and their respective frequencies are known. That is, the data values are distributed over different categories or classes. This is known as frequency distribution.
When such a data set is encountered,...
When such a data set is encountered,...
16.8K