
在选定的南美国家对出版物输出的文献计量分析
Aparna Narayan1, Bharti Chogtu2, Manthan Janodia3
1Manipal College of Dental Sciences, Manipal Academy of Higher Education, Manipal, Karnataka, India.
F1000Research
|December 7, 2023

概括
研究和开发 (R&D) 的支出和产出在南美各地有很大差异. 巴西花费最多,但引用影响较低,而乌拉圭则在投资较少的情况下显示出高影响.
科学领域:
- 圣经计量学和科学计量学
- 科学和技术政策政策 科学和技术政策
- 南美研究景观研究景观
背景情况:
- 研究成果是国家科学能力的关键指标.
- 研究和开发 (R&D) 的预算拨款往往与研究成果相关.
- 对于南美国家而言,仅存在有限的图书统计分析.
研究的目的:
- 用各种指标分析和比较南美国家的研究成果.
- 调查R&D投资与该地区研究影响之间的关系.
- 识别研究生产率和合作模式的差异.
主要方法:
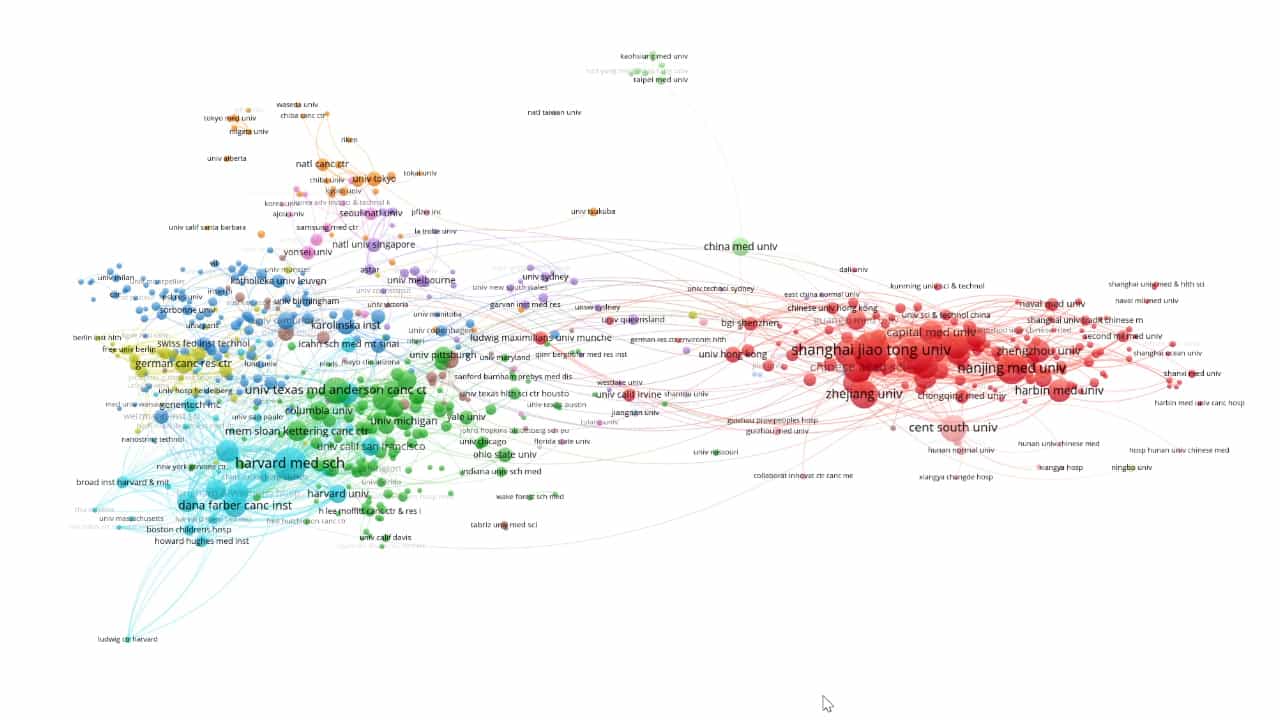
- 从南美国家研究出版物的图书统计分析.
- 数据收集和分析涵盖2010年至2020年期间的数据.
- 评估包括研发支出,出版成果,字段加权引用影响 (FWCI),人均研究人员和共同作者模式在内的指标.
主要成果:
- 巴西的研发支出最高,但FWCI影响最低.
- 乌拉圭的FWCI高,尽管研发投资和出版量较低.
- 阿根廷在每百万人口的研究人员中处于领先地位,但每名研究人员 (0.3 /年) 的论文数量最低.
- 在研发支出,研究成果,研究人员生产力和共同作者趋势方面观察到显著的差异.
结论:
- 研究和开发投资与研究影响之间的关系是复杂的,南美国家之间存在差异.
- 高度的研发支出并不能自动转化为更高的引用影响,就像在巴西看到的那样.
- 乌拉圭的成功表明,高效的研发战略可以在适度的投资下产生高影响.
- 阿根廷每名研究人员的论文产量低,表明研究翻译或生产率的潜在效率低下.
相关概念视频
 01:11
Statistical Analysis: Overview
6.6K
When we take repeated measurements on the same or replicated samples, we will observe inconsistencies in the magnitude. These inconsistencies are called errors. To categorize and characterize these results and their errors, the researcher can use statistical analysis to determine the quality of the measurements and/or suitability of the methods.
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
One of the most commonly used statistical quantifiers is the mean, which is the ratio between the sum of the numerical values of all results and the...
6.6K
 01:12
Analysis of Population Pharmacokinetic Data
266
Analysis of population pharmacokinetic data involves studying the behavior of drugs within diverse populations to understand their pharmacokinetic parameters. Traditional pharmacokinetic methods typically involve collecting samples from a few individuals and estimating these parameters. While these methods are commonly used, they have limitations in capturing the variability in drug response among individuals or heterogeneous populations. Population pharmacokinetics is employed to address these...
266
 01:01
Production Efficiency
16.8K
Net production efficiency (NPE) is the efficiency at which organisms assimilate energy into biomass for the next trophic level. Due to low metabolic rates and less energy spent on thermoregulatory processes, the NPE of ectotherms (cold-blooded animals) is 10 times higher than endotherms (warm-blooded animals).
16.8K
 01:12
Statistical Methods to Analyze Parametric Data: ANOVA
391
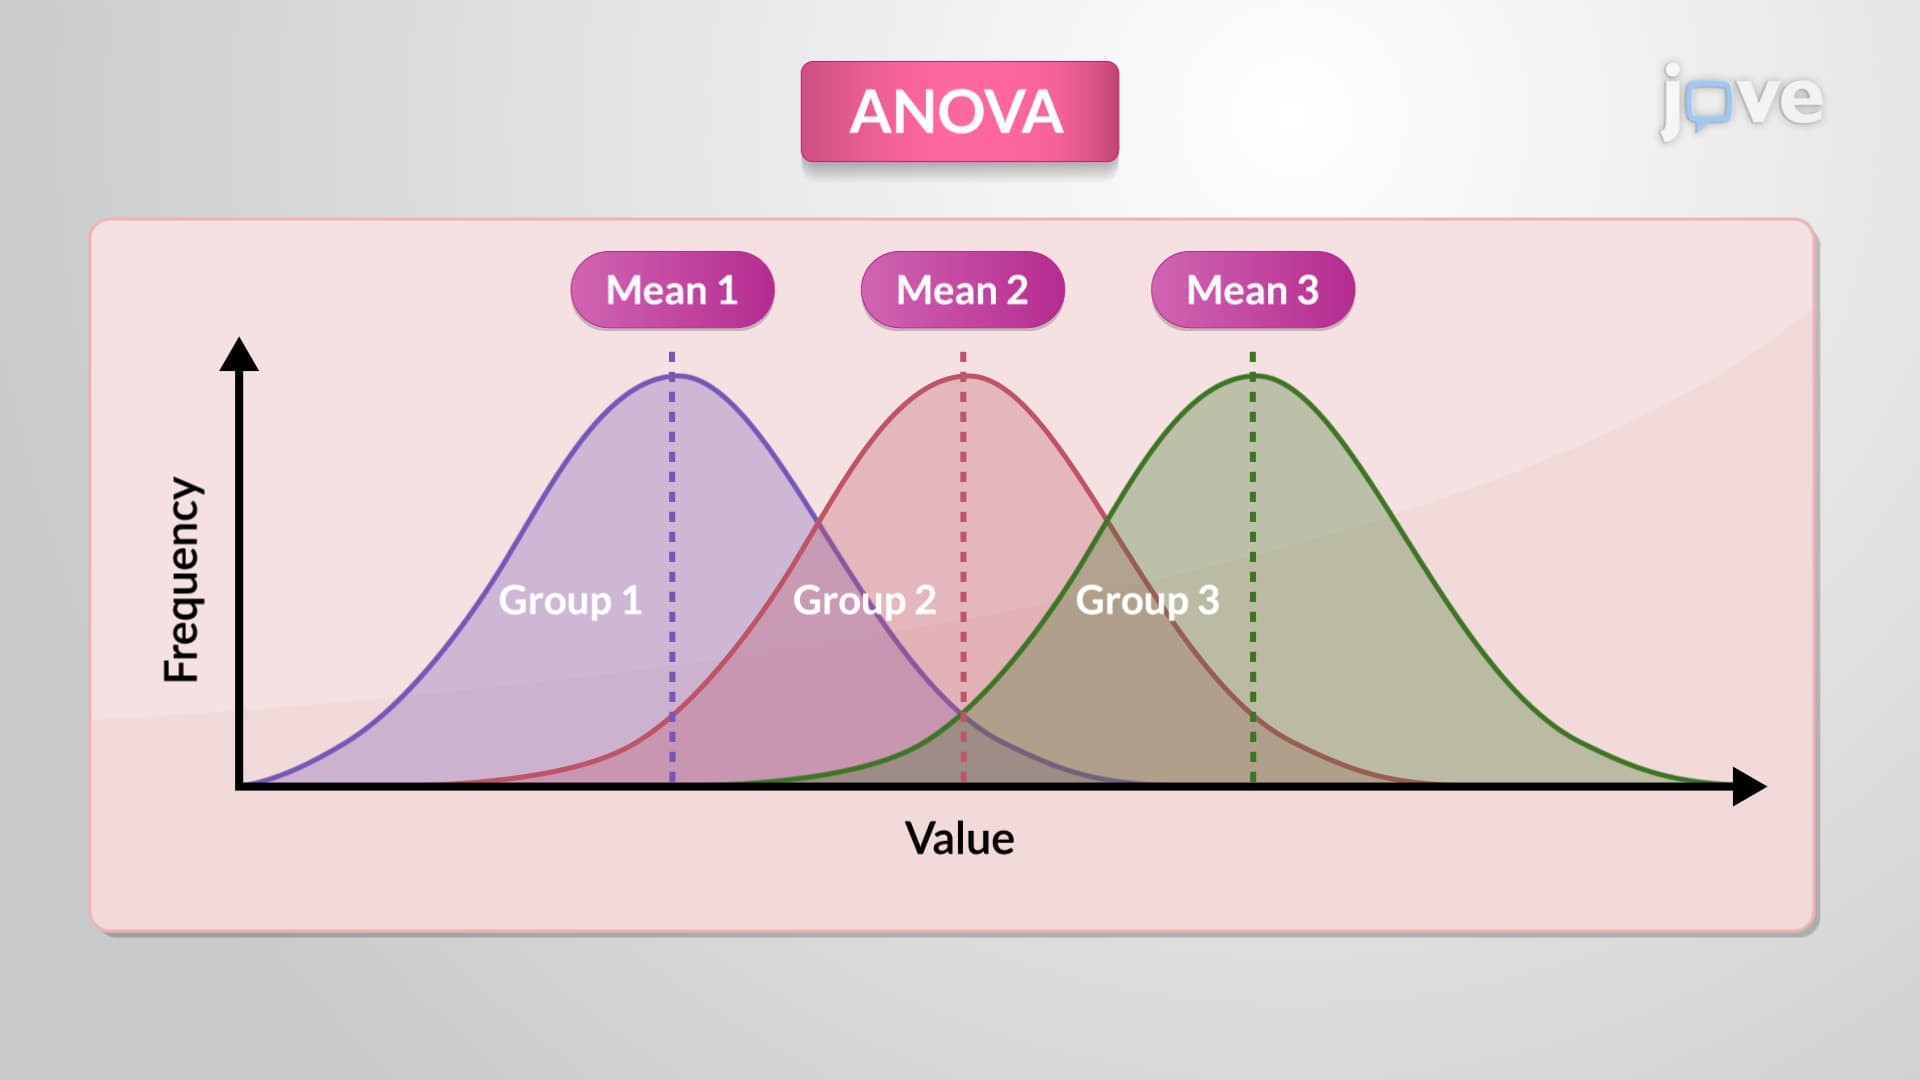
Analysis of Variance, or ANOVA, is a powerful statistical technique used to analyze parametric data, primarily in research and experimental studies. It's designed to compare the means of two or more groups, assisting researchers in identifying any significant differences between these group means. There are two main types of ANOVA based on the complexity of the analysis: one-way and two-way.
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
One-way ANOVA is applied when a single independent variable or factor is scrutinized. It compares...
391
 02:20
Longitudinal Research
12.0K
Sometimes we want to see how people change over time, as in studies of human development and lifespan. When we test the same group of individuals repeatedly over an extended period of time, we are conducting longitudinal research. Longitudinal research is a research design in which data-gathering is administered repeatedly over an extended period of time. For example, we may survey a group of individuals about their dietary habits at age 20, retest them a decade later at age 30, and then again...
12.0K
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K