
健身模型提供了SARS-CoV-2变种频率的准确短期预测
Eslam Abousamra1,2, Marlin Figgins1,3, Trevor Bedford1,2,4
1Vaccine and Infectious Disease Division, Fred Hutchinson Cancer Center, Seattle, WA, USA.
medRxiv : the preprint server for health sciences
|December 11, 2023

概括
准确预测SARS-CoV-2变种的频率至关重要. 像多项逻辑回归 (MLR) 这样的简单模型提供可靠的短期预测,即使基因组数据有限.
科学领域:
- 基因组流行病学基因组流行病学
- 病毒进化建模病毒进化建模
- 公共卫生监督是对公共卫生的监督.
背景情况:
- 基因组监测对于跟踪病原体进化,告知公共卫生战略和指导疫苗开发至关重要.
- 有几个模型,包括多项逻辑回归 (MLR) 和各种健身参数 (FGA,GARW,Piantham),用于预测SARS-CoV-2变种动态.
研究的目的:
- 引入和应用一个框架来评估病毒变种频率的实时预测.
- 评估不同进化模型在预测SARS-CoV-2变种在2022年期间传播的准确性.
- 调查基因组监测强度,序列数量和质量的对预测准确性的影响.
主要方法:
- 开发了一个实时预测评估框架.
- 应用并将MLR,FGA,GARW和Piantham模型与不同国家的2022年SARS-CoV-2进化数据进行比较.
- 进行了系统的下方采样实验,以确定最佳序列数据要求,以准确预测.
主要成果:
- 大多数模型表现出良好的表现,为变种频率提供了合理的预测.
- 在具有强有力的监测的国家,MLR模型在30天的预测中实现了~0.6%的中位数绝对误差和~6%的平均绝对误差.
- 每周只有1000个序列被发现足以准确的短期预测.
结论:
- 健身模型是有价值的预后工具,用于对SARS-CoV-2等病毒病原体的短期进化预测.
- 强大的基因组监测,即使有适度的序列数据量,也支持可靠的变异频率预测.
- MLR模型提供了一种简单而有效的实时SARS-CoV-2变种预测方法.

相关概念视频
 01:18
Steps in Outbreak Investigation
131
In the ever-evolving field of public health, statistical analysis serves as a cornerstone for understanding and managing disease outbreaks. By leveraging various statistical tools, health professionals can predict potential outbreaks, analyze ongoing situations, and devise effective responses to mitigate impact. For that to happen, there are a few possible stages of the analysis:
131
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:08
Determination of Expected Frequency
2.2K
Suppose one wants to test independence between the two variables of a contingency table. The values in the table constitute the observed frequencies of the dataset. But how does one determine the expected frequency of the dataset? One of the important assumptions is that the two variables are independent, which means the variables do not influence each other. For independent variables, the statistical probability of any event involving both variables is calculated by multiplying the individual...
2.2K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:17
Clearance Models: Noncompartmental Models
62
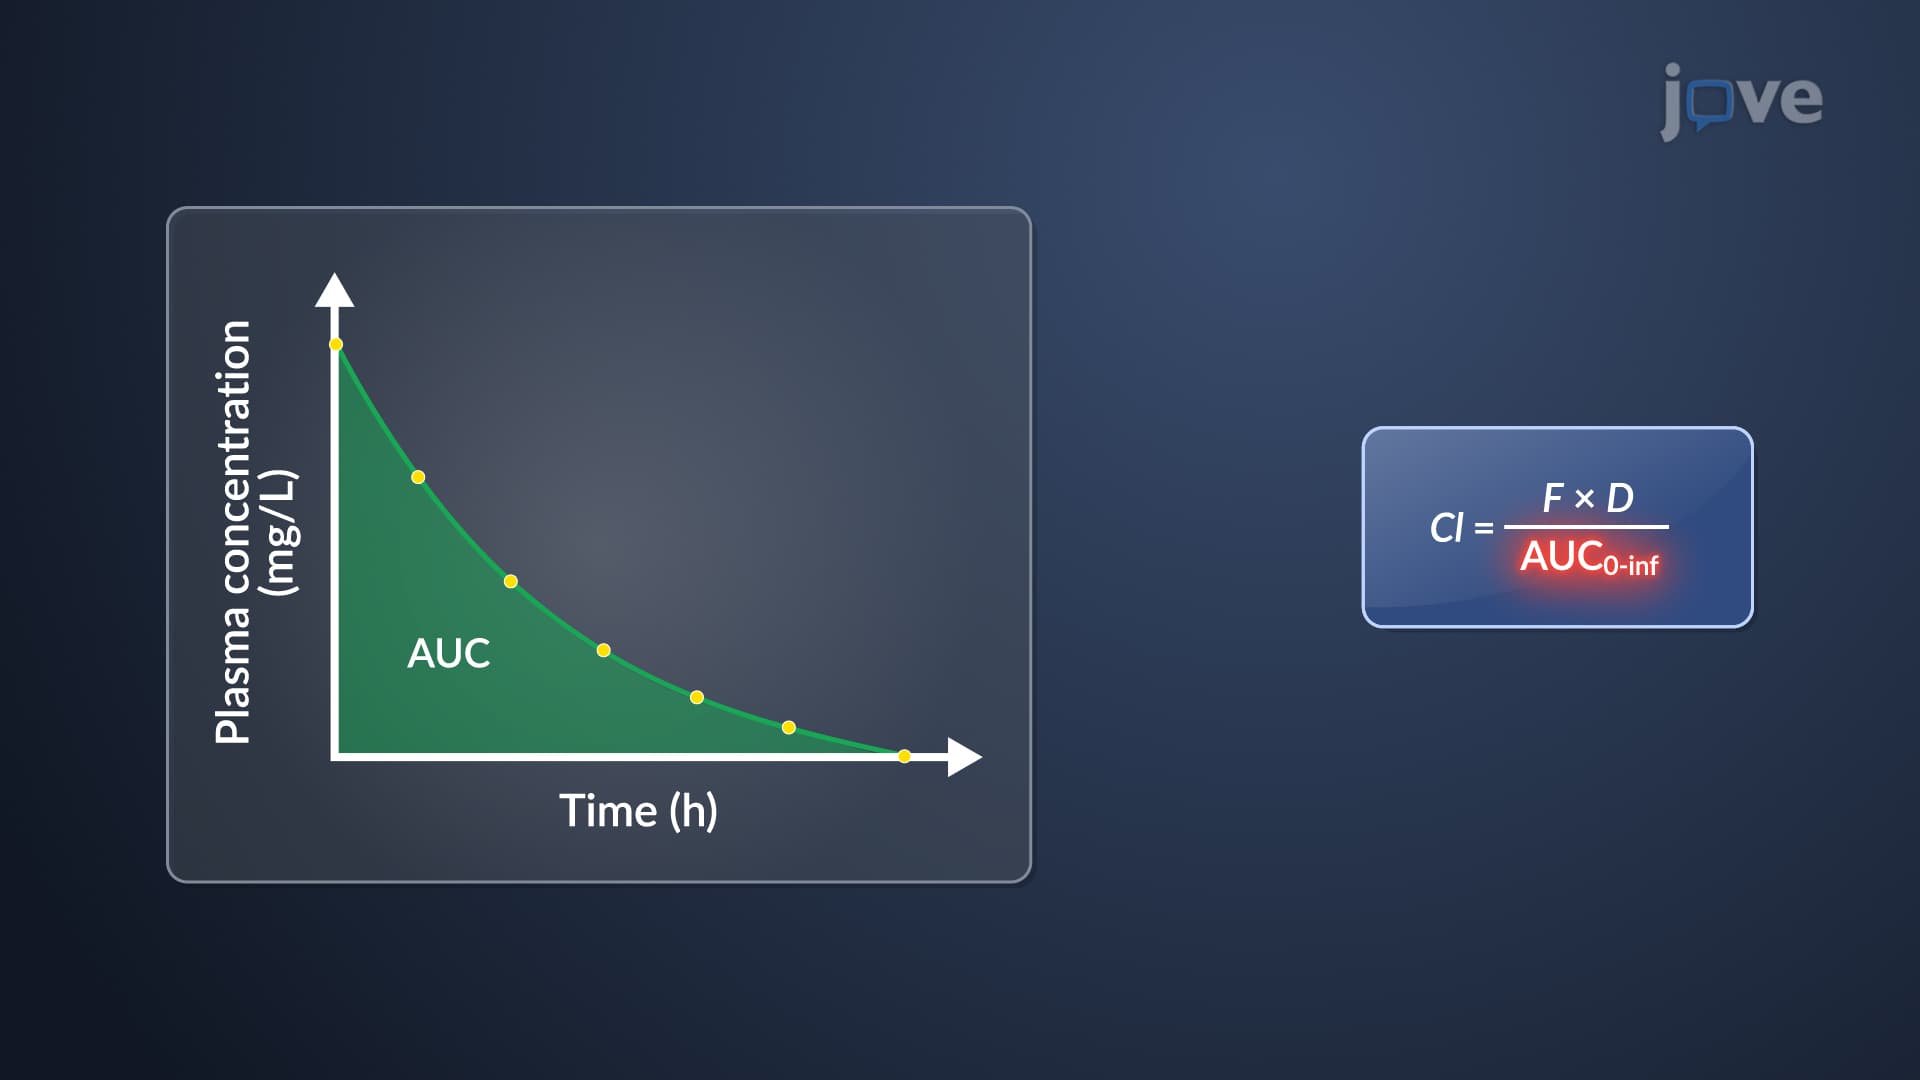
Clearance is a pharmacokinetic parameter traditionally defined by compartment models, signifying the rate at which a drug is expelled from the body. However, a noncompartmental model offers an alternative method for assessing clearance, primarily employing empirical data obtained after administering a single drug dose.
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
The noncompartmental approach capitalizes on extensive sampling data, correlating the volume of distribution to systemic exposure and the administered dosage. This method enables...
62