
基于时间序列的类型人气特征的调查,用于票房成功预测
Muzammil Hussain Shahid1, Muhammad Arshad Islam1
1Computer Science, National University of Computer and Emerging Sciences, Islamabad, Pakistan.
PeerJ. Computer science
|December 11, 2023

概括
早期预测电影利率是很困难的. 这项研究使用时间序列分析引入了类型流行特征,通过梯度提升将预测准确度提高了35%以上.
科学领域:
- * 计算金融和娱乐分析.
- * 机器学习在媒体投资中的应用.
- * 预测模型用于票房表现.
背景情况:
- * 早期电影投资决策受到有限的生产数据的阻碍.
- *准确预测电影利率仍然是一个重大挑战.
- *现有的模型往往缺乏动态的类型趋势分析.
研究的目的:
- * 开发新的功能来预测电影在制作阶段的利能力.
- * 利用时间序列分析来估计类型的流行程度.
- * 提高机器学习模型在票房收入预测中的性能.
主要方法:
- * 拟议的新型"流派人气"特征包括预算,收入,频率,成功和投资回报率 (ROI).
- * 利用时间序列预测来预测类型的流行趋势.
- * 整合预测的类型受欢迎程度与发布时间,用于机器学习分类器培训.
- *使用渐变增强分类器进行绩效评估.
主要成果:
- * 电影利率的预测准确度超过92.4%.
- *与现有最先进的方法相比,表现出35.7%的改善.
- * 在多类分类问题中验证了拟议的类型人气特征的有效性.
结论:
- *类型的流行,当通过时间序列分析预测和结合发行数据,显著提高电影利预测.
- * 拟议的方法为电影行业的早期投资决策提供了强有力的方法.
- * 机器学习模型,特别是渐变增强,从这些新的预测特性中获得了很大的好处.

相关概念视频
 00:54
Time-Series Graph
4.4K
A time-series graph is a line graph with repeated measurements taken at successive intervals of time. It is also called a time series chart. To construct a time-series graph, one must look at both pieces of a paired data set. The horizontal axis is used to plot the time increments, and the vertical axis is used to plot the values of the variable that one is measuring. By using the axes in this way, each point on the graph will correspond to time and a measured quantity. The points on the graph...
4.4K
 01:07
End Point Prediction: Gran Plot
332
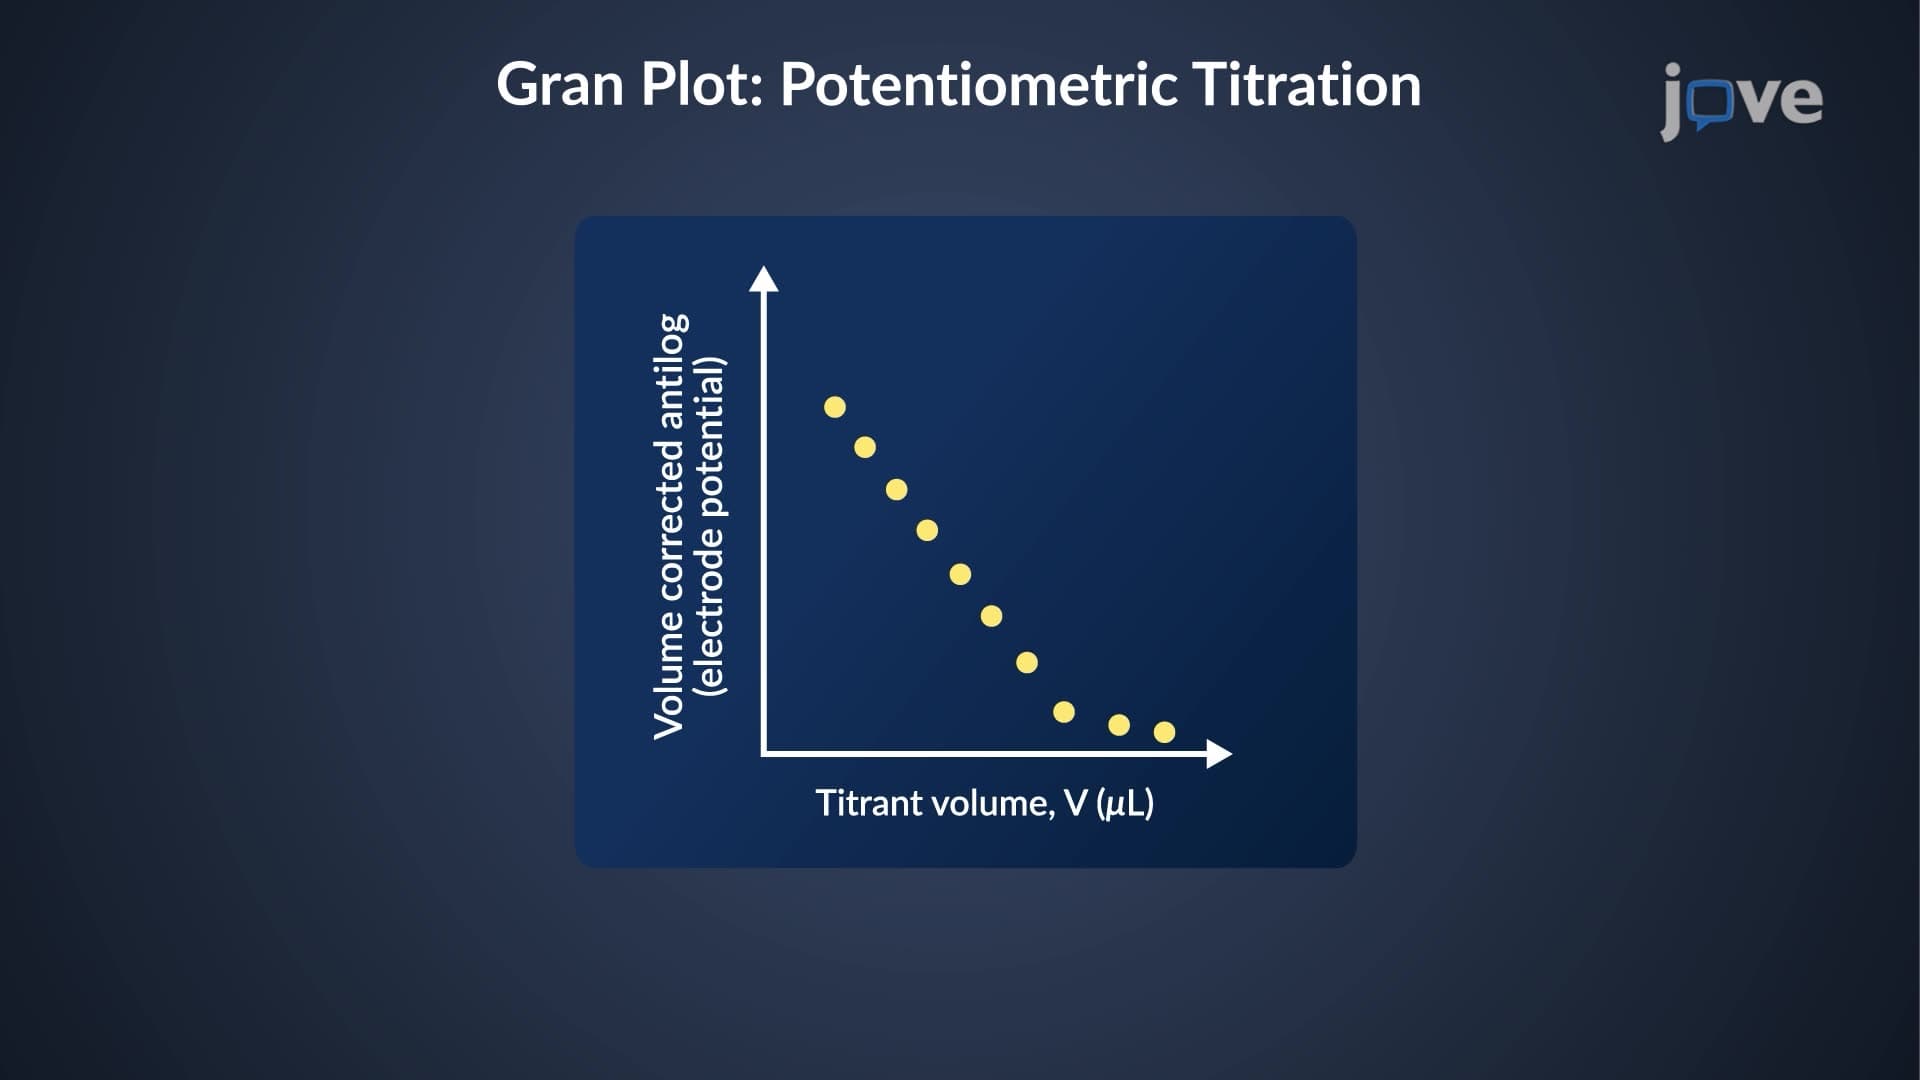
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
332
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 00:57
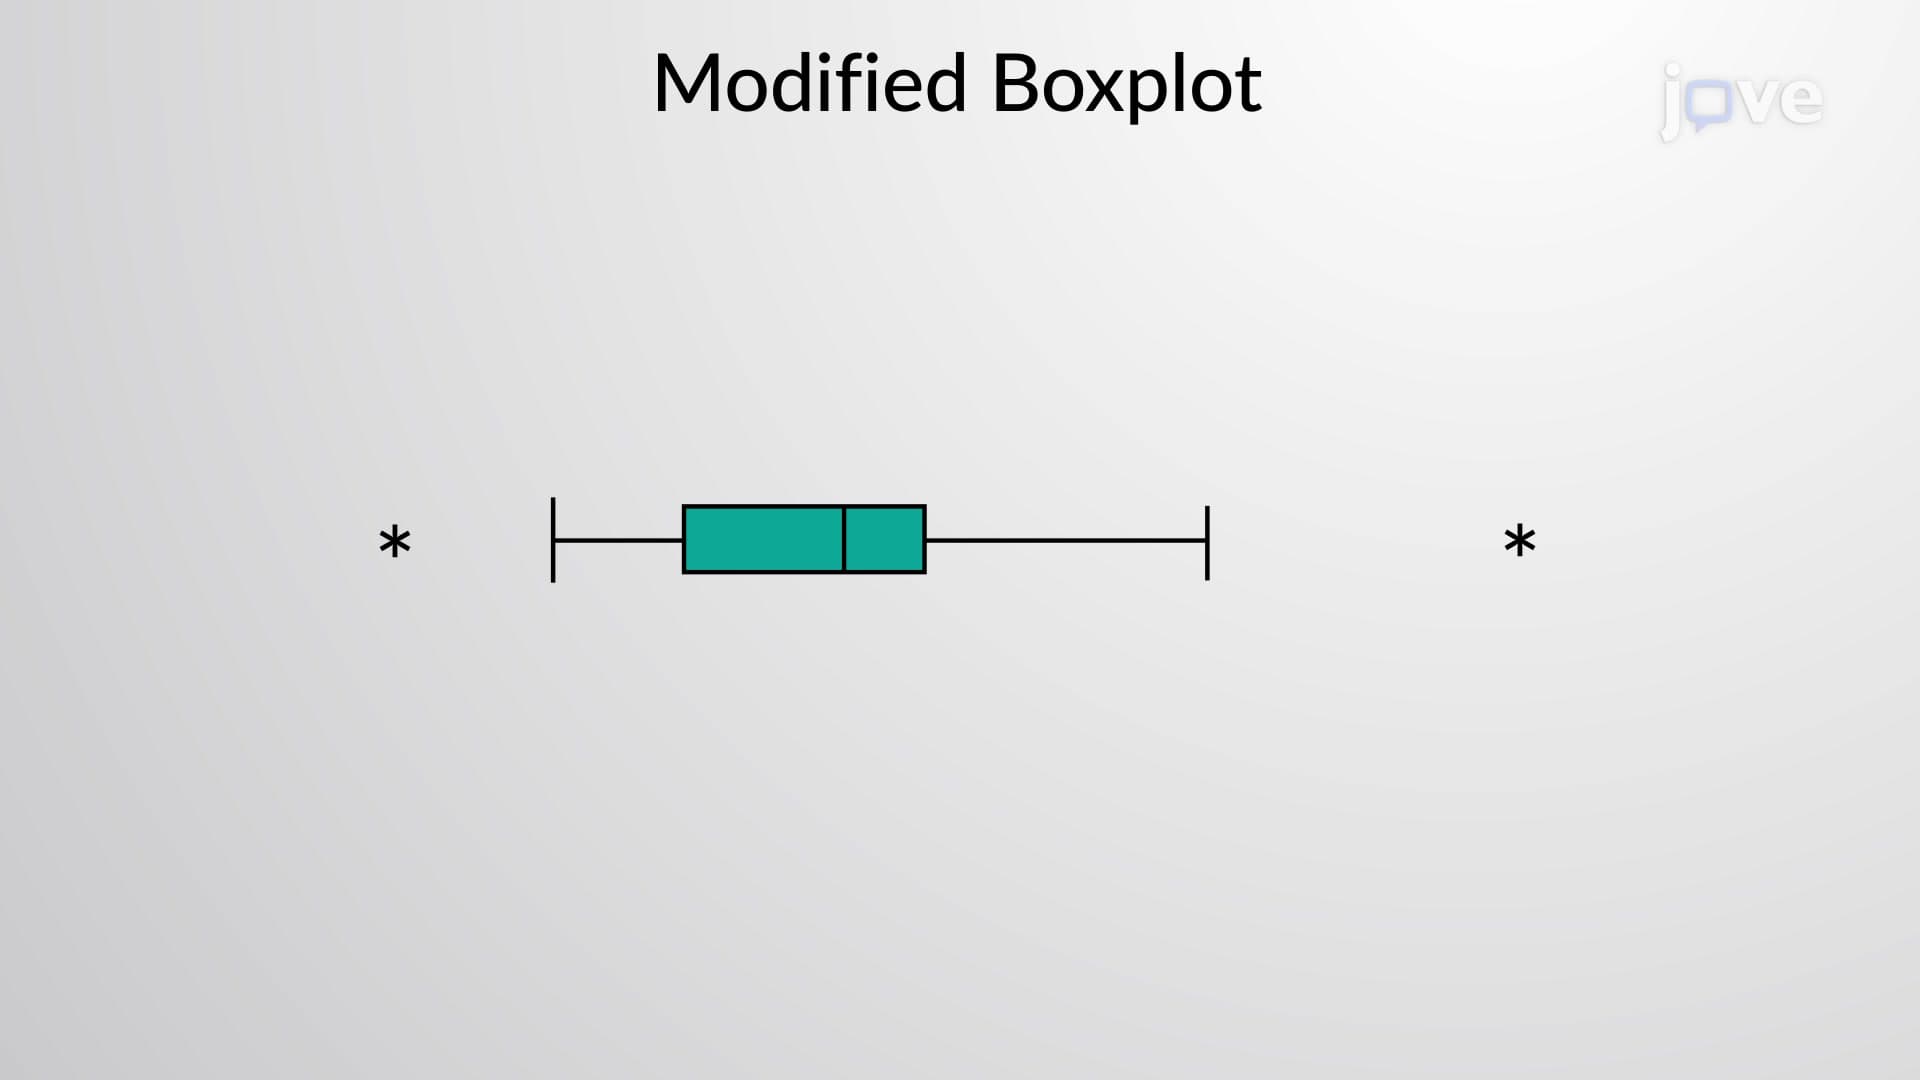
Modified Boxplots
9.7K
A standard box and whisker plot informs us about the spread of the data in a given sample. One can identify the minimum value, maximum value, first quartile value, second quartile or median value, and third quartile.
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
However, the box plot does not tell the reader about outliers - values that lie far from the center of the data. We can modify the standard box and whisker plot to identify the outliers and visualize the actual spread of the data in a sample.
Initially, we calculate the adjusted...
9.7K
 01:19
Expected Frequencies in Goodness-of-Fit Tests
2.5K
A goodness-of-fit test is conducted to determine whether the observed frequency values are statistically similar to the frequencies expected for the dataset. Suppose the expected frequencies for a dataset are equal such as when predicting the frequency of any number appearing when casting a die. In that case, the expected frequency is the ratio of the total number of observations (n) to the number of categories (k).
2.5K
 01:14
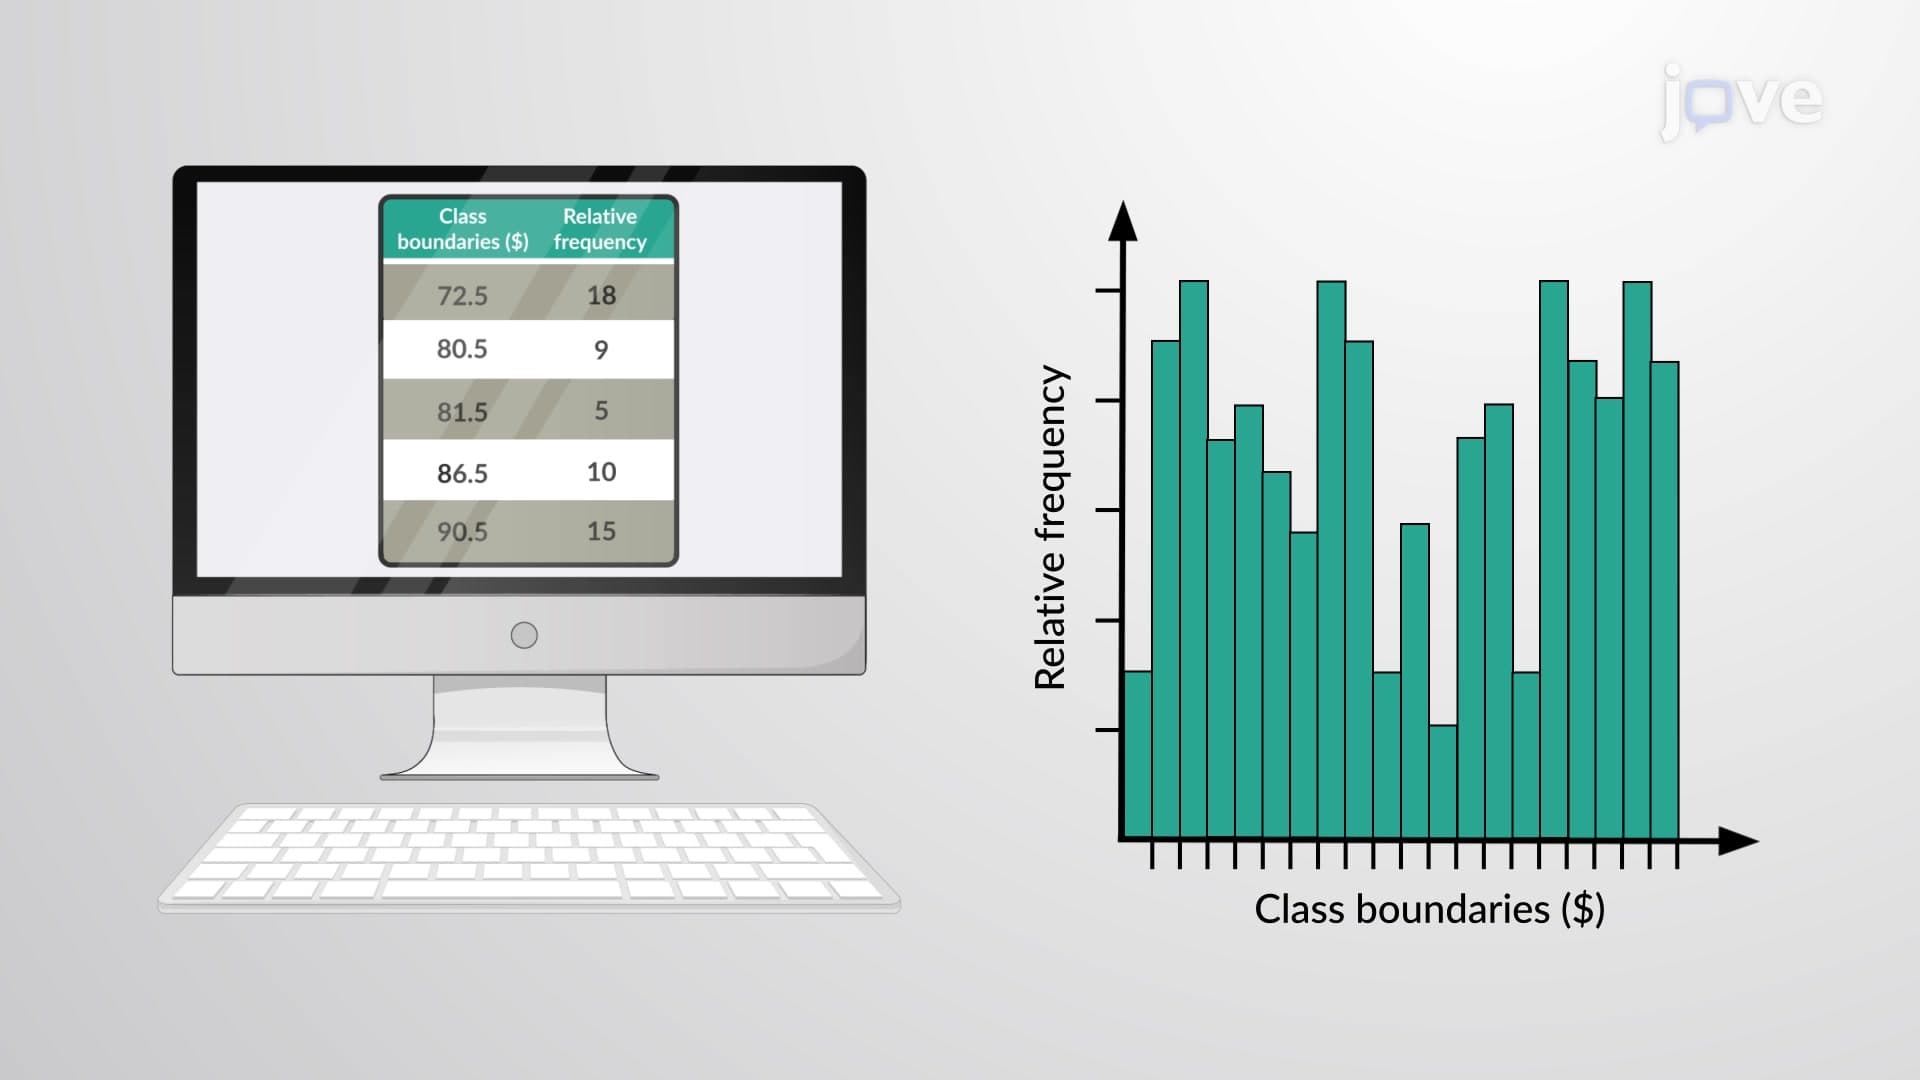
Relative Frequency Histogram
5.5K
The relative frequency depicts the proportion of data points that have each value. The frequency tells the number of data points that have each value. Like the histogram, a relative frequency histogram also has the same shape with a horizontal scale (the x-axis), but the vertical scale (the y-axis) is marked with relative frequencies (percentages of the whole) instead of actual frequencies. A relative frequency histogram is a graphical representation of a frequency distribution where the...
5.5K