相关实验视频
Updated: Jul 8, 2025
08:50

A Nonsequencing Approach for the Rapid Detection of RNA Editing
Published on: April 21, 2022
2.6K
从直接RNA测序中解开C-to-URNA编辑事件
Adriano Fonzino1, Caterina Manzari1, Paola Spadavecchia1
1Department of Biosciences, Biotechnology and Environment, University of Bari, Bari, Italy.
RNA biology
|December 13, 2023

概括
检测细胞因子到尿素RNA编辑具有挑战性. 使用隔离森林 (iForest) 的新机器学习方法有效地识别了这些罕见的C-to-U事件,在牛津纳米孔技术 (ONT) 中直接对RNA测序数据的准确度超过90%.
科学领域:
- 分子生物学分子生物学
- 基因组学就是基因组学.
- 生物信息学是一种生物信息学.
背景情况:
- RNA编辑,包括腺-氨酸 (A-to-I) 和细胞-氨酸 (C-to-U) 转换,在生物功能中起着至关重要的作用,其失调与人类疾病有关.
- 虽然A-to-I编辑很容易用Illumina RNAseq检测到,但C-to-U编辑的识别很难,因为它很罕见,并且难以与测序噪声区分.
- 使用牛津纳米孔技术 (ONT) 的直接RNA测序提供了直接C-to-U事件检测的潜力,但受到基调调用的系统错误的影响.
研究的目的:
- 从直接RNA测序数据中准确识别C-to-URNA编辑事件的挑战.
- 开发和验证一种新的计算策略,以提高C-to-U编辑站点的检测.
- 评估机器学习方法的性能,以消除ONT读数和改进RNA修饰识别.
主要方法:
- 使用隔离森林 (iForest) 算法开发了一种机器学习策略,以将C-to-U编辑事件视为异常.
- 该iForest模型是使用体外合成RNA和人类ONT直接RNA测序数据进行训练和测试的.
- 通过比较模型在各种数据集中检测C-to-U编辑站点的准确性来评估性能.
主要成果:
- 在ONT直接RNA测序读取中发现了细胞蛋白 (C) 基调用中的系统错误,导致错误的C到U编辑事件检测.
- 基于iForest的机器学习模型成功优化了ONT读取中的信号噪声比.
- 开发的方法在所有测试样本 (包括人类数据) 中识别C-to-U编辑站点时,获得了高精度,超过90%.
结论:
- 隔离森林 (iForest) 算法是一种强大而高效的工具,用于消除牛津纳米孔技术 (ONT) 的直接RNA测序读数.
- 这种新的机器学习策略显著提高了C-to-U RNA编辑站点识别的准确性和可靠性.
- 这些发现为准确检测RNA修饰,特别是C-to-U编辑事件提供了一个有希望的解决方案,使用直接RNA测序技术.
相关概念视频
 02:23
RNA Editing
9.0K
RNA editing is a post-transcriptional modification where a precursor mRNA (pre-mRNA) nucleotide sequence is changed by base insertion, deletion, or modification. The extent of RNA editing varies from a few hundred bases, in mitochondrial DNA of trypanosomes, to a just single base, in nuclear genes of mammals. Even a single base change in the pre-mRNA can convert a codon for one amino acid into the codon for another amino acid or a stop codon. This type of re-coding can significantly affect the...
9.0K
 03:21
RNA-seq
10.0K
RNA sequencing, or RNA-Seq, is a high-throughput sequencing technology used to study the transcriptome of a cell. Transcriptomics helps to interpret the functional elements of a genome and identify the molecular constituents of an organism. Additionally, it also helps in understanding the development of an organism and the occurrence of diseases.
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
10.0K
 01:32
RNA Splicing
56.4K
Splicing is the process by which eukaryotic RNA is edited before its translation into protein. The RNA strand transcribed from eukaryotic DNA is called the primary transcript. The primary transcripts that become mRNAs are called precursor messenger RNAs (pre-mRNAs). Eukaryotic pre-mRNA contains alternating sequences of exons and introns. Exons are nucleotide sequences that code for proteins, whereas introns are the non-coding regions. In RNA splicing, introns are removed and exons are bonded...
56.4K
 02:27
Nonsense-mediated mRNA Decay
10.6K
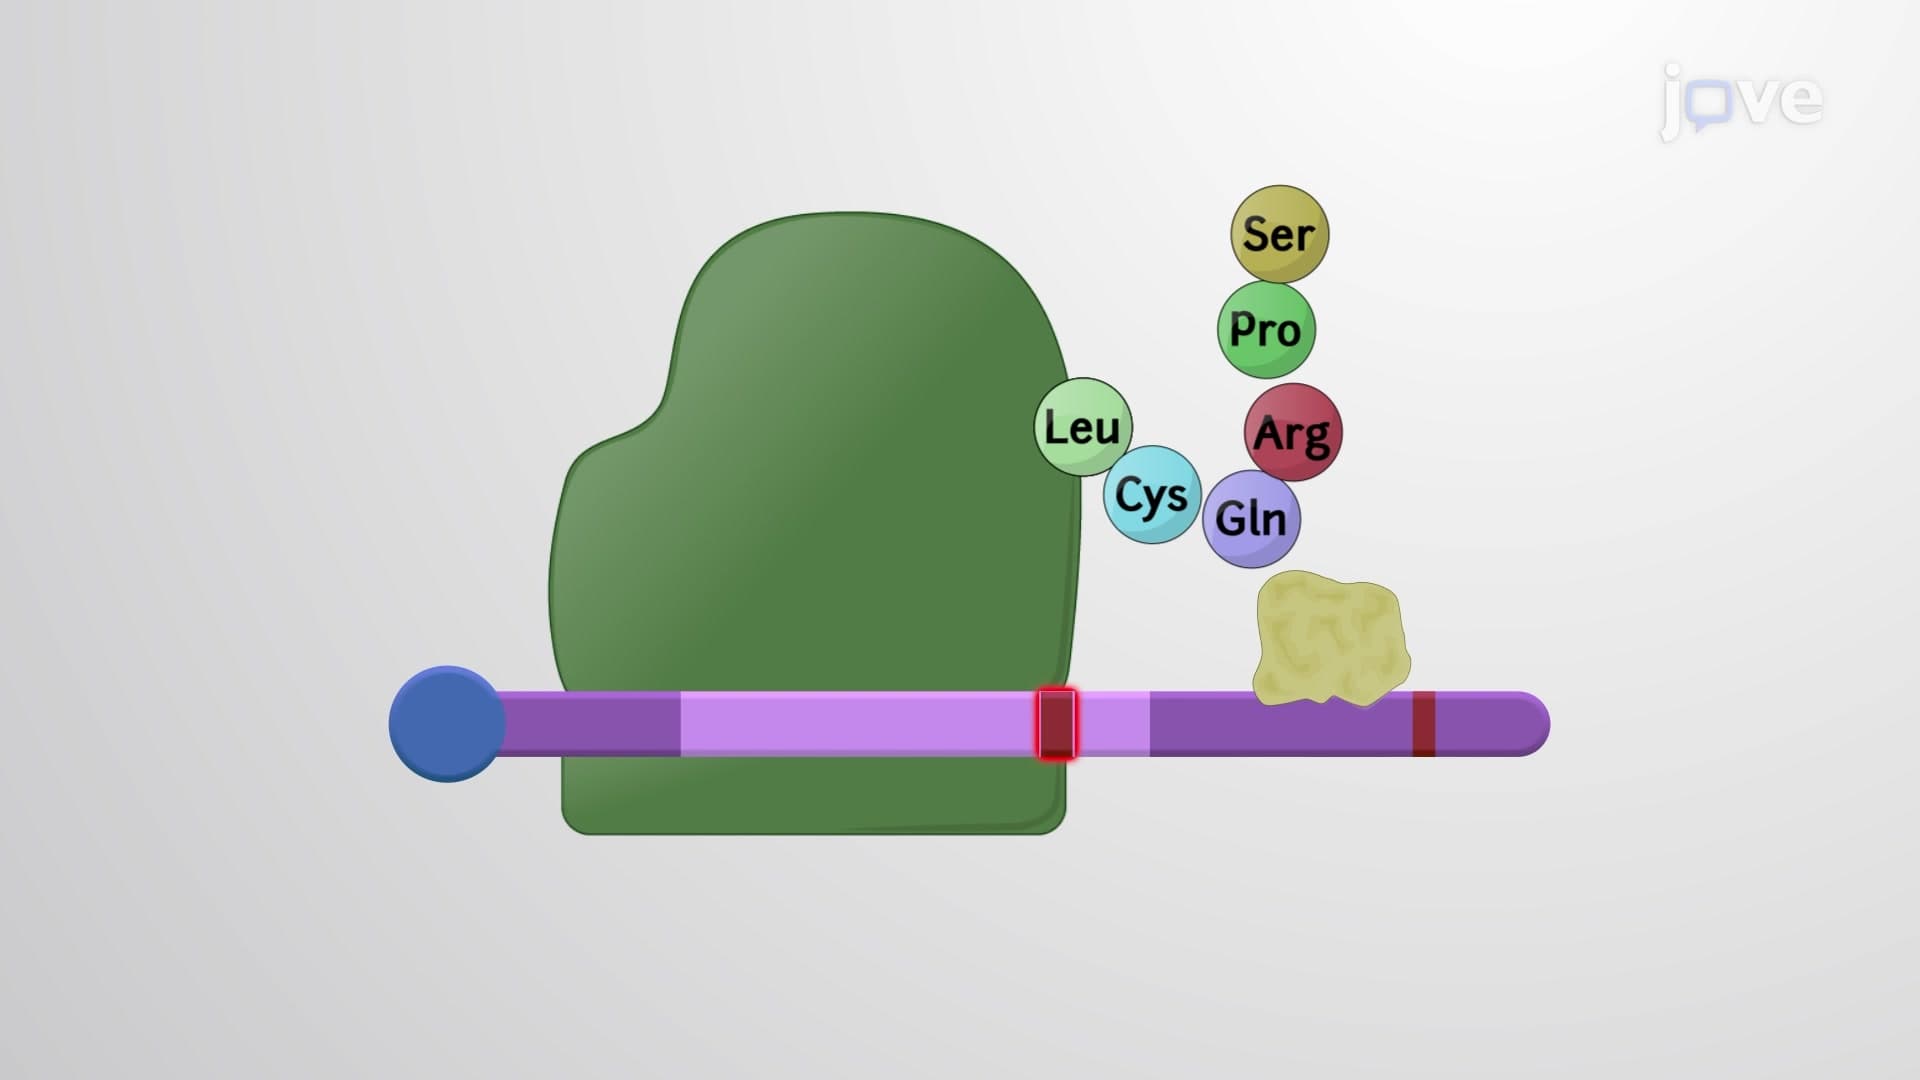
The Upf proteins that carry out nonsense-mediated decay (NMD) are found in all eukaryotic organisms, including humans. Each protein has an individual role, but they need to work in collaboration. Upf1 is an ATP-dependent RNA helicase that unwinds the RNA helix. Because Upf1 can unwind any RNA, Upf2 and Upf3 are required to help Upf1 discriminate between nonsense and normal mRNAs.
Usually, Upf3 binds to an Exon Junction Complex (EJC) at mRNA splice sites. If a ribosome fully translates the mRNA,...
Usually, Upf3 binds to an Exon Junction Complex (EJC) at mRNA splice sites. If a ribosome fully translates the mRNA,...
10.6K
 02:35
RACE - Rapid Amplification of cDNA Ends
6.4K
Rapid Amplification of cDNA Ends, or RACE, is one of the most effective methods to obtain a full-length cDNA from an mRNA sequence between a known internal region to the unknown sequence at the 5’ or 3’ end. The unknown region is cloned in the cDNA by a gene-specific primer that binds the known end, and a hybrid primer that attaches a predefined anchor sequence to the unknown end of the cDNA. The sequence in between is amplified by PCR with an anchor primer and a gene-specific...
6.4K
 01:20
Mismatch Repair
4.9K
Organisms are capable of detecting and fixing nucleotide mismatches that occur during DNA replication. This sophisticated process requires identifying the new strand and replacing the erroneous bases with correct nucleotides. Mismatch repair is coordinated by many proteins in both prokaryotes and eukaryotes.
The Mutator Protein Family Plays a Key Role in DNA Mismatch Repair
The human genome has more than 3 billion base pairs of DNA per cell. Prior to cell division, that vast amount of genetic...
The Mutator Protein Family Plays a Key Role in DNA Mismatch Repair
The human genome has more than 3 billion base pairs of DNA per cell. Prior to cell division, that vast amount of genetic...
4.9K