
推断的违约率作为保加利亚银行体系中的信用风险指标
1Faculty of Applied Informatics and Statistics, University of National and World Economy, 1700 Sofia, Bulgaria.
Entropy (Basel, Switzerland)
|December 23, 2023

概括
推断的违约率 (IRD) 是使用宏观经济因素预测银行违约风险的新指标. 这种方法为银行集团之间的信用风险比较提供了一个新的视角.
科学领域:
- 经济学 经济学 经济学
- 金融 金融 金融 金融 金融
- 风险管理 风险管理
背景情况:
- 推断的违约率 (IRD) 最初是作为违约风险指标开发的,使用来自保加利亚国家银行的数据.
- 现有的违约风险评估方法需要加强银行系统层面的分析.
研究的目的:
- 为预测银行集团和银行系统层面的IRD方法提供详细的理由.
- 通过时间序列分析提供支持IRD预测方法的经验证据.
- 为了证明IRD在比较不同银行集团的信用风险方面的实用性.
主要方法:
- 基于宏观经济因素的时间序列分析用于IRD预测.
- 模型估计与保加利亚法规和IFRS 9标准保持一致.
主要成果:
- 该研究提出了一种可靠的方法来预测推断的违约率 (IRD).
- 经验证据支持IRD预测模型的有效性.
- 在银行间集团信用风险比较中,IRD 证明是有价值的.
结论:
- 拟议的IRD预测模型符合当前的财务法规和会计准则.
- 实践者可以利用这些模型来预测每月的违约概率.
- 这些模型有助于有效监测和管理银行业内的信用风险.
相关概念视频
 01:11
Hazard Rate
112
The hazard rate, also known as the hazard function or failure rate, is a statistical measure used to describe the instantaneous rate at which an event occurs, given that the event has not yet happened. From a probabilistic perspective, it represents the likelihood that a subject will experience the event in a very small time interval, conditional on surviving up to the beginning of that interval. In terms of frequency, the hazard rate can be viewed as the ratio of the number of events to the...
112
 01:23
Types of Biopharmaceutical Studies: Controlled and Non-Controlled Approaches
130
Biopharmaceutical studies constitute a vital field aiming to enhance drug delivery methods and refine therapeutic approaches, drawing upon diverse interdisciplinary knowledge. In research methodologies, the choice between controlled and non-controlled studies significantly influences the study's reliability and accuracy.
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast,...
Non-controlled studies, commonly employed for initial exploration, lack a control group, rendering them susceptible to biases and external influences. In contrast,...
130
 01:19
Testing a Claim about Standard Deviation
2.5K
A complete procedure to test a claim about population standard deviation or population variance is explained here.
The hypothesis testing for the claim of population standard deviation (or variance) requires the data and samples to be random and unbiased. The population distribution also must be normal. There is no specific requirement on the sample size as the estimation is based on the chi-square distribution.
As a first step, the hypothesis (null and alternative) concerning the claim about...
2.5K
 01:13
Range Rule of Thumb to Interpret Standard Deviation
9.0K
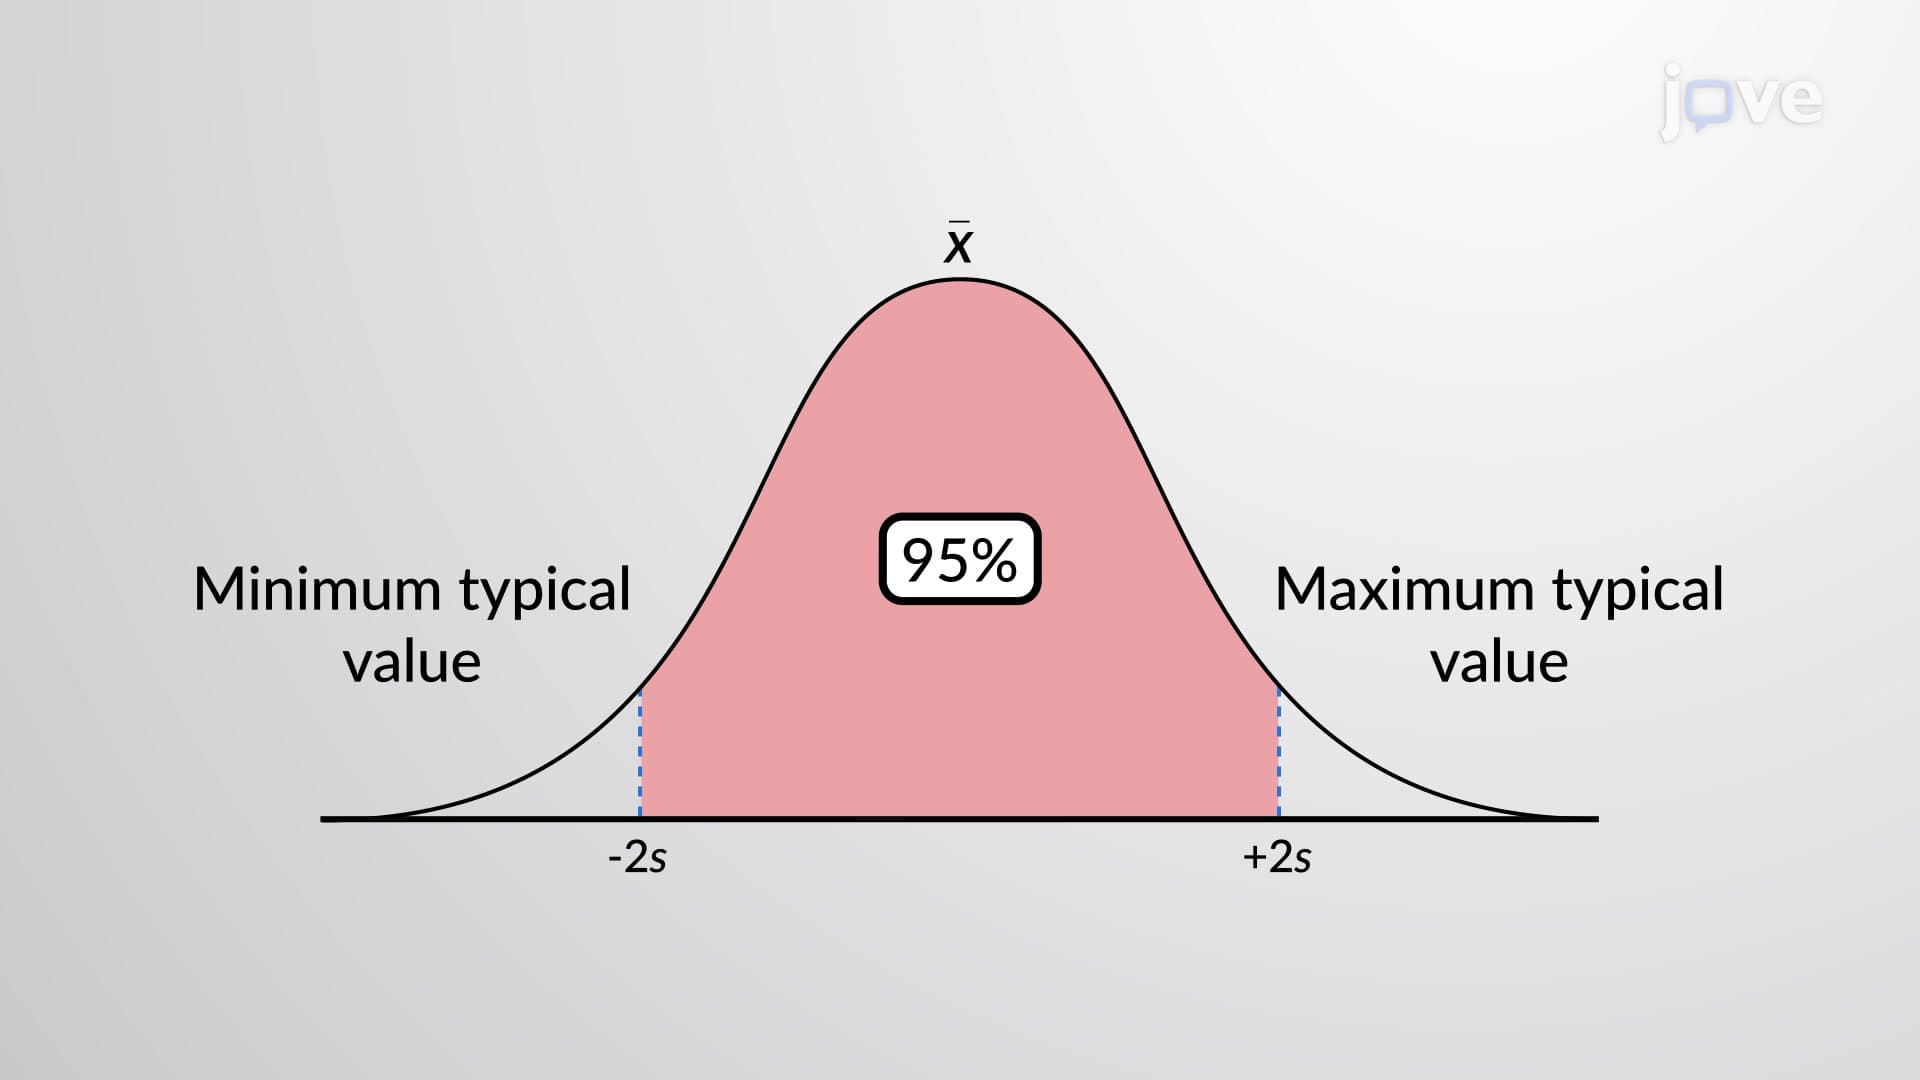
The range rule of thumb in statistics helps us calculate a dataset's minimum and maximum values with known standard deviation. This rule is based on the concept that 95% of all values in a dataset lie within two standard deviations from the mean.
For instance, the range rule of thumb can be used to find the tallest and the shortest student in a class, given the mean student height and standard deviation. If the mean student height is 1.6 m and the standard deviation, s is 0.05 m, the height...
For instance, the range rule of thumb can be used to find the tallest and the shortest student in a class, given the mean student height and standard deviation. If the mean student height is 1.6 m and the standard deviation, s is 0.05 m, the height...
9.0K
 01:09
Empirical Method to Interpret Standard Deviation
5.3K
The empirical rule, also known as the three-sigma rule, allows a statistician to interpret the standard deviation in a normally distributed dataset. The rule states that 68% of the data lies within one standard deviation from the mean, 95% lies within two standard deviations from the mean, and 99.7% lies within three standard deviations from the mean. Additionally, this rule is also called the 68-95-99.7 rule.
This rule is used widely in statistics to calculate the proportion of data values...
This rule is used widely in statistics to calculate the proportion of data values...
5.3K
 01:14
Standard Deviation of Calculated Results
6.2K
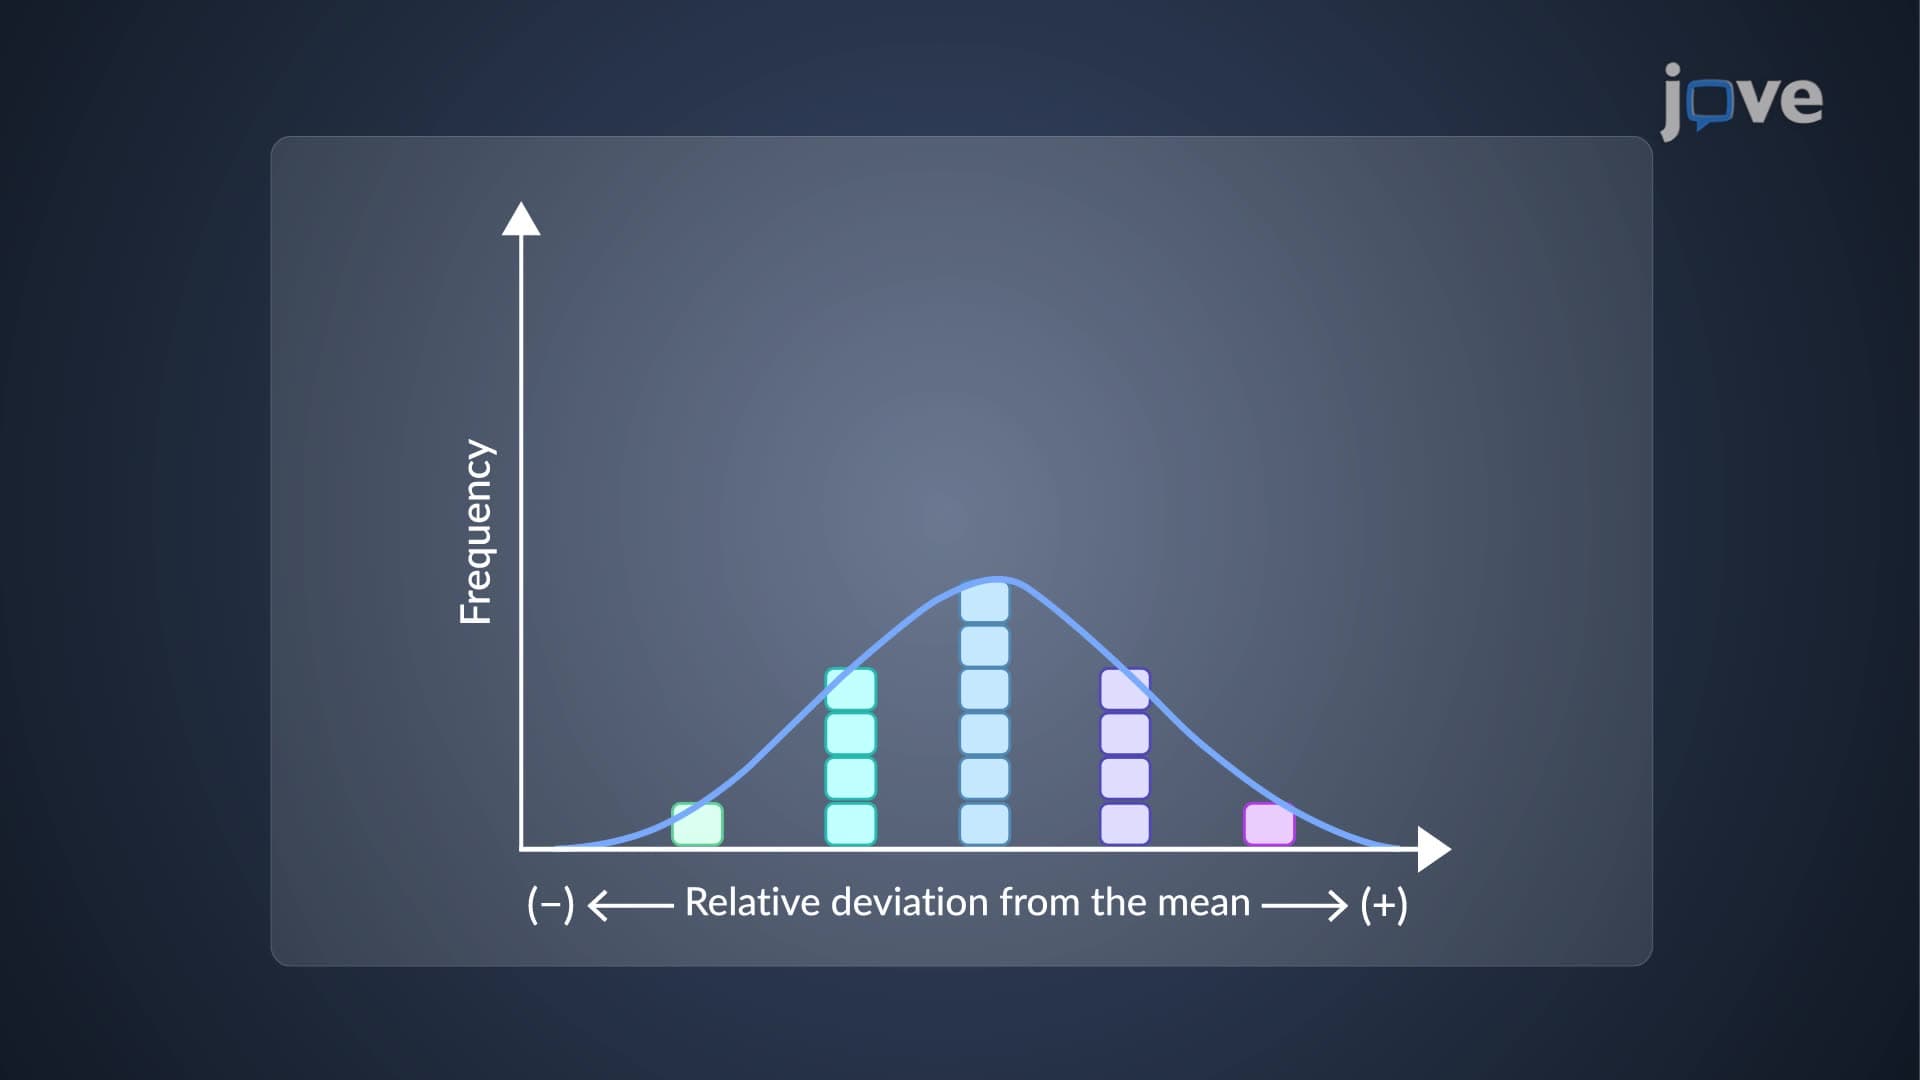
Standard deviation measures the spread of data around the mean value. Many large data sets follow a Gaussian distribution, also known as a normal distribution. This distribution is bell-shaped curved, with the most frequently observed value (mean or central value) in the middle. The farther away from the central value, the greater the deviation from the central value, and the lower the frequency.
A broad Gaussian distribution curve has a wider standard deviation, representing a data set with...
A broad Gaussian distribution curve has a wider standard deviation, representing a data set with...
6.2K