相关实验视频
Updated: Jul 7, 2025
09:05

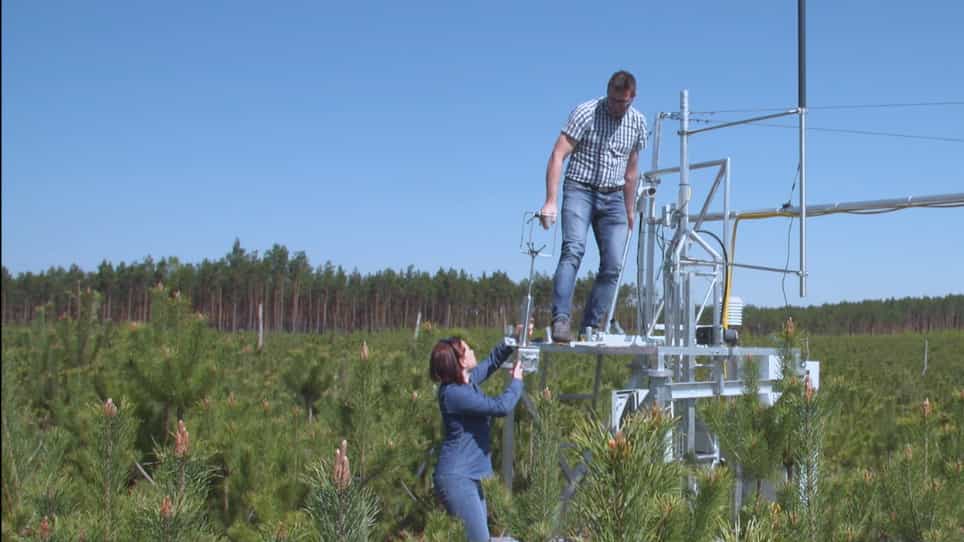
Measurements of CO2 Fluxes at Non-Ideal Eddy Covariance Sites
Published on: June 24, 2019
7.9K
欧洲国家生态足迹的决定因素:贝叶斯模型对面板数据分析的平均值的新见解
1Azerbaijan State Economic University, International Magistrate and Doctorate Center, Abbas Sahhat 45A, Nasimi, Baku AZ1007, Azerbaijan.
The Science of the total environment
|December 23, 2023

概括
这项研究表明,生物容量,能源消耗和预期寿命显著影响欧洲.
科学领域:
- 环境科学 环境科学
- 经济学 经济学 经济学
- 可持续性研究 可持续性研究
背景情况:
- 生态足迹分析对于了解环境压力至关重要.
- 确定以生产为基础的生态足迹的关键驱动因素对于可持续发展政策至关重要.
- 之前的研究并没有使用先进的统计方法充分探索多方面的决定因素.
研究的目的:
- 确定和量化欧洲国家生产生态足迹的决定因素.
- 分析生态足迹与其关键驱动因素之间的长期关系.
- 为可持续发展规划和政策干预提供基于证据的见解.
主要方法:
- 使用了部分和半部分相关性分析.
- 贝叶斯模型平均 (BMA) 用于通过后置包含概率 (PIP) 来评估变量重要性.
- 协同整合测试和权重聚合DOLS估计被用于检查长期关系.
主要成果:
- 生物容量,能源消耗和预期寿命被确定为生态足迹的重要驱动因素.
- 工业化,金融发展和全球化等变量显示出相对较小的影响.
- 在欧洲各个小组中,在生态足迹和解释变量之间发现了显著的共同整合.
结论:
- 该研究强调了生物容量,能源消耗和预期寿命在塑造生态足迹方面的关键作用.
- 调查结果为旨在加强欧洲可持续发展战略的政策制定者提供了宝贵的见解.
- 有效的政策干预需要对经济,社会和环境因素之间的相互作用有细微的了解.

相关概念视频
 01:25
Statistical Methods for Analyzing Epidemiological Data
371
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
371
 01:23
Mechanistic Models: Compartment Models in Individual and Population Analysis
43
Mechanistic models are utilized in individual analysis using single-source data, but imperfections arise due to data collection errors, preventing perfect prediction of observed data. The mathematical equation involves known values (Xi), observed concentrations (Ci), measurement errors (εi), model parameters (ϕj), and the related function (ƒi) for i number of values. Different least-squares metrics quantify differences between predicted and observed values. The ordinary least...
43
 01:11
Variability: Analysis
143
Measures of variability are statistical metrics that reveal the dispersion pattern within a dataset. They are pivotal in biostatistics, providing insights into the heterogeneity within health and biological data. Variability signifies the degree to which data points diverge from one another, helping researchers understand the potential range of values and associated uncertainty within the data.
The range is a simple measure of variability, indicating the difference between the highest and...
The range is a simple measure of variability, indicating the difference between the highest and...
143
 01:29
Econometric Views (EViews)
145
Econometric Views, often stylized as EViews, is a package that merges statistical analysis with econometric studies. It is designed to provide tools for time series analysis, forecasting, and econometric model simulation. The software originated from MicroTSP software and has evolved significantly since its inception in 1981. The history of EViews is marked by a continuous effort to enhance its computational speed and user interface. It was initially developed for large computing systems but...
145
 01:11
Regression Analysis
5.7K
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:26
Distributions to Estimate Population Parameter
4.1K
The accurate values of population parameters such as population proportion, population mean, and population standard deviation (or variance) are usually unknown. These are fixed values that can only be estimated from the data collected from the samples. The estimates of each of these parameters are sample proportion, the sample mean, and sample standard deviation (or variance). To obtain the values of these sample statistics, data are required that have particular distribution and central...
4.1K