在拓数据分析中的依赖网络的统计推理
Anass B El-Yaagoubi1, Moo K Chung2, Hernando Ombao1
1Statistics Program, King Abdullah University of Science and Technology, Thuwal, Saudi Arabia.
Frontiers in artificial intelligence
|December 29, 2023

概括
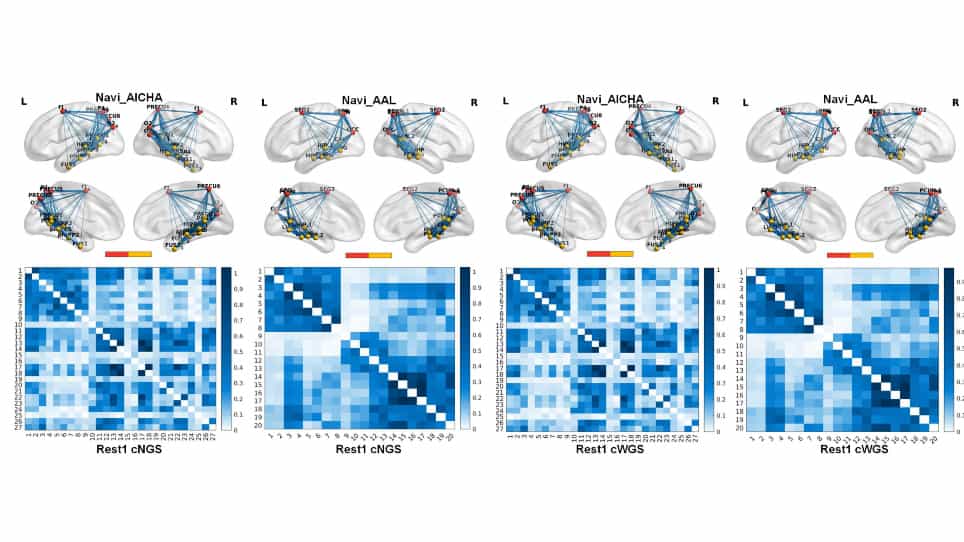
研究人员开发了一种用于多变量时间序列的新模拟方法,使复杂的大脑网络模式的分析成为可能. 这为研究神经疾病的拓数据分析 (TDA) 带来了进步.
科学领域:
- 计算神经科学是一种计算神经科学.
- 应用数学 应用数学 应用数学
- 统计推断的统计推断.
背景情况:
- 拓数据分析 (TDA) 越来越多地用于多变量时间序列.
- 分析大脑网络中的依赖模式对于理解认知过程和神经障碍至关重要.
- 测试新的TDA方法是具有挑战性的,因为在真实大脑信号中缺乏基准真相数据.
研究的目的:
- 开发新的统计推理程序来分析多变量时间序列数据.
- 创建一个模拟方法来生成具有用户指定的连接模式的多变量时间序列.
- 为了能够在神经科学应用中对TDA方法进行可靠的评估.
主要方法:
- 开发一种新的方法来模拟多变量时间序列数据.
- 在它们的依赖网络中生成特定数量的循环/洞的时间序列.
- 产生更高维的拓特征的程序.
主要成果:
- 已经建立了一种模拟复杂,用户定义的依赖结构的多变量时间序列的新方法.
- 模拟方法允许创建具有受控拓特征的合成数据.
- 这便于对TDA方法的假设测试和性能评估.
结论:
- 开发的模拟方法解决了评估多变量时间序列分析的TDA技术的关键差距.
- 这种方法为推进计算神经科学研究和理解大脑网络动态提供了有价值的工具.
- 它允许对TDA方法进行更严格的测试和开发,用于神经和认知障碍研究中的应用.
相关概念视频
 01:16
Statistical Inference Techniques in Hypothesis Testing: Parametric Versus Nonparametric Data
130
Statistical inference techniques, paramount in hypothesis testing, differentiate into two broad categories: parametric and nonparametric statistics.
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
Parametric statistics, as the name suggests, assumes that data follow a specific distribution, often a normal distribution. This assumption enables robust hypothesis testing and estimation. Parametric methods, like the Student's t-test or Goodness-of-fit test, are frequently employed in biostatistics due to their robustness. For instance,...
130
 01:21
Introduction to Test of Independence
2.3K
In statistics, the term independence means that one can directly obtain the probability of any event involving both variables by multiplying their individual probabilities. Tests of independence are chi-square tests involving the use of a contingency table of observed (data) values.
The test statistic for a test of independence is similar to that of a goodness-of-fit test:
The test statistic for a test of independence is similar to that of a goodness-of-fit test:
2.3K
 01:16
Hypothesis Test for Test of Independence
3.6K
The test of independence is a chi-square-based test used to determine whether two variables or factors are independent or dependent. This hypothesis test is used to examine the independence of the variables. One can construct two qualitative survey questions or experiments based on the variables in a contingency table. The goal is to see if the two variables are unrelated (independent) or related (dependent). The null and alternative hypotheses for this test are:
H0: The two variables (factors)...
H0: The two variables (factors)...
3.6K
 02:26
Protein Networks
4.0K
An organism can have thousands of different proteins, and these proteins must cooperate to ensure the health of an organism. Proteins bind to other proteins and form complexes to carry out their functions. Many proteins interact with multiple other proteins creating a complex network of protein interactions.
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
These interactions can be represented through maps depicting protein-protein interaction networks, represented as nodes and edges. Nodes are circles that are representative of a protein,...
4.0K
 01:25
Statistical Methods for Analyzing Epidemiological Data
369
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
369
 01:21
Friedman Two-way Analysis of Variance by Ranks
199
Friedman's Two-Way Analysis of Variance by Ranks is a nonparametric test designed to identify differences across multiple test attempts when traditional assumptions of normality and equal variances do not apply. Unlike conventional ANOVA, which requires normally distributed data with equal variances, Friedman's test is ideal for ordinal or non-normally distributed data, making it particularly useful for analyzing dependent samples, such as matched subjects over time or repeated measures...
199