来自COVID-19趋势和影响调查调查的县级疫苗接种范围的偏差调整预测
Marissa B Reitsma1, Sherri Rose1, Alex Reinhart2,3
1Department of Health Policy, Stanford University, Stanford, CA, USA.

概括
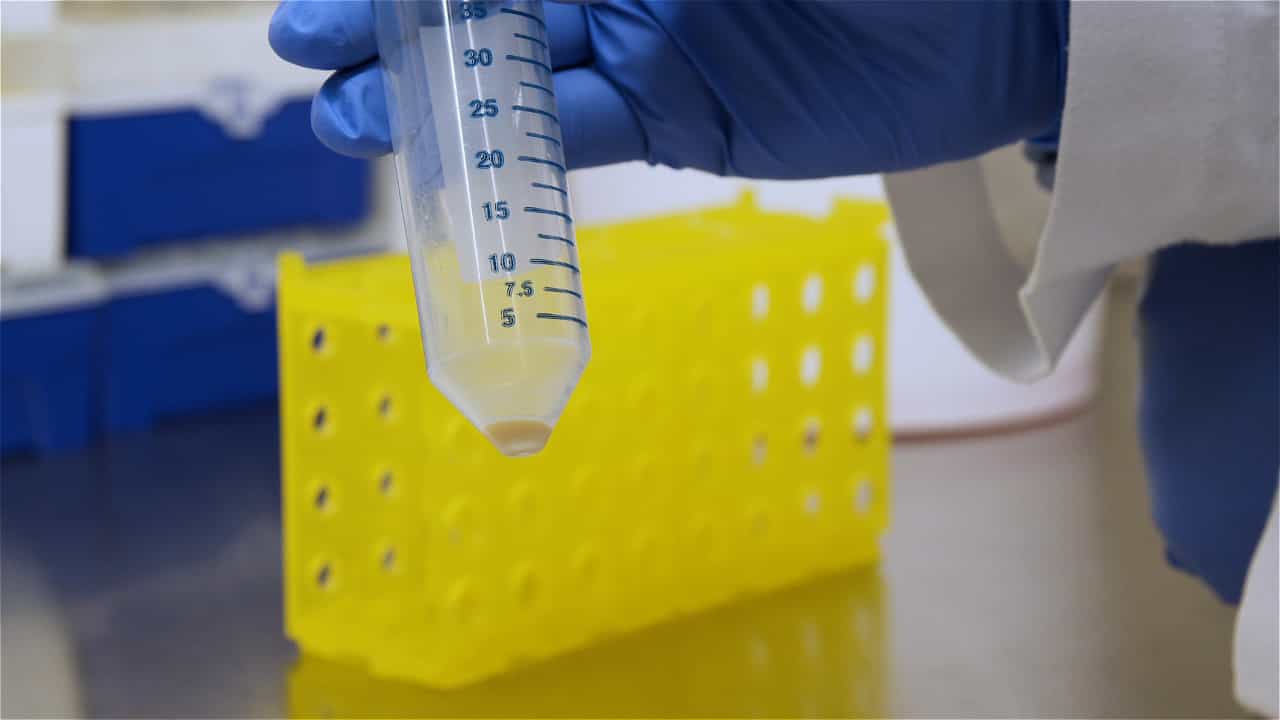
来自大型调查的偏差调整的COVID-19疫苗接种预测改善了公共卫生洞察力. 该方法解决了非代表性数据的选择偏差,为决策提供了关键的地理和公平信息.
科学领域:
- 公共卫生 公共卫生
- 流行病学 流行病学
- 生物统计学 生物统计学
背景情况:
- 大规模,低成本的调查往往缺乏代表性,这可能会限制它们在人口健康测量中的使用.
- 非代表性数据的选择偏差引发了人们对公共卫生决策准确性的担忧.
- 美国COVID-19趋势和影响调查 (US COVID-19 Trends and Impact Survey) 举例说明,大型数据集优先考虑及时性和大小,而不是代表性.
研究的目的:
- 为县级的COVID-19疫苗接种覆盖率预测开发和应用一个偏差调整方法.
- 从美国COVID-19趋势和影响调查中得出的预测中解决选择偏差.
- 为县级和国家级的公共卫生决策产生可靠的估计.
主要方法:
- 开发了一个多步回归框架,以调整选择偏差.
- 该方法包括对美国社区调查数据的后分层化和共变量调整.
- 进行了对无偏见的参考指标的二次规范化,并对儿童疫苗接种覆盖率进行了前性应用.
主要成果:
- 预测的长期全国接种疫苗覆盖率估计为46%,具有显著的地理差异 (11%91%跨县).
- 在紧急使用授权后的3个月内,在5至11岁儿童的疫苗接种扩大速度中发现了实质性的差异.
- 该方法突出了疫苗接种中的不平等现象,并提供了县级的见解.
结论:
- 开发的方法有效地利用多个数据源来产生及时和地理相关的估计.
- 偏差调整对于在公共卫生中使用大量非代表性调查数据至关重要.
- 结合多种数据源的综合健康测量系统可以优化相对于成本的数据收集效益.
更多相关视频
相关概念视频
 01:29
Bias in Epidemiological Studies
280
Biases can arise at various stages of research, from study design and data collection to analysis and interpretation. Recognizing and addressing these biases is essential to ensure the validity and reliability of epidemiological findings.Broadly speaking, biases in epidemiology fall into three main categories: selection bias, information bias, and confounding. A more detailed description of possible biases is:
280
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:29
Contingency Table
2.5K
A contingency table provides a way of portraying data that can facilitate calculating probabilities. It is a method of displaying a frequency distribution as a table with rows and columns to show how two variables may be dependent (contingent) upon each other; The table helps determine conditional probabilities quite quickly and can help systematically organize, analyze and quantify data. The table displays sample values concerning two variables that may be dependent or contingent on one...
2.5K
 01:09
Types of Skewness
11.6K
If the frequency distribution of a data set is more inclined towards smaller or larger values, the distribution is said to be skewed. If data values are skewed to the right, then the distribution is called positively skewed. Conversely, if the plot is skewed to the left, the distribution is called negatively skewed.
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
For instance, in the middle of a pandemic, the geographical distribution of vaccine coverage may be positively skewed towards populations in the global north countries. However,...
11.6K
 01:25
Statistical Methods for Analyzing Epidemiological Data
369
Epidemiological data primarily involves information on specific populations' occurrence, distribution, and determinants of health and diseases. This data is crucial for understanding disease patterns and impacts, aiding public health decision-making and disease prevention strategies. The analysis of epidemiological data employs various statistical methods to interpret health-related data effectively. Here are some commonly used methods:
369
 01:25
Confidence Interval for Estimating Population Mean
7.3K
A point estimate of the population mean is obtained from a single sample. Such a point estimate does not represent a population well because it needs to account for variability in the population. Single point estimate can also be biased despite the sample being selected randomly. Thus, a point estimate is often unreliable. A confidence interval is needed to reduce this unreliability.
A confidence interval for the mean is a range of values that provides an estimate of the population mean. As the...
A confidence interval for the mean is a range of values that provides an estimate of the population mean. As the...
7.3K