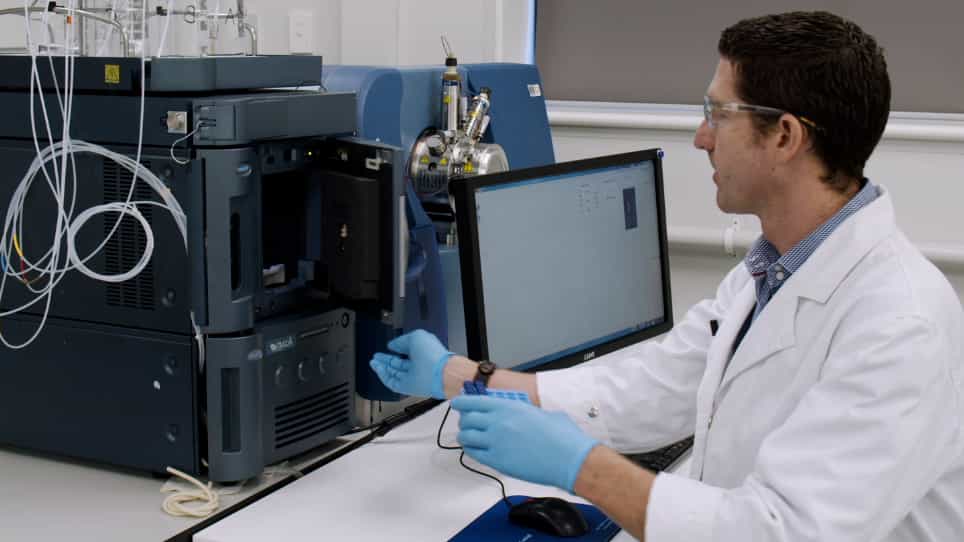

变化系数方法与XGboost组合模型相结合,用于小麦生长监测
Xinyan Li1, Changchun Li1, Fuchen Guo1
1School of Surveying and Land Information Engineering, Henan Polytechnic University, Jiaozuo, China.
Frontiers in plant science
|January 18, 2024

概括
这项研究开发了一种使用无人机光谱数据和综合增长监测指标 (CGMI) 的小麦生长监测系统. 该系统准确地估计了小麦的生长,提高了精准农业实践.
科学领域:
- 农业科学 农业科学
- 遥感 遥感 遥感 遥感
- 数据科学数据科学数据科学
背景情况:
- 准确的小麦生长监测对于产量估计和农业发展至关重要.
- 精准农业依赖于有效的数据采集,用于作物管理.
研究的目的:
- 开发一种准确和有效的方法来监测小麦生长,使用基于无人机的光谱数据.
- 构建一个全面的增长监测指标 (CGMI) 以改进小麦增长的评估.
主要方法:
- 收集的小麦生物质,,叶绿素和叶面积指数数据.
- 使用变化系数方法构建的CGMI.
- 在无人机光谱数据上应用分数导数处理.
- 利用灰色相关性分析来确定最佳的光谱频段.
- 开发和评估使用随机森林,回归和XGBoost.使用小麦生长逆转模型.
主要成果:
- CGMI与光谱数据的相关性增加,增长率达到82.22%.
- 差分光谱处理增强了光谱相关性,在开花阶段的系数达到0.92.
- 在小麦生长监测中,XGBoost模型显示了最高的反转精度 (R2 0.904训练,0.870测试).
结论:
- 将CGMI与差分光谱处理相结合,显著提高了小麦生长监测的准确性.
- XGBoost模型是精确反转小麦生长的有效工具.
- 这种方法为精准农业管理提供了新的方法.

相关概念视频
 01:25
Multiple Regression
3.0K
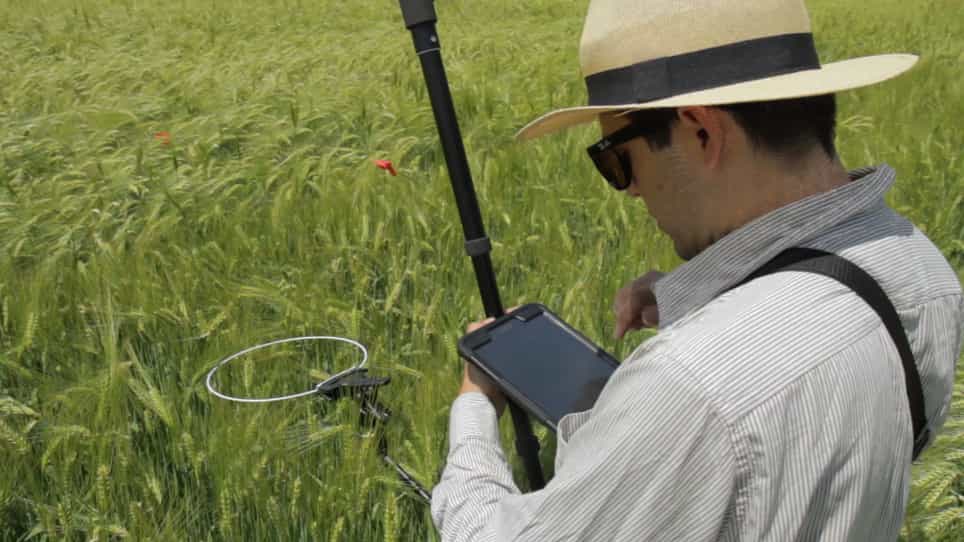
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:10
Coefficient of Variation
3.8K
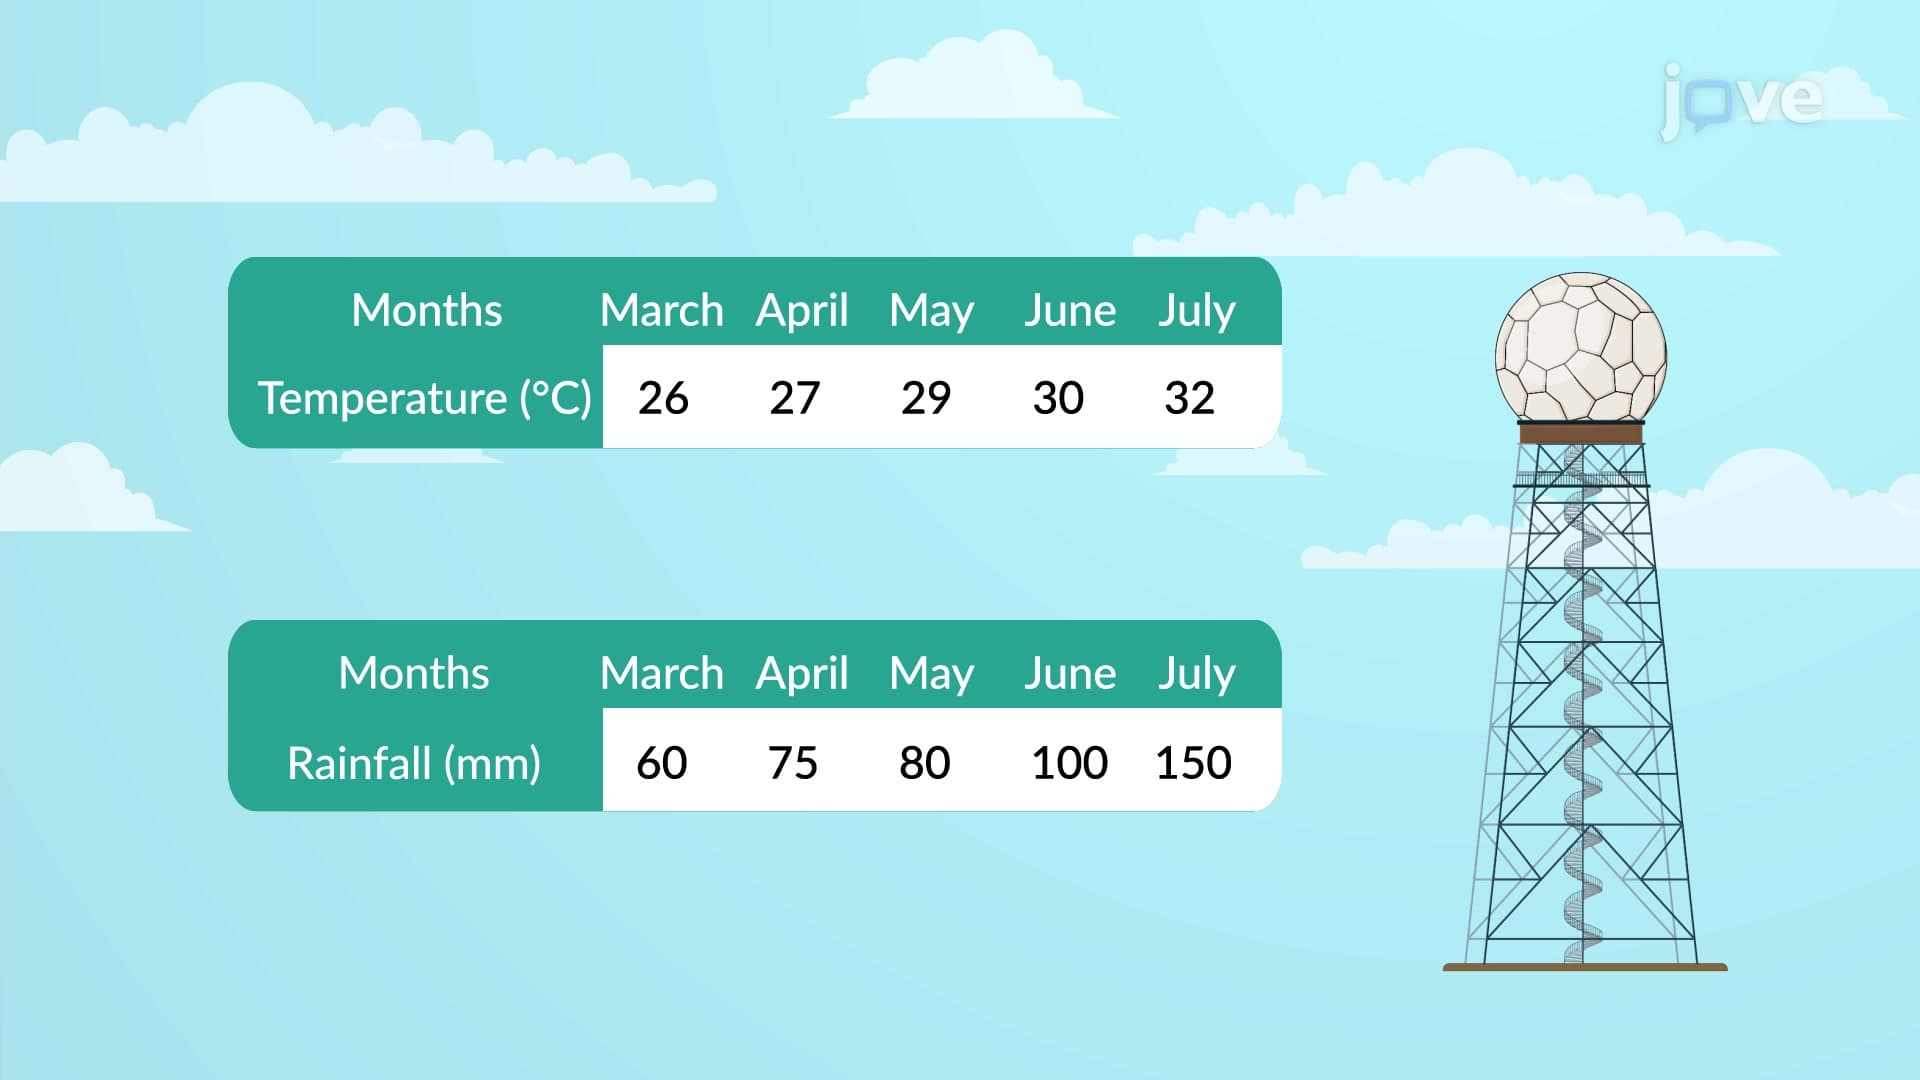
The coefficient of variation measures the dispersion of the data points or distribution around the mean. Using the coefficient of variation, we can compare two data series with drastically different means or different units of measurement. The coefficient of variation for a sample and a population is expressed as a percentage of the ratio of standard deviation to the mean.
The coefficient of variation is a practical statistical tool in finance. It allows investors to assess the volatility or...
The coefficient of variation is a practical statistical tool in finance. It allows investors to assess the volatility or...
3.8K
 01:19
Variation
6.8K
An important characteristic of any set of data is the variation in the data. In some data sets, the data values are concentrated closely near the mean; in other data sets, the data values are more widely spread out from the mean. The most common measure of variation, or spread, is the standard deviation, which is the square root of variance.
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
When independent and dependent variables are plotted on a scatter plot, the slope of a line is a value that describes the rate of change between the two...
6.8K
 01:26
Estimating Population Standard Deviation
3.0K
When the population standard deviation is unknown and the sample size is large, the sample standard deviation s is commonly used as a point estimate of σ. However, it can sometimes under or overestimate the population standard deviation. To overcome this drawback, confidence intervals are determined to estimate population parameters and eliminate any calculation bias accurately. However, this only applies to random samples from normally distributed populations. Knowing the sample mean and...
3.0K
 01:11
Regression Analysis
5.7K
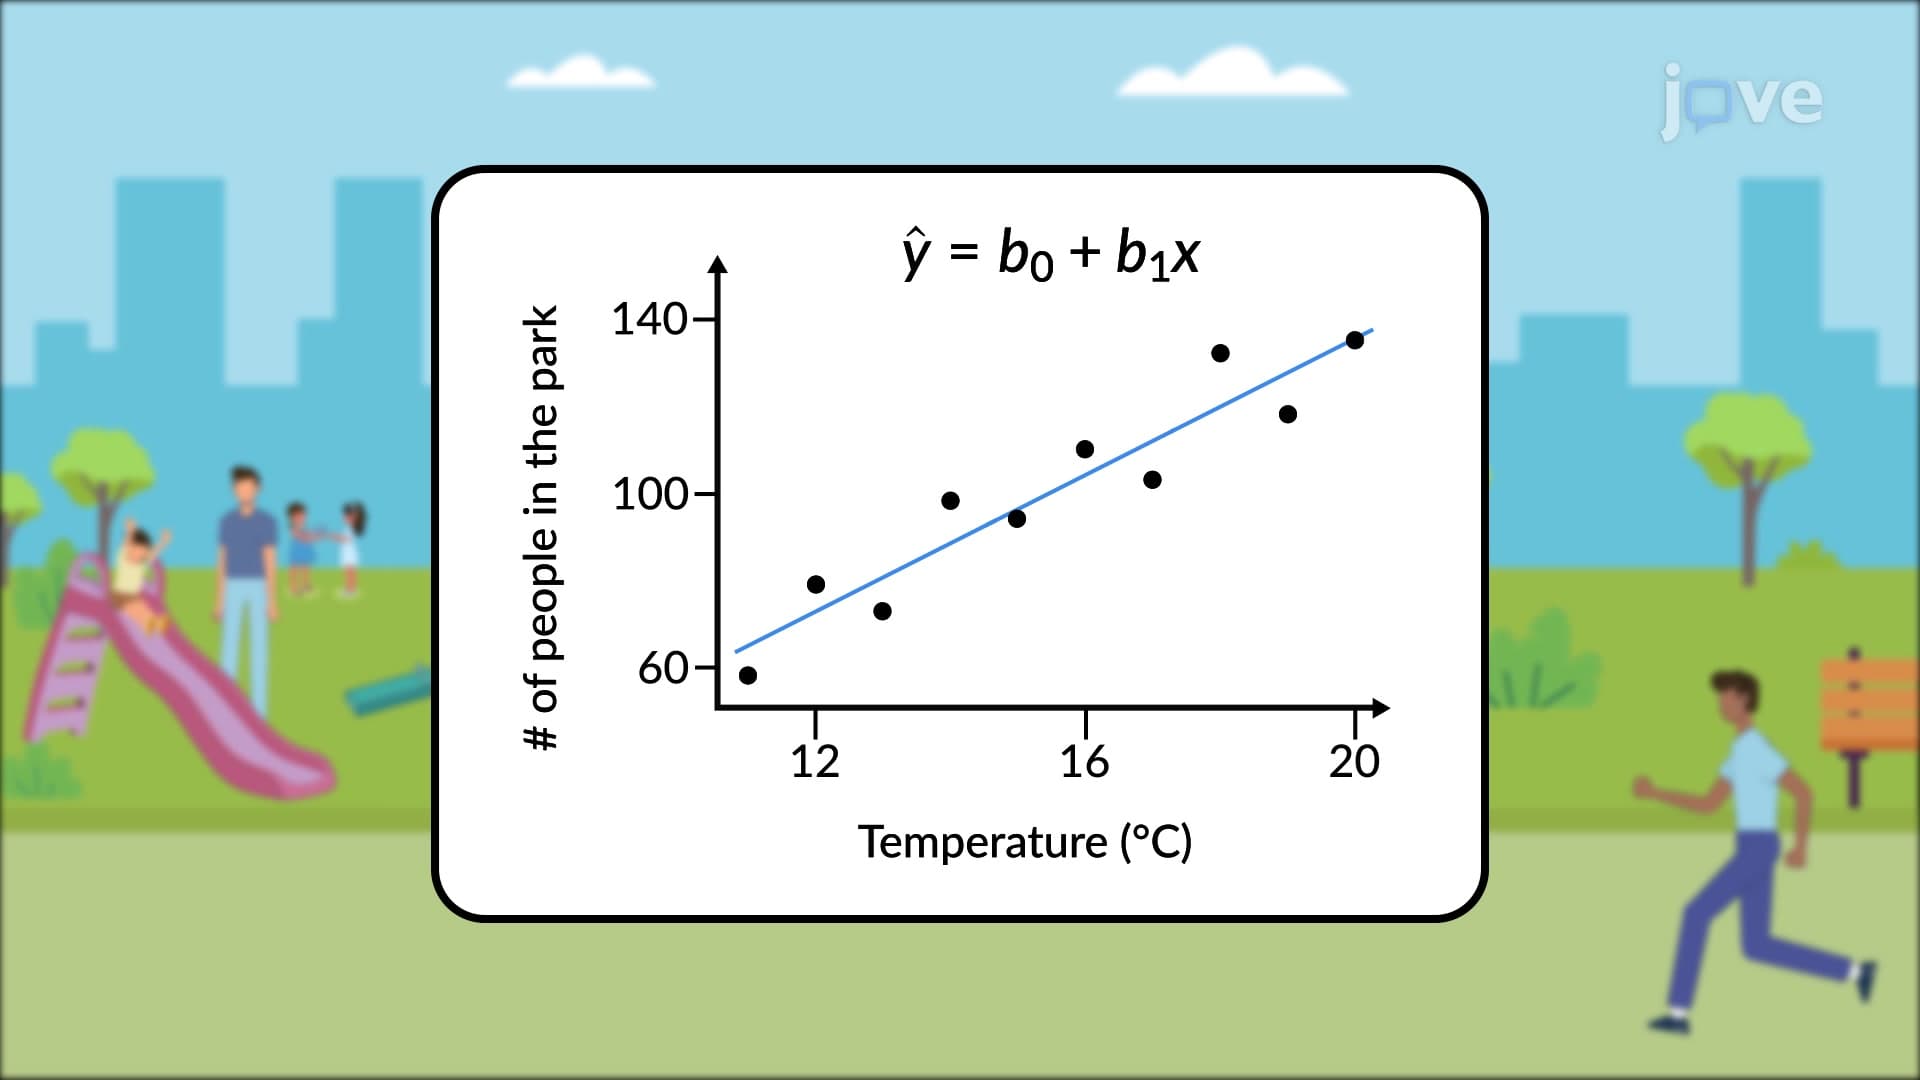
Regression analysis is a statistical tool that describes a mathematical relationship between a dependent variable and one or more independent variables.
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
In regression analysis, a regression equation is determined based on the line of best fit– a line that best fits the data points plotted in a graph. This line is also called the regression line. The algebraic equation for the regression line is called the regression equation. It is represented as:
5.7K
 01:22
Estimating Population Mean with Unknown Standard Deviation
7.7K
In practice, we rarely know the population standard deviation. In the past, when the sample size was large, this did not present a problem to statisticians. They used the sample standard deviation s as an estimate for σ and proceeded as before to calculate a confidence interval with close enough results. However, statisticians ran into problems when the sample size was small. A small sample size caused inaccuracies in the confidence interval.
William S. Gosset (1876–1937) of the...
William S. Gosset (1876–1937) of the...
7.7K