
使用GRAPHDeep组装空间聚类框架,用于使用异质空间转录组学数据
Teng Liu1,2, Zhaoyu Fang3, Xin Li1,2
1Department of Clinical Research Center (CRC), Clinical Pathology Center (CPC), Cancer Early Detection and Treatment Center (CEDTC) and Translational Medicine Research Center (TMRC), Chongqing University Three Gorges Hospital, Chongqing University, Wanzhou, Chongqing, 404000, China.
Bioinformatics (Oxford, England)
|January 20, 2024

概括
通过选择最好的图形神经网络来实现准确的空间聚类,GRAPHDeep优化了空间转录学分析. 它确定了基因计数等关键因素,并推了特定的网络,以改善生物洞察力.
科学领域:
- 计算生物学是一种计算生物学.
- 基因组学就是基因组学.
- 生物信息学是一种生物信息学.
背景情况:
- 空间转录学使组织微环境的高分辨率分析成为可能.
- 空间聚类对于理解细胞组织和功能至关重要.
- 图形神经网络 (GNN) 显示了整合空间和基因表达数据的前景.
研究的目的:
- 开发一个框架,GRAPHDeep,用于在空间转录组学中选择空间聚类的最佳GNN.
- 调查不同图形深度学习模块和GNN架构的影响.
- 为选择适合的GNN提供指导,用于空间信息学数据分析.
主要方法:
- 开发了GRAPHDeep,这是一个整合2个图形深度学习模块和20个GNN的框架.
- 在异质空间转录组学数据集上评估了GNN性能.
- 将GRAPHDeep的空间聚类与最先进的方法进行比较.
主要成果:
- 基因/蛋白质的数量显著影响空间聚类性能.
- 变量图形自编码器在这个任务中表现优于深度图形infomax.
- 推的GNN包括UniMP,SAGE,SuperGAT,GATv2,GCN和TAG. 这些是GNN的首选.
- 现有的空间聚类框架可能不使用最佳的GNN.
结论:
- GRAPHDeep提供了一个有效的方法,用于空间转录学中的空间聚类.
- 这项研究为选择适合的GNN用于空间空间数据提供了关键的见解.
- 这项工作指导研究人员优化生物发现的空间聚类分析.
相关概念视频
 03:21
RNA-seq
10.0K
RNA sequencing, or RNA-Seq, is a high-throughput sequencing technology used to study the transcriptome of a cell. Transcriptomics helps to interpret the functional elements of a genome and identify the molecular constituents of an organism. Additionally, it also helps in understanding the development of an organism and the occurrence of diseases.
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
Before the discovery of RNA-seq, microarray-based methods and Sanger sequencing were used for transcriptome analysis. However, while...
10.0K
 01:20
Cluster Sampling Method
11.9K
Appropriate sampling methods ensure that samples are drawn without bias and accurately represent the population. Because measuring the entire population in a study is not practical, researchers use samples to represent the population of interest.
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
To choose a cluster sample, divide the population into clusters (groups) and then randomly select some of the clusters. All the members from these clusters are in the cluster sample. For example, if you randomly sample four departments from your...
11.9K
 02:34
DNA Microarrays
17.4K
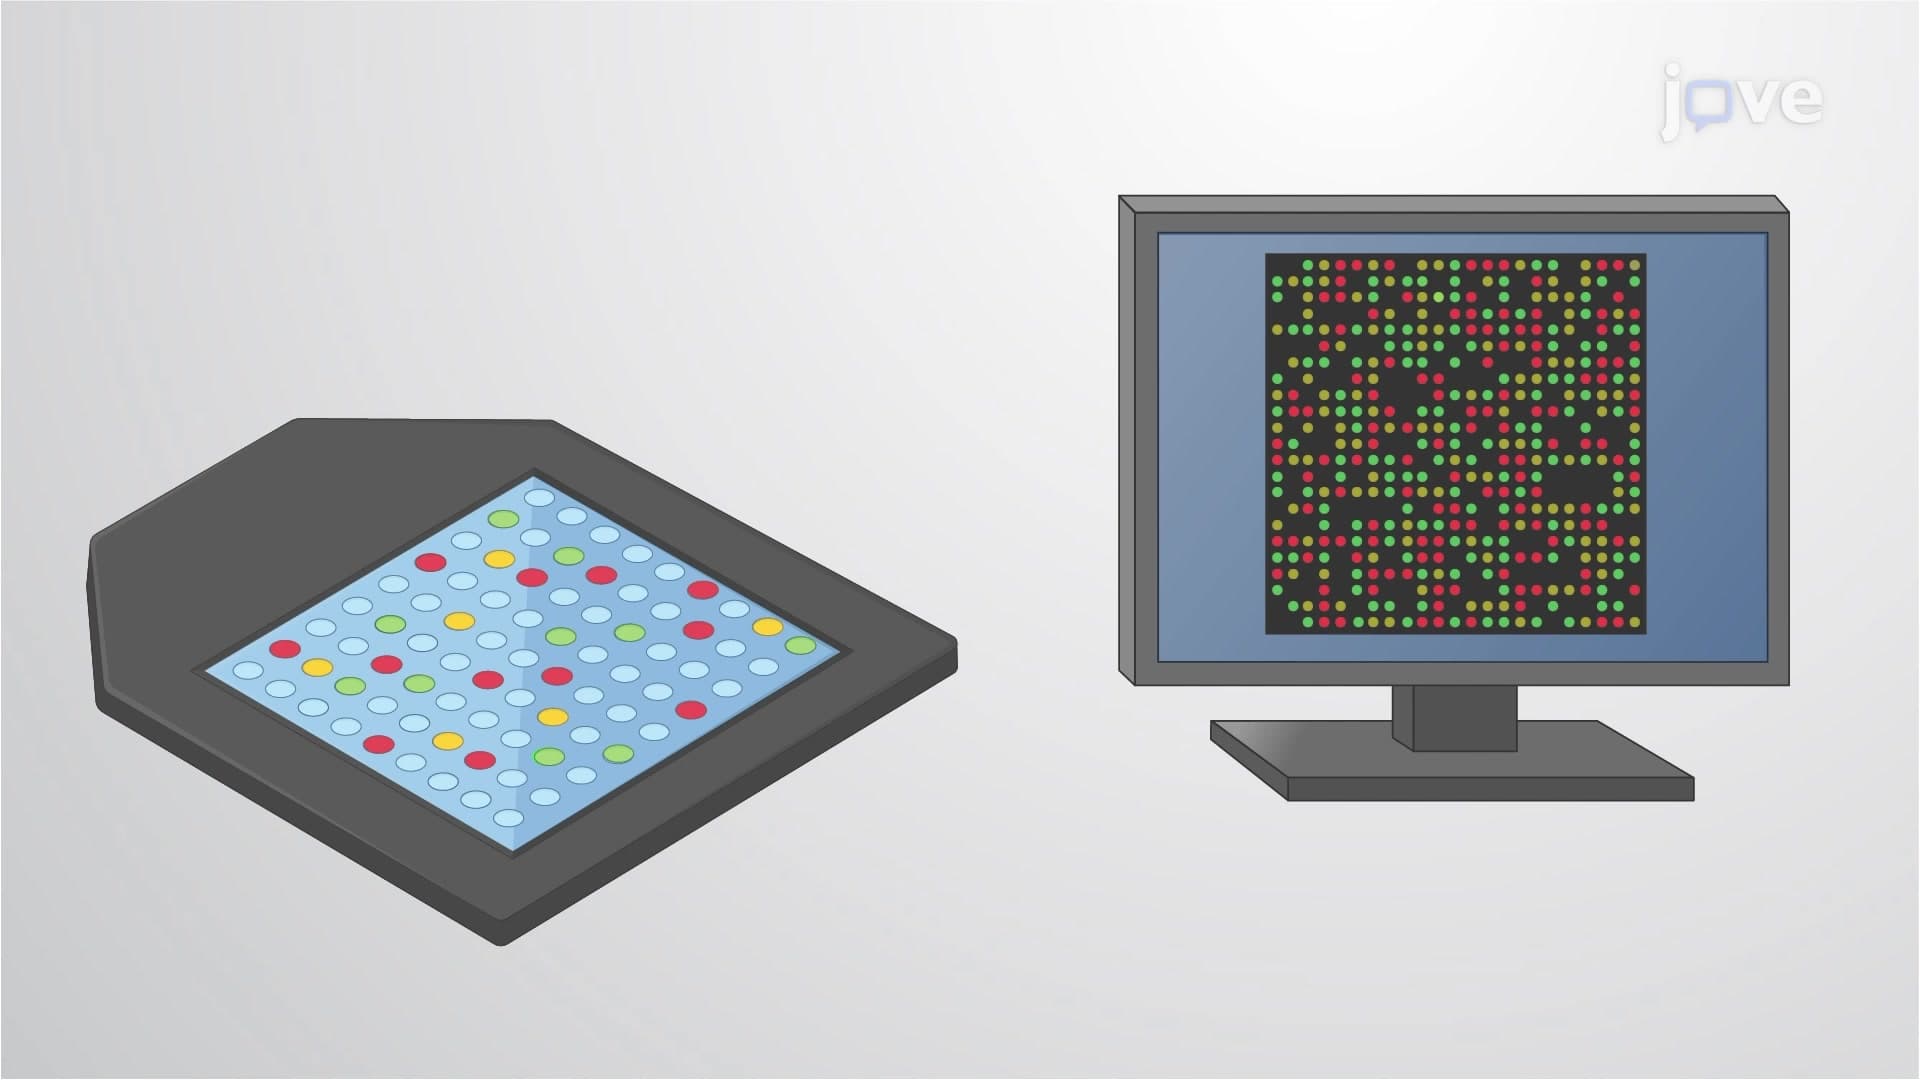
Microarrays are high-throughput and relatively inexpensive assays that can be automated to analyze large quantities of data at a time. They are used in genome-wide studies to compare gene or protein expression under two varied conditions, such as healthy and diseased states. Microarrays consist of glass or silica slides on which probe molecules are covalently attached through surface functionalization. Most commonly, the slides are prepared through the chemisorption of silanes to silica...
17.4K
 02:07
Improving Translational Accuracy
10.5K
Base complementarity between the three base pairs of mRNA codon and the tRNA anticodon is not a failsafe mechanism. Inaccuracies can range from a single mismatch to no correct base pairing at all. The free energy difference between the correct and nearly correct base pairs can be as small as 3 kcal/ mol. With complementarity being the only proofreading step, the estimated error frequency would be one wrong amino acid in every 100 amino acids incorporated. However, error frequencies observed in...
10.5K
 03:36
Genome Annotation and Assembly
18.9K
The genome refers to all of the genetic material in an organism. It can range from a few million base pairs in microbial cells to several billion base pairs in many eukaryotic organisms. Genome assembly refers to the process of taking the DNA sequencing data and putting it all back together in a correct order to create a close representation of the original genome. This is followed by the identification of functional elements on the newly assembled genome, a process called genome annotation.
18.9K