通过使用PCA支持的梯度提升和随机森林算法预测水牛 (Bubalus bubalis) 在墨西哥东南部养的体重
Armando Gomez-Vazquez1, Cem Tırınk2, Alvar Alonzo Cruz-Tamayo3
1División Académica de Ciencias Agropecuarias, Universidad Juárez Autónoma de Tabasco, Villahermosa C.P. 86280, Tabasco, Mexico.
Animals : an open access journal from MDPI
|January 23, 2024

概括
这项研究使用机器学习和主要组件分析 (PCA) 来估计水牛的体重. 渐变增强优于随机森林,为可持续的畜牧业提供了更可靠的方法.
科学领域:
- 动物科学动物科学
- 数据科学数据科学数据科学
- 机器学习 机器学习
背景情况:
- 准确估计体重 (BW) 对于有效的畜牧业和管理至关重要.
- 传统的BW估计方法可能是劳动密集型和不那么精确.
- 先进的计算技术为更高效和可靠的BW预测提供了潜力.
研究的目的:
- 用机器学习技术估计水牛的体重 (BW).
- 应用主要组件分析 (PCA) 来进行尺寸缩小和特征选择.
- 为了比较梯度提升和随机森林算法的预测性能,用于BW估计.
主要方法:
- 从水牛身上收集了身体尺寸.
- 使用主要组件分析 (PCA) 来减少数据的维度,并确定关键变量.
- 使用PCA衍生组件开发了两种机器学习模型,即渐变增强和随机森林.
- 模型性能使用R2,根平均平方误差 (RMSE) 和平均绝对误差 (MAE) 度量来评估.
主要成果:
- 主要组件分析 (PCA) 有效地降低了数据的复杂性,促进了更快的模型训练.
- 与随机森林模型相比,渐变增强模型表现出更高的性能.
- 在BW预测中,渐变增强实现了更高的R2值和更低的错误率 (RMSE,MAE).
- 该研究证实了PCA支持的机器学习对BW估计的有效性.
结论:
- 主要组件分析 (PCA) 提高了机器学习模型的可靠性,用于估计水牛的体重.
- 在这个特定的预测任务中,渐变增强算法比随机森林更有效.
- 机器学习方法,特别是PCA的渐变增强,显示出通过改进决策来支持可持续畜牧业的巨大潜力.
相关概念视频
 00:57
Weighted Mean
5.2K
While taking the arithmetic, geometric, or harmonic mean of a sample data set, equal importance is assigned to all the data points. However, all the values may not always be equally important in some data sets. An intrinsic bias might make it more important to give more weightage to specific values over others.
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
For example, consider the number of goals scored in the matches of a tournament. While computing the average number of goals scored in the tournament, it may be more important to...
5.2K
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:52
Regression Toward the Mean
6.3K
Regression toward the mean (“RTM”) is a phenomenon in which extremely high or low values—for example, and individual’s blood pressure at a particular moment—appear closer to a group’s average upon remeasuring. Although this statistical peculiarity is the result of random error and chance, it has been problematic across various medical, scientific, financial and psychological applications. In particular, RTM, if not taken into account, can interfere when...
6.3K
 01:03
Prediction Intervals
2.3K
The interval estimate of any variable is known as the prediction interval. It helps decide if a point estimate is dependable.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
However, the point estimate is most likely not the exact value of the population parameter, but close to it. After calculating point estimates, we construct interval estimates, called confidence intervals or prediction intervals. This prediction interval comprises a range of values unlike the point estimate and is a better predictor of the observed sample value, y.
2.3K
 01:07
End Point Prediction: Gran Plot
327
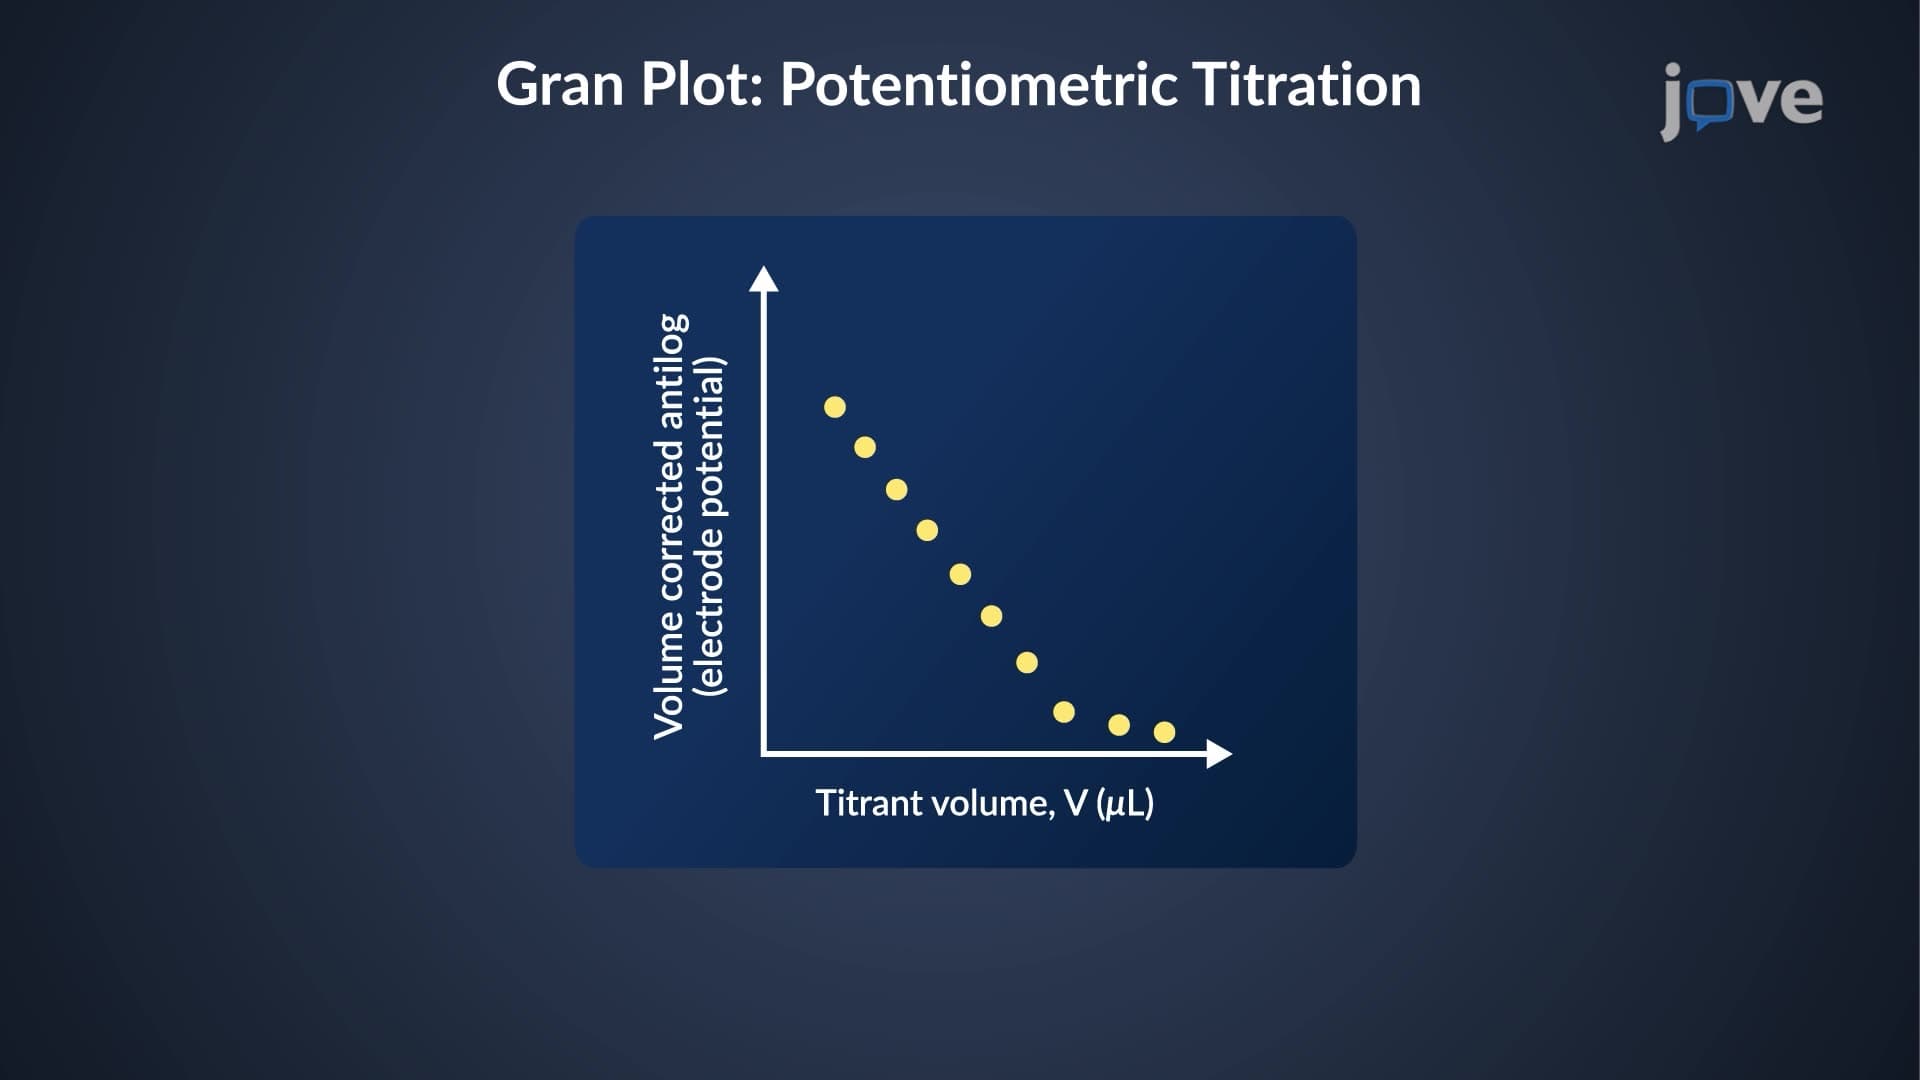
A Gran plot is used to predict the equivalence volume or endpoint of a potentiometric or acid-base titration without reaching the endpoint. Typically, titration data is collected as a function of the titrant's volume up to a point less than the equivalence volume and then transformed into a linear format. The straight line is extended to the x-axis, indicating the necessary titrant volume to achieve the equivalence point.
For potentiometric titration, the Gran plot is created by plotting...
For potentiometric titration, the Gran plot is created by plotting...
327
 01:22
Estimating Population Mean with Unknown Standard Deviation
7.7K
In practice, we rarely know the population standard deviation. In the past, when the sample size was large, this did not present a problem to statisticians. They used the sample standard deviation s as an estimate for σ and proceeded as before to calculate a confidence interval with close enough results. However, statisticians ran into problems when the sample size was small. A small sample size caused inaccuracies in the confidence interval.
William S. Gosset (1876–1937) of the...
William S. Gosset (1876–1937) of the...
7.7K