
一项对线性随机时间序列模型的NNAR方法的新型比较研究,用于预测网球运动员的表现
Abdullah M Almarashi1, Muhammad Daniyal2, Farrukh Jamal3
1Department of Statistics, Faculty of Science, King Abdulaziz University, 21589, Jeddah, Saudi Arabia.
BMC sports science, medicine & rehabilitation
|January 25, 2024

概括
准确的网球表现预测需要考虑比赛时间. 神经网络自动回归 (NNAR) 模型,包括时间,在预测球员排名方面优于ARIMA等传统模型.
科学领域:
- 运动分析 运动分析
- 时间序列预测时间序列预测
- 运动中的机器学习
背景情况:
- 球员表现预测对于体育决策至关重要.
- 现有的模型往往忽视了比赛安排的时间方面.
- 纳入时间对于准确的网球运动员表现预测至关重要.
研究的目的:
- 开发和评估网球运动员绩效指标的预测模型.
- 通过整合时间因素来预测球员排名.
- 帮助玩家和分析师做出明智的决策.
主要方法:
- 利用动态技术分析性能结构,使用线性和非线性时间序列模型.
- 将神经网络自动回归 (NNAR) 模型与ARIMA,ETS和TBATS进行了比较.
- 在评估中使用了根平均平方误差 (RMSE),平均绝对误差 (MAE) 和平均绝对百分比误差 (MAPE).
主要成果:
- 在所有评估指标 (RMSE,MAE,MAPE) 中,NNAR模型表现出卓越的性能.
- NNAR预测显示较窄的95%信心区间,表明准确性和可靠性提高.
- 在网球表现预测方面,NNAR模型被证明比传统模型更有效.
结论:
- 时间是预测网球运动员表现的重要因素.
- 推使用NNAR模型来预测未来的球员排名.
- 与ARIMA,ETS和TBATS等传统模型相比,这种方法提供了更准确的预测.

相关概念视频
 01:25
Multiple Regression
3.0K
Multiple regression assesses a linear relationship between one response or dependent variable and two or more independent variables. It has many practical applications.
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
Farmers can use multiple regression to determine the crop yield based on more than one factor, such as water availability, fertilizer, soil properties, etc. Here, the crop yield is the response or dependent variable as it depends on the other independent variables. The analysis requires the construction of a scatter plot...
3.0K
 01:12
Coefficient of Correlation
6.1K
The correlation coefficient, r, developed by Karl Pearson in the early 1900s, is numerical and provides a measure of strength and direction of the linear association between the independent variable x and the dependent variable y.
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
If you suspect a linear relationship between x and y, then r can measure how strong the linear relationship is.
What the VALUE of r tells us:
The value of r is always between –1 and +1: –1 ≤ r ≤ 1.
The size of the correlation r indicates the...
6.1K
 01:29
Mechanistic Models: Compartment Models in Algorithms for Numerical Problem Solving
55
Mechanistic models play a crucial role in algorithms for numerical problem-solving, particularly in nonlinear mixed effects modeling (NMEM). These models aim to minimize specific objective functions by evaluating various parameter estimates, leading to the development of systematic algorithms. In some cases, linearization techniques approximate the model using linear equations.
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
In individual population analyses, different algorithms are employed, such as Cauchy's method, which uses a...
55
 01:11
Residuals and Least-Squares Property
7.4K
The vertical distance between the actual value of y and the estimated value of y. In other words, it measures the vertical distance between the actual data point and the predicted point on the line
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
If the observed data point lies above the line, the residual is positive, and the line underestimates the actual data value for y. If the observed data point lies below the line, the residual is negative, and the line overestimates the actual data value for y.
The process of fitting the best-fit...
7.4K
 01:17
Wald-Wolfowitz Runs Test I
648
The Wald-Wolfowitz test, also known as the runs test, is a nonparametric statistical test used to assess the randomness of a sequence of two different types of elements (e.g., positive/negative values, successes/failures). It examines whether the order of the elements in a sequence is random or if there is a pattern or trend present. This nonparametric test applies to any ordered data despite the population and sample data distribution, even if a higher sample size is available.
The test works...
The test works...
648
 01:18
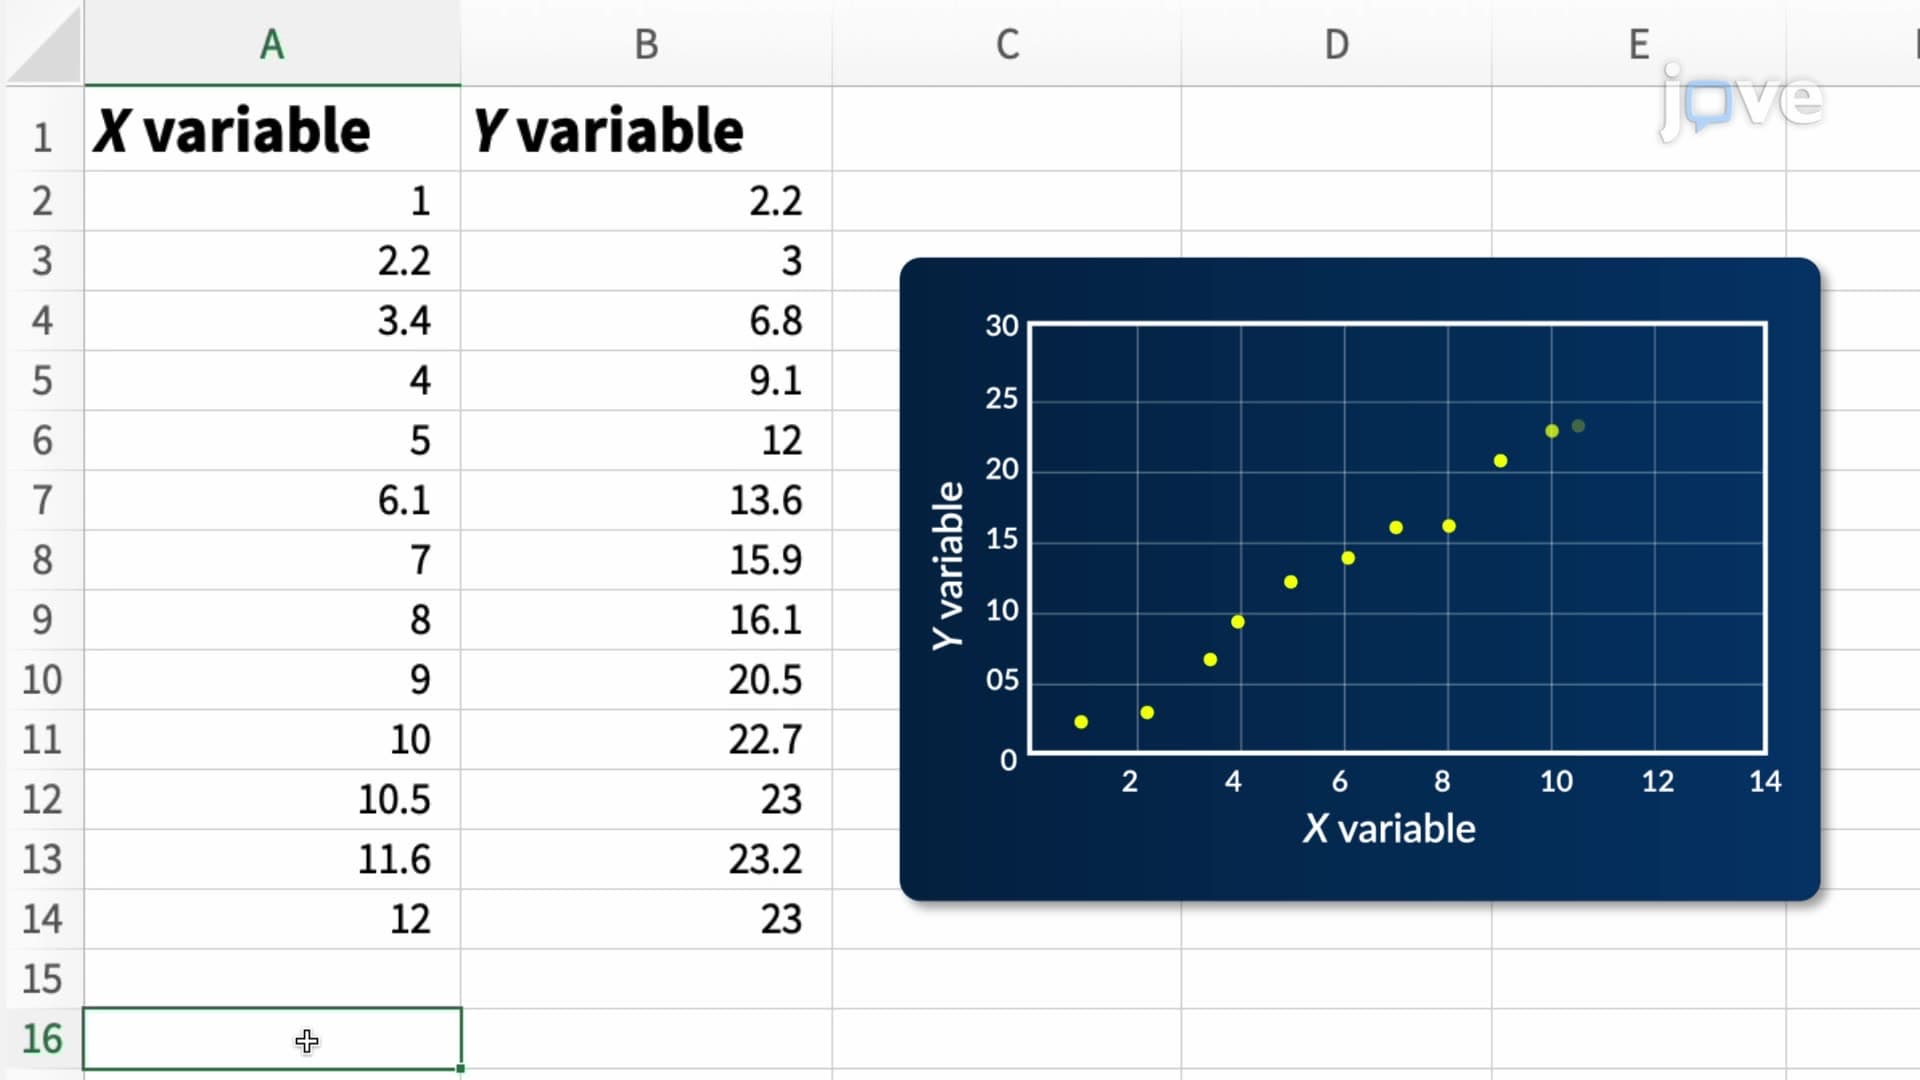
Microsoft Excel: Regression Analysis
608
Regression analysis in Microsoft Excel is a powerful statistical method for examining the relationship between a dependent variable and one or more independent variables. It's used extensively in fields such as economics, biology, and business to predict outcomes, understand relationships, and make data-driven decisions. The most common type is linear regression, which attempts to fit a straight line through the data points to model the relationship between variables.
To perform regression...
To perform regression...
608